Three versions for Databricks-Certified-Professional-Data-Engineer training materials are available, and you can choose the most suitable one according to your own needs. Databricks-Certified-Professional-Data-Engineer PDF version is printable, and you can print them into hard one and take them with you, you can also study anywhere and anyplace. Databricks-Certified-Professional-Data-Engineer Soft test engine can install in more than 200 computers, and it has two modes for practice. Databricks-Certified-Professional-Data-Engineer Soft test engine can also simulate the real exam environment, so that your confidence for the exam will be strengthened. Databricks-Certified-Professional-Data-Engineer Online test engine is convenient and easy to learn. You can have a review of what you have learned through this version.
Databricks Certified Professional Data Engineer exam is designed for professionals who want to showcase their expertise in building and managing data pipelines on the Databricks platform. Databricks is a unified analytics platform that provides powerful tools for data engineers, data scientists, and business analysts to collaborate and build data-driven solutions. Databricks-Certified-Professional-Data-Engineer Exam is a great opportunity for data engineers to validate their skills and knowledge in using Databricks to build scalable data pipelines.
>> Databricks-Certified-Professional-Data-Engineer Valid Exam Camp Pdf <<
The privacy protection of users is an eternal issue in the internet age. Many illegal websites will sell users' privacy to third parties, resulting in many buyers are reluctant to believe strange websites. But you don't need to worry about it at all when buying our Databricks-Certified-Professional-Data-Engineer Learning Engine. We assure you that we will never sell users’ information on the Databricks-Certified-Professional-Data-Engineer exam questions because it is damaging our own reputation. And we will help you on the Databricks-Certified-Professional-Data-Engineer study materials if you have any question.
Databricks Certified Professional Data Engineer is an exam designed for professionals who are willing to demonstrate their expertise in building and managing big data pipelines using Databricks. Databricks is a unified analytics platform that provides a collaborative environment for processing large-scale data. The Databricks Certified Professional Data Engineer exam validates the candidate's ability to design, build, and deploy large-scale data processing solutions using Databricks.
NEW QUESTION # 11
In order to use Unity catalog features, which of the following steps needs to be taken on man-aged/external tables in the Databricks workspace?
Answer: E
Explanation:
Explanation
Upgrade tables and views to Unity Catalog - Azure Databricks | Microsoft Docs Managed table: Upgrade a managed to Unity Catalog External table: Upgrade an external table to Unity Catalog
NEW QUESTION # 12
You were asked to create a table that can store the below data, orderTime is a timestamp but the finance team when they query this data normally prefer the orderTime in date format, you would like to create a calculated column that can convert the orderTime column timestamp datatype to date and store it, fill in the blank to complete the DDL.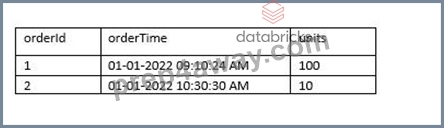
Answer: B
Explanation:
Explanation
The answer is, GENERATED ALWAYS AS (CAST(orderTime as DATE))
https://docs.microsoft.com/en-us/azure/databricks/delta/delta-batch#--use-generated-columns Delta Lake supports generated columns which are a special type of columns whose values are au-tomatically generated based on a user-specified function over other columns in the Delta table. When you write to a table with generated columns and you do not explicitly provide values for them, Delta Lake automatically computes the values.
Note: Databricks also supports partitioning using generated column
NEW QUESTION # 13
Which statement describes the default execution mode for Databricks Auto Loader?
Answer: D
Explanation:
Databricks Auto Loader simplifies and automates the process of loading data into Delta Lake. The default execution mode of the Auto Loader identifies new files by listing the input directory. It incrementally and idempotently loads these new files into the target Delta Lake table. This approach ensures that files are not missed and are processed exactly once, avoiding data duplication. The other options describe different mechanisms or integrations that are not part of the default behavior of the Auto Loader.
Reference:
Databricks Auto Loader Documentation: Auto Loader Guide
Delta Lake and Auto Loader: Delta Lake Integration
NEW QUESTION # 14
Consider flipping a coin for which the probability of heads is p, where p is unknown, and our goa is to
estimate p. The obvious approach is to count how many times the coin came up heads and divide by the total
number of coin flips. If we flip the coin 1000 times and it comes up heads 367 times, it is very reasonable to
estimate p as approximately 0.367. However, suppose we flip the coin only twice and we get heads both times.
Is it reasonable to estimate p as 1.0? Intuitively, given that we only flipped the coin twice, it seems a bit
rash to conclude that the coin will always come up heads, and____________is a way of avoiding such rash
conclusions.
Answer: A
Explanation:
Explanation
Smooth the estimates:consider flipping a coin for which the probability of heads is p, where p is unknown, and
our goal is to estimate p. The obvious approach is to count how many times the coin came up heads and divide
by the total number of coin flips. If we flip the coin 1000 times and it comes up heads 367 times, it is very
reasonable to estimate p as approximately 0.367. However, suppose we flip the coin only twice and we get
heads both times. Is it reasonable to estimate p as 1.0? Intuitively, given that we only flipped the coin twice, it
seems a bit rash to conclude that the coin will always come up heads, and smoothing is a way of avoiding such
rash conclusions. A simple smoothing method, called Laplace smoothing (or Laplace's law of succession or
add-one smoothing in R&N), is to estimate p by (one plus the number of heads) / (two plus the total number of
flips). Said differently, if we are keeping count of the number of heads and the number of tails, this rule is
equivalent to starting each of our counts at one, rather than zero. Another advantage of Laplace smoothing is
that it avoids estimating any probabilities to be zero, even for events never observed in the data. Laplace
add-one smoothing now assigns too much probability to unseen words
NEW QUESTION # 15
A Delta Lake table representing metadata about content posts from users has the following schema:
user_id LONG
post_text STRING
post_id STRING
longitude FLOAT
latitude FLOAT
post_time TIMESTAMP
date DATE
Based on the above schema, which column is a good candidate for partitioning the Delta Table?
Answer: B
Explanation:
Partitioning a Delta Lake table is a strategy used to improve query performance by dividing the table into distinct segments based on the values of a specific column. This approach allows queries to scan only the relevant partitions, thereby reducing the amount of data read and enhancing performance.
Considerations for Choosing a Partition Column:
Cardinality: Columns with high cardinality (i.e., a large number of unique values) are generally poor choices for partitioning. High cardinality can lead to a large number of small partitions, which can degrade performance.
Query Patterns: The partition column should align with common query filters. If queries frequently filter data based on a particular column, partitioning by that column can be beneficial.
Partition Size: Each partition should ideally contain at least 1 GB of data. This ensures that partitions are neither too small (leading to too many partitions) nor too large (negating the benefits of partitioning).
Evaluation of Columns:
date:
Cardinality: Typically low, especially if data spans over days, months, or years.
Query Patterns: Many analytical queries filter data based on date ranges.
Partition Size: Likely to meet the 1 GB threshold per partition, depending on data volume.
user_id:
Cardinality: High, as each user has a unique ID.
Query Patterns: While some queries might filter by user_id, the high cardinality makes it unsuitable for partitioning.
Partition Size: Partitions could be too small, leading to inefficiencies.
post_id:
Cardinality: Extremely high, with each post having a unique ID.
Query Patterns: Unlikely to be used for filtering large datasets.
Partition Size: Each partition would be very small, resulting in a large number of partitions.
post_time:
Cardinality: High, especially if it includes exact timestamps.
Query Patterns: Queries might filter by time, but the high cardinality poses challenges.
Partition Size: Similar to user_id, partitions could be too small.
Conclusion:
Given the considerations, the date column is the most suitable candidate for partitioning. It has low cardinality, aligns with common query patterns, and is likely to result in appropriately sized partitions.
Reference:
Delta Lake Best Practices
Partitioning in Delta Lake
NEW QUESTION # 16
......
Best Databricks-Certified-Professional-Data-Engineer Practice: https://www.prep4away.com/Databricks-certification/braindumps.Databricks-Certified-Professional-Data-Engineer.ete.file.html