Certified-Data-Engineer-Professional Fragen&Antworten & Certified-Data-Engineer-Professional Übungsmaterialien

Unser It-Pruefung verspricht, dass Sie die Databricks Certified-Data-Engineer-Professional Prüfung einmalig bestehen und das Zertifikat von den Experten bekommen können. Denn unser It-Pruefung stellt Ihnen die besten Prüfungsfragen und Antworten zur Databricks Certified-Data-Engineer-Professional zur Verfügung. Und Sie können sich schrittweise auf die Prüfung gut vorbereiten. Unser It-Pruefung verspricht, dass die Fragen und Antworten zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung von It-Pruefung Ihren Erfolg garantiert.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 2. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 3. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 4. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 5. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 6. Create pipeline components using control flow operators such as if/else and foreach
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 2. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 3. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 4. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 5. Apply Change Data Feed to address streaming table limitations and improve latency
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
|
| Monitoring and Alerting | - Monitoring
- 1. Use Query Profile and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
| Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Simplify data layout decisions and optimize query performance using liquid clustering
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
>> Certified-Data-Engineer-Professional Fragen&Antworten <<
Certified-Data-Engineer-Professional Prüfungsfragen Prüfungsvorbereitungen, Certified-Data-Engineer-Professional Fragen und Antworten, Databricks Certified Data Engineer Professional
Die Zertifikat der Databricks Certified-Data-Engineer-Professional ist international anerkannt. Sie zu erwerben bedeutet, dass Sie den Schlüssel zur höheren Stelle besitzen. Die Databricks Certified-Data-Engineer-Professional Prüfungsunterlagen von It-Pruefung werden von erfahrenen IT-Profis herstellt und immer wieder aktualisiert. Jetzt können Sie mit günstigem Preis die verlässliche Databricks Certified-Data-Engineer-Professional Prüfungsunterlagen genießen. Nachdem Sie die Zertifizierung erwerbt haben, können Sie leicht eine höhere Arbeitsposition oder Gehalten bekommen.
Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional Prüfungsfragen mit Lösungen (Q193-Q198):
193. Frage
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
- B. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.
- C. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
- D. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
- E. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
Antwort: E
Begründung:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
194. Frage
A data engineer needs to implement column masking for a sensitive column in a Unity Catalog- managed table. The masking logic must dynamically check if users belong to specific groups defined in a separate table (group_access) that maps groups to allowed departments. Which approach should the engineer use to efficiently enforce this requirement?
- A. Create a view without selecting the sensitive column.
- B. Apply a column mask that references the group_access mapping table in its UDF.
- C. Create a UDF that hardcodes allowed groups and apply it as a column mask.
- D. Use a row filter to restrict access based on the user's group.
Antwort: B
Begründung:
Databricks Unity Catalog supports dynamic column masking, where masking logic can be implemented using SQL functions or UDFs that reference external mapping tables or metadata for context-aware access control.
By referencing the group_access table inside the masking function, the mask dynamically evaluates whether a requesting user belongs to an authorized group. If permitted, the original column value is returned; otherwise, a masked value (such as NULL or asterisks) is shown.
This method enables fine-grained, data-driven masking policies while maintaining a single authoritative access mapping source.
Hardcoding values (A) reduces flexibility, and row filters (D) apply to entire rows rather than specific columns. Therefore, C correctly aligns with Databricks best practices for dynamic masking.
195. Frage
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable. Which approach will solve the problem with minimum overhead while preserving data integrity?
- A. Use a SCALAR Pandas UDF that processes the entire dataset at once, implementing custom partitioning logic within the UDF to group by stock symbol and maintain state using global variables shared across all executor processes.
- B. Use applyInPandas() on a Spark DataFrame that receives all rows for each stock symbol as a Pandas DataFrame, allowing processing within each group while maintaining state variables local to each group's processing function.
- C. Use a grouped_agg Pandas UDF that processes each stock symbol group independently, maintaining state through intermediate aggregation results that get passed between successive UDF calls via broadcast variables.
- D. Use a SCALAR_ITER Pandas UDF with iterator-based processing, implementing state management through persistent storage (Delta tables) that gets updated after each batch to maintain continuity across iterator chunks.
Antwort: B
Begründung:
The Databricks documentation recommends applyInPandas() for complex per-group operations where maintaining internal state within each group is necessary. When using applyInPandas(), Spark provides all records for each grouping key as a Pandas DataFrame to the function, allowing efficient vectorized operations with local state management. This approach ensures high performance and scalability while maintaining logical isolation between groups. In contrast, SCALAR and SCALAR_ITER UDFs operate on individual rows or batches and cannot maintain inter-row state effectively. grouped_agg UDFs are limited to computing aggregates and do not support complex multi-row transformations. Therefore, applyInPandas() is the correct and Databricks-recommended solution for stateful per-group time-series computations.
196. Frage
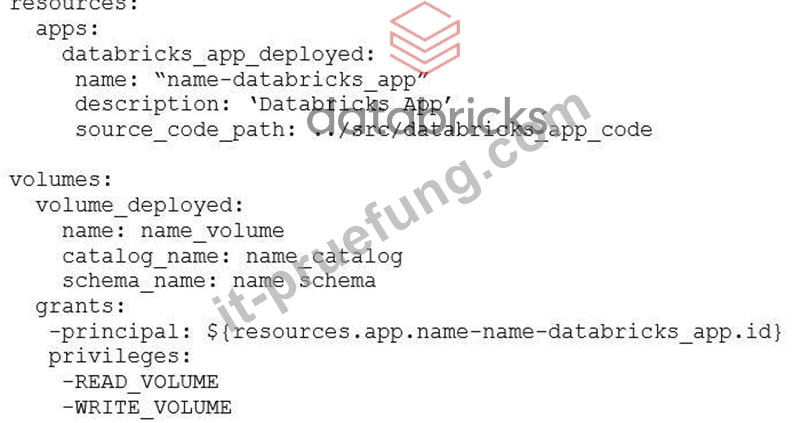
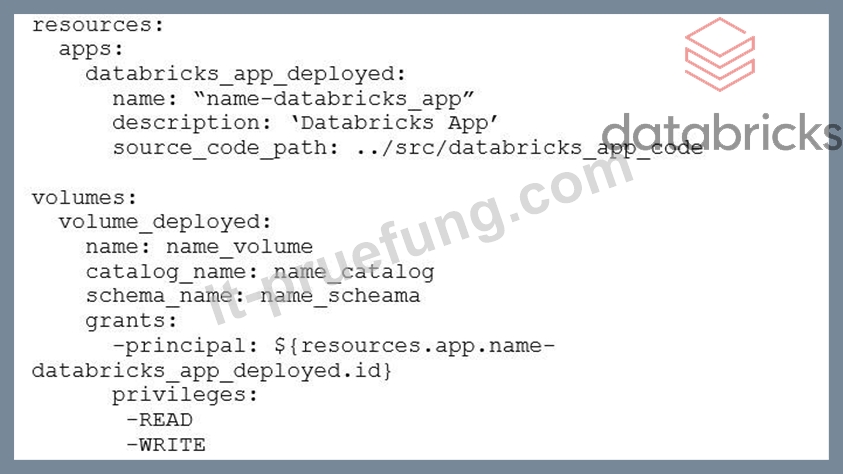
In a Databricks Asset Bundle project, in the file resources/app.yml, the data engineer would like to deploy a Databricks Apps databricks_app_deployed and Volume volume_deployed and grant the Service Principal behind Databricks Apps permissions to READ and WRITE to the Volume.
How should the data engineer achieve the deployment?
Antwort: B
Begründung:
This configuration correctly references the service principal created for the Databricks App using the deployed app resource identifier, and it grants the required READ and WRITE privileges at the Volume level. The privileges are specified using the correct Volume-specific permissions, ensuring the Databricks App can securely access the Volume after deployment.
197. Frage
A junior data engineer has manually configured a series of jobs using the Databricks Jobs UI.
Upon reviewing their work, the engineer realizes that they are listed as the "Owner" for each job.
They attempt to transfer "Owner" privileges to the "DevOps" group, but cannot successfully accomplish this task.
Which statement explains what is preventing this privilege transfer?
- A. The creator of a Databricks job will always have "Owner" privileges; this configuration cannot be changed.
- B. Only workspace administrators can grant "Owner" privileges to a group.
- C. A user can only transfer job ownership to a group if they are also a member of that group.
- D. Other than the default "admins" group, only individual users can be granted privileges on jobs.
- E. Databricks jobs must have exactly one owner; "Owner" privileges cannot be assigned to a group.
Antwort: E
Begründung:
A job cannot have more than one owner. A job cannot have a group as an owner.
198. Frage
......
Möchten Sie die nur mit die Hälfte Zeit und Energie bestehen? Dann wählen Sie It-Pruefung. Nach mehrjährigen Bemühungen ist die Bestehensquote von der Webseite It-Pruefung in der ganzen Welt am höchsten. Wenn Sie die Genauigkeit der Fragenkataloge zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung aus It-Pruefung prüfen möchten, können Sie ein paar Exam Fragen auf der Webseite It-Pruefung herunterladen, damit bastätigen Sie Ihre Wahl.
Certified-Data-Engineer-Professional Übungsmaterialien: https://www.it-pruefung.com/Certified-Data-Engineer-Professional.html
- Certified-Data-Engineer-Professional Deutsche 🕌 Certified-Data-Engineer-Professional Dumps ⛽ Certified-Data-Engineer-Professional Schulungsangebot 🧳 Öffnen Sie die Webseite ➤ www.zertpruefung.ch ⮘ und suchen Sie nach kostenloser Download von ➽ Certified-Data-Engineer-Professional 🢪 😿Certified-Data-Engineer-Professional Prüfungs-Guide
- Certified-Data-Engineer-Professional Pass4sure Dumps - Certified-Data-Engineer-Professional Sichere Praxis Dumps 🐂 [ www.itzert.com ] ist die beste Webseite um den kostenlosen Download von ☀ Certified-Data-Engineer-Professional ️☀️ zu erhalten 🤞Certified-Data-Engineer-Professional Lernhilfe
- Certified-Data-Engineer-Professional Online Prüfung 🕌 Certified-Data-Engineer-Professional Lernhilfe 😵 Certified-Data-Engineer-Professional Schulungsangebot 🤓 Öffnen Sie die Webseite { www.itzert.com } und suchen Sie nach kostenloser Download von ▛ Certified-Data-Engineer-Professional ▟ 🤟Certified-Data-Engineer-Professional Ausbildungsressourcen
- Certified-Data-Engineer-Professional Studienmaterialien: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional Torrent Prüfung - Certified-Data-Engineer-Professional wirkliche Prüfung 🛫 Suchen Sie auf der Webseite ▶ www.itzert.com ◀ nach ▛ Certified-Data-Engineer-Professional ▟ und laden Sie es kostenlos herunter 🅾Certified-Data-Engineer-Professional Prüfungsunterlagen
- Certified-Data-Engineer-Professional Deutsch Prüfung 😆 Certified-Data-Engineer-Professional Online Praxisprüfung 🥟 Certified-Data-Engineer-Professional Online Prüfung 🥳 Öffnen Sie ▛ www.zertpruefung.ch ▟ geben Sie { Certified-Data-Engineer-Professional } ein und erhalten Sie den kostenlosen Download 🍫Certified-Data-Engineer-Professional Lernhilfe
- Certified-Data-Engineer-Professional Mit Hilfe von uns können Sie bedeutendes Zertifikat der Certified-Data-Engineer-Professional einfach erhalten! 🌝 Suchen Sie einfach auf [ www.itzert.com ] nach kostenloser Download von ➡ Certified-Data-Engineer-Professional ️⬅️ ✒Certified-Data-Engineer-Professional Dumps
- Certified-Data-Engineer-Professional Dumps 🪂 Certified-Data-Engineer-Professional Deutsch Prüfung 🔯 Certified-Data-Engineer-Professional Ausbildungsressourcen 👋 Geben Sie [ www.zertpruefung.ch ] ein und suchen Sie nach kostenloser Download von 《 Certified-Data-Engineer-Professional 》 👯Certified-Data-Engineer-Professional Examsfragen
- Certified-Data-Engineer-Professional Schulungsangebot 🎪 Certified-Data-Engineer-Professional PDF Testsoftware 😴 Certified-Data-Engineer-Professional Lernhilfe 🪂 Suchen Sie jetzt auf ▛ www.itzert.com ▟ nach 「 Certified-Data-Engineer-Professional 」 um den kostenlosen Download zu erhalten ✋Certified-Data-Engineer-Professional Musterprüfungsfragen
- Certified-Data-Engineer-Professional PDF Testsoftware ⚪ Certified-Data-Engineer-Professional Prüfungs-Guide ⭕ Certified-Data-Engineer-Professional Zertifikatsdemo 👔 Suchen Sie jetzt auf ▶ www.deutschpruefung.com ◀ nach ⏩ Certified-Data-Engineer-Professional ⏪ und laden Sie es kostenlos herunter 🎃Certified-Data-Engineer-Professional Musterprüfungsfragen
- Certified-Data-Engineer-Professional Prüfungsunterlagen 🔗 Certified-Data-Engineer-Professional Testing Engine 🪐 Certified-Data-Engineer-Professional Musterprüfungsfragen 🤒 Öffnen Sie die Webseite ✔ www.itzert.com ️✔️ und suchen Sie nach kostenloser Download von ➡ Certified-Data-Engineer-Professional ️⬅️ 🎷Certified-Data-Engineer-Professional Zertifizierungsprüfung
- Certified-Data-Engineer-Professional PrüfungGuide, Databricks Certified-Data-Engineer-Professional Zertifikat - Databricks Certified Data Engineer Professional ➡ Suchen Sie auf ▛ www.deutschpruefung.com ▟ nach 「 Certified-Data-Engineer-Professional 」 und erhalten Sie den kostenlosen Download mühelos 🎒Certified-Data-Engineer-Professional Testantworten
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, rare-books.library.sites.carleton.edu, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes