Databricks-Certified-Data-Engineer-Professional試験の準備方法 |有難いDatabricks-Certified-Data-Engineer-Professional受験記対策試験 |実用的なDatabricks Certified Data Engineer Professional Exam日本語問題集

2026年GoShikenの最新Databricks-Certified-Data-Engineer-Professional PDFダンプおよびDatabricks-Certified-Data-Engineer-Professional試験エンジンの無料共有:https://drive.google.com/open?id=1jr3WOglFiylFTlyPZdqISvOkMkWe5mEq
GoShikenを利用するのは君の合格率を100%保証いたします。GoShikenは多種なDatabricks認証試験を受ける方を正確な資料を提供者でございます。弊社の無料なDatabricks-Certified-Data-Engineer-Professionalサンプルを遠慮なくダウンロードしてください。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Data Processing | 28% | - ETL Pipelines
- Data Transformation
- Spark SQL
- Structured Streaming
|
| Topic 2: Data Quality and Governance | 12% | - Governance
- Data Lineage
- Data Quality
|
| Topic 3: Monitoring and Troubleshooting | 16% | - Monitoring
- Performance Optimization
- Troubleshooting
|
| Topic 4: Databricks Lakehouse Platform | 24% | - Data Management
- Delta Lake
- Lakehouse Architecture
- Unity Catalog
|
| Topic 5: Data Modeling and Storage | 20% | - File Formats
- Storage Optimization
- Data Modeling
|
>> Databricks-Certified-Data-Engineer-Professional受験記対策 <<
Databricks-Certified-Data-Engineer-Professional日本語問題集 & Databricks-Certified-Data-Engineer-Professional PDF問題サンプル
現在、IT業界での激しい競争に直面しているあなたは、無力に感じるでしょう。これは避けられないことですから、あなたがしなければならないことは、自分のキャリアを護衛するのです。色々な選択がありますが、GoShikenのDatabricksのDatabricks-Certified-Data-Engineer-Professional問題集と解答をお勧めします。それはあなたが成功認定を助ける良いヘルパーですから、あなたはまだ何を待っているのですか。速く最新のGoShikenのDatabricksのDatabricks-Certified-Data-Engineer-Professionalトレーニング資料を取りに行きましょう。
Databricks Certified Data Engineer Professional Exam 認定 Databricks-Certified-Data-Engineer-Professional 試験問題 (Q80-Q85):
質問 # 80
A nightly batch job is configured to ingest all data files from a cloud object storage container where records are stored in a nested directory structure YYYY/MM/DD. The data for each date represents all records that were processed by the source system on that date, noting that some records may be delayed as they await moderator approval. Each entry represents a user review of a product and has the following schema:
user_id STRING, review_id BIGINT, product_id BIGINT, review_timestamp TIMESTAMP, review_text STRING The ingestion job is configured to append all data for the previous date to a target table reviews_raw with an identical schema to the source system. The next step in the pipeline is a batch write to propagate all new records inserted into reviews_raw to a table where data is fully deduplicated, validated, and enriched.
Which solution minimizes the compute costs to propagate this batch of data?
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
- A. Reprocess all records in reviews_raw and overwrite the next table in the pipeline.
- B. Perform a batch read on the reviews_raw table and perform an insert-only merge using the natural composite key user_id, review_id, product_id, review_timestamp.
- C. Configure a Structured Streaming read against the reviews_raw table using the trigger once execution mode to process new records as a batch job.
- D. Filter all records in the reviews_raw table based on the review_timestamp; batch append those records produced in the last 48 hours.
- E. Use Delta Lake version history to get the difference between the latest version of reviews_raw and one version prior, then write these records to the next table.
正解:C
解説:
https://www.databricks.com/blog/2017/05/22/running-streaming-jobs-day-10x-cost-savings.html
質問 # 81
A data engineer is implementing a job to download multiple PDF files from a third-party provided REST API endpoint by specifying different report types. The REST API is time-consuming and encounters intermittent errors, so the engineer wants to track each download activity to know when it fails and to retry partially, while providing scalable throughput. The engineer needs to download ten report types, and the list can be changed over time. How should the data engineer achieve this?
- A. Use a Delta Lake table to track each report download status as 10 rows, and use it as a source table to execute the download function as a Pandas UDF.
- B. Define a list variable within a Notebook to loop through the report types to download them, and print the download results. Execute it as a Notebook tasks.
- C. Define ten Notebook tasks to clearly track which report download failed.
- D. Use a foreach task with a list of report types as its inputs.
正解:D
解説:
A foreach task allows the job to dynamically iterate over a configurable list of report types, execute downloads in parallel, and track the success or failure of each item independently. This enables scalable throughput, partial retries for failed downloads, and easy updates when the list of report types changes, without hardcoding tasks or introducing unnecessary complexity.
質問 # 82
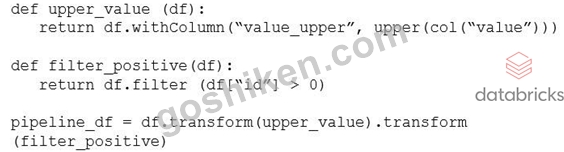
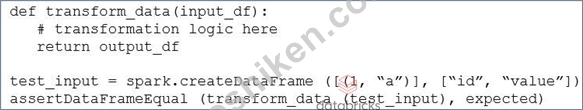
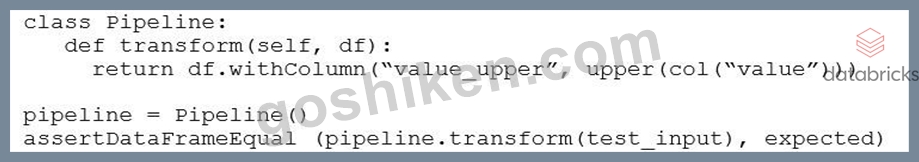
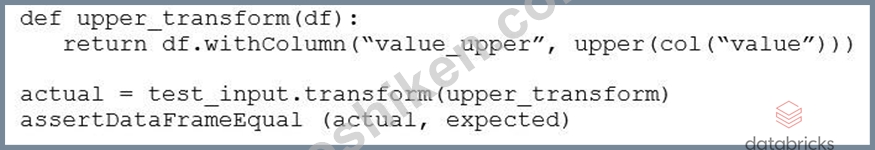
Which approach demonstrates a modular and testable way to use DataFrame transform for ETL code in PySpark?
正解:D
解説:
Using DataFrame.transform with a pure transformation function promotes modular, reusable, and easily testable ETL logic. Each transformation is encapsulated as a standalone function, can be independently unit tested, and composed cleanly in a pipeline without coupling to orchestration or class state.
質問 # 83
A data team is working to optimize an existing large, fast-growing table 'orders' with high cardinality columns, which experiences significant data skew and requires frequent concurrent writes. The team notice that the columns 'user_id', 'event_timestamp' and 'product_id' are heavily used in analytical queries and filters, although those keys may be subject to change in the future due to different business requirements. Which partitioning strategy should the team choose to optimize the table for immediate data skipping, incremental management over time, and flexibility?
- A. Z-order the table with OPTIMIZE orders ZORDER BY (user_id, product_id, event_timestamp)
- B. Use z-order after partitiing the table: OPTIMIZE orders ZORDER BY (user_id, product_id) WHERE event_timestamp = current date () - 1 DAY
- C. Partition the table with: ALTER TABLE orders PARTITION BY user_id, product_id, event_timestamp
- D. Cluster the table with: ALTER TABLE orders CLUSTER BY user_id, product_id, event_timestamp
正解:A
解説:
Z-ordering optimizes data skipping for selective queries on high-cardinality columns without physically repartitioning the table, making it flexible if query patterns change. Using OPTIMIZE ...
ZORDER BY (user_id, product_id, event_timestamp) improves query performance for filters and joins while allowing incremental writes, avoiding the data skew and maintenance overhead that explicit partitioning or clustering could introduce.
質問 # 84
A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor.
When evaluating the Ganglia Metrics for this cluster, which indicator would signal a bottleneck caused by code executing on the driver?
- A. Overall cluster CPU utilization is around 25%
- B. Network I/O never spikes
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from - C. The five Minute Load Average remains consistent/flat
- D. Bytes Received never exceeds 80 million bytes per second
- E. Total Disk Space remains constant
正解:A
解説:
This is the correct answer because it indicates a bottleneck caused by code executing on the driver. A bottleneck is a situation where the performance or capacity of a system is limited by a single component or resource. A bottleneck can cause slow execution, high latency, or low throughput. A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor. When evaluating the Ganglia Metrics for this cluster, one can look for indicators that show how the cluster resources are being utilized, such as CPU, memory, disk, or network. If the overall cluster CPU utilization is around 25%, it means that only one out of the four nodes (driver + 3 executors) is using its full CPU capacity, while the other three nodes are idle or underutilized. This suggests that the code executing on the driver is taking too long or consuming too much CPU resources, preventing the executors from receiving tasks or data to process. This can happen when the code has driver-side operations that are not parallelized or distributed, such as collecting large amounts of data to the driver, performing complex calculations on the driver, or using non-Spark libraries on the driver.
質問 # 85
......
あなたのキャリアでいくつかの輝かしい業績を行うことを望まないのですか。きっとそれを望んでいるでしょう。では、常に自分自身をアップグレードする必要があります。では、IT業種で仕事しているあなたはどうやって自分のレベルを高めるべきですか。実は、Databricks-Certified-Data-Engineer-Professional認定試験を受験して認証資格を取るのは一つの良い方法です。Databricksの認定試験のDatabricks-Certified-Data-Engineer-Professional資格は非常に大切なものですから、Databricksの試験を受ける人もますます多くなっています。
Databricks-Certified-Data-Engineer-Professional日本語問題集: https://www.goshiken.com/Databricks/Databricks-Certified-Data-Engineer-Professional-mondaishu.html
- Databricks-Certified-Data-Engineer-Professional試験資料 🍄 Databricks-Certified-Data-Engineer-Professional資格模擬 🐹 Databricks-Certified-Data-Engineer-Professional日本語版参考資料 💔 ▶ www.mogiexam.com ◀で☀ Databricks-Certified-Data-Engineer-Professional ️☀️を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional日本語版対応参考書
- Databricks-Certified-Data-Engineer-Professional試験の準備方法|認定するDatabricks-Certified-Data-Engineer-Professional受験記対策試験|効率的なDatabricks Certified Data Engineer Professional Exam日本語問題集 🛑 ▷ www.goshiken.com ◁は、[ Databricks-Certified-Data-Engineer-Professional ]を無料でダウンロードするのに最適なサイトですDatabricks-Certified-Data-Engineer-Professional受験体験
- Databricks-Certified-Data-Engineer-Professionalテストエンジン、Databricks-Certified-Data-Engineer-Professional試験トレント、Databricks-Certified-Data-Engineer-Professional資格問題集 🍶 ✔ www.jpshiken.com ️✔️を開き、【 Databricks-Certified-Data-Engineer-Professional 】を入力して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional模擬解説集
- Databricks-Certified-Data-Engineer-Professional受験体験 ❇ Databricks-Certified-Data-Engineer-Professional日本語版参考書 🎪 Databricks-Certified-Data-Engineer-Professional最新な問題集 ⛑ { www.goshiken.com }で✔ Databricks-Certified-Data-Engineer-Professional ️✔️を検索して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional復習テキスト
- Databricks-Certified-Data-Engineer-Professionalシュミレーション問題集 🧺 Databricks-Certified-Data-Engineer-Professional日本語版参考書 😉 Databricks-Certified-Data-Engineer-Professional試験解説 🏩 今すぐ▛ www.goshiken.com ▟で{ Databricks-Certified-Data-Engineer-Professional }を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional受験内容
- Databricks-Certified-Data-Engineer-Professional受験内容 📠 Databricks-Certified-Data-Engineer-Professional復習対策書 🦱 Databricks-Certified-Data-Engineer-Professional日本語版参考資料 🔍 “ Databricks-Certified-Data-Engineer-Professional ”を無料でダウンロード《 www.goshiken.com 》で検索するだけDatabricks-Certified-Data-Engineer-Professional模擬解説集
- Databricks-Certified-Data-Engineer-Professional最新な問題集 🐒 Databricks-Certified-Data-Engineer-Professional復習テキスト ↖ Databricks-Certified-Data-Engineer-Professional復習対策書 🐝 “ www.passtest.jp ”の無料ダウンロード[ Databricks-Certified-Data-Engineer-Professional ]ページが開きますDatabricks-Certified-Data-Engineer-Professional試験解説
- Databricks-Certified-Data-Engineer-Professional受験体験 👫 Databricks-Certified-Data-Engineer-Professional認定内容 🪒 Databricks-Certified-Data-Engineer-Professionalシュミレーション問題集 📪 ☀ www.goshiken.com ️☀️で使える無料オンライン版( Databricks-Certified-Data-Engineer-Professional ) の試験問題Databricks-Certified-Data-Engineer-Professional試験勉強攻略
- Databricks-Certified-Data-Engineer-Professional試験勉強攻略 🛌 Databricks-Certified-Data-Engineer-Professional日本語版参考資料 🏠 Databricks-Certified-Data-Engineer-Professional模擬解説集 👏 サイト( www.goshiken.com )で➽ Databricks-Certified-Data-Engineer-Professional 🢪問題集をダウンロードDatabricks-Certified-Data-Engineer-Professional受験内容
- Databricks-Certified-Data-Engineer-Professional試験資料 📂 Databricks-Certified-Data-Engineer-Professional関連試験 🛫 Databricks-Certified-Data-Engineer-Professional日本語版対応参考書 💫 ➽ www.goshiken.com 🢪で⏩ Databricks-Certified-Data-Engineer-Professional ⏪を検索して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional独学書籍
- Databricks-Certified-Data-Engineer-Professionalテストエンジン、Databricks-Certified-Data-Engineer-Professional試験トレント、Databricks-Certified-Data-Engineer-Professional資格問題集 📤 ⏩ Databricks-Certified-Data-Engineer-Professional ⏪を無料でダウンロード【 www.japancert.com 】ウェブサイトを入力するだけDatabricks-Certified-Data-Engineer-Professional最新な問題集
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.ted.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, wanderlog.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
ちなみに、GoShiken Databricks-Certified-Data-Engineer-Professionalの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1jr3WOglFiylFTlyPZdqISvOkMkWe5mEq