To keep you updated with latest changes in the Databricks-Certified-Professional-Data-Engineer test questions, we offer one-year free updates in the form of new questions according to the requirement of Databricks-Certified-Professional-Data-Engineer real exam. Updated Databricks-Certified-Professional-Data-Engineer vce dumps ensure the accuracy of learning materials and guarantee success of in your first attempt. Why not let our Databricks-Certified-Professional-Data-Engineer Dumps Torrent help you to pass your exam without spending huge amount of money.
| Section | Weight | Objectives |
|---|---|---|
| Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Cost & Performance Optimisation | 13% | - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) - Query optimization and caching |
| Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion - Connecting to diverse data sources - Schema inference and evolution |
| Monitoring and Alerting | 10% | - Setting up alerts and notifications - Performance and health monitoring - Pipeline observability and logging |
| Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Data encryption and masking - Access control and permissions |
| Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices - Troubleshooting pipelines and errors |
| Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Standardization and normalization - Data validation and quality checks |
| Data Modelling | 6% | - Medallion Architecture implementation - Delta Lake table design - Schema design and management |
| Data Governance | 7% | - Data lineage and metadata tracking - Unity Catalog management - Policy enforcement |
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Data transformation and aggregation - Integration with Databricks APIs and tools |
>> Databricks-Certified-Professional-Data-Engineer Simulated Test <<
In today's era, knowledge is becoming more and more important, and talents are becoming increasingly saturated. In such a tough situation, how can we highlight our advantages? It may be a good way to get the test Databricks-Certified-Professional-Data-Engineer certification. In fact, we always will unconsciously score of high and low to measure a person's level of strength, believe that we have experienced as a child by elders inquire achievement feeling, now, we still need to face the fact. Our society needs all kinds of comprehensive talents, the Databricks-Certified-Professional-Data-Engineer Latest Dumps can give you what you want, but not just some boring book knowledge, but flexible use of combination with the social practice. Therefore, it is necessary for us to pass all kinds of qualification examinations, the Databricks-Certified-Professional-Data-Engineer study practice question can bring you high quality learning platform.
NEW QUESTION # 76
A table in the Lakehouse namedcustomer_churn_paramsis used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
Answer: C
Explanation:
Explanation
The approach that would simplify the identification of the changed records is to replace the current overwrite logic with a merge statement to modify only those records that have changed, and write logic to make predictions on the changed records identified by the change data feed. This approach leverages the Delta Lake features of merge and change data feed, which are designed to handle upserts and track row-level changes in a Delta table12. By using merge, the data engineering team can avoid overwriting the entire table every night, and only update or insert the records that have changed in the source data. By using change data feed, the ML team can easily access the change events that have occurred in the customer_churn_params table, and filter them by operation type (update or insert) and timestamp. This way, they can only make predictions on the records that have changed in the past 24 hours, and avoid re-processing the unchanged records.
The other options are not as simple or efficient as the proposed approach, because:
Option A would require applying the churn model to all rows in the customer_churn_params table, which would be wasteful and redundant. It would also require implementing logic to perform an upsert into the predictions table, which would be more complex than using the merge statement.
Option B would require converting the batch job to a Structured Streaming job, which would involve changing the data ingestion and processing logic. It would also require using the complete output mode, which would output the entire result table every time there is a change in the source data, which would be inefficient and costly.
Option C would require calculating the difference between the previous model predictions and the current customer_churn_params on a key identifying unique customers, which would be computationally expensive and prone to errors. It would also require storing and accessing the previous predictions, which would add extra storage and I/O costs.
Option D would require modifying the overwrite logic to include a field populated by calling spark.sql.functions.current_timestamp() as data are being written, which would add extra complexity and overhead to the data engineering job. It would also require using this field to identify records written on a particular date, which would be less accurate and reliable than using the change data feed.
References: Merge, Change data feed
NEW QUESTION # 77
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame namedpredswith the schema "customer_id LONG, predictions DOUBLE, date DATE".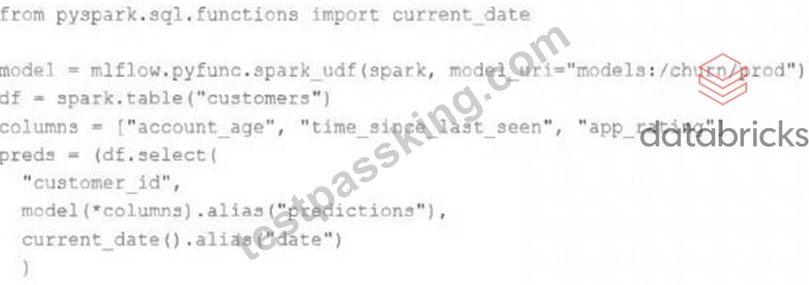
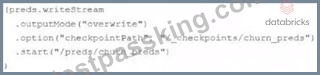
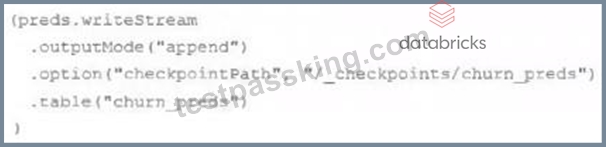
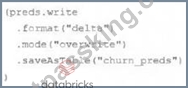
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
Answer: B
Explanation:
Explanation
This is the correct answer because it will save the predictions to a Delta Lake table with the ability to compare all predictions across time. The code uses the mergeInto method to perform an upsert operation, which means it will insert new records or update existing records based on the customer_id and date columns. This way, the table will always contain the latest predictions for each customer and date, and also keep the history of previous predictions. The code also uses a new job cluster to run the job, which will minimize the compute costs as it will be created and terminated for each run. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Upsert into a table using merge" section.
NEW QUESTION # 78
When you drop an external DELTA table using the SQL Command DROP TABLE table_name, how does it impact metadata(delta log, history), and data stored in the storage?
Answer: C
Explanation:
Explanation
The answer is Drops table from metastore, but keeps metadata and data in storage.
When an external table is dropped, only the table definition is dropped from metastore everything including data and metadata(Delta transaction log, time travel history) remains in the storage. Delta log is considered as part of metadata because if you drop a column in a delta table(managed or external) the column is not physically removed from the parquet files rather it is recorded in the delta log. The delta log becomes a key metadata layer for a Delta table to work.
Please see the below image to compare the external delta table and managed delta table and how they differ in how they are created and what happens if you drop the table.
Diagram Description automatically generated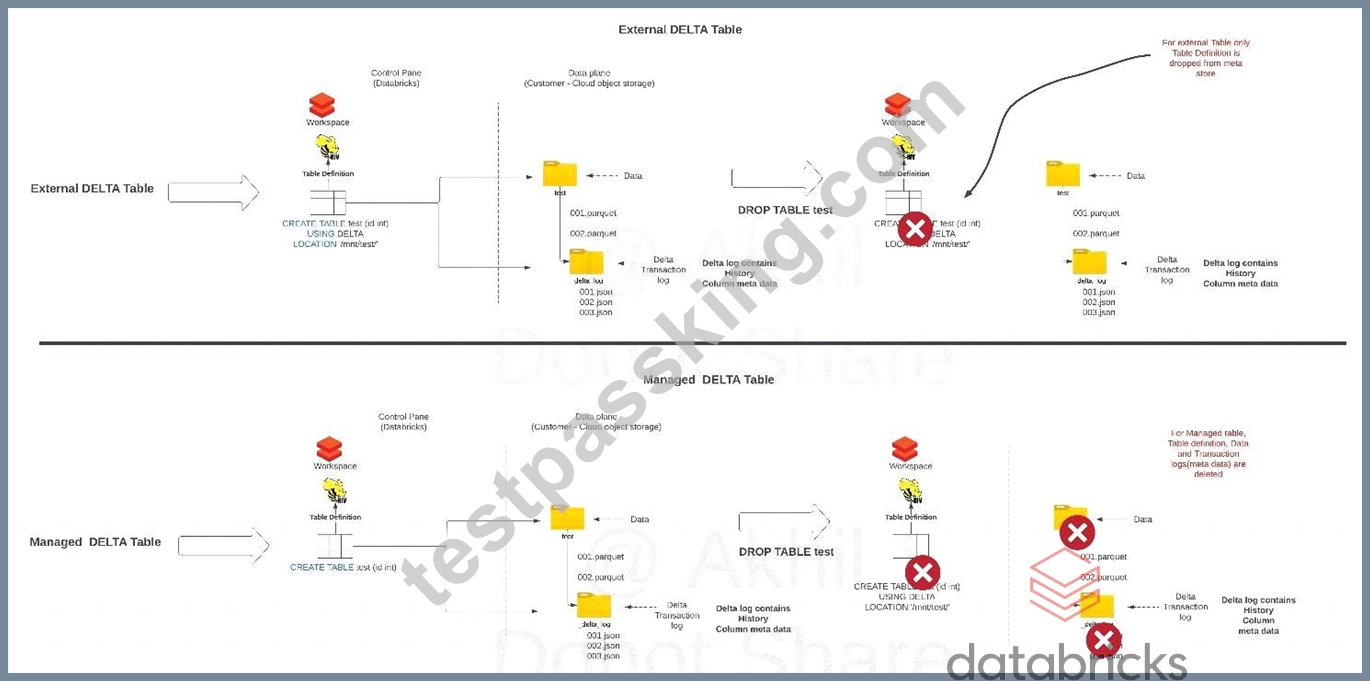
NEW QUESTION # 79
A data engineer has created a transactions Delta table on Databricks that should be used by the analytics team.
The analytics team wants to use the table with another tool that requires Apache Iceberg format.
What should the data engineer do?
Answer: D
Explanation:
Delta Lake introduced Delta Universal Format (Delta UniForm), which allows seamless interoperability between Delta Lake and Apache Iceberg. This means a Delta table can be converted into an Iceberg table while maintaining Delta capabilities.
Explanation of Each Option:
* (A) Require the analytics team to use a tool that supports Delta table
* Incorrect: While Delta Lake is widely used, requiring the team to change tools is not a flexible or scalable solution.
* (B) Enable uniform on the transactions table to 'iceberg' so that the table can be read as an Iceberg table
* Incorrect:
* The uniform feature must be enabled after conversion.
* You cannot directly enable uniform without first converting the table.
* (C) Create an Iceberg copy of the transactions Delta table which can be used by the analytics team
* Incorrect:
* Creating a separate Iceberg copy would duplicate storage and increase maintenance complexity.
* This is not necessary when Delta UniForm allows direct compatibility with Iceberg.
* (D) Convert the transactions Delta table to Iceberg and enable uniform so that the table can be read as a Delta table
* Correct:
* The best approach is to convert the existing Delta table to Iceberg using the Databricks Delta to Iceberg migration tools.
* After conversion, enabling uniform ensures the table remains accessible in both Delta and Iceberg formats.
Conclusion:
The best practice for interoperability between Delta and Iceberg is to convert the Delta table to Iceberg and enable uniform, ensuring cross-compatibility without data duplication.
Thus, Option (D) is the correct answer.
References:
Delta UniForm for Apache Iceberg - Databricks Documentation
Convert Delta to Iceberg - Databricks
NEW QUESTION # 80
Spill occurs as a result of executing various wide transformations. However, diagnosing spill requires one to proactively look for key indicators.
Where in the Spark UI are two of the primary indicators that a partition is spilling to disk?
Answer: C
Explanation:
In Apache Spark's UI, indicators of data spilling to disk during the execution of wide transformations can be found in the Stage's detail screen and the Query's detail screen. These screens provide detailed metrics about each stage of a Spark job, including information about memory usage and spill data. If a task is spilling data to disk, it indicates that the data being processed exceeds the available memory, causing Spark to spill data to disk to free up memory. This is an important performance metric as excessive spill can significantly slow down the processing.
Reference:
Apache Spark Monitoring and Instrumentation: Spark Monitoring Guide
Spark UI Explained: Spark UI Documentation
NEW QUESTION # 81
......
Our exam prep material is famous among Databricks exam candidates which help to polish the knowledge required to pass the Databricks Certified Professional Data Engineer Exam exam. The certification is organized by Databricks internationally. Our Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam questions are the most cost-effective as we understand that you need low-cost material but are authentic and updated. TestPassKing provides its Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions in three forms, one is PDF eBook, the second is practice exam software for Windows-based systems, and the third is an online practice test.
Databricks-Certified-Professional-Data-Engineer Free Exam Dumps: https://www.testpassking.com/Databricks-Certified-Professional-Data-Engineer-exam-testking-pass.html