VCE4Plus also offers a demo of the Microsoft DP-750 exam product which is absolutely free. Up to 1 year of free Implementing Data Engineering Solutions Using Azure Databricks (DP-750) questions updates are also available if in any case the sections of the Microsoft DP-750 Actual Test changes after your purchase. Lastly, we also offer a full refund guarantee according to terms and conditions if you do not get success in the Implementing Data Engineering Solutions Using Azure Databricks exam after using our DP-750 product.
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
>> Exam Dumps DP-750 Provider <<
Passing a certification exam means opening up a new and fascination phase of your professional career. VCE4Plus’s exam dumps enable you to meet the demands of the actual certification exam within days. Hence they are your real ally for establishing your career pathway and get your potential attested. If you want to check the quality of DP-750 certificate dumps, then go for free demo of the dumps and make sure that the quality of our questions and answers serve you the best. You are not required to pay any amount or getting registered with us for downloading free dumps.
NEW QUESTION # 51
You have an Azure Databricks workspace that contains a Delta table named Table 1. Table 1 has accumulated obsolete files.
You need to reduce storage costs. The solution must preserve 30 days of time travel history. Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,B
Explanation:
The correct answers are B and E.
The goal is to reduce storage costs while preserving 30 days of time travel. Two actions are needed:
Set delta.deletedFileRetentionDuration to a value aligned with the 30-day requirement (Option B). Note: the answer option states '10 days' which would be insufficient for 30-day time travel - in practice this property should be set to at least 30 days. This property defines the retention floor: VACUUM will not delete any file newer than this threshold.
Run VACUUM on Table1 (Option E). VACUUM physically removes unreferenced data files older than the retention duration from storage. Without running VACUUM, obsolete files accumulate indefinitely regardless of the retention property setting - the property tells VACUUM what to keep; VACUUM is what does the actual cleanup.
Option C (OPTIMIZE) compacts small files for better query performance but never deletes anything. Option D (logRetentionDuration) keeps the transaction log for time travel but doesn't free up the data file storage.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-vacuum
NEW QUESTION # 52
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
- Ensure that amount is always greater than 0.
- Prevent an update to Table1 from being committed when data that
violates rule1 is detected.
Which statement should you execute?
Answer: C
Explanation:
To ensure the data validation rule forces the pipeline update to abort and roll back transactions when data violates the condition, you must use a "fail" expectation operator. In Databricks Lakeflow Spark Declarative Pipelines (SDP), the command/syntax depends on whether your pipeline is written in Python or SQL.
Python Implementation
If your pipeline uses Python, apply the @dp.expect_or_fail decorator above your table definition (note: dp is the standard alias for the databricks.pipelines module in Lakeflow SDP):
dp.expect_or_fail("amount_greater_than_zero", "amount > 0")
Reference:
https://docs.databricks.com/aws/en/ldp/expectations
NEW QUESTION # 53
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1 You need to meet the following requirements:
* Records that violate rule! must NOT be written to Table1. but the pipeline must continue processing valid records.
* Data engineers must be able to review expectation metrics by using minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.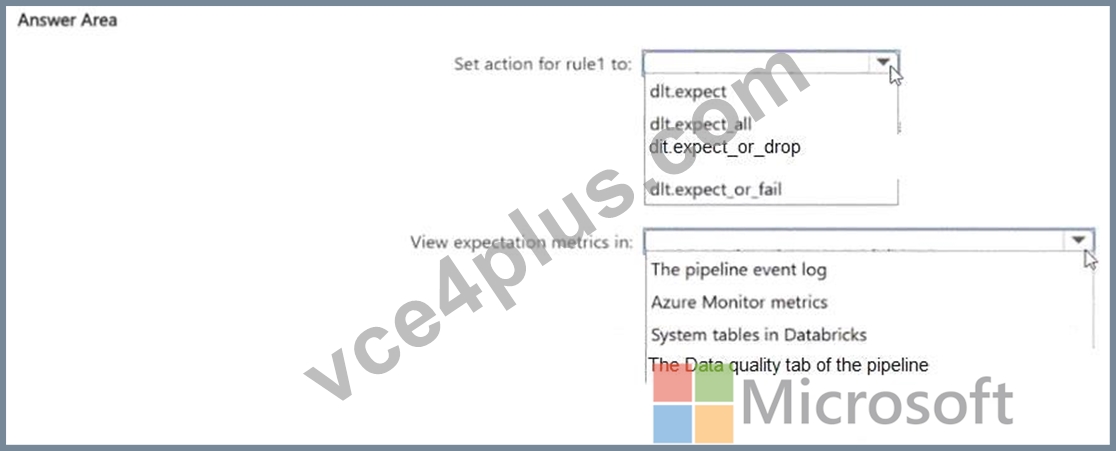
Answer:
Explanation: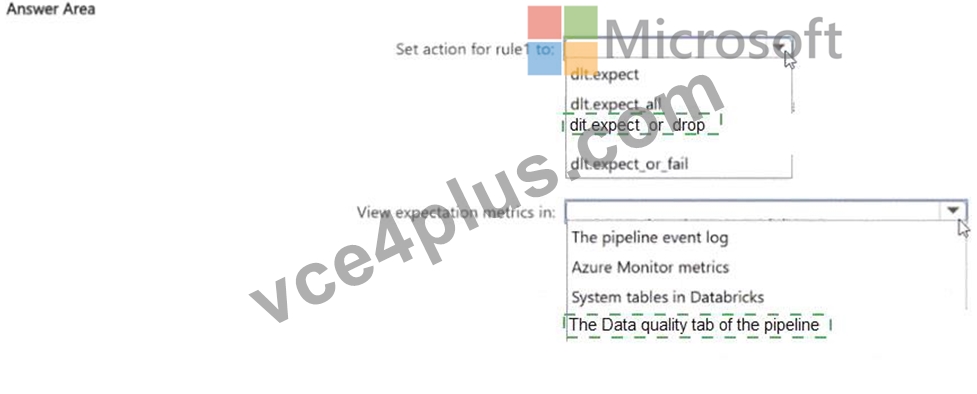
Explanation:
Two things are needed here:
For the rule enforcement: use @dlt.expect_or_drop. This drops any record that violates rule1 before it reaches Table1, while the pipeline continues processing all valid records. The table only ever receives clean data.
For reviewing metrics: the Lakeflow SDP Pipeline UI is the right tool - zero development effort required.
The pipeline graph shows expectation pass/fail counts directly on each table node, and the event log provides a detailed per-batch breakdown of how many records were dropped and why. Data engineers can inspect this at any time without writing additional monitoring queries or connecting external dashboards.
This combination is one of the strongest arguments for SDP over hand-coded Structured Streaming:
expectation observability is built in, not bolted on.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 54
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.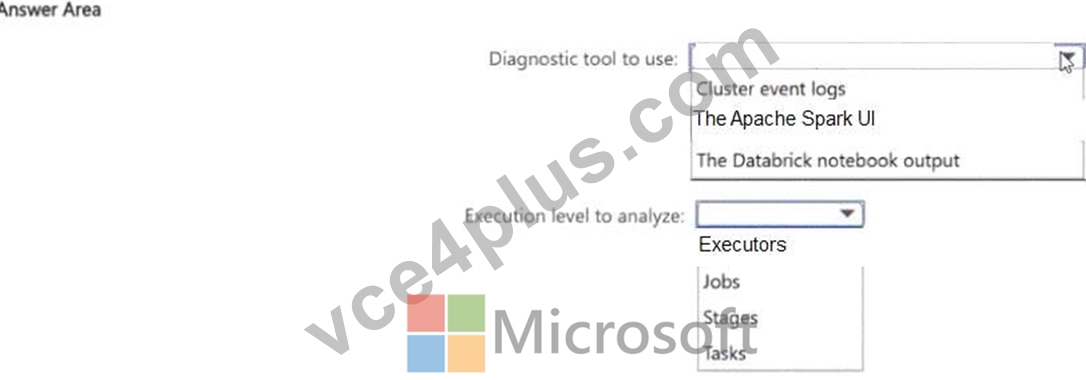
Answer:
Explanation: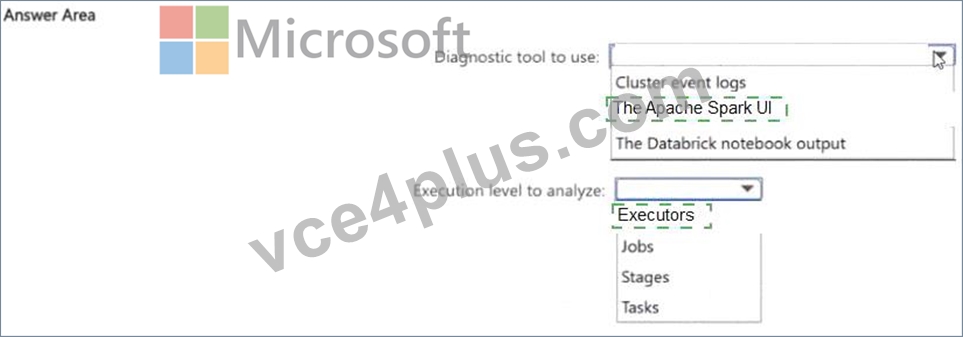
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it's accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it's processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that's data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
NEW QUESTION # 55
You have an Azure Databricks workspace.
Users report that a Databricks notebook that runs each day takes longer than expected to run.
When reading the Directed Acyclic Graph (DAG), you discover the following issues concerning the Apache Spark stage:
* Most tasks in the stage finish quickly.
* A few tasks in the stage run more slowly.
* The CPU is underutilized at the end of the stage.
* The slow tasks process many more input records.
* The stage is blocked while it waits for the few slow tasks.
What is the root cause of the issues?
Answer: A
NEW QUESTION # 56
......
Have you ever noticed that people who prepare themselves for Microsoft DP-750 certification exam do not need to negotiate their salaries for a higher level, they just get it after they are Microsoft DP-750 Certified? The reason behind this fact is that they are considered the most deserving candidates for that particular job.
DP-750 Test Pattern: https://www.vce4plus.com/Microsoft/DP-750-valid-vce-dumps.html