Snowflake DAA-C01試験対策書、DAA-C01日本語版試験解答

2026年Pass4Testの最新DAA-C01 PDFダンプおよびDAA-C01試験エンジンの無料共有:https://drive.google.com/open?id=1u4gYa4JGGzFe8k2aWVxoBn5mfMVGNV5h
Pass4Test製品を購入する前に、DAA-C01学習ツールを無料でダウンロードして試用できます。 Webサイト上の製品のページでデモを提供しているため、タイトルの一部とDAA-C01テストトレントの形式を理解できます。 Webサイトで製品のページにアクセスすると、更新時間、3つのバージョンを選択できます。 DAA-C01ガイド急流の答えとタイトルと内容のフォームを確認してください。弊社のDAA-C01テストトレントを購入する価値があると思われる場合は、お好みのバージョンを選択できます。
Snowflake DAA-C01 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Perform Predictive Analysis | 5–10% | - Using Snowflake ML and built-in analytics
- Forecasting and predictive modeling
|
| Topic 2: Prepare and Present Data | 10–15% | - Data visualization and reporting
- Snowsight dashboards and sharing results
- Align outputs with business requirements
|
| Topic 3: Build and Troubleshoot Advanced SQL Queries | 20–25% | - Query optimization and troubleshooting
- Semi-structured data processing
- Complex joins, subqueries, window functions
|
| Topic 4: Use Built-in Functions and Create UDFs | 10–15% | - User-Defined Functions (UDFs)
- Scalar, aggregate, table, system functions
|
| Topic 5: Prepare and Load Data | 15–20% | - File formats: CSV, JSON, Parquet, Avro
- Data ingestion methods: COPY INTO, stages, Snowpipe
- External tables and data validation
|
| Topic 6: Perform Simple Data Transformations for Analysis | 15–20% | - Views, materialized views, CTEs
- Handling NULLs and structuring datasets
- Data cleansing, standardization, type conversion
|
| Topic 7: Perform Descriptive and Diagnostic Analysis | 10–15% | - Anomaly detection and root cause analysis
- Exploratory and ad-hoc analysis
- Statistical summarization and trend analysis
|
>> Snowflake DAA-C01試験対策書 <<
DAA-C01日本語版試験解答 & DAA-C01問題と解答
IT認定試験の中でどんな試験を受けても、Pass4TestのDAA-C01試験参考資料はあなたに大きなヘルプを与えることができます。それは Pass4TestのDAA-C01問題集には実際の試験に出題される可能性がある問題をすべて含んでいて、しかもあなたをよりよく問題を理解させるように詳しい解析を与えますから。真剣にPass4TestのSnowflake DAA-C01問題集を勉強する限り、受験したい試験に楽に合格することができるということです。
Snowflake SnowPro Advanced: Data Analyst Certification Exam 認定 DAA-C01 試験問題 (Q12-Q17):
質問 # 12
You have a large CSV file containing customer transaction data that you need to load into Snowflake using Snowsight. The CSV file is located in an AWS S3 bucket. The file contains fields like 'transaction id', 'customer id', 'transaction date', and 'transaction amount. However, the 'transaction_date' column is in the format 'YYYYMMDD' and you need to convert it to Snowflake's DATE format ('YYYY-MM-DD') during the load process. Which of the following steps should you take in Snowsight to accomplish this efficiently and correctly?
- A. Create an external table pointing to the S3 bucket. Then, create a view on top of the external table with the 'TO_DATE(transaction_date, 'YYYYMMDD')' transformation applied. Finally, create a new table using 'CREATE TABLE AS SELECT from the view.
- B. Load the CSV file into Snowflake without any transformation. Write a stored procedure to transform the 'transaction_date' column and schedule the stored procedure to run periodically.
- C. Load the data into a staging table with all columns as VARCHAR. Then, create a new table with the desired schema. Finally, use a 'CREATE TABLE AS SELECT (CTAS) statement with 'TO DATE(transaction_date, to transform and load the data from the staging table to the final table.
- D. Create a new table in Snowflake with the desired schema (including DATE data type for 'transaction_date'). Use Snowsight's 'Load Data' wizard to load the CSV file, selecting the appropriate file format options and using a computed column expression 'TO_DATE(transaction_date, 'YYYYMMDD')' for the 'transaction date' column.
- E. Use Snowsight's 'Load Data' wizard to load the CSV file directly into a table with the required schema. After loading, execute an "UPDATE statement to convert the 'transaction_date' column using 'TO DATE(transaction_date, YYYYMMDD'V.
正解:D
解説:
Option A is the most efficient and correct approach. Snowsight's 'Load Data' wizard allows you to specify transformations during the load process using computed columns, which is more performant than loading into a staging table or updating after loading. Options B, C, D and E are functional but less efficient due to the extra steps involved. Using external tables for initial loading then CTAS can be good for exploration but not as direct as option A. Updates should generally be avoided on large datasets after loading when you have a chance to transform during load.
質問 # 13
A marketing company is analyzing customer purchase data stored in Snowflake to understand which customer demographics are most likely to purchase a newly launched product. The 'CUSTOMERS table has columns: 'customer_id', 'age' , 'gender' , 'location' , and 'household income'. The 'PURCHASES' table has columns: 'customer_id', 'purchase_date', and 'product id'. Which SQL query would most effectively identify the top three age groups with the highest purchase rate for the new product (product_id = 'NEW PRODUCT')?
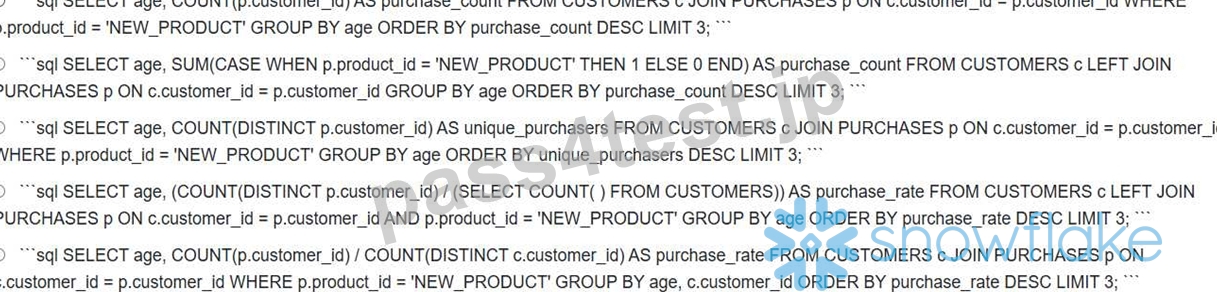
- A. Option A
- B. Option D
- C. Option E
- D. Option B
- E. Option C
正解:B
解説:
Option D is the most effective because it calculates the purchase rate by dividing the count of distinct customers who purchased the new product by the total number of customers in each age group. This provides a normalized purchase rate for each age group, allowing for a fair comparison regardless of the size of each group. Options A and C only provide the raw count of purchases or unique purchasers, which doesn't account for the size of each age group. Option B uses 'SUM(CASE...V , which can work, but is less efficient than using 'COUNT(DISTINCTV in combination with a left join to account for all customers, even those who didn't make any purchases. Option E would produce an incorrect rate as it is dividing a customer's count by the distinct count of each customer, resulting in a rate close to 1.0 for each customer that made a purchase.
質問 # 14
How does incorporating visualizations in reports and dashboards aid in presenting data for business use analyses?
- A. Presenting data visually doesn't impact business use analyses.
- B. It limits data presentation to textual formats only.
- C. Visualizations enhance data comprehension for effective analysis.
- D. Visualizations complicate data representation, hindering analysis.
正解:C
解説:
Visualizations enhance data comprehension, aiding effective analysis in business use scenarios.
質問 # 15
You are tasked with building a data ingestion pipeline to retrieve data from a transactional database using Change Data Capture (CDC).The source database is a MySQL instance. Which of the following approaches is MOST suitable for efficiently retrieving and loading the changed data into Snowflake while minimizing latency?
- A. Use a third-party CDC tool that supports MySQL as a source and Snowflake as a target. Configure the tool to capture changes from the MySQL binary logs and stream them directly into Snowflake tables.
- B. Create a Snowpark Python UDF that connects to the MySQL database, reads the binary logs, and applies the changes directly to Snowflake tables.
- C. Use a scheduled task to periodically query the MySQL database for records modified within a specific time window and load them into Snowflake using COPY INTO. Implement a timestamp-based or version-based change tracking mechanism in the query.
- D. Configure MySQL binary log replication to a cloud storage location (e.g., AWS S3, Azure Blob Storage, Google Cloud Storage) and use Snowpipe to continuously ingest the binary log files into Snowflake.
- E. Create a Snowflake external table pointing to the MySQL database. Use the external table to read data directly from the MySQL database into Snowflake tables.
正解:A、D
解説:
Options B and C are the most efficient and reliable for CDC. Option B leverages the MySQL binary logs directly. Configuring replication to cloud storage and using Snowpipe provides a continuous and near real-time ingestion pipeline. Option C, using a dedicated CDC tool, offers a managed solution that handles the complexities of binary log parsing, change tracking, and data transformation. Option A is less efficient due to the need for periodic polling and potential data loss if changes occur between polls. Option D involves significant coding complexity and potential performance issues. Option E is generally not recommended for transactional data due to performance limitations.
質問 # 16
You are designing a data ingestion pipeline for a financial institution. The pipeline loads transaction data from various sources into a Snowflake table named 'TRANSACTIONS. The 'TRANSACTIONS table includes columns such as TRANSACTION , 'ACCOUNT ID', 'TRANSACTION DATE, 'TRANSACTION AMOUNT, and 'TRANSACTION TYPE. The data is loaded in micro- batches using Snowpipe. Due to potential source system errors and network issues, duplicate records with the same 'TRANSACTION ID' are occasionally ingested. You need to ensure data integrity by preventing duplicate 'TRANSACTION_ID' values in the 'TRANSACTIONS' table while minimizing the impact on ingestion performance. Which of the following approaches is the MOST efficient and reliable way to handle this deduplication requirement in Snowflake, considering data integrity and performance?
- A. Create a staging table with the same schema as 'TRANSACTIONS'. Use a 'MERGE' statement within the Snowpipe load process to insert new records from the incoming data into the 'TRANSACTIONS' table, only if the 'TRANSACTION ID does not already exist. Define 'TRANSACTION ID' as the primary key in the staging table. Use clustering on 'TRANSACTION_ID on the target 'TRANSACTIONS' table.
- B. Use a materialized view built on top of the TRANSACTIONS table that selects distinct transaction ids. This ensures that querying through the materialized view returns no duplicates.
- C. Create a stream on the 'TRANSACTIONS' table and use it to identify newly inserted rows. Then, use a merge statement to insert new, distinct transactions into a separate staging table. Finally, periodically truncate the original 'TRANSACTIONS table and load the deduped data from the staging table.
- D. Create a scheduled task that runs every hour to identify and delete duplicate records based on 'TRANSACTION ID. The task will use a SQL query to find duplicate ' TRANSACTION ID values and remove the older entries.
- E. Define as the primary key on the 'TRANSACTIONS' table. Snowflake will automatically reject any duplicate inserts during Snowpipe ingestion.
正解:A
解説:
Option E provides the most performant and robust solution. Although Snowflake doesn't enforce primary key constraints, defining them on the staging table and leveraging a 'MERGE' statement during the Snowpipe load process allows for efficient deduplication. Clustering on TRANSACTION_I[Y on the target table also helps with performance. A regular task would be less efficient and introduce latency. Snowflake does not automatically reject duplicate inserts based on defined primary keys (option A). Materialized views don't prevent duplicate data from entering the base table. Option C is possible but more complex to implement than a MERGE statement.
質問 # 17
......
業種別の人々は自分が将来何か成績を作るようにずっと努力しています。IT業種で勤めているあなたもきっとずっと努力して自分の技能を向上させているでしょう。では、最近最も人気があるSnowflakeのDAA-C01認定試験の認証資格を既に取りましたか。DAA-C01試験に対して、あなたはいくらぐらい分かっていますか。もしこの試験に関連する知識が非常に不足であると同時にこの試験に合格したい場合、あなたはどうするつもりですか。そうですか。どうするか全然分からないですか。そうしても焦らないでください。Pass4Testはあなたに援助を提供します。
DAA-C01日本語版試験解答: https://www.pass4test.jp/DAA-C01.html
- DAA-C01参考書勉強 🐲 DAA-C01復習範囲 🛰 DAA-C01資格トレーニング 😼 時間限定無料で使える➤ DAA-C01 ⮘の試験問題は[ www.passtest.jp ]サイトで検索DAA-C01日本語対策問題集
- DAA-C01試験の準備方法 | 真実的なDAA-C01試験対策書試験 | 認定するSnowPro Advanced: Data Analyst Certification Exam日本語版試験解答 🛹 今すぐ➤ www.goshiken.com ⮘で➥ DAA-C01 🡄を検索し、無料でダウンロードしてくださいDAA-C01資格トレーニング
- DAA-C01試験の準備方法|素晴らしいDAA-C01試験対策書試験|正確的なSnowPro Advanced: Data Analyst Certification Exam日本語版試験解答 😰 最新▷ DAA-C01 ◁問題集ファイルは▶ www.xhs1991.com ◀にて検索DAA-C01的中率
- DAA-C01試験の準備方法 | 真実的なDAA-C01試験対策書試験 | 認定するSnowPro Advanced: Data Analyst Certification Exam日本語版試験解答 🥡 ウェブサイト[ www.goshiken.com ]を開き、☀ DAA-C01 ️☀️を検索して無料でダウンロードしてくださいDAA-C01的中問題集
- DAA-C01試験問題集、DAA-C01問題集ガイド、DAA-C01ベスト問題 🆎 時間限定無料で使える【 DAA-C01 】の試験問題は「 www.xhs1991.com 」サイトで検索DAA-C01認定資格試験問題集
- DAA-C01受験準備 🙆 DAA-C01試験勉強過去問 🐣 DAA-C01技術内容 🤟 ▛ www.goshiken.com ▟サイトで✔ DAA-C01 ️✔️の最新問題が使えるDAA-C01復習過去問
- 試験の準備方法-効率的なDAA-C01試験対策書試験-検証するDAA-C01日本語版試験解答 🌑 検索するだけで✔ www.xhs1991.com ️✔️から➠ DAA-C01 🠰を無料でダウンロードDAA-C01受験資格
- DAA-C01参考書勉強 🕉 DAA-C01関連資格知識 🦩 DAA-C01受験練習参考書 ⚔ { www.goshiken.com }で⇛ DAA-C01 ⇚を検索して、無料でダウンロードしてくださいDAA-C01ファンデーション
- DAA-C01関連資格知識 🌠 DAA-C01復習過去問 🚖 DAA-C01無料ダウンロード 👓 ➽ www.xhs1991.com 🢪サイトにて最新【 DAA-C01 】問題集をダウンロードDAA-C01関連復習問題集
- 正確的なDAA-C01試験対策書 - 合格スムーズDAA-C01日本語版試験解答 | ハイパスレートのDAA-C01問題と解答 🍔 検索するだけで⏩ www.goshiken.com ⏪から▶ DAA-C01 ◀を無料でダウンロードDAA-C01受験練習参考書
- 信頼できるDAA-C01試験対策書一回合格-素晴らしいDAA-C01日本語版試験解答 ⚛ ⮆ www.xhs1991.com ⮄を入力して《 DAA-C01 》を検索し、無料でダウンロードしてくださいDAA-C01関連日本語内容
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! Pass4Test DAA-C01ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1u4gYa4JGGzFe8k2aWVxoBn5mfMVGNV5h