The Reason to Trust on DumpStillValid Databricks Certified-Data-Engineer-Professional Exam Questions

After purchasing our Certified-Data-Engineer-Professional exam questions, we provide email service and online service you can contact us any time within one year. Also we provide one year free updates of Certified-Data-Engineer-Professional learning guide if we release new version in one year, our system will send the link of the latest version of our Certified-Data-Engineer-Professional training braindump to your email box for your downloading. It is free of charge. And you can save a lot of time and money for our updates of Certified-Data-Engineer-Professional study guide. We make sure that you will have a happy free-shopping experience.
| Section | Objectives |
|---|
| Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
|
| Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Apply anonymization and pseudonymization techniques
- 3. Use ACLs to secure workspace objects and enforce least privilege
|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Configure Databricks-to-Databricks Sharing
- 3. Share live Lakehouse data with external computing platforms
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest data from message buses and cloud storage
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake
|
| Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
- Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use Query Profiler and Spark UI to monitor workloads
|
| Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Understand deletion vectors and liquid clustering
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- Building and Testing ETL Pipelines
- 1. Configure environments, dependencies, memory, and retry behavior
- 2. Use APPLY CHANGES APIs for change data capture
- 3. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 4. Develop unit and integration tests for data processing code
- 5. Use control flow operators in pipeline components
- 6. Compare streaming tables and materialized views
- 7. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 8. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
>> Certified-Data-Engineer-Professional Exam Vce Format <<
Certified-Data-Engineer-Professional Latest Test Materials & Certified-Data-Engineer-Professional Pdf Files
After taking a bird's eye view of applicants' issues, DumpStillValid has decided to provide them with the real Certified-Data-Engineer-Professional Questions. These Certified-Data-Engineer-Professional dumps pdf is according to the new and updated syllabus so they can prepare for Certified-Data-Engineer-Professional certification anywhere, anytime, with ease. A team of professionals has made the product of DumpStillValid after much hard work with their complete potential so the candidates can prepare for Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice test in a short time.
Databricks Certified Data Engineer Professional Sample Questions (Q189-Q194):
NEW QUESTION # 189
The data architect has mandated that all tables in the Lakehouse should be configured as external Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. When the workspace is being configured, make sure that external cloud object storage has been mounted.
- B. Whenever a table is being created, make sure that the location keyword is used.
- C. When configuring an external data warehouse for all table storage. leverage Databricks for all ELT.
- D. When tables are created, make sure that the external keyword is used in the create table statement.
- E. Whenever a database is being created, make sure that the location keyword is used
Answer: B
Explanation:
This is the correct answer because it ensures that this requirement is met. The requirement is that all tables in the Lakehouse should be configured as external Delta Lake tables. An external table is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created by using the location keyword to specify the path to an existing directory in a cloud storage system, such as DBFS or S3. By creating external tables, the data engineering team can avoid losing data if they drop or overwrite the table, as well as leverage existing data without moving or copying it.
NEW QUESTION # 190
A data engineering team is collaborating on a Databricks project where each team member needs to develop and test code independently before merging changes into the main branch.
They want to avoid accidental overwrites or branch switching issues while ensuring that all work is version- controlled and can be integrated into their CI/CD pipeline.
How should the data engineer achieve collaboration?
- A. Team members edit notebooks directly in the workspace's shared folder and periodically copy changes into a Git folder for version control.
- B. Team members use the Databricks CLI to clone the Git repository and perform Git operations from a cluster's web terminal.
- C. Each team member creates their own Databricks Git folder, mapped to the same remote Git repository, and works in their own development branch within their personal folder.
- D. All team members work in the same Databricks Git folder and perform Git operations (pull, push, commit, branch switching) directly in that shared folder.
Answer: C
Explanation:
Using separate Databricks Git folders per user mapped to the same remote repository allows each team member to work independently on their own branch without interfering with others.
This prevents accidental overwrites or branch conflicts while ensuring all changes are version- controlled and easily integrated into CI/CD workflows.
NEW QUESTION # 191
A data engineer is developing a Lakeflow Declarative Pipeline (LDP) using a Databricks notebook directly connected to their pipeline. After adding new table definitions and transformation logic in their notebook, they want to check for any syntax errors in the pipeline code without actually processing data or running the pipeline. How should the data engineer perform this syntax check?
- A. Switch to a workspace file instead of a notebook to access validation and diagnostics tools.
- B. Disconnect the notebook from the pipeline and reconnect it to a compute cluster to access code validation features.
- C. Open the web terminal from the notebook and run a shell command to validate the pipeline code.
- D. Use the "Validate" option in the notebook to check for syntax errors.
Answer: D
Explanation:
Databricks provides a "Validate" option within the Lakeflow Declarative Pipeline development interface that checks pipeline configurations, transformations, and syntax errors before actual execution.
This feature parses and validates the pipeline logic defined in notebooks or workspace files to ensure correctness and consistency of table dependencies, DLT (Delta Live Table) syntax, and schema references.
The validation process does not process or move any data, making it ideal for testing new configurations before deployment.
Using the shell terminal (B) or workspace files (D) does not perform integrated pipeline-level validation, while reconnecting to compute clusters (C) is unrelated to syntax checks. Therefore, the verified and correct approach is A.
NEW QUESTION # 192
A view is registered with the following code:
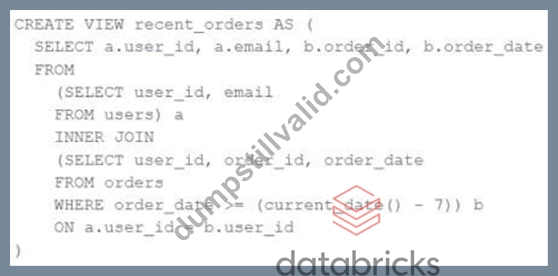
Both users and orders are Delta Lake tables.
Which statement describes the results of querying recent_orders?
- A. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
- B. All logic will execute when the table is defined and store the result of joining tables to the DBFS; this stored data will be returned when the table is queried.
- C. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
- D. The versions of each source table will be stored in the table transaction log; query results will be saved to DBFS with each query.
Answer: A
NEW QUESTION # 193
A production workload incrementally applies updates from an external Change Data Capture feed to a Delta Lake table as an always-on Structured Stream job. When data was initially migrated for this table, OPTIMIZE was executed and most data files were resized to 1 GB. Auto Optimize and Auto Compaction were both turned on for the streaming production job. Recent review of data files shows that most data files are under 64 MB, although each partition in the table contains at least 1 GB of data and the total table size is over 10 TB.
Which of the following likely explains these smaller file sizes?
- A. Databricks has autotuned to a smaller target file size based on the overall size of data in the table
- B. Z-order indices calculated on the table are preventing file compaction C Bloom filler indices calculated on the table are preventing file compaction
- C. Databricks has autotuned to a smaller target file size based on the amount of data in each partition
- D. Databricks has autotuned to a smaller target file size to reduce duration of MERGE operations
Answer: D
Explanation:
This is the correct answer because Databricks has a feature called Auto Optimize, which automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones and sorting data within each file by a specified column. However, Auto Optimize also considers the trade- off between file size and merge performance, and may choose a smaller target file size to reduce the duration of merge operations, especially for streaming workloads that frequently update existing records. Therefore, it is possible that Auto Optimize has autotuned to a smaller target file size based on the characteristics of the streaming production job.
NEW QUESTION # 194
......
DumpStillValid's Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions contain Databricks Certified-Data-Engineer-Professional real questions and answers that have been compiled and verified by Databricks specialists in the field. This demonstrates that the real questions and answers in the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) material are legitimate for the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice exam. The Databricks Certified-Data-Engineer-Professional practice questions are intended to help you easily and confidently clear the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional).
Certified-Data-Engineer-Professional Latest Test Materials: https://www.dumpstillvalid.com/Certified-Data-Engineer-Professional-prep4sure-review.html
- Certified-Data-Engineer-Professional Dumps Collection ⏬ Clearer Certified-Data-Engineer-Professional Explanation 🦐 Clearer Certified-Data-Engineer-Professional Explanation 🚲 Download ⏩ Certified-Data-Engineer-Professional ⏪ for free by simply entering ▷ www.prepawaypdf.com ◁ website 🎽Test Certified-Data-Engineer-Professional Cram Pdf
- Latest Certified-Data-Engineer-Professional Exam Forum 🪀 Clearer Certified-Data-Engineer-Professional Explanation ✈ Certified-Data-Engineer-Professional Latest Test Testking 🎭 The page for free download of ⮆ Certified-Data-Engineer-Professional ⮄ on ▶ www.pdfvce.com ◀ will open immediately 🐔Certified-Data-Engineer-Professional Dumps Collection
- 100% Pass Authoritative Databricks - Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Exam Vce Format 💱 Download ➠ Certified-Data-Engineer-Professional 🠰 for free by simply searching on ☀ www.practicevce.com ️☀️ 🤒Certified-Data-Engineer-Professional Latest Dumps Questions
- Real Databricks Certified-Data-Engineer-Professional Exam Question In PDF 🚆 Immediately open ▛ www.pdfvce.com ▟ and search for 「 Certified-Data-Engineer-Professional 」 to obtain a free download 😀Printable Certified-Data-Engineer-Professional PDF
- Certified-Data-Engineer-Professional Actual Questions 👘 Certified-Data-Engineer-Professional Test Question 🛄 Valid Certified-Data-Engineer-Professional Exam Materials 🌘 ▛ www.torrentvce.com ▟ is best website to obtain { Certified-Data-Engineer-Professional } for free download 🐭Certified-Data-Engineer-Professional Latest Dumps Questions
- Valid Certified-Data-Engineer-Professional Exam Experience 🧦 Valid Certified-Data-Engineer-Professional Exam Bootcamp 🦮 Certified-Data-Engineer-Professional Valid Dumps Demo 🧚 Search for ▶ Certified-Data-Engineer-Professional ◀ on ➽ www.pdfvce.com 🢪 immediately to obtain a free download 🧺Certified-Data-Engineer-Professional Latest Test Testking
- Valid Certified-Data-Engineer-Professional Exam Materials 🦱 Test Certified-Data-Engineer-Professional Cram Pdf 🕯 Latest Certified-Data-Engineer-Professional Exam Questions 🚝 The page for free download of ➤ Certified-Data-Engineer-Professional ⮘ on ➠ www.examcollectionpass.com 🠰 will open immediately 🔧Latest Certified-Data-Engineer-Professional Exam Questions
- 2026 Certified-Data-Engineer-Professional Exam Vce Format Pass Certify | Efficient Certified-Data-Engineer-Professional Latest Test Materials: Databricks Certified Data Engineer Professional 🖕 Download ▛ Certified-Data-Engineer-Professional ▟ for free by simply entering 【 www.pdfvce.com 】 website 🤬Latest Certified-Data-Engineer-Professional Exam Forum
- Realistic Certified-Data-Engineer-Professional Exam Vce Format - Easy and Guaranteed Certified-Data-Engineer-Professional Exam Success 😽 Search for ⮆ Certified-Data-Engineer-Professional ⮄ and download it for free immediately on ▷ www.pdfdumps.com ◁ 🤹Valid Certified-Data-Engineer-Professional Exam Materials
- Printable Certified-Data-Engineer-Professional PDF 🏤 Printable Certified-Data-Engineer-Professional PDF 🛩 Certified-Data-Engineer-Professional Accurate Answers 👷 Search for 《 Certified-Data-Engineer-Professional 》 and download it for free immediately on ▶ www.pdfvce.com ◀ 🌾Latest Certified-Data-Engineer-Professional Exam Test
- Certified-Data-Engineer-Professional Actual Questions ↙ Certified-Data-Engineer-Professional Actual Questions 🥾 New Certified-Data-Engineer-Professional Braindumps Sheet 🎽 Open ➤ www.dumpsmaterials.com ⮘ and search for 「 Certified-Data-Engineer-Professional 」 to download exam materials for free 🛫Certified-Data-Engineer-Professional Latest Dumps Questions
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, knowyourmeme.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes