実際的なDP-700技術問題試験-試験の準備方法-ユニークなDP-700試験解答

BONUS!!! JPNTest DP-700ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1nZLZ_3dOizzHbguqSCaVEsN38t519cKJ
どんなに宣伝しても、あなたの自身体験は一番重要なことです。我々社のJPNTestからMicrosoft DP-700問題集デモを無料にダウンロードできます。多くの受験生は試験に合格できましたのを助けるMicrosoft DP-700ソフト版問題はあなたの大好きになります。DP-700問題集を使用してから、あんたはIT業界でのエリートになります。
Microsoft DP-700 Exam Overview:
| Certification Vendor: | Microsoft |
|---|
| Exam Name: | Implementing Data Engineering Solutions Using Microsoft Fabric |
|---|
| Exam Number: | DP-700 |
|---|
| Exam Price: | $165 USD |
|---|
| Available Languages: | Japanese, Portuguese (Brazil), German, Chinese (Simplified), English, Spanish, French, Korean |
|---|
| Passing Score: | 700 (scaled score 100–1000) |
|---|
| Exam Format: | Multiple select, Scenario-based, Multiple choice, Case studies, Interactive items |
|---|
| Real Exam Qty: | 50–60 |
|---|
| Certificate Validity Period: | 1 year |
|---|
| Related Certifications: | Microsoft Certified: Azure Data Engineer Associate
Microsoft Certified: Power BI Data Analyst Associate |
|---|
| Exam Duration: | 100 minutes |
|---|
| Recommended Training: | Microsoft Learn: Implementing Data Engineering Solutions Using Microsoft Fabric
Microsoft Fabric Documentation |
|---|
| Exam Registration: | Pearson VUE Registration
Microsoft Official Exam Registration |
|---|
| Sample Questions: | Microsoft DP-700 Sample Questions |
|---|
| Exam Way: | Online proctored or onsite testing center |
|---|
| Pre Condition: | No mandatory prerequisites; recommended experience with data integration, transformation, SQL, PySpark, KQL, and Microsoft Fabric |
|---|
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/dp-700 |
|---|
>> DP-700技術問題 <<
DP-700試験解答 & DP-700ミシュレーション問題
Microsoft DP-700資格認定はバッジのような存在で、あなたの所有する専業技術と能力を上司に直ちに知られさせます。次のジョブプロモーション、プロジェクタとチャンスを申し込むとき、Microsoft DP-700資格認定はライバルに先立つのを助け、あなたの大業を成し遂げられます。
Microsoft DP-700 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - Monitor and optimize an analytics solution: This section of the exam measures the skills of Data Analysts in monitoring various components of analytics solutions in Microsoft Fabric. It focuses on tracking data ingestion, transformation processes, and semantic model refreshes while configuring alerts for error resolution. One skill to be measured is identifying performance bottlenecks in analytics workflows.
|
| トピック 2 | - Implement and manage an analytics solution: This section of the exam measures the skills of Microsoft Data Analysts regarding configuring various workspace settings in Microsoft Fabric. It focuses on setting up Microsoft Fabric workspaces, including Spark and domain workspace configurations, as well as implementing lifecycle management and version control. One skill to be measured is creating deployment pipelines for analytics solutions.
|
| トピック 3 | - Ingest and transform data: This section of the exam measures the skills of Data Engineers that cover designing and implementing data loading patterns. It emphasizes preparing data for loading into dimensional models, handling batch and streaming data ingestion, and transforming data using various methods. A skill to be measured is applying appropriate transformation techniques to ensure data quality.
|
Microsoft Implementing Data Engineering Solutions Using Microsoft Fabric 認定 DP-700 試験問題 (Q92-Q97):
質問 # 92
You have a table in a Fabric lakehouse that contains the following data.
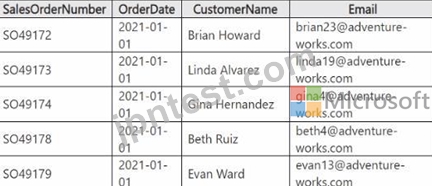
You have a notebook that contains the following code segment.

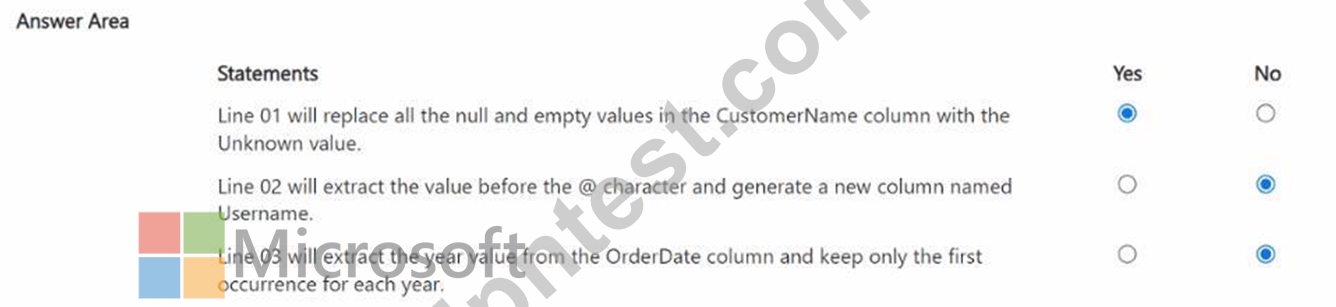
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
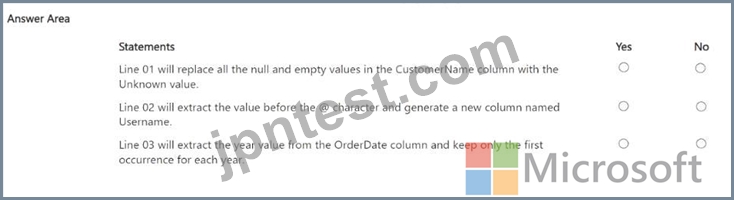
正解:
解説:
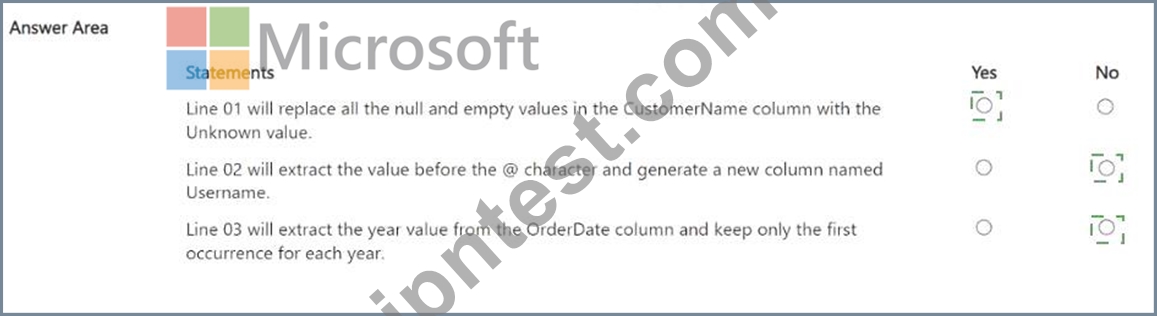
Explanation:
質問 # 93
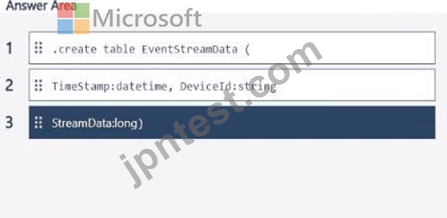
You have a Fabric workspace that contains an eventhouse named Eventhouse1.
In Eventhouse1, you plan to create a table named DeviceStreamData in a KQL database. The table will contain data based on the following sample.
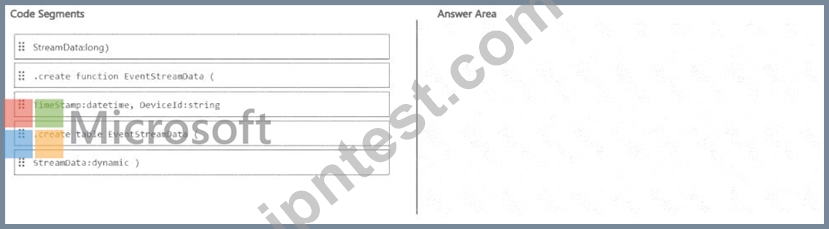
正解:
解説:
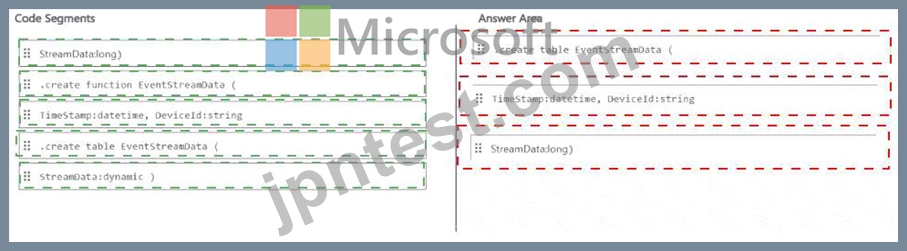
Explanation:
質問 # 94
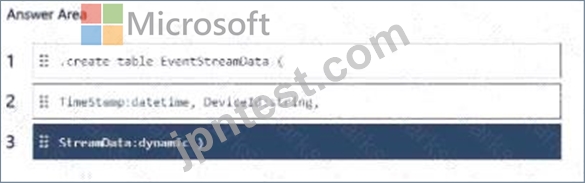
You have Fabric workspace that contains eventhouse named Eventhouse1.
In Eventhouse1, you plan to create a table named EventStreamData in a KQL database. The table will contain data based on the following sample.
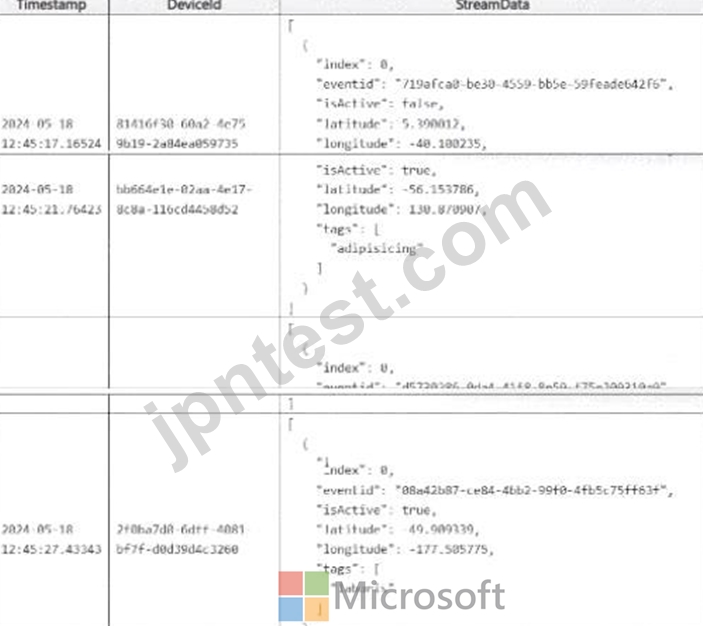
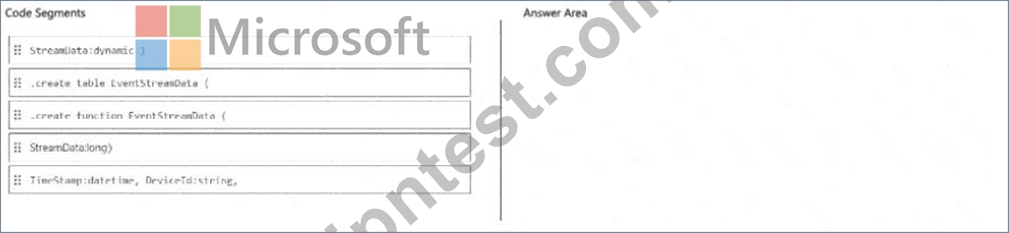
正解:
解説:
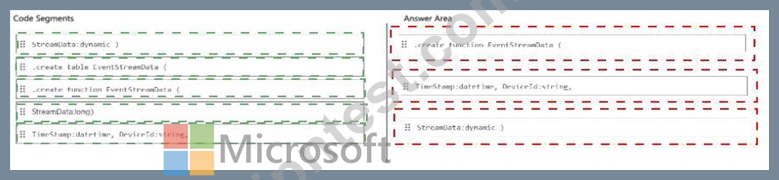
Explanation:
質問 # 95
You are developing a data engineering solution in Fabric by using Apache Spark.
You need to monitor the performance of Spark workloads the solution must meet the following requirements
* Provide comprehensive information about the performance of the data engineering workloads.
* Identify stages and tasks that run slowly.
* Minimize administrative effort
What should you use?
- A. the Spark Ul
- B. workspace metrics in Fabric
- C. Spark job event logs
- D. Spark application logs
正解:A
質問 # 96
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.
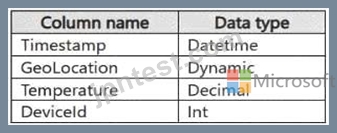
Reference contains reference data in the following format.
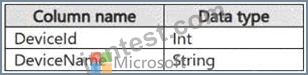
Both tables contain millions of rows.
You have the following KQL queryset.
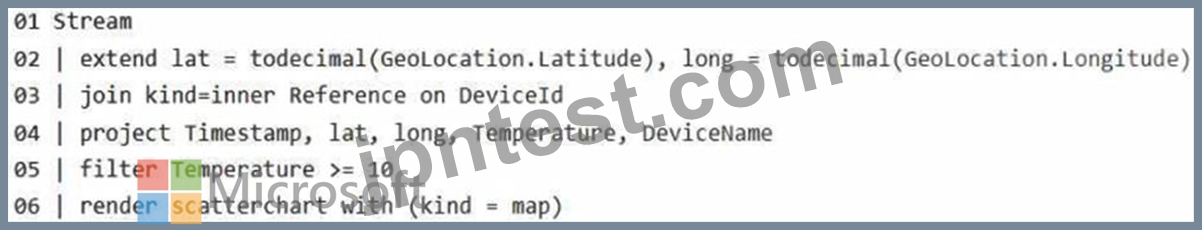
You need to reduce how long it takes to run the KQL queryset.
Solution: You change the join type to kind=outer.
Does this meet the goal?
正解:B
解説:
An outer join will include unmatched rows from both tables, increasing the dataset size and processing time.
It does not improve query performance.
質問 # 97
......
DP-700試験解答: https://www.jpntest.com/shiken/DP-700-mondaishu
- DP-700合格資料 🚲 DP-700合格記 🥊 DP-700試験合格攻略 🧿 { www.it-passports.com }サイトにて➡ DP-700 ️⬅️問題集を無料で使おうDP-700無料模擬試験
- DP-700受験料過去問 🚀 DP-700問題無料 🎒 DP-700認証資格 🏖 ⏩ www.goshiken.com ⏪で▷ DP-700 ◁を検索し、無料でダウンロードしてくださいDP-700日本語版試験勉強法
- 素敵なDP-700技術問題試験-試験の準備方法-正確的なDP-700試験解答 🕎 ▛ www.it-passports.com ▟サイトにて✔ DP-700 ️✔️問題集を無料で使おうDP-700日本語版受験参考書
- DP-700試験の準備方法 | 有難いDP-700技術問題試験 | 認定するImplementing Data Engineering Solutions Using Microsoft Fabric試験解答 🕓 { DP-700 }を無料でダウンロード{ www.goshiken.com }で検索するだけDP-700学習教材
- DP-700専門知識 🐾 DP-700合格資料 🌱 DP-700認証資格 🐾 「 www.jptestking.com 」に移動し、「 DP-700 」を検索して、無料でダウンロード可能な試験資料を探しますDP-700無料過去問
- DP-700無料過去問 🕳 DP-700無料模擬試験 🏬 DP-700専門知識 😅 今すぐ《 www.goshiken.com 》を開き、➡ DP-700 ️⬅️を検索して無料でダウンロードしてくださいDP-700技術内容
- DP-700学習教材 🏫 DP-700合格資料 🚪 DP-700試験時間 ☢ ⏩ www.xhs1991.com ⏪サイトにて最新☀ DP-700 ️☀️問題集をダウンロードDP-700受験料過去問
- DP-700関連問題資料 ⭕ DP-700技術内容 🦊 DP-700学習教材 ⛄ ➽ www.goshiken.com 🢪サイトで➠ DP-700 🠰の最新問題が使えるDP-700無料過去問
- DP-700関連問題資料 🍗 DP-700試験合格攻略 🤾 DP-700合格記 🤞 ➥ www.xhs1991.com 🡄から[ DP-700 ]を検索して、試験資料を無料でダウンロードしてくださいDP-700認証資格
- 100%合格率-高品質なDP-700技術問題試験-試験の準備方法DP-700試験解答 📤 ( www.goshiken.com )には無料の▶ DP-700 ◀問題集がありますDP-700最新関連参考書
- DP-700日本語版受験参考書 ✅ DP-700試験合格攻略 🌷 DP-700専門知識 😣 ▷ www.xhs1991.com ◁で☀ DP-700 ️☀️を検索して、無料で簡単にダウンロードできますDP-700問題無料
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! JPNTest DP-700ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1nZLZ_3dOizzHbguqSCaVEsN38t519cKJ