For starters and professionals Implementing Data Engineering Solutions Using Azure Databricks play a significant role to verify skills, experience, and knowledge in a specific technology. Enrollment in the Implementing Data Engineering Solutions Using Azure Databricks DP-750 is open to everyone. Upon completion of Implementing Data Engineering Solutions Using Azure Databricks DP-750 Exam Questions' particular criteria. Participants in the DP-750 Questions come from all over the world and receive the credentials for the Implementing Data Engineering Solutions Using Azure Databricks DP-750 Questions. They can quickly advance their careers in the fiercely competitive market and benefit from certification after earning the DP-750 Questions badge. However, passing the Implementing Data Engineering Solutions Using Azure Databricks DP-750 is the primary concern.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 2: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 3: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 4: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
>> Pass4sure DP-750 Dumps Pdf <<
There has been fierce and intensified competition going on in the practice materials market. As the leading commodity of the exam, our DP-750 training materials have get pressing requirements and steady demand from exam candidates all the time. So our DP-750 Exam Questions have active demands than others with high passing rate of 98 to 100 percent. Don't doubt the pass rate, as long as you try our DP-750 study questions, then you will find that pass the exam is as easy as pie.
NEW QUESTION # 91
You have an Azure Databricks workspace that is attached to a Unity Catalog metastore named metastore1.
Metastore1 contains a catalog named catalog 1.
You need to create a new schema named schema2 that meets the following requirements:
* Is contained in catalog1
* Uses abfss://containergstorageaccount.dfs.core.windows.net/data as the Managed location Which SQL statement should you execute?
Answer: D
Explanation:
The correct answer is A. The Unity Catalog DDL for creating a schema inside a specific catalog and setting a custom managed storage path uses the three-part name (catalog.schema) and the MANAGED LOCATION clause:
CREATE SCHEMA catalog1.schema2 MANAGED LOCATION 'abfss://...';
The three-part name explicitly places the schema inside catalog1. MANAGED LOCATION tells Unity Catalog where to store managed tables and volumes created under this schema - any managed table without its own explicit location will inherit this path.
Option B uses CREATE CATALOG, which creates an entirely new catalog rather than a schema. Option C uses the LOCATION keyword without MANAGED - that syntax is for external locations, not for overriding the managed storage path of a schema. Option D uses WITH DBPROPERTIES, which stores arbitrary key- value metadata but has no effect on where Unity Catalog physically stores data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-ddl-create- schema
NEW QUESTION # 92
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes curated Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Answer: B
Explanation:
The best choice is a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
Low Development Effort: Lakeflow SDP (formerly known as Delta Live Tables or DLT) is a completely declarative ETL framework. You simply define the target schemas and data transformations using standard SQL or Python. Databricks automatically manages the underlying operational complexities, state maintenance, task orchestration, and DAG dependencies for you.
Built-in Quality & Monitoring: It offers out-of-the-box data monitoring capabilities via Expectations, which allow you to specify data cleansing policies (like drop, retain, or fail on bad rows) with zero custom validation code. It also captures complete, automatic end-to-end data lineage and operational stats straight into Unity Catalog.
Built-in Resilience: Infrastructure failure handling and automatic retries are natively managed by the Lakeflow runtime.
Native Storage Ingestion: Using read_files() (Auto Loader) within SDP allows effortless, incremental ingestion of files from cloud object storage directly into curated Delta tables.
Reference:
https://docs.databricks.com/aws/en/ldp/
NEW QUESTION # 93
You have an Azure Databricks workspace.
Users report that a Databricks notebook that runs each day takes longer than expected to run.
When reading the Directed Acyclic Graph (DAG), you discover the following issues concerning the Apache Spark stage:
* Most tasks in the stage finish quickly.
* A few tasks in the stage run more slowly.
* The CPU is underutilized at the end of the stage.
* The slow tasks process many more input records.
* The stage is blocked while it waits for the few slow tasks.
What is the root cause of the issues?
Answer: D
Explanation:
The symptoms indicate data skew. Spark partitions the stage's work into tasks, but a few partitions contain substantially more records than the others. Tasks processing the smaller partitions finish quickly, leaving the cluster underutilized while the stage waits for the oversized partitions. Caching would concern whether reused data is stored in memory and does not inherently explain an uneven distribution of input records. Shuffling transfers data between executors and can be expensive, but the decisive evidence is that only a few tasks process far more records. Spilling occurs when an executor cannot keep intermediate data in memory and writes it to disk; the scenario does not identify high spill volumes. Examining per-task input sizes in the Spark UI would confirm the skewed partition distribution.
NEW QUESTION # 94
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! contains three tasks named Task1, Task2. and Task3.
If Task1 fails, Task2 and Task3 must be prevented from running. Successfully completed tasks must NOT rerun during recovery.
You need to configure Job1 to support controlled failure handling and recovery What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.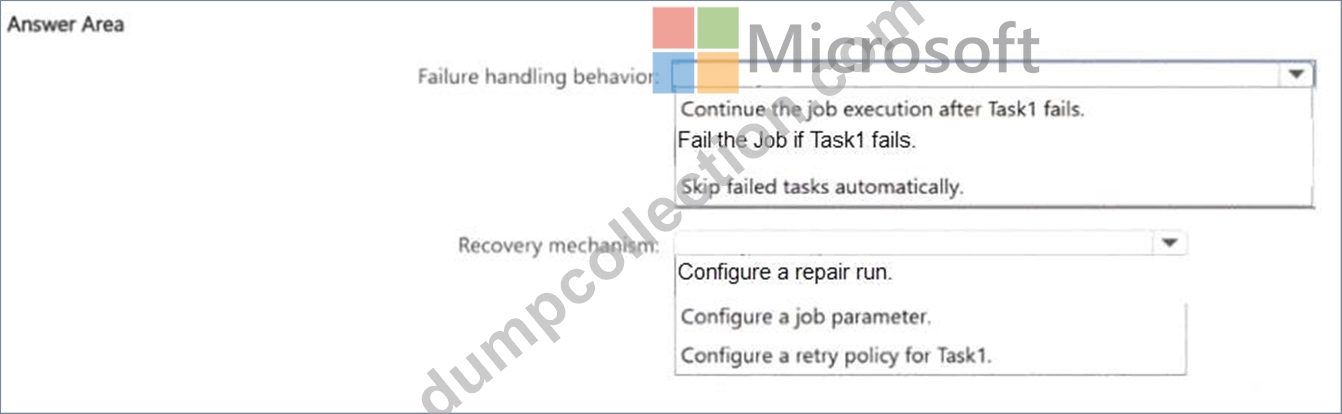
Answer:
Explanation: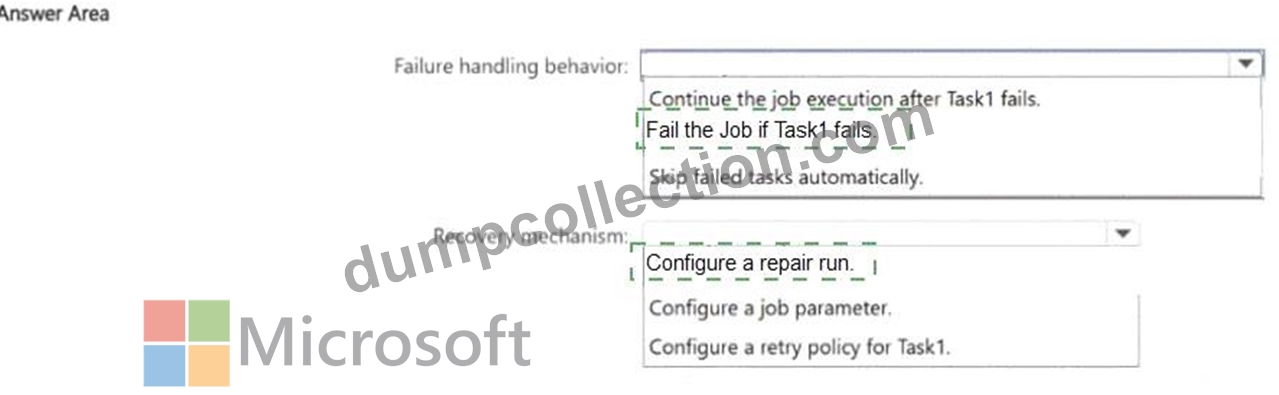
Explanation:
Two configurations are needed:
Task dependency with 'All succeeded' run condition: Set Task2 and Task3 to depend on Task1. Change the run condition on Task2 and Task3 to 'All succeeded' - this means they only execute when all their upstream dependencies (Task1) have succeeded. If Task1 fails, both downstream tasks are skipped automatically, not run with failed inputs.
Repair run for recovery: Lakeflow Jobs' Repair Run feature lets you re-execute only the tasks that failed (Task1 in this case) and their dependents (Task2 and Task3 if they were skipped), while skipping Task1 and any other tasks that already completed successfully. Successfully completed tasks are never re-executed during repair - their results are reused as-is.
Together these provide both controlled failure propagation (nothing runs downstream of a failure) and efficient recovery.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/repair-job-failures
NEW QUESTION # 95
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
dbl sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the dbl.sales.ordets table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.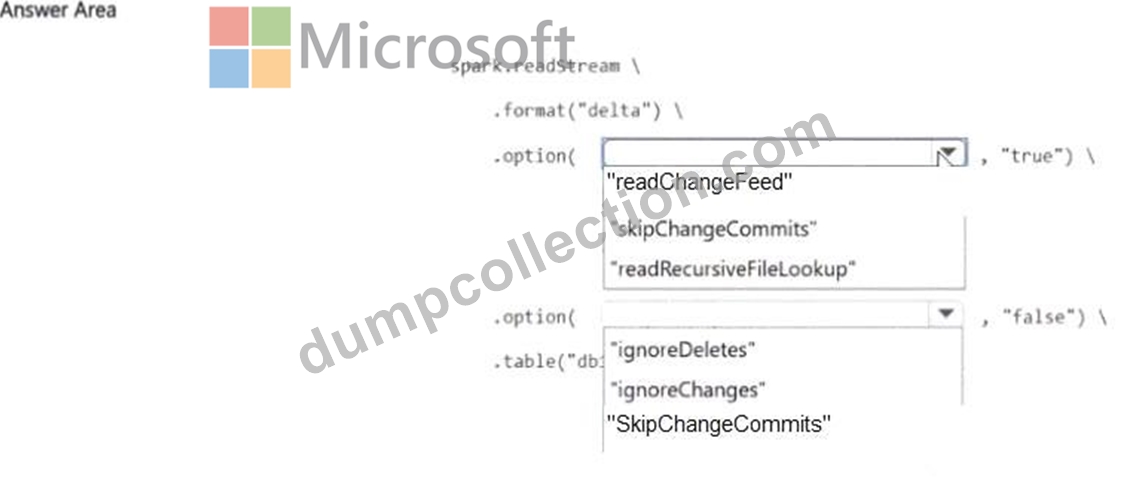
Answer:
Explanation: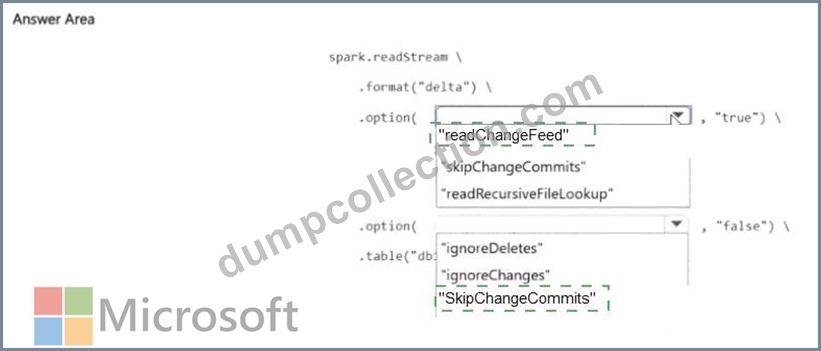
Explanation:
When Change Data Feed (CDF) is enabled on a Delta table, reading the full change stream - inserts, updates, and deletes - requires this pattern:
spark.readStream.format('delta').option('readChangeFeed', 'true').table('db1.sales_orders') The readChangeFeed option switches the reader from the default 'new rows only' mode to a mode that returns all change events. Each row in the resulting DataFrame includes a _change_type column (insert, update_preimage, update_postimage, delete) so downstream processing can distinguish what happened to each record.
Without readChangeFeed = true, streaming a Delta table only surfaces newly appended rows. Deletes and updates are invisible, making it unsuitable for true CDC pipelines. The stream also supports startingVersion or startingTimestamp options to begin from a specific point in table history rather than the current moment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-change-data-feed
NEW QUESTION # 96
......
When you first contact our software, different people will have different problems. Maybe you are not comfortable with our DP-750 exam question and want to know more about our products and operations. As long as you have questions, you can send e-mail to us, we have online staff responsible for ensuring 24-hour service to help you solve all the problems about our DP-750 Test Prep. After you purchase our DP-750 quiz guide, we will still provide you with considerate services. Maybe you will ask whether we will charge additional service fees.
Latest DP-750 Test Guide: https://www.dumpcollection.com/DP-750_braindumps.html