MLA-C01資料的中率、MLA-C01日本語サンプル

無料でクラウドストレージから最新のShikenPASS MLA-C01 PDFダンプをダウンロードする:https://drive.google.com/open?id=1-gdzMNjWw7Heg_Y0Pxu7wPZslBdCPOni
ローマは一日に建てられませんでした。多くの人にとって、短い時間でMLA-C01試験に合格できることは難しいです。しかし、幸いにして、MLA-C01の練習問題の専門会社として、弊社の最も正確な質問と回答を含むMLA-C01試験の資料は、MLA-C01試験対する問題を効果的に解決できます。MLA-C01練習問題をちゃんと覚えると、MLA-C01に合格できます。あなたはMLA-C01練習問題を選ばれば、試験に合格できますよ!
Amazon MLA-C01 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - MLワークフローのデプロイメントとオーケストレーション:このセクションでは、フォレンジックデータアナリストのスキルを測定し、機械学習モデルの本番環境へのデプロイメントに焦点を当てます。適切なインフラストラクチャの選択、コンテナの管理、スケーリングの自動化、CI
- CDパイプラインを介したワークフローのオーケストレーションなど、幅広い分野を網羅しています。受験者は、実世界の不正検出システムにおいて、一貫したデプロイメントと効率的な再トレーニングサイクルをサポートする環境を構築し、スクリプトを作成できる必要があります。
|
| トピック 2 | - 機械学習モデル開発:この試験セクションでは、不正検査官のスキルを測定し、不正検出などのビジネス課題を解決するための機械学習モデルの選択とトレーニングについて学びます。アルゴリズムの選択、組み込みモデルまたはカスタムモデルの使用、パラメータの調整、標準指標によるパフォーマンス評価などが含まれます。この分野では、過剰適合を回避するためのモデルの改良と、継続的な調査と監査証跡をサポートするためのバージョン管理の維持に重点が置かれています。
|
| トピック 3 | - 機械学習ソリューションの監視、保守、セキュリティ:この試験セクションでは、不正検査官のスキルを測定し、機械学習モデルの監視、インフラストラクチャコストの管理、セキュリティのベストプラクティスの適用能力を評価します。モデルパフォーマンスの追跡設定、ドリフトの検出、ログ記録とアラートのためのAWSツールの使用などが含まれます。受験者は、アクセス制御の設定、環境の監査、金融不正検出などの機密データ環境におけるコンプライアンスの維持についてもテストされます。
|
| トピック 4 | - 機械学習(ML)のためのデータ準備:この試験セクションでは、フォレンジックデータアナリストのスキルを評価し、機械学習用のデータの収集、保存、準備について扱います。様々なデータ形式、取り込み方法、そしてデータの処理と変換に使用されるAWSツールの理解に重点が置かれます。受験者は、不正分析のコンテキストにおいて高品質なデータセットを準備するために不可欠な、特徴量のクリーニングとエンジニアリング、データの整合性の確保、そしてバイアスやコンプライアンスの問題への対処を行うことが求められます。
|
>> MLA-C01資料的中率 <<
MLA-C01認定に関する最高のAmazon MLA-C01受験問題集
生活で他の人が何かやったくれることをいつも要求しないで、私が他の人に何かやってあげられることをよく考えるべきです。職場でも同じです。ボスに偉大な価値を創造してあげたら、ボスは無論あなたをヘアします。これに反して、あなたがずっと普通な職員だったら、遅かれ早かれ解雇されます。ですから、IT認定試験に受かって、自分の能力を高めるべきです。 ShikenPASSのAmazonのMLA-C01「AWS Certified Machine Learning Engineer - Associate」試験問題集はあなたが成功へのショートカットを与えます。IT 職員はほとんど行動しましたから、あなたはまだ何を待っているのですか。ためらわずにShikenPASSのAmazonのMLA-C01試験トレーニング資料を購入しましょう。
Amazon AWS Certified Machine Learning Engineer - Associate 認定 MLA-C01 試験問題 (Q22-Q27):
質問 # 22
A company needs to deploy a custom-trained classification ML model on AWS. The model must make near real-time predictions with low latency and must handle variable request volumes.
Which solution will meet these requirements?
- A. Create an Amazon SageMaker AI batch transform job to process inference requests in batches.
- B. Deploy an Amazon SageMaker AI endpoint. Configure auto scaling for the endpoint.
- C. Launch AWS Deep Learning AMIs (DLAMI) on two Amazon EC2 instances. Run the instances behind an Application Load Balancer.
- D. Use Amazon API Gateway to receive prediction requests. Use an Amazon S3 bucket to host and serve the model.
正解:B
解説:
For near real-time inference with low latency and variable traffic, AWS recommends deploying models to managed SageMaker endpoints. By enabling auto scaling, the endpoint automatically adjusts the number of instances based on request volume, ensuring consistent performance while optimizing cost.
Amazon SageMaker Endpoints abstracts infrastructure management, health checks, scaling, and model deployment. This provides lower operational overhead than managing EC2 instances manually.
Batch transform is for offline inference. API Gateway with S3 cannot serve ML models. EC2-based deployments require manual scaling and monitoring.
Therefore, a SageMaker endpoint with auto scaling is the correct solution.
質問 # 23
A company is using Amazon SageMaker and millions of files to train an ML model. Each file is several megabytes in size. The files are stored in an Amazon S3 bucket. The company needs to improve training performance.
Which solution will meet these requirements in the LEAST amount of time?
- A. Transfer the data to a new S3 bucket that provides S3 Express One Zone storage. Adjust the training job to use the new S3 bucket.
- B. Create an Amazon Elastic File System (Amazon EFS) file system. Transfer the existing data to the file system. Adjust the training job to read from the file system.
- C. Create an Amazon ElastiCache (Redis OSS) cluster. Link the Redis OSS cluster to the existing S3 bucket. Stream the data from the Redis OSS cluster directly to the training job.
- D. Create an Amazon FSx for Lustre file system. Link the file system to the existing S3 bucket. Adjust the training job to read from the file system.
正解:D
解説:
Amazon FSx for Lustre is designed for high-performance workloads like ML training. It provides fast, low- latency access to data by linking directly to the existing S3 bucket and caching frequently accessed files locally. This significantly improves training performance compared to directly accessing millions of files from S3. It requires minimal changes to the training job and avoids the overhead of transferring or restructuring data, making it the fastest and most efficient solution.
質問 # 24
A company shares Amazon SageMaker Studio notebooks that are accessible through a VPN.
The company must enforce access controls to prevent malicious actors from exploiting presigned URLs to access the notebooks.
Which solution will meet these requirements?
- A. Set up Studio client user endpoint validation by using the aws:PrincipalTag IAM policy condition.
- B. Set up Studio client IP validation by using the aws:sourceIp IAM policy condition.
- C. Set up Studio client role endpoint validation by using the aws:PrimaryTag IAM policy condition.
- D. Set up Studio client VPC validation by using the aws:sourceVpc IAM policy condition.
正解:B
質問 # 25
A credit card company has a fraud detection model in production on an Amazon SageMaker endpoint. The company develops a new version of the model. The company needs to assess the new model's performance by using live data and without affecting production end users.
Which solution will meet these requirements?
- A. Set up shadow testing with a shadow variant of the new model.
- B. Set up SageMaker Debugger and create a custom rule.
- C. Set up blue/green deployments with all-at-once traffic shifting.
- D. Set up blue/green deployments with canary traffic shifting.
正解:A
解説:
Shadow testing allows you to send a copy of live production traffic to a shadow variant of the new model while keeping the existing production model unaffected. This enables you to evaluate the performance of the new model in real-time with live data without impacting end users. SageMaker endpoints support this setup by allowing traffic mirroring to the shadow variant, making it an ideal solution for assessing the new model's performance.
質問 # 26
A company uses a training job on Amazon SageMaker Al to train a neural network. The job first trains a model and then evaluates the model ' s performance ag test dataset. The company uses the results from the evaluation phase to decide if the trained model will go to production.
The training phase takes too long. The company needs solutions that can shorten training time without decreasing the model ' s final performance.
Select the correct solutions from the following list to meet the requirements for each description. Select each solution one time or not at all. (Select THREE.)
. Change the epoch count.
. Choose an Amazon EC2 Spot Fleet.
Change the batch size.
. Use early stopping on the training job.
Use the SageMaker Al distributed data parallelism (SMDDP) library.
. Stop the training job.
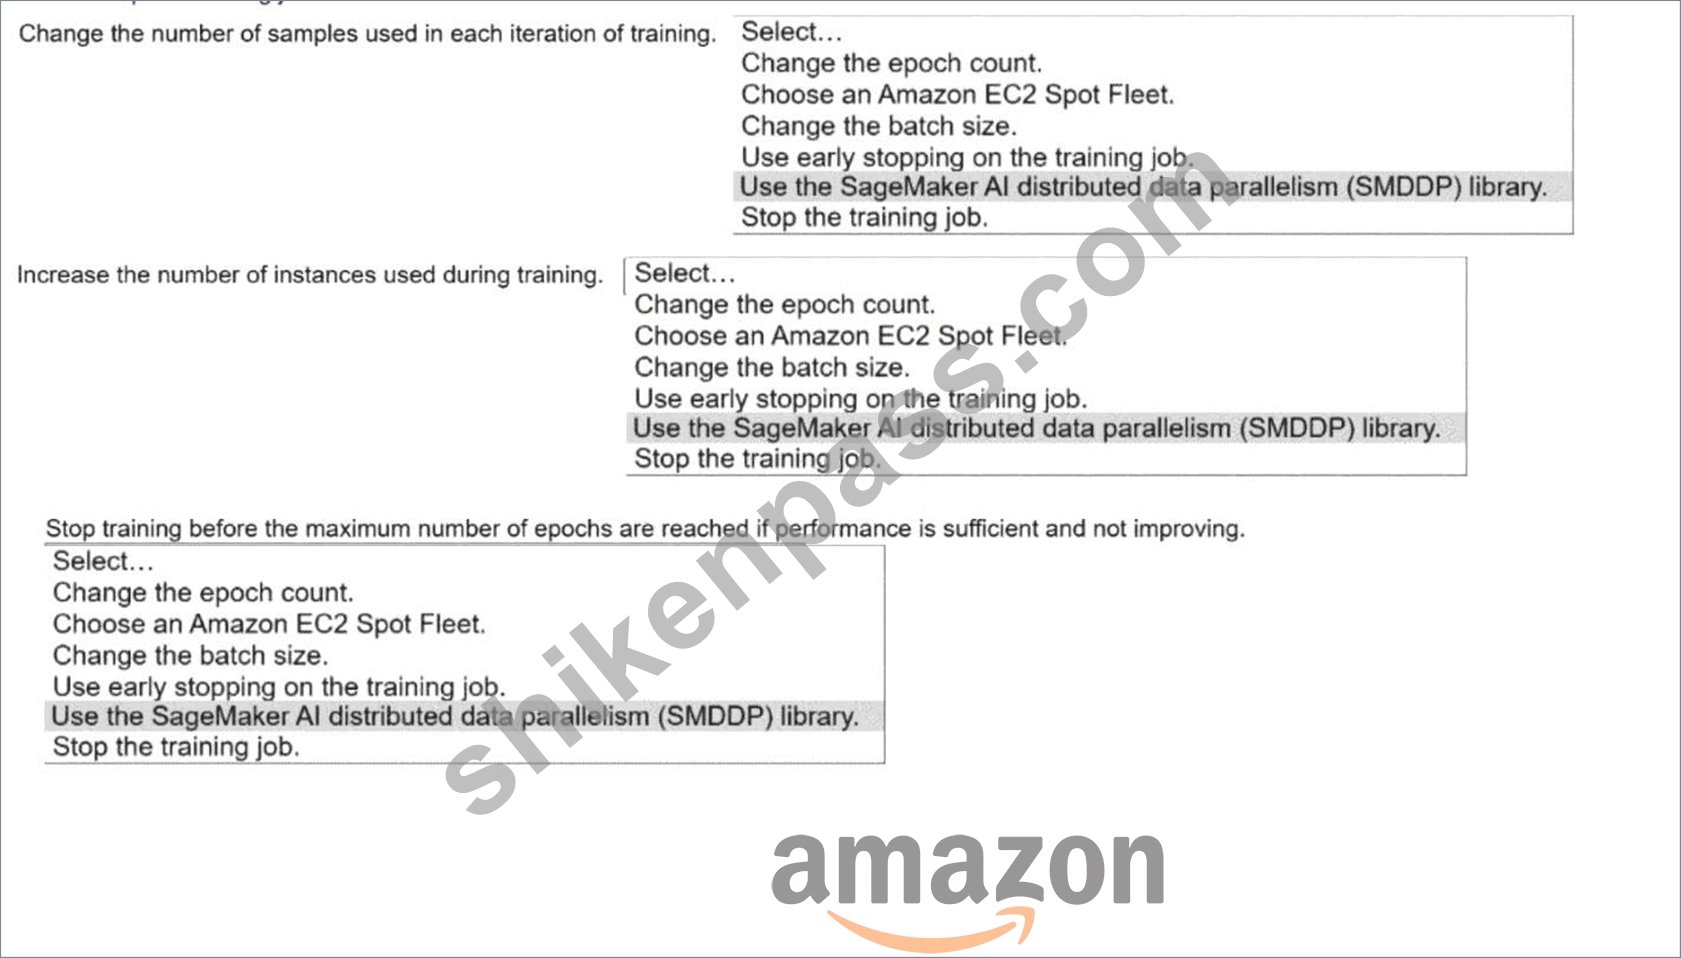
正解:
解説:
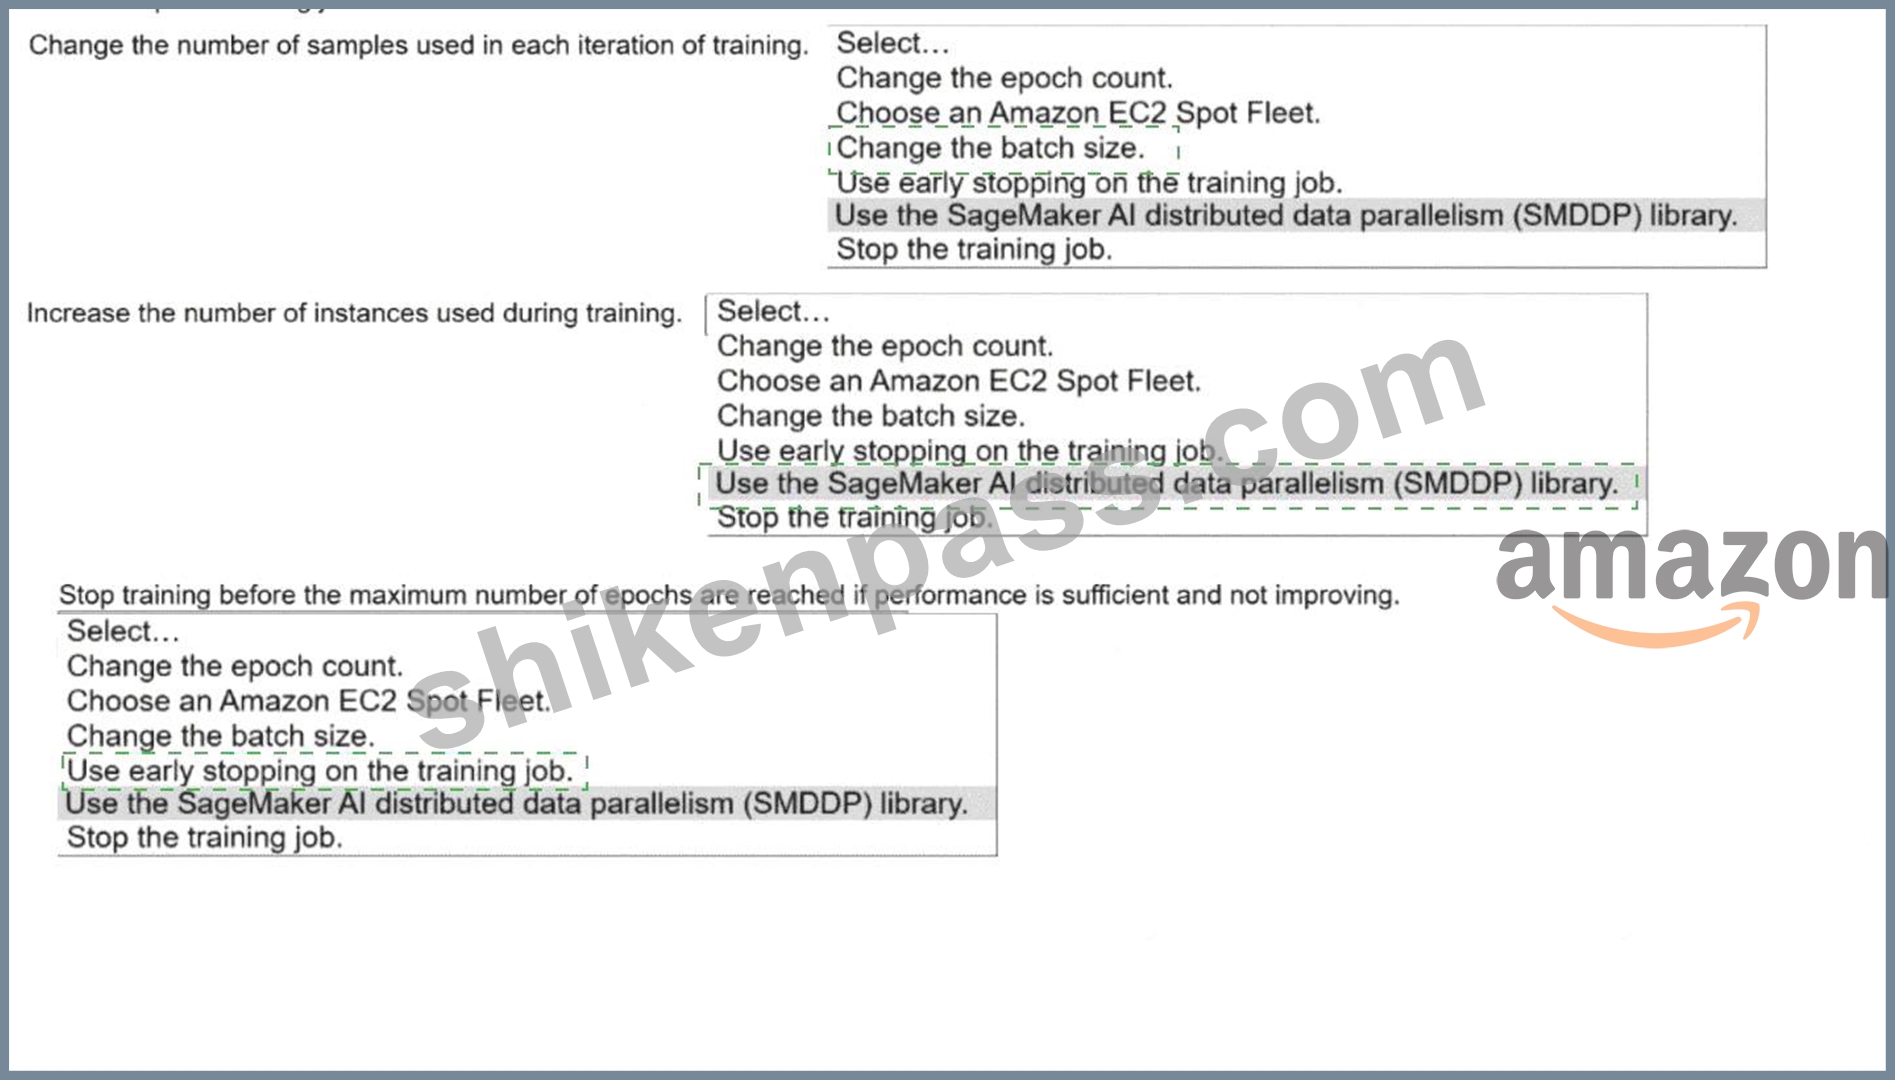
Explanation:
Change the number of samples used in each iteration of training
Correct selection:
Change the batch size
Why:
Increasing the batch size reduces the number of iterations per epoch, which can significantly shorten training time while maintaining model quality when tuned appropriately. AWS explicitly recommends batch size tuning as a primary performance optimization.
Increase the number of instances used during training
Correct selection:
Use the SageMaker AI distributed data parallelism (SMDDP) library
Why:
SMDDP is designed to efficiently distribute training data across multiple GPU instances with optimized gradient synchronization. This accelerates training without affecting model convergence or accuracy, unlike naive scaling approaches.
Stop training before the maximum number of epochs are reached if performance is sufficient and not improving Correct selection:
Use early stopping on the training job
Why:
Early stopping automatically terminates training when validation metrics stop improving. AWS recommends this to reduce wasted compute time while preserving optimal model performance.
質問 # 27
......
高品質のMLA-C01準備ガイドを購入できるだけでなく、当社から大きな勇気と信頼を得ることもできます。多くのオンライン教育プラットフォームのリソースは、購入後に使用するためにユーザー登録によって提供される必要がありますが、それは当社のウェブサイトでは簡単です。 MLA-C01ガイドトレントの無料デモを提供しています。登録せずにいつでもダウンロードできます。高速配信-支払い後、10分以内にMLA-C01試験トレントを受信できるため、迅速かつ効率的に学習できます。 何を待っていますか? MLA-C01試験問題を購入してください。
MLA-C01日本語サンプル: https://www.shikenpass.com/MLA-C01-shiken.html
- Amazon MLA-C01資料的中率: AWS Certified Machine Learning Engineer - Associate - www.it-passports.com 合格のを助ける 🎤 サイト“ www.it-passports.com ”で( MLA-C01 )問題集をダウンロードMLA-C01日本語版試験勉強法
- 更新するMLA-C01資料的中率 - 合格スムーズMLA-C01日本語サンプル | 信頼的なMLA-C01日本語復習赤本 🚍 ➡ www.goshiken.com ️⬅️から簡単に▷ MLA-C01 ◁を無料でダウンロードできますMLA-C01合格記
- 試験の準備方法-高品質なMLA-C01資料的中率試験-実際的なMLA-C01日本語サンプル 🧓 《 www.japancert.com 》から⮆ MLA-C01 ⮄を検索して、試験資料を無料でダウンロードしてくださいMLA-C01的中問題集
- MLA-C01資格勉強 🍼 MLA-C01最新な問題集 🐢 MLA-C01独学書籍 🐂 ( www.goshiken.com )を入力して⮆ MLA-C01 ⮄を検索し、無料でダウンロードしてくださいMLA-C01日本語版トレーリング
- www.it-passports.com MLA-C01 一冊で合格まで導く 🥵 “ www.it-passports.com ”に移動し、☀ MLA-C01 ️☀️を検索して無料でダウンロードしてくださいMLA-C01無料過去問
- MLA-C01テスト模擬問題集 🔈 MLA-C01テスト模擬問題集 🦢 MLA-C01資格勉強 😞 “ www.goshiken.com ”から➠ MLA-C01 🠰を検索して、試験資料を無料でダウンロードしてくださいMLA-C01復習資料
- 信用のあるAmazon MLA-C01認定試験の問題集 🍏 ➥ www.jptestking.com 🡄には無料の( MLA-C01 )問題集がありますMLA-C01最新資料
- Amazon MLA-C01資料的中率: AWS Certified Machine Learning Engineer - Associate - GoShiken 合格のを助ける 🕛 「 MLA-C01 」の試験問題は[ www.goshiken.com ]で無料配信中MLA-C01復習資料
- MLA-C01最新な問題集 📎 MLA-C01受験対策解説集 👗 MLA-C01出題内容 🎩 Open Webサイト【 www.shikenpass.com 】検索( MLA-C01 )無料ダウンロードMLA-C01受験対策解説集
- 有難いMLA-C01資料的中率 - 合格スムーズMLA-C01日本語サンプル | 実用的なMLA-C01日本語復習赤本 🤪 今すぐ( www.goshiken.com )を開き、➽ MLA-C01 🢪を検索して無料でダウンロードしてくださいMLA-C01出題内容
- MLA-C01最新資料 🍁 MLA-C01日本語版トレーリング 🦃 MLA-C01出題内容 🦇 ⮆ www.passtest.jp ⮄は、《 MLA-C01 》を無料でダウンロードするのに最適なサイトですMLA-C01出題内容
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! ShikenPASS MLA-C01ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1-gdzMNjWw7Heg_Y0Pxu7wPZslBdCPOni