P.S. Free 2026 Microsoft DP-600 dumps are available on Google Drive shared by TopExamCollection: https://drive.google.com/open?id=1dcOoD6gyrZICu8Deph29b5zUipSM01rd
With the pass rate reaching 98.65%, DP-600 exam materials have gained popularity among candidates. We have received feedbacks from customers, and we examine and review DP-600 exam bootcamp on a continuous basis, so that exam dumps you receive are the latest version. In order to build up your confidence for DP-600 training materials, we are pass guarantee and money back guarantee, if you fail to pass the exam we will give you full refund. You can receive download link for DP-600 Exam Materials within ten minutes, and if you don’t, you can contact with us, we will have professional staff to solve this problem for you.
| Section | Objectives |
|---|---|
| Topic 1: Manage and secure Microsoft Fabric | - Governance and administration
|
| Topic 2: Implement data engineering solutions | - Lakehouse architecture
|
| Topic 3: Real-time analytics | - Streaming and event processing
|
| Topic 4: Implement analytics solutions | - Data warehousing and modeling
|
| Topic 5: Get data into Microsoft Fabric | - Data ingestion and integration
|
>> DP-600 Exam Guide Materials <<
As you may see the data on the website, our sales volumes of our DP-600 exam questions are the highest in the market. You can browse our official websites to check our sales volumes. At the same time, many people pass the exam for the first time under the guidance of our DP-600 Practice Exam. And there is no exaggeration that our pass rate for our DP-600 study guide is 98% to 100% which is proved and tested by our loyal customers.
NEW QUESTION # 106
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric tenant that contains a semantic model named Model1.
You discover that the following query performs slowly against Model1.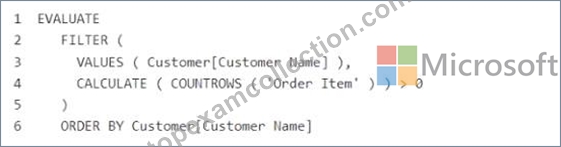
You need to reduce the execution time of the query.
Solution: You replace line 4 by using the following code:
Does this meet the goal?
Answer: B
Explanation:
Topic 1, Litware. Inc. Case Study
Overview
Litware. Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
litware has been using a Microsoft Power Bl tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Fabric Environment
Litware has data that must be analyzed as shown in the following table.
The Product data contains a single table and the following columns.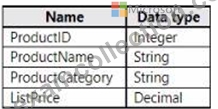
The customer satisfaction data contains the following tables:
* Survey
* Question
* Response
For each survey submitted, the following occurs:
* One row is added to the Survey table.
* One row is added to the Response table for each question in the survey.
The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Litware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity.
The following three workspaces will be created:
* AnalyticsPOC: Will contain the data store, semantic models, reports, pipelines, dataflows, and notebooks used to populate the data store
* DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate Onelake
* DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
* A data store (type to be decided)
* A custom semantic model
* A default semantic model
* Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
* Read access by using T-SQL or Python
* Semi-structured and unstructured data
* Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model.
The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model.
The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SQL queries and in the default semantic model. The following logic must be used:
* List prices that are less than or equal to 50 are in the low pricing group.
* List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
* List pnces that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC. Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
* Fabric administrators will be the workspace administrators.
* The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
* The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
* The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook.
* The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power Bl reports by using the semantic models created by the analytics engineers.
* The date dimension must be available to all users of the data store.
* The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
* FabricAdmins: Fabric administrators
* AnalyticsTeam: All the members of the analytics team
* DataAnalysts: The data analysts on the analytics team
* DataScientists: The data scientists on the analytics team
* Data Engineers: The data engineers on the analytics team
* Analytics Engineers: The analytics engineers on the analytics team
Report Requirements
The data analysis must create a customer satisfaction report that meets the following requirements:
* Enables a user to select a product to filter customer survey responses to only those who have purchased that product
* Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected date
* Shows data as soon as the data is updated in the data store
* Ensures that the report and the semantic model only contain data from the current and previous year
* Ensures that the report respects any table-level security specified in the source data store
* Minimizes the execution time of report queries
NEW QUESTION # 107
You have a Fabric workspace that contains a warehouse named Warehouse!. Warehousel contains the following data.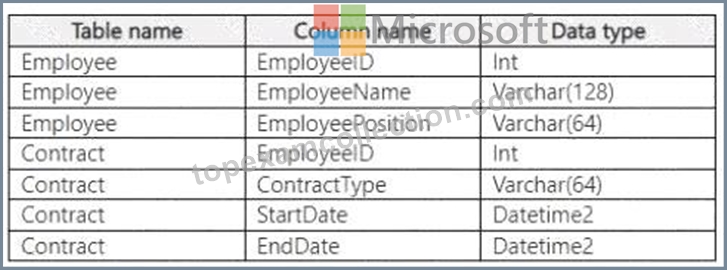
You need to create a T-SQL statement that will denormalize the tables and include the ContractType and StartDate attributes in the results. The solution must meet the following requirements:
* Include attributes from matching rows in the Contract table.
* Ensure that all the rows from the Employee table are preserved.
* Return the total number of employees per contract type for all the contract types that have more than two employees.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.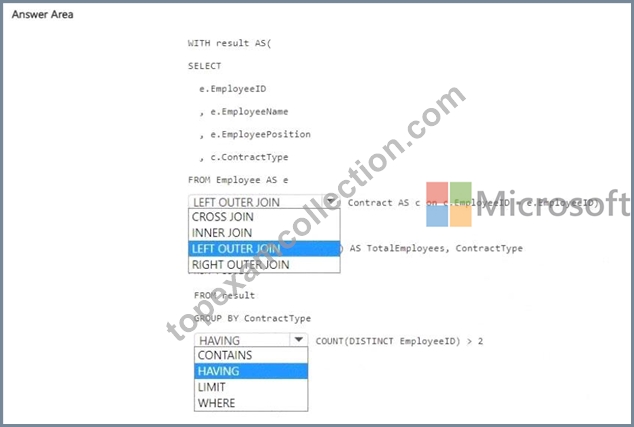
Answer:
Explanation: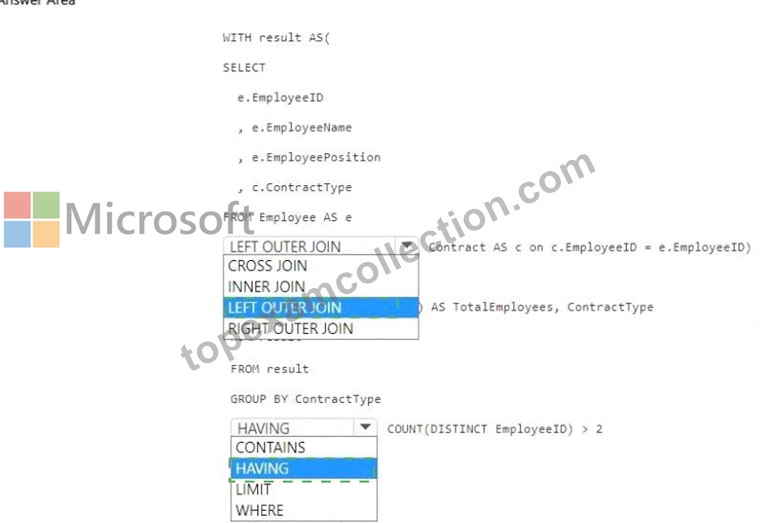
Explanation: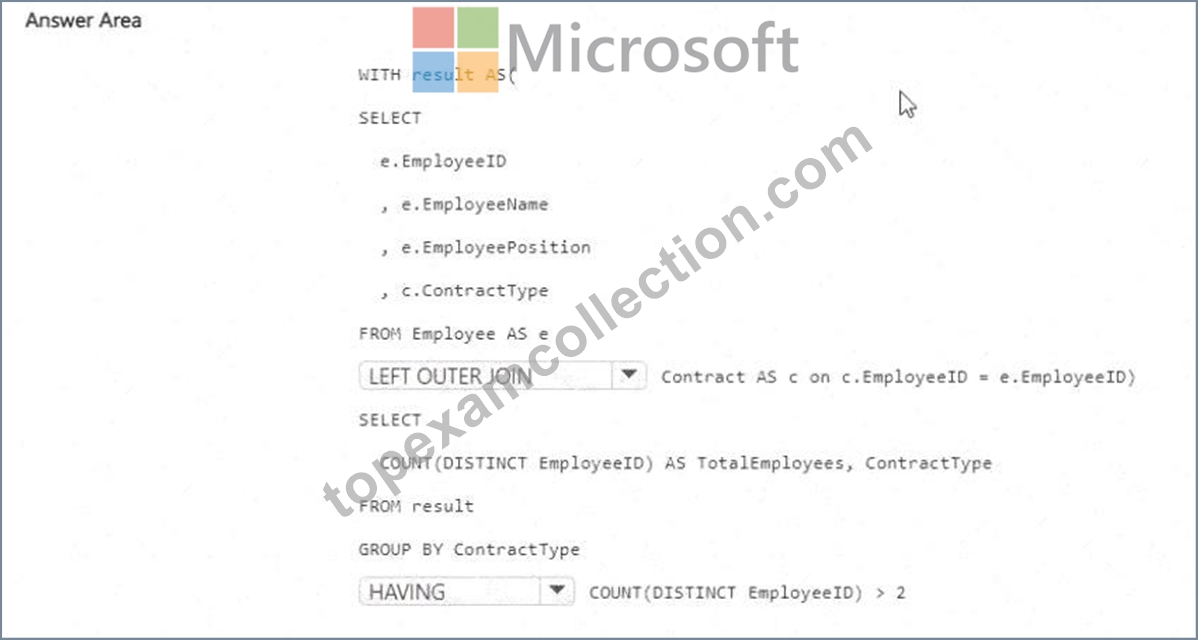
Comprehensive Detailed Explanation
We are tasked with writing a T-SQL query to denormalize the tables Employee and Contract in a Fabric warehouse.
Requirements Breakdown
Include attributes from matching rows in the Contract table
This means we must join Employee and Contract on EmployeeID .
Ensure that all rows from the Employee table are preserved
This requires a LEFT OUTER JOIN from Employee to Contract. If an employee has no contract, we still want the employee record included.
Return the total number of employees per contract type for all contract types that have more than two employees This means we need to:
Group by ContractType
Count distinct EmployeeID
Filter groups where that count > 2.
To filter aggregated results, we use HAVING , not WHERE.
Completed Query
WITH result AS (
SELECT
e.EmployeeID,
e.EmployeeName,
e.EmployeePosition,
c.ContractType,
c.StartDate
FROM Employee AS e
LEFT OUTER JOIN Contract AS c
ON c.EmployeeID = e.EmployeeID
)
SELECT
ContractType,
COUNT ( DISTINCT EmployeeID) AS TotalEmployees
FROM result
GROUP BY ContractType
HAVING COUNT ( DISTINCT EmployeeID) > 2 ;
Why This is Correct
LEFT OUTER JOIN ensures all employees are included, regardless of contracts.
HAVING allows filtering aggregated groups by employee counts.
The query returns ContractType , StartDate (as requested in denormalization), and aggregated employee counts.
References
T-SQL JOINs in Microsoft Fabric
Aggregate functions and HAVING clause
Denormalization best practices in Fabric warehouses
NEW QUESTION # 108
You have a Microsoft Power Bl report named Report1 that uses a Fabric semantic model.
Users discover that Report1 renders slowly.
You open Performance analyzer and identify that a visual named Orders By Date is the slowest to render. The duration breakdown for Orders By Date is shown in the following table.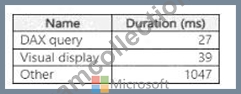
What will provide the greatest reduction in the rendering duration of Report1?
Answer: C
Explanation:
Based on the duration breakdown provided, the major contributor to the rendering duration is categorized as " Other, " which is significantly higher than DAX Query and Visual display times. This suggests that the issue is less likely with the DAX calculation or visual rendering times and more likely related to model performance or the complexity of the visual. However, of the options provided, optimizing the DAX query can be a crucial step, even if " Other " factors are dominant. Using DAX Studio, you can analyze and optimize the DAX queries that power your visuals for performance improvements. Here's how you might proceed:
Open DAX Studio and connect it to your Power BI report.
Capture the DAX query generated by the Orders By Date visual.
Use the Performance Analyzer feature within DAX Studio to analyze the query.
Look for inefficiencies or long-running operations.
Optimize the DAX query by simplifying measures, removing unnecessary calculations, or improving iterator functions.
Test the optimized query to ensure it reduces the overall duration.
References: The use of DAX Studio for query optimization is a common best practice for improving Power BI report performance as outlined in the Power BI documentation.
NEW QUESTION # 109
Drag and Drop Question
You have Fabric tenant that contains a semantic model named Model1. Model1 contains the following tables.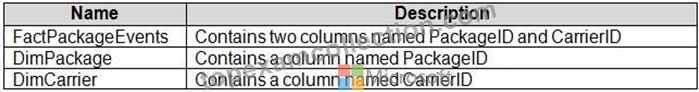
You are designing a Microsoft Power BI report named Report1 that will deliver near-real-time (NRT) shipping data. Report1 will contain data about many shipped packages.
You need to ensure that each table is in the appropriate storage mode to support Report1. The solution must support near-real-time data delivery while maintaining high query performance.
Which storage mode should you select for each table? To answer, drag the appropriate storage modes to the correct tables. Each mode may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: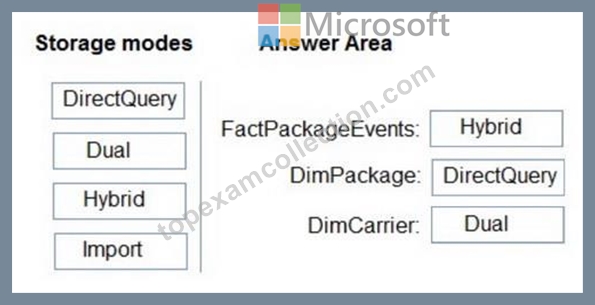
NEW QUESTION # 110
You have a Fabric tenant that contains two lakehouses.
You are building a dataflow that will combine data from the lakehouses. The applied steps from one of the queries in the dataflow is shown in the following exhibit.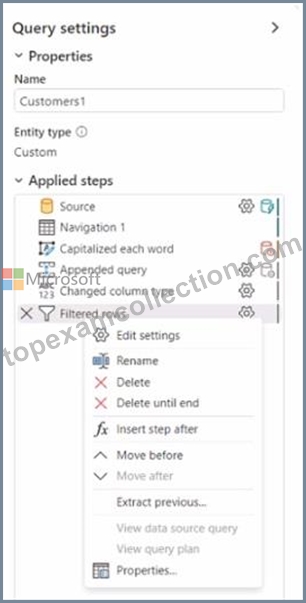
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic. NOTE: Each correct selection is worth one point.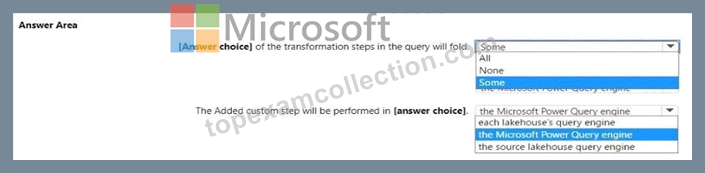
Answer:
Explanation:
Explanation: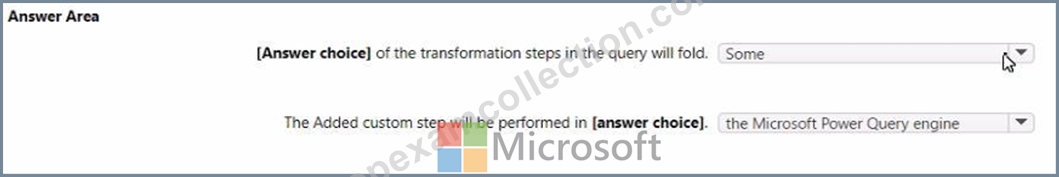
Folding in Power Query refers to operations that can be translated into source queries. In this case, "some" of the steps can be folded, which means that some transformations will be executed at the data source level. The steps that cannot be folded will be executed within the Power Query engine. Custom steps, especially those that are not standard query operations, are usually executed within Power Query engine rather than being pushed down to the source system.
References =
* Query folding in Power Query
* Power Query M formula language
NEW QUESTION # 111
......
Being anxious for the exam ahead of you? Have a look of our DP-600 practice materials please. Presiding over the line of DP-600 practice materials over ten years, our experts are proficient as elites who made our DP-600 practice materials, and it is their job to officiate the routines of offering help for you. All points are predominantly related with the exam ahead of you. Every page is full of well-turned words for your reference related wholly with the real exam.
DP-600 Exam Consultant: https://www.topexamcollection.com/DP-600-vce-collection.html
DOWNLOAD the newest TopExamCollection DP-600 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1dcOoD6gyrZICu8Deph29b5zUipSM01rd