Die Examfragen zur Microsoft DP-750 Zertifizierungsprüfung von EchteFrage ist von den IT-Experten verifiziert und überprüft. Die Fragen und Antworten zur Microsoft DP-750 Zertifizierungsprüfung sind die von der Praxis überprüfte Software und die Schulungsinstrumente. In EchteFrage werden Sie die besten Zertifizierungsmaterialien finden, die originale Fragen und Antworten enthalten. Unsere Materialien bieten Ihnen die Chance, die echten Übungen zu machen. Endlich werden Sie Ihr Ziel, nämlich die Microsoft DP-750 Zertifizierungsprüfung zu bestehen, erreichen.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Topic 2: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Topic 3: Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Topic 4: Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
Bereiten Sie sich jetzt auf Microsoft DP-750 Prüfung? Auf der offiziellen Webseite unserer EchteFrage wird alle Ihrer Bedarf an der Vorbereitung auf Microsoft DP-750 erfüllt. Insofern unsere Marke Ihnen bekannt ist, können Sie sogleich die Prüfungsunterlagen der Microsoft DP-750 nach Ihrem Bedarf innerhalb einigen Minuten erhalten. Gesicherte Zahlungsmittel, zuverlässige Kundendienste sowie die Produkte auf hohem Standard, diese Vorteilen können alle zusammen Ihnen helfen, zufriedenstellende Leistungen zu bekommen.
43. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.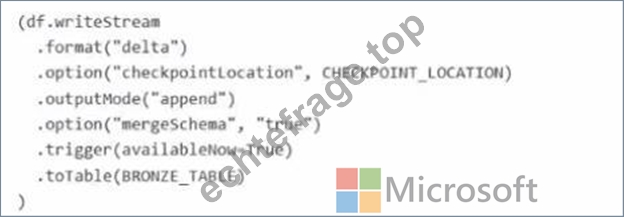
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.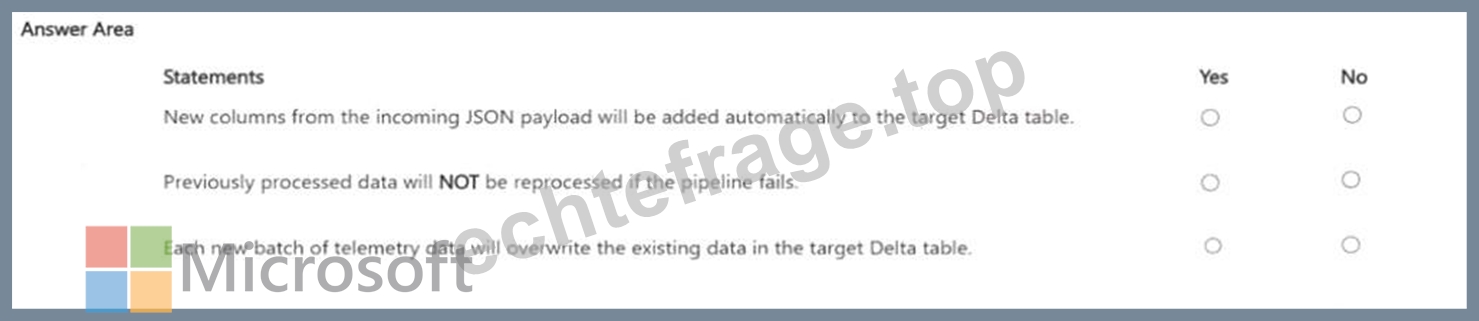
Antwort:
Begründung: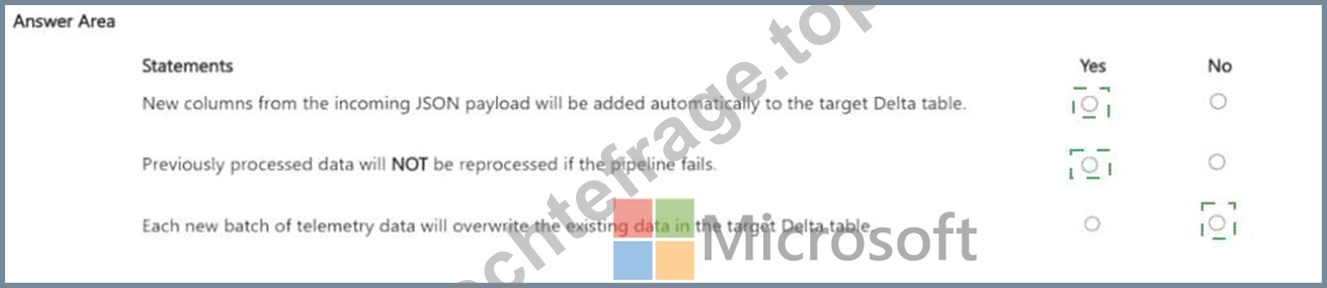
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: 'overwrite' replaces existing data; 'append' adds to it.
Always check whether the code uses the correct Delta format (.format('delta')), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
44. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
Antwort: B
Begründung:
The correct answer is A - Yes.
df.filter(df.order_amount.isNotNull()) is the correct PySpark pattern for excluding null rows. The isNotNull() method is a Column method that returns True for every row where order_amount has a value and False for rows where it is null. Spark ' s filter keeps only the rows where the condition evaluates to True, producing a DataFrame with all null order_amount rows removed.
This works correctly because isNotNull() is explicitly null-aware - unlike the != None comparison in Q52, it doesn ' t rely on Python equality semantics. Under the hood it maps to the SQL expression order_amount IS NOT NULL, which is unambiguous in both SQL and Spark.
Both df.filter(df.order_amount.isNotNull()) and df.dropna(subset=[ ' order_amount ' ]) produce identical results. The choice between them is stylistic - isNotNull() reads more explicitly as a filter condition, while dropna is more compact when handling multiple columns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
45. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to share curated data with an external organization. The solution must meet the following requirements:
* The organization will use its own compute platform to query the data.
* Access to the data must be centrally governed by using Unity Catalog.
* Administrative effort must be minimized.
What should you do?
Antwort: D
Begründung:
Delta Sharing is designed to share governed data securely with recipients outside an Azure Databricks workspace. The external organization can query the shared data from its own compatible compute platform without receiving workspace access or requiring a Databricks SQL warehouse. Unity Catalog centrally controls which tables, views, or other objects are included in the share and which recipients can access them.
Moving files to an SFTP server creates additional copies and requires custom transfer and security administration. Lakeflow Connect is intended for ingesting data into Databricks rather than sharing curated data externally. Granting workspace access or creating a SQL warehouse would require the recipient to use Databricks-managed resources. Delta Sharing therefore provides the required open access model, centralized governance, and minimal administrative effort.
46. Frage
You have an Azure Databricks workspace named Workspace1 that contains a Git folder linked to a remote Git repository. The Git folder contains a Databricks notebook named Notebook1.
From the main branch, you create a feature branch named Branch1 and commit changes to Notebook1.
Another user commits changes to Notebook1 in main.
When you attempt to merge Branch1 into main, a merge conflict occurs.
You need to ensure that Notebook1 in main includes the changes from both branches.
What should you do?
Antwort: D
Begründung:
Branch1 must first incorporate the current changes from main. During that merge, the conflicting sections of Notebook1 can be reviewed and resolved so that the resulting feature-branch version contains the required work from both branches. After committing the resolution, Branch1 can be merged into main normally.
Cloning either branch into another Git folder creates another working copy but does not resolve the conflicting histories. Applying changes directly to main bypasses the controlled feature-branch workflow and risks omitting or overwriting one contributor's work. Resolving the conflict on Branch1 also allows the combined notebook to be tested before updating the shared main branch. Therefore, merging main into Branch1, resolving the conflict, and completing the final merge is the correct workflow.
47. Frage
You need to deploy Databricks Asset Bundles to a development environment. The solution must support automated and repeatable deployments across environments.
What should you use?
Antwort: B
Begründung:
The correct answer is C - the Databricks CLI.
Databricks Asset Bundles are deployed using the Databricks CLI (v0.205+) with the commands databricks bundle validate, databricks bundle deploy, and databricks bundle run. The CLI reads the databricks.yml file, resolves the target environment settings, and creates or updates all declared resources (jobs, pipelines, apps) in the workspace. This is the documented, supported deployment mechanism for DABs and integrates naturally into CI/CD pipelines.
Option A (Azure Developer CLI / azd) is a general Azure IaC tool with no native understanding of Databricks bundles. Option B (Git folders) syncs notebook and file content from a Git repository into a workspace - useful for code, but it doesn't deploy Lakeflow Jobs, SDP pipelines, or bundle configurations. Option D (Azure CLI) manages Azure infrastructure (resource groups, storage accounts, etc.) and has no native DAB deployment support.
Reference: https://learn.microsoft.com/en-us/azure/databricks/dev-tools/bundles/deploy-bundle
48. Frage
......
Unsere Webseite EchteFrage ist eine Webseite mit langer Geschichte, die Zertifizierungsantworten zur Microsoft DP-750 Prüfung bietet. Nach langjährigen Bemühungen beträgt die Bestehensrate der Microsoft DP-750 Zertifizierungsprüfung bereits 100%. Der Inhalt unserer Lehrbücher aktualisieren sich ständig, damit die Schulungsunterlagen zur Microsoft DP-750 Zertifizierungsprüfung immer korekkt sind. Darüber hinaus können Sie einjährige Aktualisierung genießen, wenn Sie unsere Dumps gekauft haben.
DP-750 Fragen Antworten: https://www.echtefrage.top/DP-750-deutsch-pruefungen.html