2026 The Best Certified-Data-Engineer-Professional: Test Databricks Certified Data Engineer Professional Sample Online

In order to serve you better, we have a complete system for you if you choose us. We have free demo for Certified-Data-Engineer-Professional training materials for you to have a try. If you have decided to buy Certified-Data-Engineer-Professional exam dumps of us, just add them to your cart, and pay for it, our system will send the downloading link and password to you within ten minutes, and if you don’t receive, just contact us, we will solve this problem for you as quickly as possible. For Certified-Data-Engineer-Professional Training Materials, we also have after-service, if you have questions about the exam dumps, you can contact us by email.
| Section | Objectives |
|---|
| Cost & Performance Optimisation | - Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Understand deletion vectors and liquid clustering
- 3. Apply data skipping and file pruning techniques
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
|
| Ensuring Data Security and Compliance | - Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Apply anonymization and pseudonymization techniques
- 3. Use row filters and column masks for sensitive data
- Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
|
| Monitoring and Alerting | - Monitoring
- 1. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 4. Use Query Profiler and Spark UI to monitor workloads
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Develop User-Defined Functions using Pandas/Python UDFs
- Building and Testing ETL Pipelines
- 1. Use APPLY CHANGES APIs for change data capture
- 2. Configure environments, dependencies, memory, and retry behavior
- 3. Develop unit and integration tests for data processing code
- 4. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 5. Use control flow operators in pipeline components
- 6. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 7. Compare streaming tables and materialized views
- 8. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
|
| Data Modelling | - Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Optimize data layout using Liquid Clustering
- 3. Design and implement scalable data models using Delta Lake
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Ingest data from message buses and cloud storage
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Data Sharing and Federation | - Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
>> Test Certified-Data-Engineer-Professional Sample Online <<
100% Pass 2026 Authoritative Databricks Certified-Data-Engineer-Professional: Test Databricks Certified Data Engineer Professional Sample Online
Our company is a professional certificate exam materials provider, and we have worked on this industry for years, therefore we have rich experiences. Certified-Data-Engineer-Professional exam dumps of us have questions and answers, and it will be easier for you to check the right answers after practicing. Certified-Data-Engineer-Professional Exam Braindumps are famous for high quality, we use the shilled professionals to compile them, and the quality is guarantee. Furthermore, our professional technicians will check the safety of our website, and we will provide you with a safe shopping environment.
Databricks Certified Data Engineer Professional Sample Questions (Q156-Q161):
NEW QUESTION # 156
A data engineer is tasked with building a nightly batch ETL pipeline that processes very large volumes of raw JSON logs from a data lake into Delta tables for reporting. The data arrives in bulk once per day, and the pipeline takes several hours to complete. Cost efficiency is important, but performance and reliability of completing the pipeline are the highest priorities. Which type of Databricks cluster should the data engineer configure?
- A. A job cluster configured to autoscale across multiple workers during the pipeline run.
- B. A lightweight single-node cluster with low worker node count to reduce costs.
- C. A high-concurrency cluster designed for interactive SQL workloads.
- D. An all-purpose cluster always kept running to ensure low-latency job startup times.
Answer: A
Explanation:
Job clusters are optimized for automated production workloads. They start when a job is triggered and terminate automatically once the task completes. This ensures cost control while maintaining performance and reliability for batch ETL. Autoscaling allows Databricks to add or remove workers dynamically based on workload size, ensuring large data volumes are processed efficiently.
All-purpose clusters are intended for development or ad-hoc workloads, not scheduled ETL.
NEW QUESTION # 157
A company processes semi-structured JSON files from an external source using Auto Loader in a classic Databricks job. Occasionally, records arrive with null critical fields, invalid types, or unexpected nested schema variations. The engineer must ensure that malformed or non- conforming records are not dropped silently and are captured in a separate quarantine table. The pipeline should continue processing good records into the Bronze layer without failing the job, and the approach must support both batch and streaming ingestion.
The data engineer needs to build a robust ingestion pattern that automatically routes bad records to a quarantine Delta table, while still ingesting good records into the Bronze layer for further processing.
Which approach fulfills the quarantine mechanism in this ingestion architecture?
- A. Use Auto Loader with LDP and implement an EXPECT () constraint with a record audit logic to route bad records.
- B. Create a notebook job with inferSchema=True, write a streaming query with .foreachBatch() and catch exceptions using try/except to redirect failed batches to quarantine.
- C. Use Lakeflow Spark Declarative Pipelines with a SQL pipeline; configure it to drop rows with nulls using where critical_fields is not null, and rely on audit logs for malformed data.
- D. Use Auto Loader with failFast mode to set to false, and enable schema evolution; invalid records will be silently ignored during ingestion.
Answer: A
Explanation:
Lakeflow Spark Declarative Pipelines provide built-in support for data quality enforcement using EXPECT clauses. By defining expectations on critical fields and configuring the pipeline to audit or quarantine failed records, malformed or non-conforming JSON records are automatically routed to a quarantine Delta table while valid records continue flowing into the Bronze layer. This approach is robust, auditable, works for both batch and streaming ingestion, and avoids silently dropping bad data or failing the pipeline.
NEW QUESTION # 158
A view is registered with the following code:
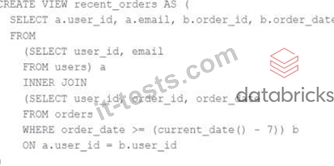
Both users and orders are Delta Lake tables.
Which statement describes the results of querying recent_orders?
- A. The versions of each source table will be stored in the table transaction log; query results will be saved to DBFS with each query.
- B. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
- C. All logic will execute when the table is defined and store the result of joining tables to the DBFS; this stored data will be returned when the table is queried.
- D. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
Answer: D
NEW QUESTION # 159
A data engineer is evaluating tools to build a production-grade data pipeline. The team must process change data from cloud object storage, filter out or isolate invalid records, and ensure the timely delivery of clean data to downstream consumers. The team is small, under tight deadlines, and wants to minimize operational overhead while keeping pipelines auditable and maintainable.
Which approach should the data engineer implement?
- A. Implement ingestion using Auto Loader with Structured Streaming, and manage invalid data handling and table updates using checkpointing and merge logic.
- B. Use LDP to build declarative pipelines with Streaming Tables and Materialized Views, leveraging built-in support for data expectations and incremental processing.
- C. Use a hybrid approach: Ingest with Auto Loader into Bronze tables, then process using SQL queries in Databricks Workflows to generate cleaned Silver and Gold tables on a schedule.
- D. Ingest data directly into Delta tables via Spark jobs, apply data quality filters using UDFs, and use LDP for creating Materialized Views.
Answer: B
Explanation:
LDP provides a declarative framework for building production-grade pipelines with minimal operational overhead. Streaming Tables and Materialized Views handle incremental processing automatically, while built-in data expectations allow invalid records to be filtered or isolated in a consistent and auditable way. This approach is well suited for small teams under tight deadlines, as it simplifies maintenance, improves reliability, and ensures timely delivery of clean data to downstream consumers.
NEW QUESTION # 160
The marketing team is looking to share data in an aggregate table with the sales organization, but the field names used by the teams do not match, and a number of marketing specific fields have not been approval for the sales org.
Which of the following solutions addresses the situation while emphasizing simplicity?
- A. Add a parallel table write to the current production pipeline, updating a new sales table that varies as required from marketing table.
- B. Create a new table with the required schema and use Delta Lake's DEEP CLONE functionality to sync up changes committed to one table to the corresponding table.
- C. Create a view on the marketing table selecting only these fields approved for the sales team alias the names of any fields that should be standardized to the sales naming conventions.
- D. Instruct the marketing team to download results as a CSV and email them to the sales organization.
- E. Use a CTAS statement to create a derivative table from the marketing table configure a production jon to propagation changes.
Answer: C
Explanation:
Creating a view is a straightforward solution that can address the need for field name standardization and selective field sharing between departments. A view allows for presenting a transformed version of the underlying data without duplicating it. In this scenario, the view would only include the approved fields for the sales team and rename any fields as per their naming conventions.
NEW QUESTION # 161
......
As we all know that the better the products are, the more proffesional the according services are. So are our Certified-Data-Engineer-Professional exam braindumps! Not only we provide the most effective Certified-Data-Engineer-Professional study guide, but also we offer 24 hours online service to give our worthy customers Certified-Data-Engineer-Professional guides and suggestions. Your time will be largely saved for our workers know about our Certified-Data-Engineer-Professional practice materials better. Trust us and give yourself a chance to success!
Valid Certified-Data-Engineer-Professional Test Question: https://www.it-tests.com/Certified-Data-Engineer-Professional.html
- Evaluate Yourself with Online Databricks Certified-Data-Engineer-Professional Practice Test Engine 😲 Search on ➡ www.torrentvce.com ️⬅️ for 【 Certified-Data-Engineer-Professional 】 to obtain exam materials for free download 😬Certified-Data-Engineer-Professional Latest Exam Registration
- Trustworthy Certified-Data-Engineer-Professional Exam Content 🚇 Exam Certified-Data-Engineer-Professional Reference 💄 Accurate Certified-Data-Engineer-Professional Test 🍚 Open [ www.pdfvce.com ] enter 《 Certified-Data-Engineer-Professional 》 and obtain a free download 🏘Certified-Data-Engineer-Professional Latest Exam Discount
- Accurate Certified-Data-Engineer-Professional Test 😲 Certified-Data-Engineer-Professional Reliable Dump 📉 Accurate Certified-Data-Engineer-Professional Test 🐸 The page for free download of 「 Certified-Data-Engineer-Professional 」 on ⏩ www.troytecdumps.com ⏪ will open immediately 🎐Exam Certified-Data-Engineer-Professional Reference
- Certified-Data-Engineer-Professional PDF Question 💋 Exam Certified-Data-Engineer-Professional Reference 🔒 Passing Certified-Data-Engineer-Professional Score 🏅 Search for ( Certified-Data-Engineer-Professional ) and easily obtain a free download on ✔ www.pdfvce.com ️✔️ 🔉Latest Certified-Data-Engineer-Professional Test Sample
- Certified-Data-Engineer-Professional Latest Exam Discount 🦗 Accurate Certified-Data-Engineer-Professional Test 🥇 Certified-Data-Engineer-Professional Examcollection 😂 Open website 「 www.troytecdumps.com 」 and search for ▶ Certified-Data-Engineer-Professional ◀ for free download 🛂Latest Certified-Data-Engineer-Professional Test Sample
- Updated Test Certified-Data-Engineer-Professional Sample Online - Trustable Valid Certified-Data-Engineer-Professional Test Question - Hot Databricks Databricks Certified Data Engineer Professional 💼 Search for ⮆ Certified-Data-Engineer-Professional ⮄ and obtain a free download on { www.pdfvce.com } 🤡Reliable Certified-Data-Engineer-Professional Test Cost
- Reliable Certified-Data-Engineer-Professional Test Preparation ❇ Certified-Data-Engineer-Professional PDF Question 🗣 Accurate Certified-Data-Engineer-Professional Test 🏚 ⮆ www.testkingpass.com ⮄ is best website to obtain ➠ Certified-Data-Engineer-Professional 🠰 for free download 🆒Trustworthy Certified-Data-Engineer-Professional Exam Content
- Valid Test Certified-Data-Engineer-Professional Fee 📋 Relevant Certified-Data-Engineer-Professional Answers 🏐 Exam Certified-Data-Engineer-Professional Reference 🔕 Search for ➥ Certified-Data-Engineer-Professional 🡄 and download exam materials for free through ☀ www.pdfvce.com ️☀️ 🆎Valid Certified-Data-Engineer-Professional Exam Bootcamp
- Choose The Right Databricks Certified-Data-Engineer-Professional and Get Certified Today! 🐴 Download { Certified-Data-Engineer-Professional } for free by simply searching on ✔ www.prepawayete.com ️✔️ ⏰Exam Certified-Data-Engineer-Professional Reference
- Reliable Certified-Data-Engineer-Professional Test Cost 🏅 Certified-Data-Engineer-Professional Reliable Dump 🏎 Certified-Data-Engineer-Professional Latest Exam Registration 🤕 ➥ www.pdfvce.com 🡄 is best website to obtain ➠ Certified-Data-Engineer-Professional 🠰 for free download ➿Reliable Certified-Data-Engineer-Professional Test Preparation
- Databricks - The Best Test Certified-Data-Engineer-Professional Sample Online 🌇 Search for 【 Certified-Data-Engineer-Professional 】 on ➥ www.prep4sures.top 🡄 immediately to obtain a free download 🗽Relevant Certified-Data-Engineer-Professional Answers
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, ehoroskop.net, www.stes.tyc.edu.tw, creative-commission.com, www.stes.tyc.edu.tw, Disposable vapes