Microsoft AI-103是IT專業人士的首選,特別是那些想晉升的IT職員。Microsoft的AI-103是一個可以給你的職業生涯帶來重大影響的考試,而獲得AI-103認證是作為IT職業發展的有力保證。AI-103考古題已經幫助了成千上萬的考生獲得成功,這是一個高品質的題庫資料。我們提供給您最近更新的AI-103題庫資料,來確保您通過認證考試,如果您一次沒有通過考試,我們將給您100%的退款保證。
| Section | Objectives |
|---|---|
| Topic 1: Plan and Manage Azure AI Solutions | - Model selection and lifecycle management - Azure AI resource provisioning and configuration - Responsible AI principles and governance |
| Topic 2: Implement Computer Vision Solutions | - Image classification and object detection - OCR and document intelligence |
| Topic 3: Knowledge Mining and Information Retrieval | - Azure AI Search configuration - RAG (Retrieval Augmented Generation) patterns - Indexing and semantic search |
| Topic 4: Develop Generative AI Applications and Agents | - Azure OpenAI Service integration
|
| Topic 5: Implement Natural Language Processing Solutions | - Text analytics and summarization - Translation and multilingual support - Language understanding and intent recognition |
我的很多IT行業的朋友為了通過Microsoft AI-103 認證考試花費了很多時間和精力,但是他們沒有選擇培訓班或者網上培訓,所以對他們而言通過考試是比較有難度的,一般他們的一次性通過的幾率很小。幸運地是NewDumps提供了最可靠的培訓工具。NewDumps提供的培訓材料包括Microsoft AI-103 認證考試的類比測試軟體和相關類比試題,練習題和答案。我們可以提供最佳最新的Microsoft AI-103 認證考試的練習題和答案來滿足你的需求。
問題 #25
You have a Microsoft Foundry project that contains two agents named PolicyWriter and RiskReviewer.
PolicyWriter generates draft updates for customer policies, and RiskReviewer reviews the drafts. In the visual builder, you need to create a workflow that meets the following requirements:
* Finalizes low-risk updates without manual intervention
* Ensures predictable execution across the agents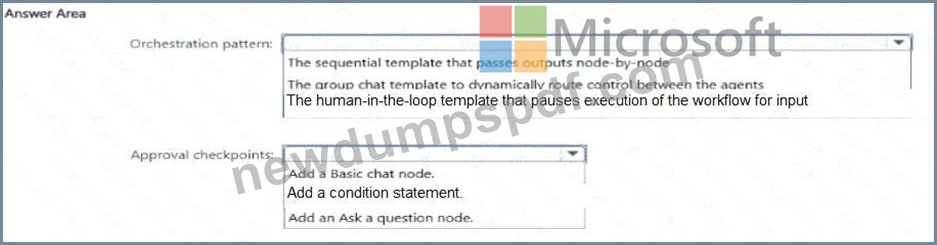
答案:
解題說明: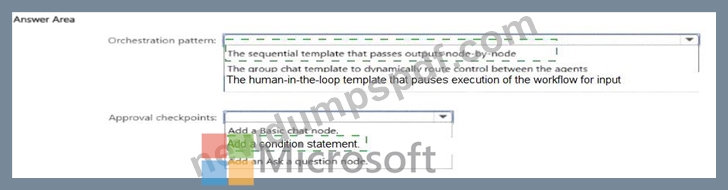
Explanation:
* Orchestration pattern: The sequential template that passes outputs node-by-node
* Approval checkpoints: Add a condition statement
Use the sequential orchestration template because the agents must execute in a fixed, predictable order.
PolicyWriter first generates the proposed policy update, and its output is then passed directly to RiskReviewer. Microsoft defines the sequential pattern as passing the result from one agent to the next in a defined order, making it appropriate for deterministic, multistage processing. The group-chat pattern would allow control to move dynamically between agents, which would reduce execution predictability.
After RiskReviewer returns a structured risk classification, add a condition statement that evaluates the result. The low-risk branch can proceed directly to the finalization action without requesting human input. A separate higher-risk branch can route to an approval step, such as an Ask a question node. Adding an Ask a question node without conditional branching would pause every workflow execution, including low-risk updates, and therefore would not satisfy the automation requirement. Microsoft Foundry workflows support if
/else branching and condition expressions for selecting the next action.
Study Guide alignment: implement orchestrated multi-agent solutions and build autonomous or semiautonomous workflows with safeguards and approval-flow controls .
問題 #26
You have a Microsoft Foundry project that contains an agent.
The agent uses a knowledge source built from documents stored in Azure Blob Storage. The documents include digitally scanned PDFs that contain multipage tables.
You have an ingestion job that extracts only plain text, causing loss of table structure, headings, and page- number metadata.
Users frequently ask questions that require the retrieval of specific table rows across the pages.
You need to configure an ingestion job for a Retrieval Augmented Generation (RAG) pipeline that performs optical character recognition (OCR) on scanned PDFs, preserves tables and headings as structure-aware chunks, and stores page-number metadata with each chunk.
How should you configure the ingestion job?
答案:B
解題說明:
The correct configuration is advanced data parsing because the issue is not merely OCR; the ingestion job must preserve document structure for reliable RAG retrieval. Microsoft guidance for advanced parsing states that it automatically detects tables across all pages, including tables in scanned documents, merges tables that span multiple pages, restores column headers, and creates table chunks with metadata such as table index, shape, page numbers, section headings, and table previews. This directly satisfies the requirement to retrieve specific rows from multipage tables while retaining source-page context.
Basic parsing with fixed-size chunking would flatten the document into arbitrary text fragments, which is the current failure mode. OCR with page-level chunking improves text extraction from scanned PDFs, but it does not provide structure-aware chunks that preserve headings and table relationships across pages. Storing each page as a single chunk is too coarse for row-level retrieval and can bury relevant table rows in excessive context. Advanced data parsing is purpose-built for RAG ingestion because it produces semantically meaningful, retrievable chunks and enriches them with metadata needed for citations and grounding.
Reference topics: RAG ingestion, advanced parsing, OCR, table extraction, structure-aware chunking, page metadata, and Azure Blob Storage document ingestion.
問題 #27
You have a Microsoft Foundry agent that grounds responses from an Azure Search index that contains the following:
- Searchable text fields for product names and product codes
- A vector field that stores embeddings for product descriptions
You need to ensure that users can query the index by using the following:
- Exact product names or codes
- Natural language descriptions of the products
What should you configure?
答案:C
解題說明:
To meet your requirements, you need to configure a Hybrid Search with Semantic Ranking in Azure AI Search. This setup combines keyword matching for exact identifiers with vector search for natural language queries, delivering the most accurate grounding data to your Microsoft Foundry agent.
Reference:
https://www.tredence.com/blog/searchsmart-enhancing-rag-with-azure-ai-search-service
問題 #28
You have a custom named entity recognition (NER) project in Azure Language in Foundry Tools for support tickets. The schema for the project contains an entity type named ContactInfo.
In tagged training files, ContactInfo is used for phone numbers, email addresses, and social media handles.
Model evaluation shows low precision for ContactInfo, including false positives in which nearby text is extracted as ContactInfo.
You need to improve the precision of the project.
What should you do before retraining the model?
答案:A
解題說明:
To improve the precision of the project before retraining the model, you should replace ContactInfo by using Phone, Email, and SocialMedia entities, and then relabel every matching span.
Reduces Model Confusion: Combining distinct types of data (like phone numbers, emails, and usernames) into a single generic entity (ContactInfo) creates conflicting patterns for the model.
Splitting them allows the model to learn the specific, unique syntax rules of each type.
Eliminates Over-extraction: When an entity is too broad, the model struggles to identify where the entity begins and ends, leading to false positives by grabbing adjacent text. Distinct entities provide sharper, cleaner boundaries.
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/language-service/custom-named-entity-recognition/overview
問題 #29
You need to configure Agent1 to meet the security and compliance requirements.
What should you use?
答案:D
解題說明:
The correct answer is B. Personally Identifiable Information (PII) Detection . The case study states that Agent1 must never reveal customer information , even if a document containing customer data is added accidentally to the product sheet repository in storage1. This is a privacy and compliance control requirement, so the appropriate capability is PII Detection.
Azure Language PII Detection is a Foundry Tools capability that identifies, classifies, and redacts sensitive information across text, conversations, and native documents. Microsoft states that PII Detection can be used to implement privacy controls, reduce sensitive data exposure, and support compliance requirements. In this scenario, PII Detection should be applied to retrieved product-sheet content and generated responses so customer names, contact details, identifiers, and other sensitive values are not exposed to users.
Prompt Shields are important for a separate requirement: protecting Agent1 from malicious instructions hidden in documents or embedded text. Microsoft describes Prompt Shields for documents as protection against hidden instructions embedded in external content. However, the option that directly satisfies the requirement to prevent disclosure of customer information is PII Detection. Self-harm and violence filters address harmful-content categories, not privacy leakage.
問題 #30
......
NewDumps的AI-103考古題有著讓你難以置信的命中率。這個考古題包含實際考試中可能出現的一切問題。因此,只要你好好學習這個考古題,通過AI-103考試就會非常容易。作為Microsoft的一項重要的考試,AI-103考試的認證資格可以給你帶來很大的好處。所以你絕對不能因為失去這次可以成功通過考試的機會。NewDumps承諾如果考試失敗就全額退款。為了你能順利通過AI-103考試,趕緊去NewDumps的網站瞭解更多的資訊吧。
AI-103在線考題: https://www.newdumpspdf.com/AI-103-exam-new-dumps.html