What's more, part of that Lead2Passed DP-750 dumps now are free: https://drive.google.com/open?id=1TOJZgL6DrPxURRHm4i3_nDi-ODuaAwT4
The Implementing Data Engineering Solutions Using Azure Databricks (DP-750) is one of the popular exams of Microsoft DP-750. It is designed for Microsoft aspirants who want to earn the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification and validate their skills. The DP-750 test is not an easy exam to crack. It requires dedication and a lot of hard work. You need to prepare well to clear the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) test on the first attempt. One of the best ways to prepare successfully for the DP-750 examination in a short time is using real DP-750 Exam Dumps.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
Studying for attending DP-750 exam pays attention to the method. The good method often can bring the result with half the effort, therefore we in the examination time, and also should know some test-taking skill. The DP-750 quiz guide on the basis of summarizing the past years, the answers have certain rules can be found, either subjective or objective questions, we can find in the corresponding module of similar things in common. To this end, the DP-750 Exam Dumps have summarized some types of questions in the qualification examination to help you pass the DP-750 exam.
NEW QUESTION # 53
You have an Azure Databricks workspace.
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically.
You need to configure compute for the pipeline. The solution must minimize operational costs and effort.
What should you use?
Answer: B
Explanation:
The best option for a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically while keeping costs and administrative effort low is a job cluster that uses autoscaling.
Lowest Costs: Job clusters (also called automated compute) are billed at a significantly lower Data Processing Unit (DBU) rate compared to all-purpose clusters. By enabling autoscaling, Databricks dynamically allocates or removes worker nodes based on real-time pipeline demand, ensuring you never pay for unutilized resources.
Low Administrative Effort: While Databricks generally recommends Serverless compute as the absolute ideal for zero-admin pipelines, when selecting from classic compute options, a job cluster automatically handles its own lifecycle. It deploys when the pipeline starts executing and terminates automatically when processing is finished.
Incorrect:
[Not A]
Databricks SQL warehouses are designed to run standalone materialized views and streaming tables via standard SQL. They are not the native compute vehicle for running a fully automated, dedicated Lakeflow Spark Declarative Pipelines (SDP) deployment framework.
[Not B]
All-purpose compute is meant for interactive development, debugging, and ad-hoc analysis. It is billed at a much higher DBU rate, which violates the requirement to keep costs low.
[Not D]
Aside from the higher billing rate of all-purpose compute, a single-node configuration does not scale horizontally. This directly conflicts with your requirement to build a pipeline that scales automatically.
Reference:
https://docs.databricks.com/gcp/en/ldp/auto-scaling
NEW QUESTION # 54
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Tabid.
Table! is written by batch jobs every hour and is queried frequently by filtering two columns named Customerld and EventDate.
You expect Table1 to grow significantly over time.
The rows in Table1 are frequently updated and deleted to support compliance requests.
You need to keep query performance consistent as Table1 grows. The solution must minimize update and deletion effort.
What should you include in the solution? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.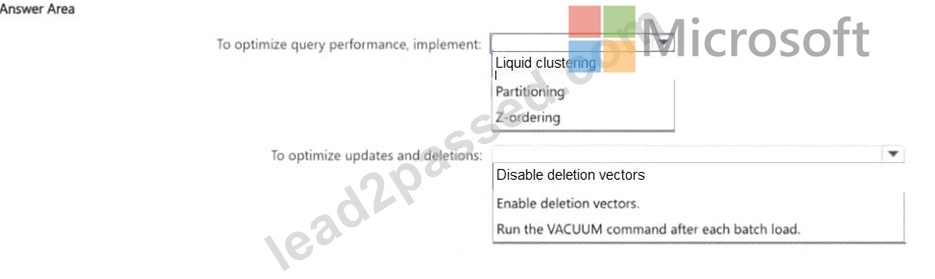
Answer:
Explanation: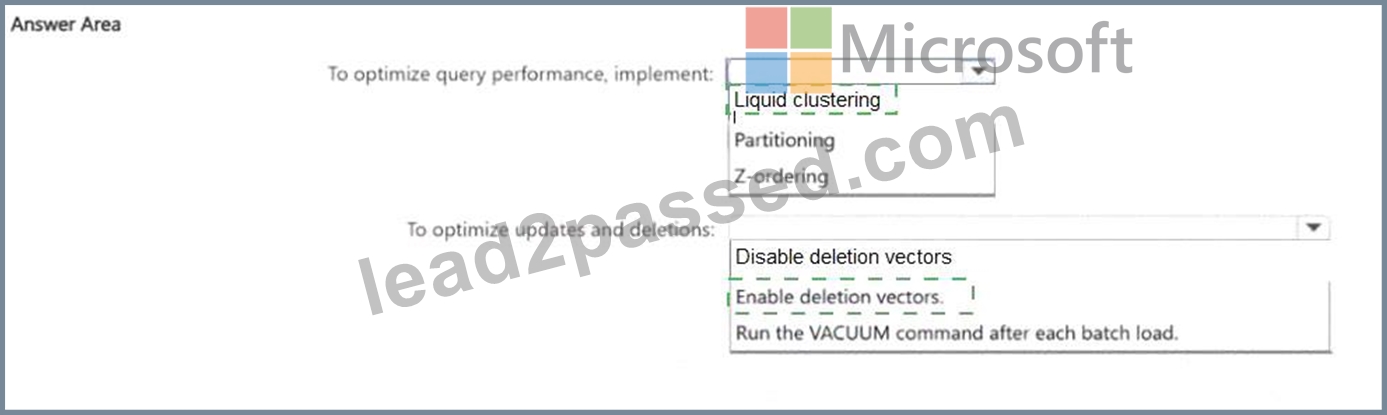
Explanation:
Two features work together to keep performance consistent and update costs low:
OPTIMIZE with ZORDER BY (CustomerId, EventDate). Z-Ordering co-locates rows with the same CustomerId and EventDate values in the same Parquet files. When a query filters on those columns, the Delta engine uses file statistics to skip files that can't possibly contain matching rows (data skipping). As the table grows, skipping scales proportionally - query time stays consistent.
Deletion Vectors (delta.enableDeletionVectors = true). When a row is updated or deleted, instead of rewriting the entire Parquet file, Delta marks the affected row in a small companion deletion vector file. This dramatically reduces write amplification for the frequent compliance-driven updates and deletions the question describes. Actual file rewrites are deferred to the next OPTIMIZE run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/data-skipping
NEW QUESTION # 55
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1.
Table1 stores customer profile data.
Business users must analyze how customer profile records change over time. They must also be able to query earlier versions of the table.
You need to implement a solution that:
* Maintains persistent historical versions of customer profile records for long-term analysis.
* Allows users to query earlier versions of the Delta table.
* Minimizes maintenance effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.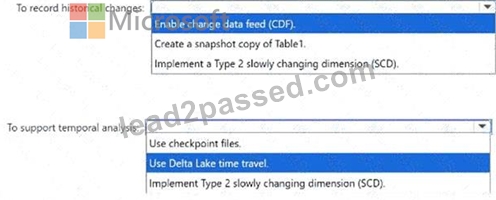
Answer:
Explanation: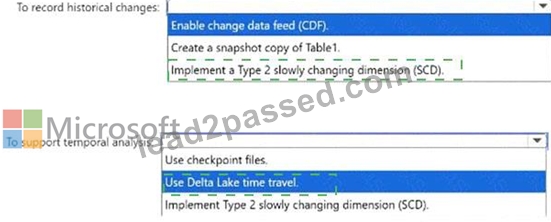
Explanation:
To record historical changes: Implement a Type 2 slowly changing dimension (SCD).
To support temporal analysis: Use Delta Lake time travel.
A Type 2 slowly changing dimension preserves customer-profile history by inserting a new record whenever a tracked attribute changes instead of overwriting the existing record. Effective dates, expiration dates, version values, or current-record indicators can identify which version applied during a particular period. This provides persistent business history for long-term analysis. Delta Lake time travel supports temporal analysis of the physical table by allowing users to query an earlier version with VERSION AS OF or TIMESTAMP AS OF. Time travel is useful for auditing and reproducing previous results, but its availability depends on retained Delta log entries and data files. Therefore, it should not replace a Type 2 SCD for permanent customer history. Together, the two features satisfy the historical-record and earlier-version requirements.
NEW QUESTION # 56
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: D
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don't prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely.
Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 57
A data engineer notices slow query performance on a large Delta table in Azure Databricks. The table has frequent updates and deletes. Which action best improves query performance?
Answer: C
Explanation:
OPTIMIZE compacts small files into larger ones, reducing file scan overhead. ZORDER improves data skipping by co-locating related column values. This combination significantly improves query performance on frequently filtered columns. Increasing cluster size does not address file fragmentation. Converting to Parquet removes Delta benefits like ACID transactions.
NEW QUESTION # 58
......
First and foremost, we have high class operation system so we can assure you that you can start to prepare for the DP-750 exam with our study materials only 5 to 10 minutes after payment. Fortunately, you need not to worry about this sort of question any more, since you can find the best solution in this website--our DP-750 Training Materials. With our continued investment in technology, people and facilities, the future of our company has never looked so bright. There are so many advantages of our DP-750 practice test and I would like to give you a brief introduction now.
DP-750 Reliable Test Braindumps: https://www.lead2passed.com/Microsoft/DP-750-practice-exam-dumps.html
P.S. Free 2026 Microsoft DP-750 dumps are available on Google Drive shared by Lead2Passed: https://drive.google.com/open?id=1TOJZgL6DrPxURRHm4i3_nDi-ODuaAwT4