変化する地域に対応するには、問題を解決する効率を改善する必要があります。これは、試験に対処するだけでなく、多くの側面を反映しています。 AI-300実践教材は、あなたがそれを実現するのに役立ちます。 これらの時間に敏感な試験の受験者にとって、重要なニュースで構成される高効率のAI-300の実際のテストは、最も役立つでしょう。 定期的にそれらを練習することによってのみ、あなたはあなたに明らかな進歩が起こったのを見るでしょう。 さらに、AI-300練習教材の獲得を待つのではなく、支払い後すぐにダウンロードできるので、今すぐAI-300成功への旅を始めましょう。
| Section | Weight | Objectives |
|---|---|---|
| Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Implement machine learning model lifecycle and operations | 25–30% | - Register, version, and package models
|
| Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
AI-300のMicrosoft試験問題の高い合格率は98%〜100%であるため、正確かつ最新のAI-300試験トレントで市場に並ぶものがないと誇らしげに主張できます。 成功をもたらす当社の強みと、取得する意図のある認定を疑うことはありません。 AI-300実践教材を使用して、候補者の勝利をますます証明しています。Pass4Test あなたは彼らのような勝者の一人になると信じています。 Operationalizing Machine Learning and Generative AI SolutionsのAI-300学習教材を購入するだけで、より明るい未来を手にすることができます。
質問 # 43
An Azure Machine Learning workspace processes sensitive training data.
The workspace must NOT be accessible from the public internet.
You need to restrict network access.
Which configuration should you implement?
正解:D
解説:
To ensure an Azure Machine Learning (AML) workspace handling sensitive data is not accessible from the public internet, you must disable the Public Network Access flag and implement Private Endpoints. This configuration creates a private link between your Azure Virtual Network (VNet) and the workspace, ensuring traffic never traverses the public internet.
Reference:
https://www.azadvertizer.net/azpolicyadvertizer/438c38d2-3772-465a-a9cc-7a6666a275ce.html
質問 # 44
You manage an Azure Machine Learning workspace. You use Azure Machine Learning Python SDK v2 to configure a trigger to schedule a pipeline job. You need to create a time-based schedule with recurrence pattern.
Which two properties must you use to successfully configure the trigger? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
正解:B、E
質問 # 45
A team is building a generative AI agent by using Retrieval-Augmented Generation (RAG) in Microsoft Foundry.
The team frequently updates prompt content. The team must be able to track changes across contributors while avoiding full application redeployments.
You need to enable rapid prompt iteration with traceability. Applications consuming the agent must be able to use updated prompts without requiring redeployment.
What should you configure for each requirement? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.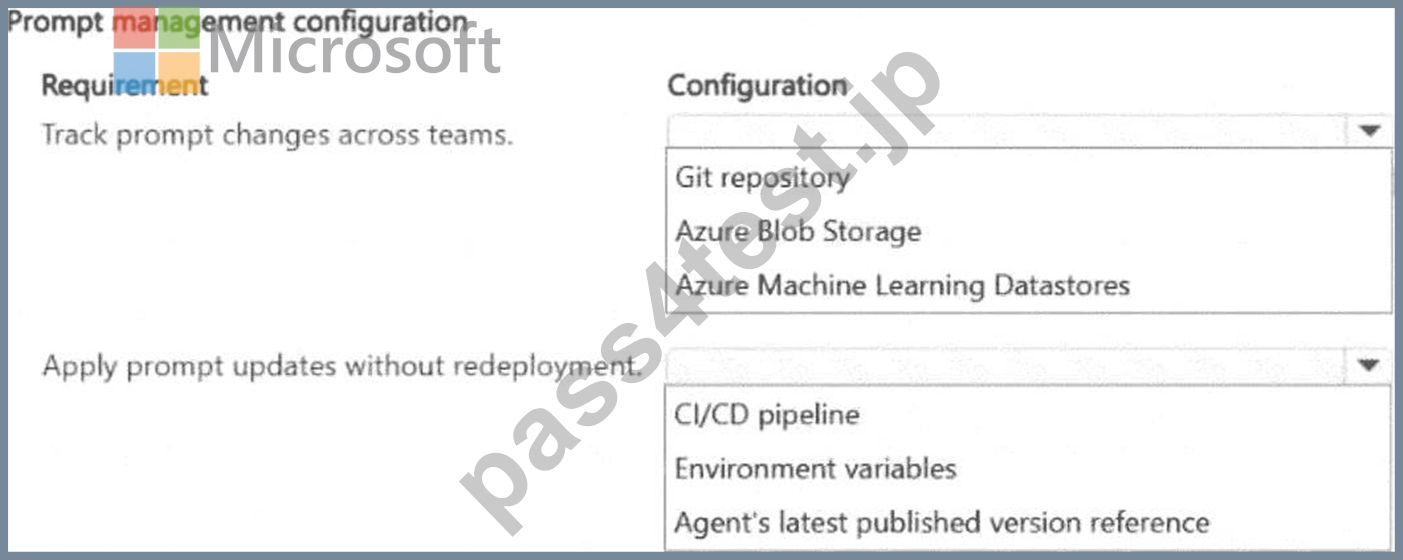
正解:
解説: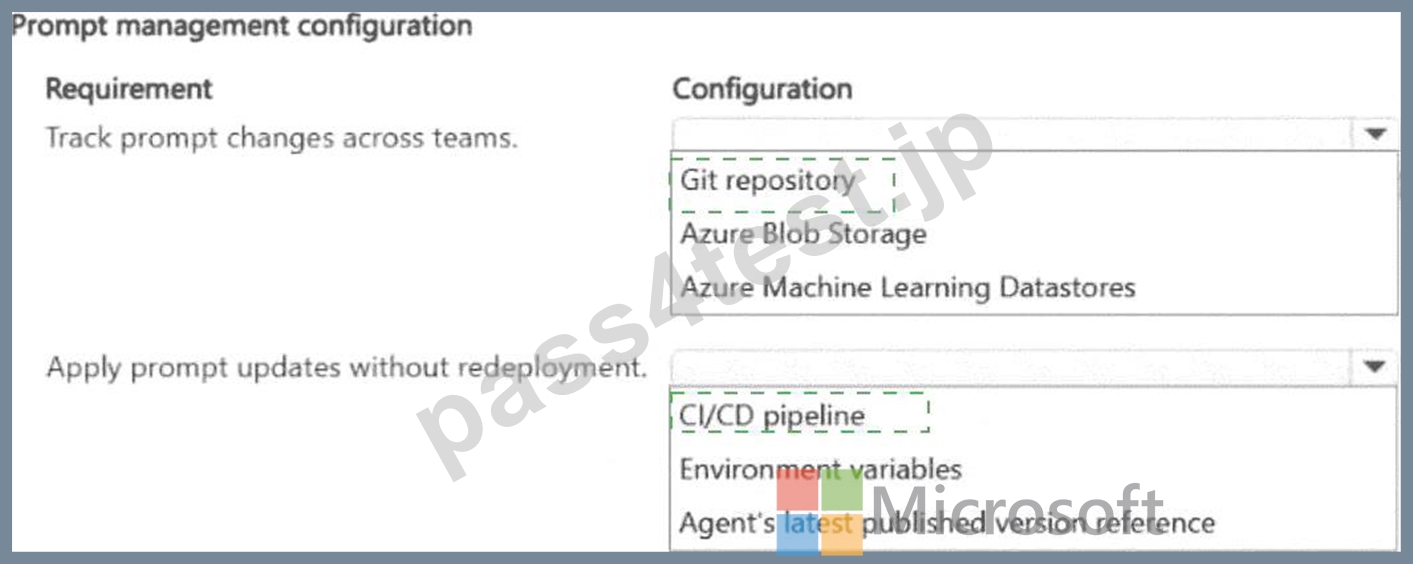
Explanation:
For tracking changes across contributors, Git integration is the answer: by connecting the Microsoft Foundry project to a Git repository, every prompt file change is tracked as a commit with author attribution, timestamp, and diff view, and pull requests enforce review before changes reach production. The Git history provides the complete audit trail and rollback capability needed for traceability. For allowing applications to consume updated prompts without requiring redeployment, Microsoft Foundry ' s prompt management feature allows prompts to be stored and versioned as named artifacts in the project. Applications reference prompts by name and load the latest approved version at inference time, rather than having prompt text hard-coded in the application deployment artifact. This decoupling means updating a prompt is a content operation - not a code deployment - so applications automatically pick up the new prompt without any redeployment.
Microsoft Learn Reference Topic: Prompt management in Microsoft Azure AI Foundry - Git integration and dynamic prompt versioning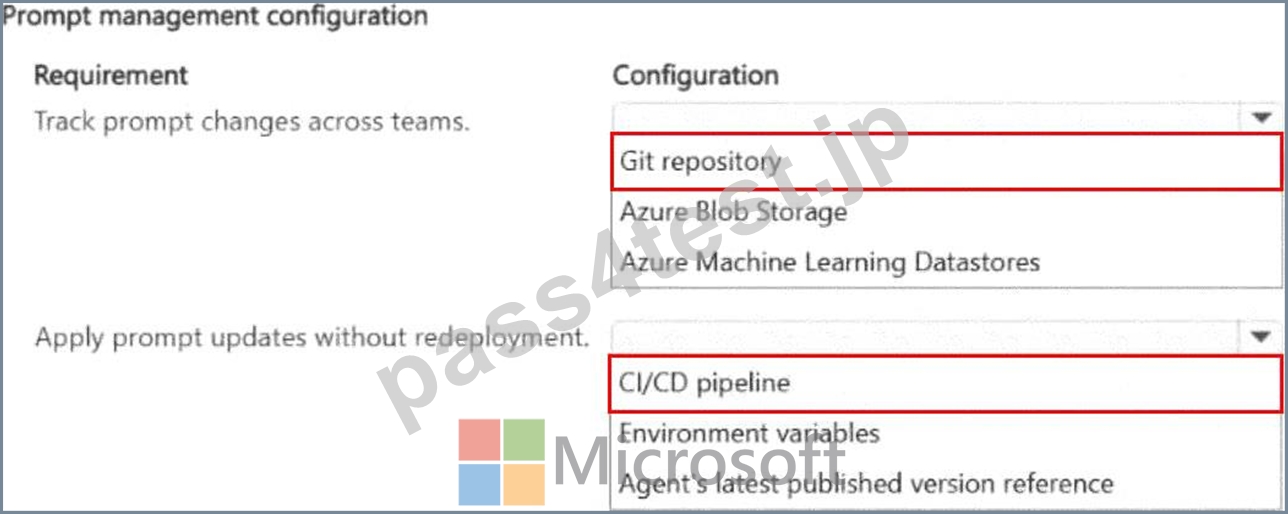
質問 # 46
A team maintains Infrastructure as Code (IaC) templates to provision Azure Machine Learning resources.
Provisioning must be triggered by changes in the templates and executed without manual intervention.
You need to automate resource provisioning.
Which action should you take for each requirement? To answer, move the appropriate actions to the correct requirements. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content . NOTE: Each correct selection is worth one point.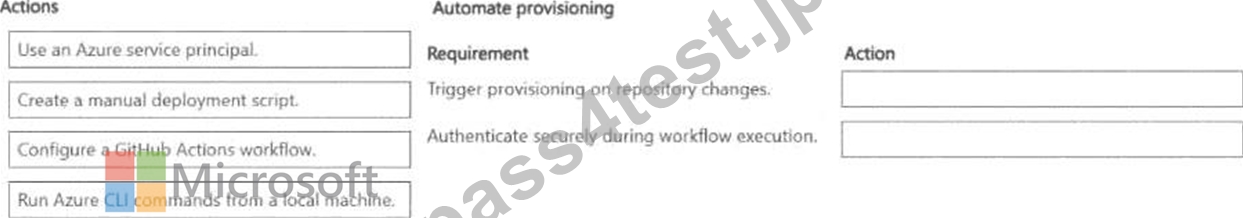
正解:
解説: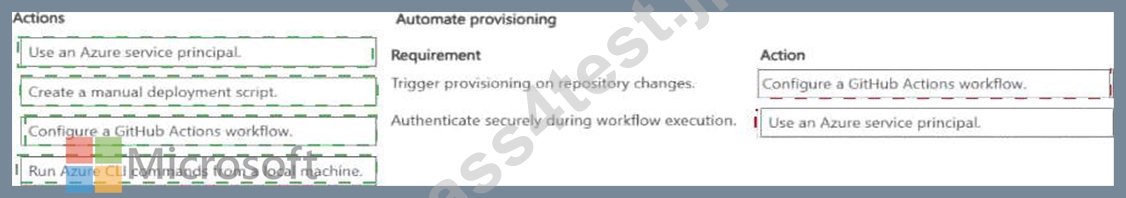
Explanation:
Azure Machine Learning infrastructure can be described as Infrastructure as Code using ARM templates, Bicep, or Terraform. To make provisioning fully automated, two separate concerns must be addressed. First, the trigger: a CI/CD system like GitHub Actions or Azure DevOps Pipelines must detect changes to IaC template files in the repository, configured through a branch-push or pull-request trigger. Second, the execution: the CI/CD pipeline runs the provisioning commands such as az ml workspace create or bicep deploy non-interactively using a service principal or managed identity, eliminating the need for a human to run scripts manually. Together, these two mechanisms deliver the GitOps-style automation that modern MLOps practices require, ensuring every template change automatically results in a consistent, auditable infrastructure update.
Microsoft Learn Reference Topic: Automate Azure Machine Learning with GitHub Actions - CI/CD for ML infrastructure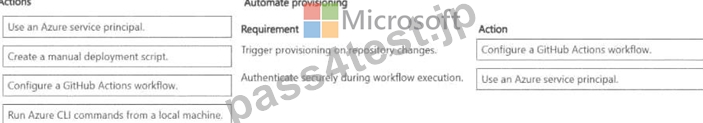
質問 # 47
Hotspot Question
You use Azure Machine Learning to implement hyperparameter tuning for an Azure ML Python SDK v2-based model training.
Training runs must terminate when the primary metric is lowered by 25 percent or more compared to the best performing run.
You need to configure an early termination policy to terminate training jobs.
Which values should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.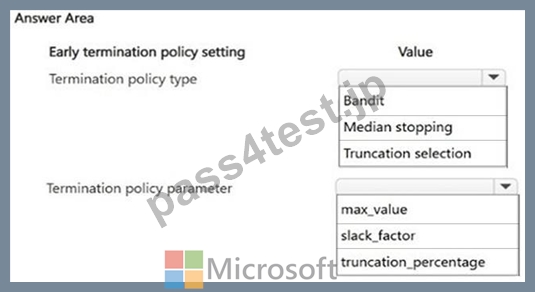
正解:
解説: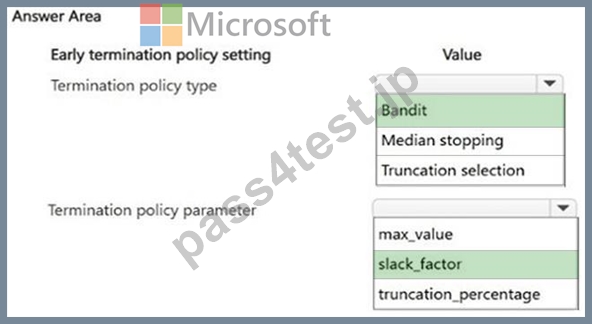
質問 # 48
......
AI-300試験ガイドには、高品質のサービスがあります。 24時間のオンラインサービスを提供しています。 AI-300試験問題の使用中に質問がある場合は、メールでお問い合わせください。 私たちMicrosoftは最大限の忍耐と態度で優れたアフターサービスを提供します。 そして、AI-300練習用トレントの使用中に発生する問題に対する詳細な解決策を提供します。 そして、AI-300の学習資料は、あなたの監督と批判を歓迎します。 私たちのAI-300学習教材の会社で、あなたはOperationalizing Machine Learning and Generative AI Solutions成功の方向を見つけるでしょう。
AI-300日本語版試験解答: https://www.pass4test.jp/AI-300.html