P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by BraindumpsVCE: https://drive.google.com/open?id=1Cmr_HCaRMwdI9kf57Ru2XLpYkjtWPHVY
All the IT professionals are familiar with the Amazon MLA-C01 exam. And all of you dream of owning the most demanding certification. So that you can get the career you want, and can achieve your dreams. With BraindumpsVCE's Amazon MLA-C01 Exam Training materials, you can get what you want.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Processing | 22% | - Data preprocessing and feature engineering - Data pipelining with AWS services ( Glue, Data Brew, etc.) - Handling imbalanced data - Data validation and quality assessment - Data ingestion and transformation |
| Topic 2: MLOps and Monitoring | 28% | - Security and access management for ML - Model monitoring and drift detection - Incident response and remediation - Model lineage and reproducibility - Cost optimization for ML workloads - CI/CD pipelines for ML |
| Topic 3: Model Deployment and Inference | 20% | - SageMaker endpoints configuration - Inference optimization (latency, throughput) - Model versioning and rollback - A/B testing and shadow mode deployment - Model deployment strategies (real-time, batch) |
| Topic 4: Model Development | 30% | - Training and validation strategies - Algorithm selection and model architecture - Transfer learning and fine-tuning - ML frameworks (SageMaker, built-in algorithms) - Hyperparameter optimization - Distributed training |
>> MLA-C01 Reliable Mock Test <<
Our MLA-C01 exam questions have the merits of intelligent application and high-effectiveness to help our clients study more leisurely. If you prepare with our MLA-C01 actual exam for 20 to 30 hours, the MLA-C01 exam will become a piece of cake in front of you. Not only you will find that to study for the exam is easy, but also the most important is that you will get the most accurate information that you need to pass the MLA-C01 Exam.
NEW QUESTION # 174
An ML engineer trained an ML model on Amazon SageMaker to detect automobile accidents from dosed- circuit TV footage. The ML engineer used SageMaker Data Wrangler to create a training dataset of images of accidents and non-accidents.
The model performed well during training and validation. However, the model is underperforming in production because of variations in the quality of the images from various cameras.
Which solution will improve the model's accuracy in the LEAST amount of time?
Answer: A
Explanation:
The model is underperforming in production due to variations in image quality from different cameras. Using the corrupt image transform with the impulse noise option in SageMaker Data Wrangler simulates real-world noise and variations in the training dataset. This approach helps the model become more robust to inconsistencies in image quality, improving its accuracy in production without the need to collect and process new data, thereby saving time.
NEW QUESTION # 175
A company uses a hybrid cloud environment. A model that is deployed on premises uses data in Amazon 53 to provide customers with a live conversational engine.
The model is using sensitive data. An ML engineer needs to implement a solution to identify and remove the sensitive data.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: D
NEW QUESTION # 176
A company runs an Amazon SageMaker domain in a public subnet of a newly created VPC. The network is configured properly, and ML engineers can access the SageMaker domain.
Recently, the company discovered suspicious traffic to the domain from a specific IP address.
The company needs to block traffic from the specific IP address.
Which update to the network configuration will meet this requirement?
Answer: D
NEW QUESTION # 177
An ML engineer is setting up an Amazon SageMaker AI pipeline for an ML model. The pipeline must automatically initiate a re-training job if any data drift is detected.
How should the ML engineer set up the pipeline to meet this requirement?
Answer: C
Explanation:
The correct answer is C. Use SageMaker Model Monitor to detect data drift. Use an AWS Lambda function to automate the re-training job.
Amazon SageMaker Model Monitor is the AWS-recommended solution for automatically detecting data drift in ML pipelines. Data drift occurs when the statistical properties of input features change over time, potentially reducing model accuracy. Model Monitor continuously analyzes incoming data and compares it to the baseline training dataset to identify deviations. It can track both feature distributions and prediction quality metrics.
Once Model Monitor detects data drift, it can trigger automated workflows using AWS Lambda or Amazon EventBridge. An AWS Lambda function can initiate a SageMaker training job to re-train the model using updated datasets, ensuring the ML model remains accurate and reliable. This setup fully automates the response to drift events, meeting the requirement of automatically initiating re-training.
Option A (AWS Glue) is designed for ETL processes but does not natively detect ML-specific data drift.
Option B (Amazon Managed Service for Apache Flink) can process streaming data but does not provide native drift detection for ML pipelines. Option D (Amazon QuickSight anomaly detection) focuses on business intelligence and visual anomaly detection, not automated re-training workflows for ML models.
By integrating SageMaker Model Monitor with Lambda, the ML engineer can maintain model performance proactively, implement automated re-training, and align with AWS best practices for ML solution monitoring, maintenance, and security. This approach ensures continuous validation of model inputs and outputs, reduces operational overhead, and prevents degradation in production ML performance due to unseen data changes.
NEW QUESTION # 178
A company wants to host an ML model on Amazon SageMaker. An ML engineer is configuring a continuous integration and continuous delivery (Cl/CD) pipeline in AWS CodePipeline to deploy the model. The pipeline must run automatically when new training data for the model is uploaded to an Amazon S3 bucket.
Select and order the pipeline ' s correct steps from the following list. Each step should be selected one time or not at all. (Select and order three.)
* An S3 event notification invokes the pipeline when new data is uploaded.
* S3 Lifecycle rule invokes the pipeline when new data is uploaded.
* SageMaker retrains the model by using the data in the S3 bucket.
* The pipeline deploys the model to a SageMaker endpoint.
* The pipeline deploys the model to SageMaker Model Registry.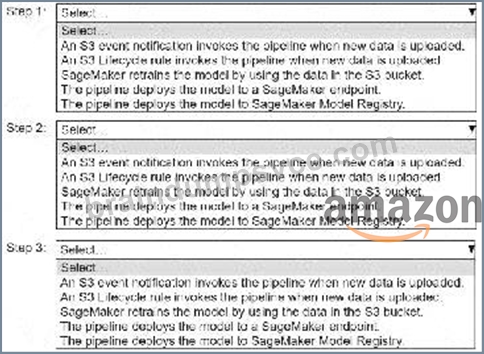
Answer:
Explanation: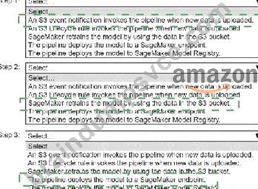
Explanation:
Step 1: An S3 event notification invokes the pipeline when new data is uploaded.
Step 2: SageMaker retrains the model by using the data in the S3 bucket.
Step 3: The pipeline deploys the model to a SageMaker endpoint.
Step 1: An S3 Event Notification Invokes the Pipeline When New Data is Uploaded Why? The CI/CD pipeline should be triggered automatically whenever new training data is uploaded to Amazon S3. S3 event notifications can be configured to send events to AWS services like Lambda, which can then invoke AWS CodePipeline.
How? Configure the S3 bucket to send event notifications (e.g., s3:ObjectCreated:*) to AWS Lambda, which in turn triggers the CodePipeline.
Step 2: SageMaker Retrains the Model by Using the Data in the S3 Bucket Why? The uploaded data is used to retrain the ML model to incorporate new information and maintain performance. This step is critical to updating the model with fresh data.
How? Define a SageMaker training step in the CI/CD pipeline, which reads the training data from the S3 bucket and retrains the model.
Step 3: The Pipeline Deploys the Model to a SageMaker Endpoint
Why? Once retrained, the updated model must be deployed to a SageMaker endpoint to make it available for real-time inference.
How? Add a deployment step in the CI/CD pipeline, which automates the creation or update of the SageMaker endpoint with the retrained model.
Order Summary:
An S3 event notification invokes the pipeline when new data is uploaded.
SageMaker retrains the model by using the data in the S3 bucket.
The pipeline deploys the model to a SageMaker endpoint.
This configuration ensures an automated, efficient, and scalable CI/CD pipeline for continuous retraining and deployment of the ML model in Amazon SageMaker.
NEW QUESTION # 179
......
We own three versions of the MLA-C01 exam torrent for you to choose. They conclude PDF version, PC version and APP online version. You can choose the most convenient version of the MLA-C01 quiz torrent. The three versions of the MLA-C01 test prep boost different strengths and you can find the most appropriate choice. For example, the PDF version is convenient for download and printing and is easy and convenient for review and learning. It can be printed into papers and is convenient to make notes. You can learn the MLA-C01 Test Prep at any time or place and repeatedly practice. The version has no limit for the amount of the persons and times. The PC version of MLA-C01 quiz torrent is suitable for the computer with Windows system. It can simulate real operation exam atmosphere and simulate exams.
MLA-C01 Valid Test Question: https://www.braindumpsvce.com/MLA-C01_exam-dumps-torrent.html
P.S. Free & New MLA-C01 dumps are available on Google Drive shared by BraindumpsVCE: https://drive.google.com/open?id=1Cmr_HCaRMwdI9kf57Ru2XLpYkjtWPHVY