BONUS!!! Download part of DumpExam Databricks-Certified-Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1vA3ckNLAZ8RF51zWjkB9g5lrb5K0koUz
Nowadays, there are more and more people realize the importance of Databricks-Certified-Data-Engineer-Associate, because more and more enterprise more and more attention it. If someone pass the Databricks-Certified-Data-Engineer-Associate exam and own relevant certificates that mean he had good grasp of this field of knowledge, that is to say, he will be popular and valued by more enterprise. In order to help most candidates who want to Pass Databricks-Certified-Data-Engineer-Associate Exam, so we compiled such a study materials to make exam simply. Our Databricks-Certified-Data-Engineer-Associate guide torrent has gone through strict analysis and summary according to the past exam papers and the popular trend in the industry and are revised and updated according to the change of the syllabus and the latest development conditions in the theory and the practice.
| Section | Objectives |
|---|---|
| Data Governance and Quality | - Unity Catalog basics - Data access control and governance - Data quality concepts and management |
| Data Processing and Transformations | - User-defined functions (UDFs) - Apache Spark SQL operations (joins, aggregations, filtering) - Delta Lake fundamentals (tables, transactions, optimization) - PySpark DataFrame transformations |
| Data Ingestion and ELT Development | - Data ingestion using Spark SQL and PySpark - Handling structured and semi-structured data - ETL patterns and transformations |
| Databricks Lakehouse Platform Fundamentals | - Workspace, architecture, and core platform concepts - Clusters, notebooks, and basic Databricks environment usage |
| Productionizing Data Pipelines | - Pipeline deployment and operationalization - Scheduling and monitoring jobs - Databricks Workflows / Jobs orchestration |
>> Databricks-Certified-Data-Engineer-Associate Exam Success <<
Now it is wise choice for you to choose our Databricks-Certified-Data-Engineer-Associate actual test guide materials. Valid exam questions help you study and prepare double results with half works. You will get high-quality 100% pass rate Databricks-Certified-Data-Engineer-Associate learning prep so that you can master the key knowledge and clear exam easily. You can Pass Databricks-Certified-Data-Engineer-Associate Exam in the shortest time and obtain a certification soon. It will benefit you more. Instead of admiring others' redoubtable life, start your new life from choosing valid test dumps. Our Databricks-Certified-Data-Engineer-Associate actual test guide is the pass king in this field which will be the best option for you.
NEW QUESTION # 254
A data engineer is attempting to drop a Spark SQL table my_table and runs the following command:
DROP TABLE IF EXISTS my_table;
After running this command, the engineer notices that the data files and metadata files have been deleted from the file system.
Which of the following describes why all of these files were deleted?
Answer: A
Explanation:
Explanation
managed tables files and metadata are managed by metastore and will be deleted when the table is dropped .
while external tables the metadata is stored in a external location. hence when a external table is dropped you clear off only the metadata and the files (data) remain.
NEW QUESTION # 255
Which of the following must be specified when creating a new Delta Live Tables pipeline?
Answer: D
Explanation:
Option E is the correct answer because it is the only mandatory requirement when creating a new Delta Live Tables pipeline. A pipeline is a data processing workflow that contains materialized views and streaming tables declared in Python or SQL source files. Delta Live Tables infers the dependencies between these tables and ensures updates occur in the correct order. To create a pipeline, you need to specify at least one notebook library to be executed, which contains the Delta Live Tables syntax. You can also specify multiple libraries of different languages within your pipeline. The other options are optional or not applicable for creating a pipeline. Option A is not required, but you can optionally provide a key-value pair configuration to customize the pipeline settings, such as the storage location, the target schema, the notifications, and the pipeline mode. Option B is not applicable, as the DBU/hour cost is determined by the cluster configuration, not the pipeline creation. Option C is not required, but you can optionally specify a storage location for the output data from the pipeline. If you leave it empty, the system uses a default location. Option D is not required, but you can optionally specify a location of a target database for the written data, either in the Hive metastore or the Unity Catalog.
Tutorial: Run your first Delta Live Tables pipeline, What is Delta Live Tables?, Create a pipeline, Pipeline configuration.
NEW QUESTION # 256
Which of the following Structured Streaming queries is performing a hop from a Silver table to a Gold table?
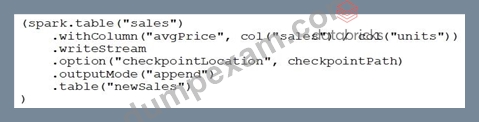
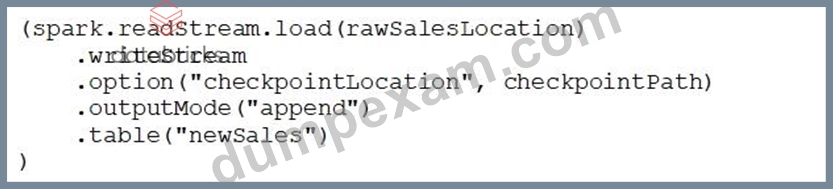
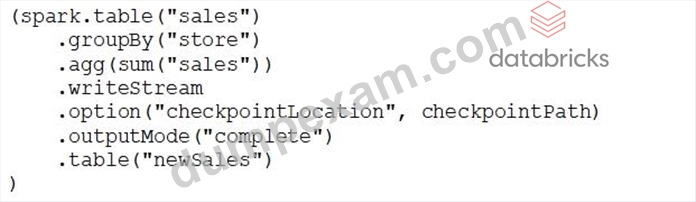
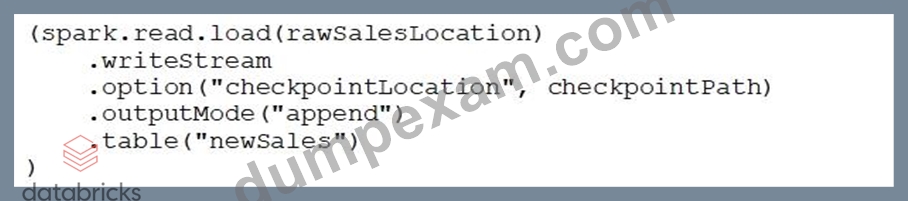
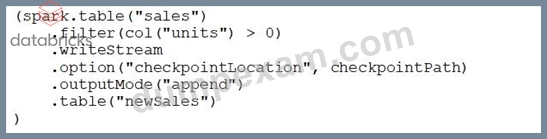
Answer: C
NEW QUESTION # 257
A data engineer has written a function in a Databricks Notebook to calculate the population of bacteria in a given medium.
Analysts use this function in the notebook and sometimes provide input arguments of the wrong data type, which can cause errors during execution.
Which Databricks feature will help the data engineer quickly identify if an incorrect data type has been provided as input?
Answer: C
Explanation:
The Databricks debugger supports setting breakpoints that pause execution and allow inspection of variables. If the wrong data type is passed to the function, the debugger raises an error at runtime, helping the engineer quickly identify the issue.
NEW QUESTION # 258
A data engineer has developed a data pipeline to ingest data from a JSON source using Auto Loader, but the engineer has not provided any type inference or schema hints in their pipeline. Upon reviewing the data, the data engineer has noticed that all of the columns in the target table are of the string type despite some of the fields only including float or boolean values.
Which of the following describes why Auto Loader inferred all of the columns to be of the string type?
Answer: A
Explanation:
Explanation
JSON data is a text-based format that uses strings to represent all values. When Auto Loader infers the schema of JSON data, it assumes that all values are strings. This is because Auto Loader cannot determine the type of a value based on its string representation. https://docs.databricks.com/en/ingestion/auto-loader/schema.html Forexample, the following JSON string represents a value that is logically a boolean: JSON "true" Use code with caution. Learn more However, Auto Loader would infer that the type of this value is string. This is because Auto Loader cannot determine that the value is a boolean based on its string representation. In order to get Auto Loader to infer the correct types for columns, the data engineer can provide type inference or schema hints. Type inference hints can be used to specify the types of specific columns. Schema hints can be used to provide the entire schema of the data.
Therefore, the correct answer is B. JSON data is a text-based format.
NEW QUESTION # 259
......
If you choose our Databricks-Certified-Data-Engineer-Associate study materials and use our products well, we can promise that you can pass the Databricks-Certified-Data-Engineer-Associate exam and get the Databricks-Certified-Data-Engineer-Associate certification. Then you will find you have so many chances to advance in stages to a great level of social influence and success. Our Databricks-Certified-Data-Engineer-Associate Guide Torrent can also provide all candidates with our free demo, in order to exclude your concerts that you can check our Databricks-Certified-Data-Engineer-Associate exam questions. We believe that you will be fond of our Databricks-Certified-Data-Engineer-Associate learning guide.
Pdf Databricks-Certified-Data-Engineer-Associate Free: https://www.dumpexam.com/Databricks-Certified-Data-Engineer-Associate-valid-torrent.html
P.S. Free & New Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by DumpExam: https://drive.google.com/open?id=1vA3ckNLAZ8RF51zWjkB9g5lrb5K0koUz