AI-200学習ガイドは世界を対象としており、ユーザーは非常に広範囲です。ユーザーにより良い体験を提供するために、私たちは常に改善しています。 AI-200試験準備の高い品質と効率は、ユーザーに認められています。当社のAI-200テスト資料の高い合格率は最大の特徴です。 AI-200試験準備を使用している限り、必要なものを確実に収集できます。最短時間でAI-200試験に合格できるだけでなく、夢のあるAI-200認定資格を取得して将来を明るくすることもできます。
| Section | Objectives |
|---|---|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Connect to and consume Azure services | - Integrate Azure services
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
AI-200試験の準備は精巧にまとめられており、非常に効率的です。時間と労力を節約できます。合格率とヒット率も非常に高く、数千人の受験者が当社のAI-200ガイドトレントを信頼し、試験に合格しています。候補者には非常に多くの保証を提供しており、AI-200学習教材を心配なく購入できます。そのため、当社Microsoftが提供するAI-200試験トレントを十分に理解し、最初の試行でAI-200試験に合格できることを願っています。
質問 # 83
Your organization requires that all prompts and completions sent to Azure OpenAI be retained for zero data logging beyond what ' s required for abuse monitoring, per contractual requirements.
What should you do?
正解:C
解説:
The applicable Azure OpenAI control is Modified Abuse Monitoring . Microsoft documents that customers processing highly sensitive or confidential information can apply to modify the normal abuse-monitoring process when they cannot permit Microsoft to store or conduct human review of prompts and completions.
Approval is subject to Microsoft ' s Limited Access eligibility requirements and must be requested through the designated Microsoft process.
For approved configurations, the abuse-monitoring treatment of prompts and completions is modified so that normal human review does not occur. Microsoft guidance on zero-data-retention scenarios specifically directs eligible customers to request Modified Abuse Monitoring rather than attempting to achieve the requirement by disabling unrelated telemetry services.
Disabling Azure Monitor does not change Azure OpenAI ' s service-side abuse-monitoring policy; it only affects customer-configured operational telemetry. Changing the model version likewise has no direct effect on retention requirements. Storing application data in Cosmos DB controls the application ' s own persistence layer and does not govern Azure OpenAI service processing.
Therefore, among the available choices, A is the required action. More precisely, the relevant request is Modified Abuse Monitoring ; modified content filtering/Guardrails is a separate control unless the organization also requires changes to safety filtering.
Study Guide references: Azure OpenAI # Data privacy and security; Abuse monitoring; Modified Abuse Monitoring; Limited Access requirements.
質問 # 84
You are developing several microservices to run on Azure Container Apps.
The microservices must allow HTTPS access by using a custom domain.
You need to configure the custom domain in Azure Container Apps.
In which order should you perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.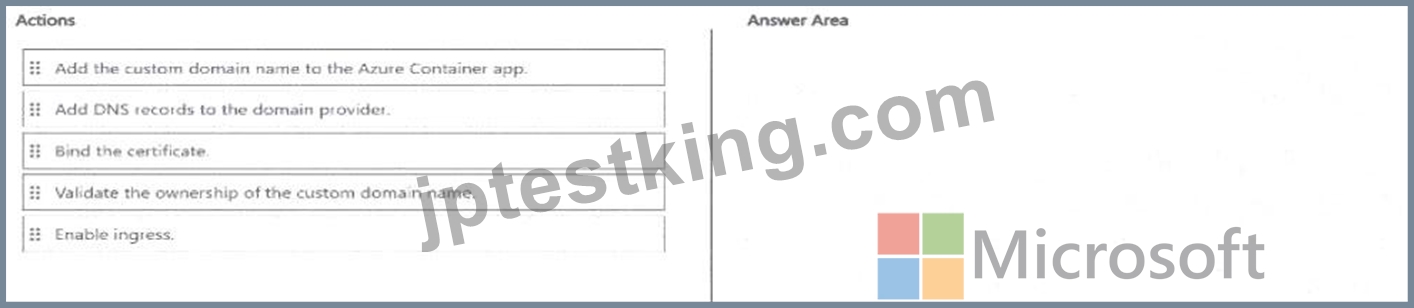
正解:
解説: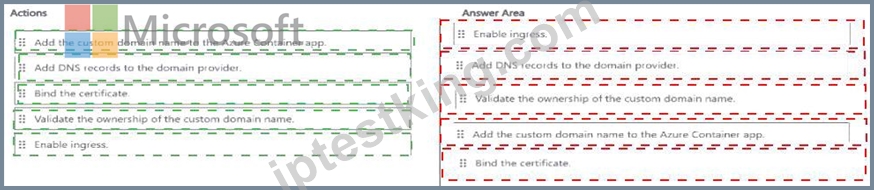
Explanation: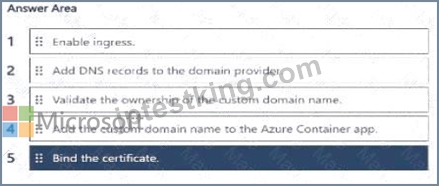
Verified answer: 1) Enable ingress; 2) add the required DNS records; 3) validate ownership of the custom domain; 4) add the custom domain to the Container App; 5) bind the certificate.
Detailed Explanation: A custom HTTPS hostname requires an ingress endpoint, DNS proof that the requester controls the hostname, the hostname association itself, and a TLS certificate bound to that hostname.
DNS records must exist before ownership validation can succeed. Once ownership is validated, the domain can be associated with the Container App and the certificate can be bound to provide HTTPS. Skipping ingress or DNS validation would prevent the hostname from being correctly routed and secured.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Custom domains and certificates in Container Apps
Topic 1, Proseware Inc. Case Study
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers. The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring:
* Telemetry generated by Azure resources is sent to Azure Monitor.
* A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
* Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version- controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known issues
RU consumption spikes during vector similarity queries.
質問 # 85
You deploy multiple instances of a change feed processor to handle a high ingestion rate within Azure Cosmos DB for NoSQL.
Each processor instance must process a different subset of partitions.
You need to ensure the workload is load-balanced across all processor instances.
What should you configure?
正解:C
解説:
The lease container is the Azure Cosmos DB component that coordinates change feed processing across multiple processor instances. Microsoft defines the lease container as the state store used by the change feed processor to track progress and coordinate ownership of partition ranges among workers. Each lease corresponds to a portion of the change feed workload, and at any given time a lease is owned by one processor instance.
When several change feed processor instances use the same lease container and the same processor name while maintaining unique instance names, the processor distributes leases across the active instances by using an equal-distribution algorithm. If instances are added or removed, the processor dynamically redistributes leases, which provides automatic workload balancing and parallelism. This is exactly what is required when ingestion volume is high and each instance must process a distinct subset of partition ranges.
Indexing precision affects query indexing behavior, not change feed coordination. Strong consistency controls read consistency semantics and does not assign partitions to processors. Autoscale throughput can increase database RU/s capacity, but it does not coordinate which processor instance owns which change feed partition range.
Study Guide references: Azure Cosmos DB for NoSQL # Change Feed Processor; lease container; parallel processing; dynamic scaling and load balancing.
質問 # 86
You are designing an Azure Function app that processes large image uploads submitted by users through an HTTP endpoint.
The solution must:
* Prevent client timeouts by decoupling image processing from the initial upload request.
* Support automatic retry behavior for failed processing attempts.
* Scale the background processing independently of the rate of incoming HTTP uploads.
You need to design a scalable and reliable asynchronous processing solution.
Which two actions should you implement? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:B、C
解説:
The correct architecture uses an Azure Storage queue as an asynchronous buffer between the HTTP ingestion path and the computationally expensive image-processing workload. The HTTP-triggered function should accept the upload, enqueue a work message, and return promptly rather than waiting for image processing to finish. Microsoft specifically recommends asynchronous patterns for long-running HTTP operations because an HTTP-triggered Azure Function can encounter the Azure Load Balancer response timeout even though the underlying function continues executing.
A queue-triggered function then performs image processing independently. Azure Functions applies target- based scaling to Azure Queue Storage triggers based on queued workload, allowing worker capacity to expand as the backlog increases rather than being directly tied to HTTP arrival processing.
For reliability, Azure Queue-triggered Functions provide retry behavior. The visibilityTimeout setting controls the delay before a failed message becomes available for another attempt, while maxDequeueCount controls how many processing attempts occur before the message is transferred to the < queue-name > - poison queue. The default maximum is five attempts.
C defeats the asynchronous requirement. D can be useful for tracking upload state, but it does not itself provide workload decoupling, retry handling, or queue-driven scaling.
Study Guide references: Azure Functions # Queue Storage triggers and bindings; event-driven scaling; retry
/poison queue behavior; asynchronous HTTP processing.
質問 # 87
You need to deploy a batch retraining workload.
How should you complete the scaling configuration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.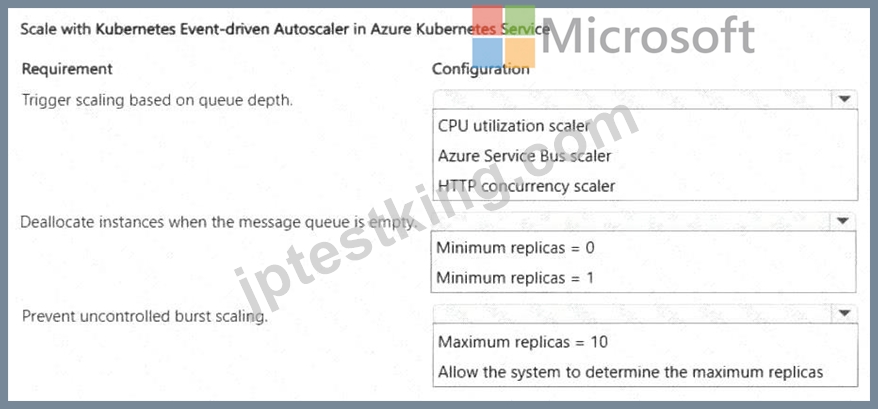
正解:
解説: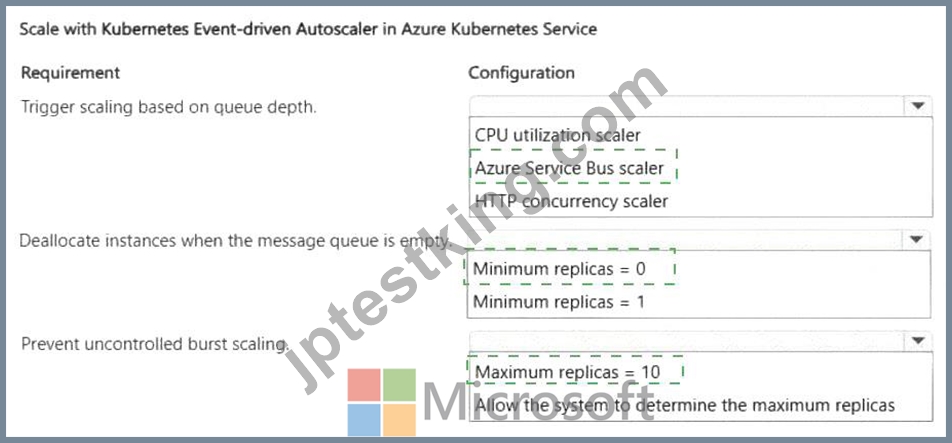
Explanation:
* Trigger scaling based on queue depth: Azure Service Bus scaler
* Deallocate instances when the message queue is empty: Minimum replicas = 0
* Prevent uncontrolled burst scaling: Maximum replicas = 10
The batch retraining workload must scale according to queue length , so the correct KEDA trigger is the Azure Service Bus scaler . KEDA integrates with Azure Service Bus and monitors queue or subscription metrics, allowing AKS workloads to scale according to the number of pending messages rather than CPU utilization or HTTP request concurrency. Microsoft documents KEDA as the event-driven autoscaling mechanism for AKS and specifically supports Azure-based scalers for queue-driven workloads.
To meet the requirement to deallocate workload instances when no messages remain, configure minimum replicas = 0 . KEDA supports scale-to-zero for event-driven workloads, which is particularly appropriate for intermittent batch or machine-learning processing because no pods need to remain running while the queue is empty. Microsoft specifically identifies scale-to-zero as a KEDA capability and recommends it for sporadic ML workloads where cost optimization is important.
Finally, configure maximum replicas = 10 . A finite maximum replica count establishes an explicit upper scaling boundary, preventing large queue bursts from creating an uncontrolled number of worker replicas and protecting both infrastructure cost and downstream services.
Study Guide references: AKS # KEDA; Azure Service Bus event-driven scaling; minReplicaCount; maxReplicaCount; scale-to-zero; autoscaling limits.
質問 # 88
......
あなたはこのような人々の一人ですか。さまざまな資料とトレーニング授業を前にして、どれを選ぶか本当に困っているのです。もしそうだったら、これ以上困ることはないです。JPTestKingはあなたにとって最も正確な選択ですから。我々はあなたに試験問題と解答に含まれている全面的な試験資料を提供することができます。JPTestKingの解答は最も正確な解釈ですから、あなたがより良い知識を身につけることに助けになれます。JPTestKingを利用したら、MicrosoftのAI-200認定試験に受かることを信じています。それも我々が全てのお客様に対する約束です。
AI-200日本語受験教科書: https://www.jptestking.com/AI-200-exam.html