BTW, DOWNLOAD part of ExamBoosts SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1p6sa4PHQp0HtVl0yX2tEE5o_-GcO3RY7
ExamBoosts provide you with the most authoritative and the fullest Snowflake SPS-C01 Exam Dumps, thus the hit rate is very high. All questions that may appear in the exam are included in our exam dumps. With the changes of exam outline, we also update our exam dumps at any time. ExamBoosts pdf real questions and answers can prevent you from wasting lots of time and efforts on preparing for the exam and can help you sail through you exam with ease and high efficiency. But even you fail the exam, we assure we will give you FULL REFUND. Opportunities always for those who are well prepared and we wish you not to miss the good opportunities.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Performance Optimization and Best Practices | 20% | - Vectorized UDFs - Caching strategies - Minimizing data transfer - Warehouse sizing for Snowpark - Query pushdown and optimization - Debugging and explain plans |
| Topic 2: Snowpark Concepts | 15% | - Client-side vs. Server-side execution - Snowpark DataFrames and query plans - Snowpark architecture and core concepts - Transformations vs. Actions - Stored procedures and conditional logic - Snowpark Sessions and connection management |
| Topic 3: Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Persisting transformed data - Using built-in functions - Window functions - Filtering, Aggregating, and Joining DataFrames |
| Topic 4: Snowpark API for Python | 30% | - DataFrame creation and manipulation - Reading and writing data - Working with Semi-structured data - User-Defined Functions (UDFs) and Stored Procedures - Establishing connections and session management |
ExamBoosts has been designing and offering real Snowflake Snowflake Certified SnowPro Specialty - Snowpark exam dumps for many years. We regularly update our valid Snowflake SPS-C01 certification test preparation material to keep them in line with the current Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam content and industry standards. Professionals from different countries give us their valuable feedback to refine SPS-C01 actual dumps even more.
NEW QUESTION # 294
You have a Python UDTF that calculates a running average from a stream of numerical data'. The UDTF's 'process' method maintains state (the running sum and count) between calls. You need to ensure that the UDTF's state is properly initialized for each new group of data processed within a Snowpark DataFrame. What are the requirements?
Answer: A,B
Explanation:
The correct answers are A and B. To ensure proper initialization, the UDTF class needs both an '__init___' method to initialize the state variables when a new instance of the UDTF is created, and a 'reset' method. The 'reset' method is crucial because it's called by Snowpark at the beginning of processing each new group of rows, allowing the UDTF to re-initialize its state for each group. Option C and D are incorrect. While end_partition' is used it's not related to state initialization. Del is for object deletion.
NEW QUESTION # 295
You are tasked with developing a data pipeline using Snowpark that involves reading data from multiple CSV files, performing transformations using Pandas DataFrames, and then loading the transformed data into a Snowflake table. You want to optimize the process by leveraging the capabilities of Snowpark and Pandas effectively. Which of the following approaches is the MOST efficient for creating the Snowpark DataFrame from the pandas dataframe? (Select all that apply.)
Answer: A,E
Explanation:
Option C is the most efficient when the transformations can be effectively done using Snowpark itself, bypassing Pandas entirely and leveraging Snowflake's compute power directly. Option D, while using Pandas for transformation, optimizes data transfer using the optimized 'write_pandas' function. Creating Snowpark DataFrames from Pandas DataFrames and then unioning (Option B) can be less performant due to data transfer overhead. Concatenating Pandas DataFrames and then creating a Snowpark DataFrame (Option A) can be memory-intensive. Option E is incorrect, setting will throw an error if table does not exist.
NEW QUESTION # 296
Consider the following Snowpark code snippet that defines and registers a UDF: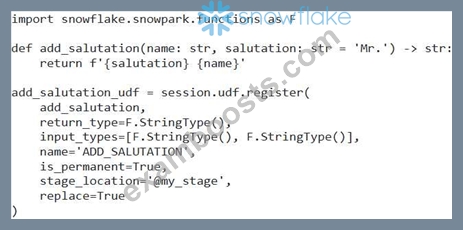
Which of the following statements about this code are TRUE?
Answer: A,B,C
Explanation:
The correct answers are C, D, and E. makes the UDF permanent. 'replace=True' overwrites any existing UDF with the same name. Python's default parameter value IS used in the SQL call if the salutation is omitted. 'input_typeS are not redundant, they are required and Python's type hints are not automatically used. Option A is incorrect because 'is_permanent' is set to true.
NEW QUESTION # 297
You have a Snowpark DataFrame 'employees df representing employee data'. You need to update the 'salary' column for employees in the 'Sales' department by applying a 10% increase. Which of the following Snowpark code snippets correctly performs this update? Assume a Snowflake table named 'employees' exists and 'employees df' is correctly created from it.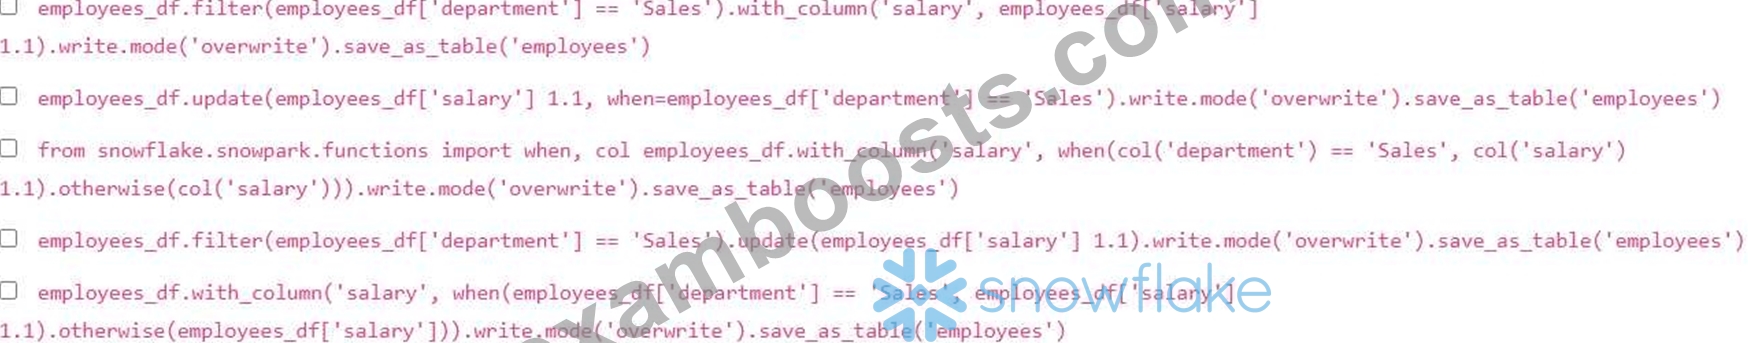
Answer: C,D
Explanation:
Options C and E are correct. Snowpark does not have an 'update' method directly on DataFrames like some other Spark-based DataFrame implementations. The correct way to update the data is to use 'with_column' along with 'when' and 'otherwise' from 'snowflake.snowpark.functions' to conditionally update the 'salary' column based on the 'department'. The part is crucial to persist the changes back to the Snowflake table after the transformation. Option C imports the required functions using 'from snowflake.snowpark.functions import when, cor and Option E directly uses the dataframe to invoke function and column names. Option A and D are incorrect because Snowpark does not provide an 'update' or direct save after filtering like that for this type of update. Option B is also incorrect because the update function doesn't exist on dataframes.
NEW QUESTION # 298
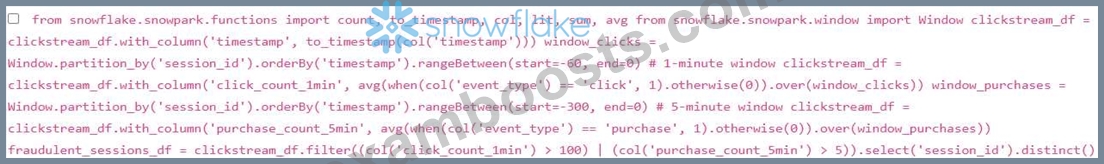
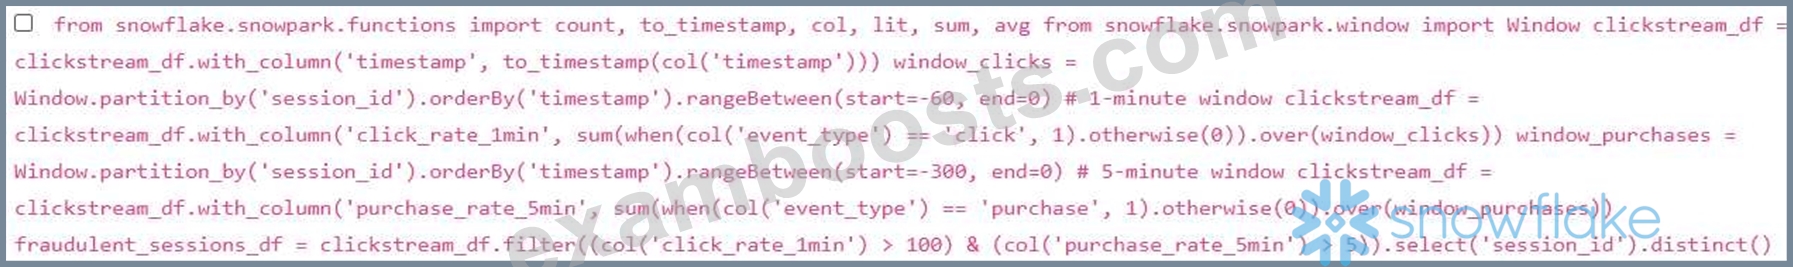
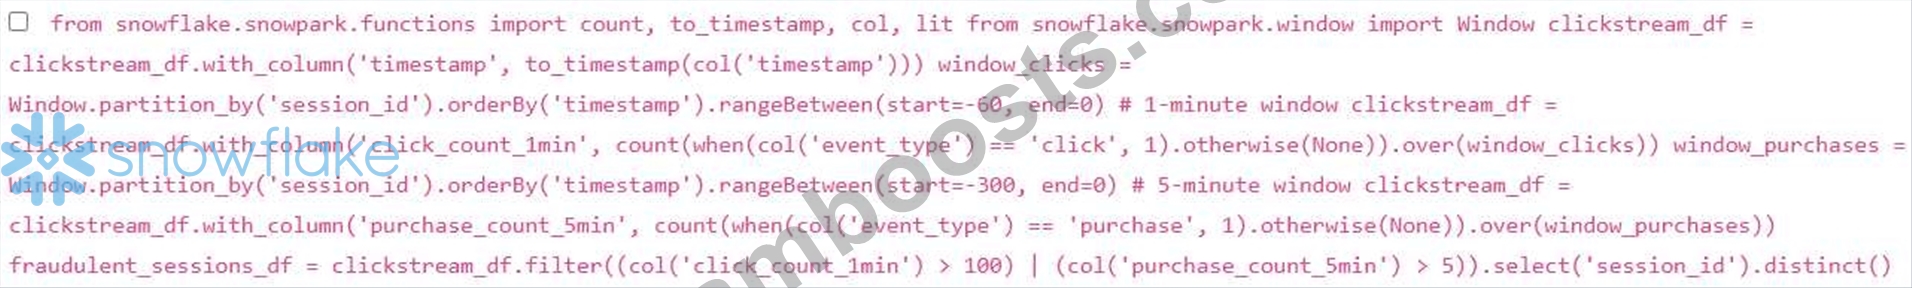
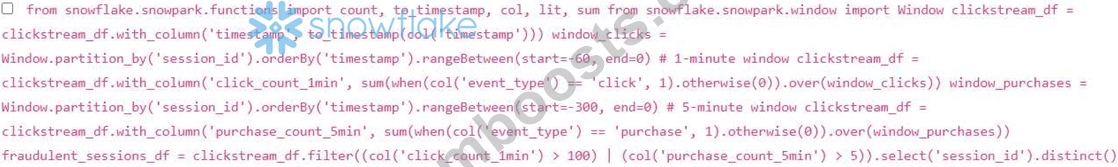
You are using Snowpark for Python to process a large dataset of website clickstream data'. The dataset contains columns such as 'session_id', 'user_id', 'timestamp', 'page_url', and 'event_type' (e.g., 'click', 'pageview', 'purchase'). You want to identify fraudulent user sessions based on the following criteria: A user session is considered fraudulent if it contains more than 100 clicks within a I-minute window. A user session is considered fraudulent if it contains more than 5 purchase events within a 5-minute window. Which of the following code snippets demonstrates the most efficient way to identify fraudulent sessions using Snowpark for Python? Select two that apply.

Answer: D,E
Explanation:
Options A and E are the most efficient and correct because they use window functions to calculate the click and purchase counts within the specified time windows and then filter the results based on the fraud criteria. Option A uses 'sum' on a conditional aggregation to count clicks and purchases. Option E Uses 'Count' and 'Otherwise(None)'. Option B is inefficient because it uses a UDF, which is slower than using built-in window functions. Options C and D are incorrect because 'click_rate_1min','purchase_rate_5min' are calculated incorrectly by making comparison, furthermore Option D uses average instead of SUM.
NEW QUESTION # 299
......
Having a Snowflake Certification SPS-C01 Exam certificate can help people who are looking for a job get better employment opportunities in the IT field and will also pave the way for a successful IT career for them.
Valid SPS-C01 Exam Cram: https://www.examboosts.com/Snowflake/SPS-C01-practice-exam-dumps.html
2026 Latest ExamBoosts SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1p6sa4PHQp0HtVl0yX2tEE5o_-GcO3RY7