2026 Latest Lead1Pass SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1dxLvuUCUqHpHI3q-tfMgoR2GUl6rsgml
We have installed the most advanced operation system in our company which can assure you the fastest delivery speed, to be specific, you can get immediately our SPS-C01 training materials only within five to ten minutes after purchase after payment. At the same time, your personal information will be encrypted automatically by our operation system as soon as you pressed the payment button, that is to say, there is really no need for you to worry about your personal information if you choose to buy the SPS-C01 Exam Practice from our company. We aim to leave no misgivings to our customers so that they are able to devote themselves fully to their studies on SPS-C01 guide materials: Snowflake Certified SnowPro Specialty - Snowpark and they will find no distraction from us. I suggest that you strike while the iron is hot since time waits for no one.
| Section | Objectives |
|---|---|
| Topic 1: Data Engineering with Snowpark | - Pipeline development
|
| Topic 2: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 3: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 4: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 5: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 6: Testing, Debugging, and Deployment | - Production readiness
|
>> Learning Snowflake SPS-C01 Mode <<
Some candidates may wonder that if the payment is quite complex and hard, in fact it is quite easy and simple. Once you have selected the SPS-C01 study materials, please add them to your cart. Then when you finish browsing our web pages, you can directly come to the shopping cart page and submit your orders of the SPS-C01 learning quiz. Our payment system will soon start to work. Then certain money will soon be deducted from your credit card to pay for the SPS-C01 preparation questions. And we will send them to you in 5 to 10 minutes after your purchase.
NEW QUESTION # 40
You have two Snowpark DataFrames, 'customers' and 'orders'. The 'customers' DataFrame has columns and 'customer name'. The 'orders' DataFrame has columns 'order id', 'customer id', and 'order amount'. You need to find all customers who have NOT placed any orders. Which of the following Snowpark set operations correctly implements this?





Answer: D
Explanation:
Option D is correct. It first selects the distinct 'customer_id' from both DataFrames. Then, it uses the 'minus' (or 'except_') set operation to find the difference between the customer IDs in the 'customers DataFrame and the customer IDs in the 'orders' DataFrame. This effectively returns the customer IDs of customers who have not placed any orders. The 'join' operation is not a set operation, and options B and C are not valid syntax for Snowpark. Option E is syntactically correct in Snowpark, and equivalent to Option D. However, since the question has to have one answer, Option D is kept.
NEW QUESTION # 41
You have created a Snowpark UDF that uses a custom Python module 'my_module.py', containing a function 'process data'. This module is not available through Anaconda'. You've packaged the module into a zip file named 'my module.zip'. What steps are necessary to deploy this UDF in Snowflake so that it can correctly use the 'my_module'?
Answer: A
Explanation:
Option B is correct. You need to upload the zip file to an internal stage. The 'imports' argument during UDF creation tells Snowflake to unpack the zip and make the module available. Snowflake handles adding the necessary path to 'sys.path', so no manual modification is needed within the UDF. Specifying external stages is possible, but internal stages are preferred for security and performance. Option A is incomplete (doesn't specify how the import relates to the UDF), Option C is technically feasible with external stages but is less preferable. Option D is incorrect as it unnecessary to modify sys.path. Option E specifies 'packages' argument where you would normally include packages available through Anaconda.
NEW QUESTION # 42
You are developing a Snowpark application that requires calling a stored procedure. Which of the following approaches is the MOST secure and efficient way to call a stored procedure from your Snowpark Python code, assuming the stored procedure returns a single value?





Answer: D
Explanation:
The 'session.call()' method (B) is the most direct and efficient way to call a stored procedure and retrieve its single return value from Snowpark Python. It handles the execution and data retrieval efficiently. Using 'session.sql()' (A and C) is less efficient as it requires parsing SQL and manual extraction of the result. 'session.sproc()' (D) is generally used to register Python functions as stored procedures and not for calling existing ones. is not valid, 'session.call()' is the right way to call procedure
NEW QUESTION # 43
You have a Snowpark DataFrame named 'employee_df in VS Code. You want to define a user-defined function (UDF) in Python that calculates the bonus for each employee based on their salary and performance rating. The UDF should take the salary (SALARY) and performance rating (PERFORMANCE RATING) as inputs and return the bonus amount. Assume you have already established a Snowpark session. Which code snippet accurately defines and registers a UDF named 'calculate_bonus' that can be applied to the 'employee_df DataFrame?
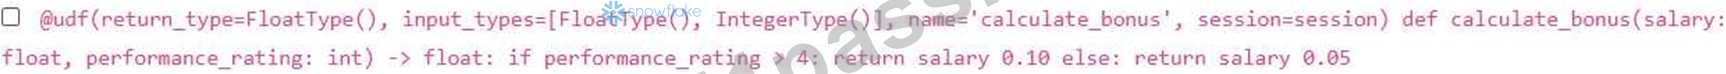




Answer: A,B
Explanation:
Options A and B are both correct methods. Option A defines the Python function and then registers it as a UDF using session.udf.register' . It explicitly specifies the return type, input types, UDF name, and the 'replace=True' option to allow overwriting if the UDF already exists. Option B uses the guff decorator to directly register the function as a UDF, providing a more concise way to define and register UDFs. Option A is also valid as the user defined datatypes and name. Option C requires the snowflake-snowpark-python package (which is already installed via dependencies) and the 'fune argument is redundant. Option D is wrong as would remove the currently configured packages. Option E is incorrect because making the UDF permanent requires additional privileges and setup that aren't covered by default.
NEW QUESTION # 44
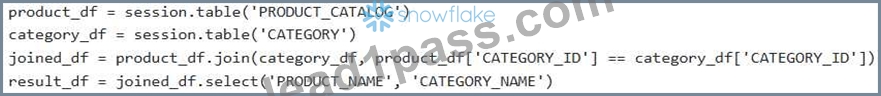
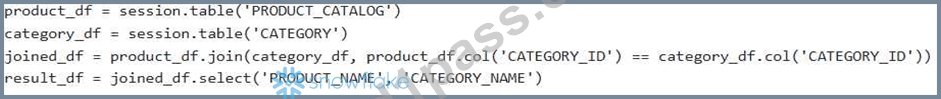
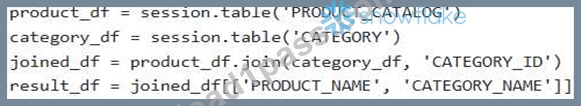
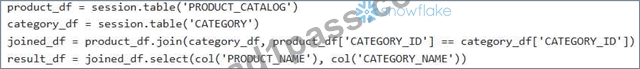
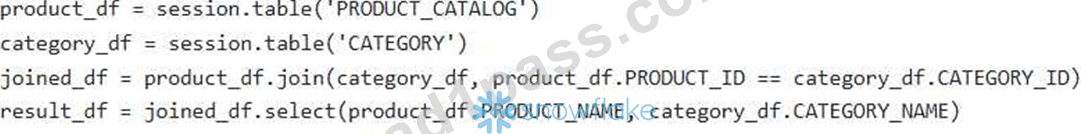
You have a Snowflake table 'PRODUCT CATALOG' with columns 'PRODUCT ID, 'PRODUCT NAME, and 'CATEGORY ID. You also have a table 'CATEGORY' with 'CATEGORY ID' and 'CATEGORY NAME. You need to create a Snowpark DataFrame that joins these two tables and includes only 'PRODUCT NAME and 'CATEGORY NAME. Assume a Snowpark Session object named 'session' is available. Which code snippet demonstrates creating the DataFrame using Snowpark's join functionality and column selection while using the 'table' method?
Answer: D
Explanation:
Option D correctly joins the tables using the 'join' method with a column expression specifying the join condition. It also correctly selects only the desired columns using and option A incorrectly uses 'PRODUCT_ID instead of for the join and needs 'col()' to reference columns. option B selects 'PRODUCT_NAME', 'CATEGORY_NAME' without using 'col(Y which will cause an error since the join brings duplicate column names from product_df and category_df. Option C uses Pythonic '[['PRODUCT_NAME', 'CATEGORY_NAME'I]' which only works on Pandas dataframes. option E attempts to use col() to reference the columns in the join condition which is incorrect as it is a column expression needs to use fully qualified table name for the same named column in two dataframes; moreover selection is missing col().
NEW QUESTION # 45
......
It is known to us that getting the SPS-C01 certification is not easy for a lot of people, but we are glad to tell you good news. The SPS-C01 study materials from our company can help you get the certification in a short time. Now we are willing to let you know our SPS-C01 Practice Questions in detail on the website, we hope that you can spare your valuable time to have a look to our products. Please believe that we will not let you down.
SPS-C01 Top Dumps: https://www.lead1pass.com/Snowflake/SPS-C01-practice-exam-dumps.html
What's more, part of that Lead1Pass SPS-C01 dumps now are free: https://drive.google.com/open?id=1dxLvuUCUqHpHI3q-tfMgoR2GUl6rsgml