If you are prepared to take the Databricks-Certified-Professional-Data-Engineer exam with the help of excellent Databricks-Certified-Professional-Data-Engineer learning materials on our website, the choice is made brilliant. Our Databricks-Certified-Professional-Data-Engineer training materials are your excellent choices, especially helpful for those who want to pass the Databricks-Certified-Professional-Data-Engineer Exam without bountiful time and eager to get through it successfully. Besides that, our Databricks-Certified-Professional-Data-Engineer study questions have three versions: PDF version, Soft version and APP version, which can be interestinng and helpful for you to choose.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Related Certifications: | Databricks Certified Data Analyst Associate Databricks Certified Associate Developer |
| Available Languages: | English |
| Certificate Validity Period: | 2 years |
| Real Exam Qty: | 60 |
| Exam Format: | Multiple Choice, Multiple Select |
| Passing Score: | 70% |
| Exam Price: | $200 USD |
| Exam Duration: | 90 minutes |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored exam (Pearson VUE) |
| Pre Condition: | Recommended: 6+ months of hands-on experience with Databricks and data engineering concepts; familiarity with Python or Scala and SQL is strongly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/professional-data-engineer |
>> Databricks-Certified-Professional-Data-Engineer Exam Tips <<
Passing the Databricks Certified Professional Data Engineer Exam exam at first attempt is a goal that many candidates strive for. However, some of them think that good Databricks Databricks-Certified-Professional-Data-Engineer study material is not important, but this is not true. The right Databricks-Certified-Professional-Data-Engineer preparation material is crucial for success in the exam. And applicants who don’t find updated Databricks-Certified-Professional-Data-Engineer prep material ultimately fail in the real examination and waste money. That's why Prep4sureGuide offers actual Databricks-Certified-Professional-Data-Engineer exam questions to help candidates pass the exam and save their resources.
Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) certification exam is designed for professionals who want to demonstrate their expertise in using Databricks to manage big data and create data pipelines. Databricks Certified Professional Data Engineer Exam certification exam is ideal for data engineers, data architects, data scientists, and other professionals who work with big data and want to validate their skills in using Databricks to build data pipelines.
Databricks Certified Professional Data Engineer certification is highly valued by organizations that use the Databricks platform for their data processing and analytics needs. By earning this certification, data engineers can demonstrate their expertise and proficiency in using the Databricks platform to design and implement complex data projects. Databricks Certified Professional Data Engineer Exam certification can also help data engineers advance their careers and increase their earning potential, as it is recognized and respected by employers in the data engineering field.
NEW QUESTION # 150
An hourly batch job is configured to ingest data files from a cloud object storage container where each batch represent all records produced by the source system in a given hour. The batch job to process these records into the Lakehouse is sufficiently delayed to ensure no late-arriving data is missed. Theuser_idfield represents a unique key for the data, which has the following schema:
user_id BIGINT, username STRING, user_utc STRING, user_region STRING, last_login BIGINT, auto_pay BOOLEAN, last_updated BIGINT New records are all ingested into a table namedaccount_historywhich maintains a full record of all data in the same schema as the source. The next table in the system is namedaccount_currentand is implemented as a Type 1 table representing the most recent value for each uniqueuser_id.
Assuming there are millions of user accounts and tens of thousands of records processed hourly, which implementation can be used to efficiently update the describedaccount_currenttable as part of each hourly batch job?
Answer: C
Explanation:
Explanation
This is the correct answer because it efficiently updates the account current table with only the most recent value for each user id. The code filters records in account history using the last updated field and the most recent hour processed, which means it will only process the latest batch of data. It also filters by the max last login by user id, which means it will only keep the most recent record for each user id within that batch. Then, it writes a merge statement to update or insert the most recent value for each user id into account current, which means it will perform an upsert operation based on the user id column. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Upsert into a table using merge" section.
NEW QUESTION # 151
A data engineer wants to enforce the principle of least privilege when configuring ACLs for Databricks jobs in a collaborative workspace.
Which approach should the data engineer use?
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Databricks follows the principle of least privilege (PoLP) to ensure users and groups have only the permissions required for their specific role.
For Databricks Jobs, three primary permission levels exist:
CAN VIEW - Allows viewing job configurations and runs.
CAN RUN - Allows triggering job runs.
CAN MANAGE - Allows full control, including editing and deletion.
To enforce PoLP, each user should be assigned only the specific permission required for their task. This approach prevents unauthorized edits and limits the risk of accidental deletions or job misconfigurations.
Granting broad permissions such as "ALL" or "CAN MANAGE to everyone" violates Databricks security best practices. Thus, the correct answer is D.
NEW QUESTION # 152
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).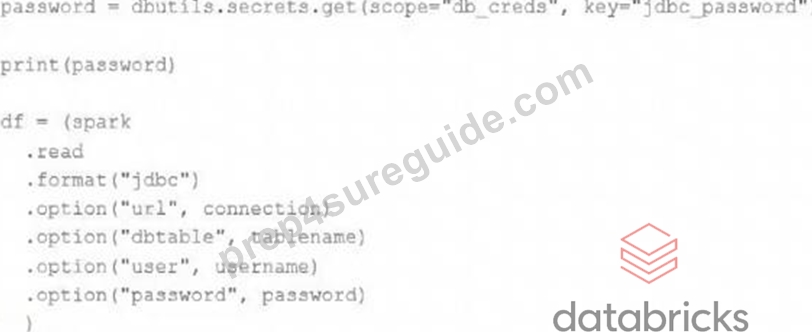
Which statement describes what will happen when the above code is executed?
Answer: E
Explanation:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks. Verified References: [Databricks Certified Data Engineer Professional], under "Security and Governance" section; Databricks Documentation, under
"Secrets" section.
NEW QUESTION # 153
Which configuration parameter directly affects the size of a spark-partition upon ingestion of data into Spark?
Answer: A
Explanation:
Explanation
This is the correct answer because spark.sql.files.maxPartitionBytes is a configuration parameter that directly affects the size of a spark-partition upon ingestion of data into Spark. This parameter configures the maximum number of bytes to pack into a single partition when reading files from file-based sources such as Parquet, JSON and ORC. The default value is 128 MB, which means each partition will be roughly 128 MB in size, unless there are too many small files or only one large file. Verified References: [Databricks Certified Data Engineer Professional], under "Spark Configuration" section; Databricks Documentation, under "Available Properties - spark.sql.files.maxPartitionBytes" section.
NEW QUESTION # 154
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats.
After converting a subset of data to Delta Lake , they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join , whereas queries on legacy formats used Sort Merge Joins . The queries reading Delta Lake data also scanned less data.
Which reason could be attributed to the difference in query performance?
Answer: C
Explanation:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage , data skipping
, and file pruning . According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters , a process called data skipping and file pruning . Additionally, Delta uses a vectorized Parquet reader , which reduces I/O and CPU overhead.
Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
NEW QUESTION # 155
......
Latest Databricks-Certified-Professional-Data-Engineer Braindumps Sheet: https://www.prep4sureguide.com/Databricks-Certified-Professional-Data-Engineer-prep4sure-exam-guide.html