Our Databricks-Certified-Professional-Data-Engineer training materials are famous for instant access to download. You can receive your downloading link and password within ten minutes, so that you can start your learning as early as possible. In order to build up your confidence for Databricks-Certified-Professional-Data-Engineer exam materials, we are pass guarantee and money back guarantee, and if you fail to pass the exam, we will give you full refund. In addition, Databricks-Certified-Professional-Data-Engineer test materials cover most of knowledge points for the exam, therefore you can mater the major points for the exam as well as improve your professional ability in the process of learning.
| Section | Weight | Objectives |
|---|---|---|
| Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Standardization and normalization - Data validation and quality checks |
| Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools - Batch and incremental processing logic - Data transformation and aggregation |
| Debugging and Deploying | 10% | - Troubleshooting pipelines and errors - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices |
| Data Governance | 7% | - Policy enforcement - Unity Catalog management - Data lineage and metadata tracking |
| Data Modelling | 6% | - Schema design and management - Medallion Architecture implementation - Delta Lake table design |
| Data Ingestion & Acquisition | 7% | - Schema inference and evolution - Connecting to diverse data sources - Auto Loader and streaming ingestion |
| Monitoring and Alerting | 10% | - Setting up alerts and notifications - Performance and health monitoring - Pipeline observability and logging |
| Cost & Performance Optimisation | 13% | - Query optimization and caching - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) |
| Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Access control and permissions - Data encryption and masking |
>> Databricks Databricks-Certified-Professional-Data-Engineer Examcollection Dumps <<
They work together and analyze the examination content to compile most probable Databricks-Certified-Professional-Data-Engineer real dumps in three formats. These Databricks Certification Exams questions will surely appear in the next Databricks Databricks-Certified-Professional-Data-Engineer exam. Memorizing these Databricks Databricks-Certified-Professional-Data-Engineer Valid Dumps will help you easily attempt the Databricks-Certified-Professional-Data-Engineer exam within the allocated time. Thousands of aspirants have passed their Databricks-Certified-Professional-Data-Engineer exam, and they all got help from our Databricks Databricks-Certified-Professional-Data-Engineer updated exam dumps.
NEW QUESTION # 181
A data engineer needs to implement column masking for a sensitive column in a Unity Catalog-managed table. The masking logic must dynamically check if users belong to specific groups defined in a separate table (group_access) that maps groups to allowed departments.
Which approach should the engineer use to efficiently enforce this requirement?
Answer: D
Explanation:
Databricks Unity Catalog supports dynamic column masking , where masking logic can be implemented using SQL functions or UDFs that reference external mapping tables or metadata for context-aware access control.
By referencing the group_access table inside the masking function, the mask dynamically evaluates whether a requesting user belongs to an authorized group. If permitted, the original column value is returned; otherwise, a masked value (such as NULL or asterisks) is shown.
This method enables fine-grained, data-driven masking policies while maintaining a single authoritative access mapping source.
Hardcoding values (A) reduces flexibility, and row filters (D) apply to entire rows rather than specific columns. Therefore, C correctly aligns with Databricks best practices for dynamic masking.
NEW QUESTION # 182
You had worked with the Data analysts team to set up a SQL Endpoint(SQL warehouse) point so they can easily query and analyze data in the gold layer, but once they started consuming the SQL Endpoint(SQL warehouse) you noticed that during the peak hours as the number of users increase you are seeing queries taking longer to finish, which of the following steps can be taken to resolve the issue?
*Please note Databricks recently renamed SQL endpoint to SQL warehouse.
Answer: A
Explanation:
Explanation
the answer is,
They can increase the maximum bound of the SQL endpoint's scaling range, when you increase the maximum bound you can add more clusters to the warehouse which can then run additional queries that are waiting in the queue to run, focus on the below explanation that talks about Scale-out.
The question is looking to test your ability to know how to scale a SQL Endpoint(SQL Warehouse) and you have to look for cue words or need to understand if the queries are running sequentially or concurrently. if the queries are running sequentially then scale up(Size of the cluster from 2X-Small to 4X-Large) if the queries are running concurrently or with more users then scale out(add more clusters).
SQL Endpoint(SQL Warehouse) Overview: (Please read all of the below points and the below diagram to understand )
1.A SQL Warehouse should have at least one cluster
2.A cluster comprises one driver node and one or many worker nodes
3.No of worker nodes in a cluster is determined by the size of the cluster (2X -Small ->1 worker, X-Small ->2 workers.... up to 4X-Large -> 128 workers) this is called Scale up
4.A single cluster irrespective of cluster size(2X-Smal.. to ...4XLarge) can only run 10 queries at any given time if a user submits 20 queries all at once to a warehouse with 3X-Large cluster size and cluster scaling (min
1, max1) while 10 queries will start running the remaining 10 queries wait in a queue for these 10 to finish.
5.Increasing the Warehouse cluster size can improve the performance of a query, example if a query runs for 1 minute in a 2X-Small warehouse size, it may run in 30 Seconds if we change the warehouse size to X-Small.
this is due to 2X-Small has 1 worker node and X-Small has 2 worker nodes so the query has more tasks and runs faster (note: this is an ideal case example, the scalability of a query performance depends on many factors, it can not always be linear)
6.A warehouse can have more than one cluster this is called Scale out. If a warehouse is con-figured with X-Small cluster size with cluster scaling(Min1, Max 2) Databricks spins up an additional cluster if it detects queries are waiting in the queue, If a warehouse is configured to run 2 clusters(Min1, Max 2), and let's say a user submits 20 queries, 10 queriers will start running and holds the remaining in the queue and databricks will automatically start the second cluster and starts redirecting the 10 queries waiting in the queue to the second cluster.
7.A single query will not span more than one cluster, once a query is submitted to a cluster it will remain in that cluster until the query execution finishes irrespective of how many clusters are available to scale.
Please review the below diagram to understand the above concepts: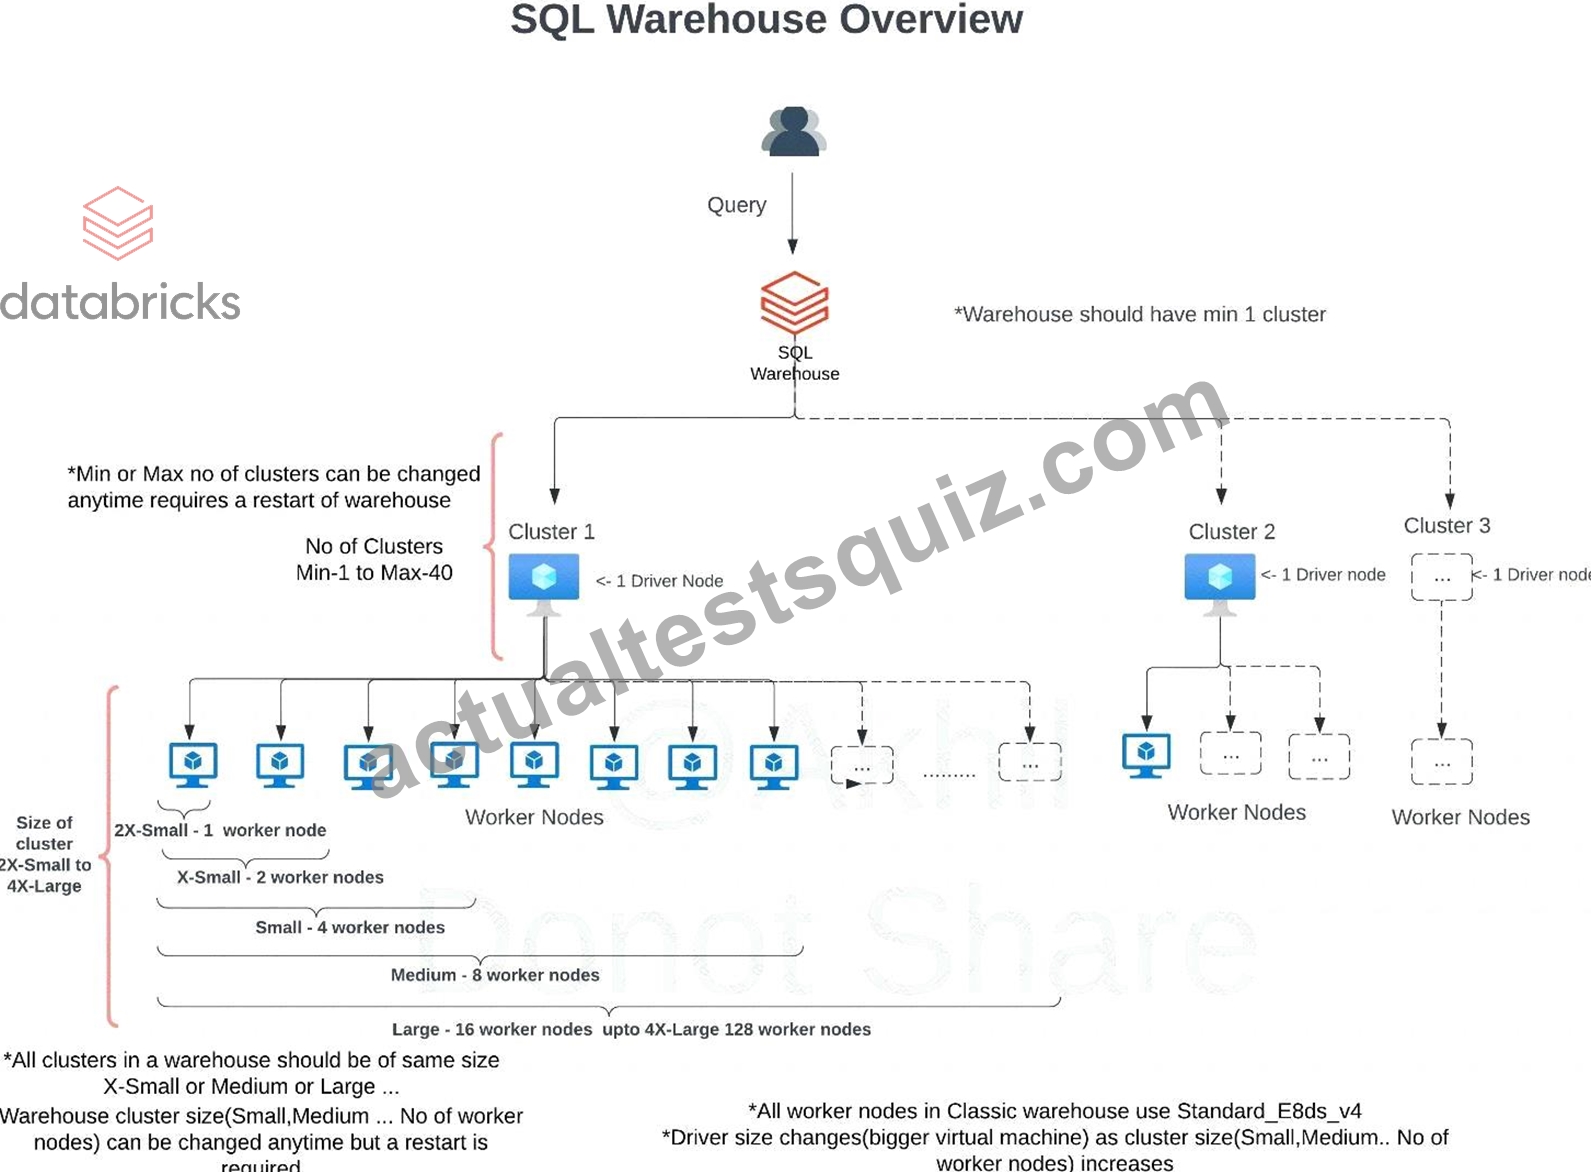
SQL endpoint(SQL Warehouse) scales horizontally(scale-out) and vertical (scale-up), you have to understand when to use what.
Scale-out -> to add more clusters for a SQL endpoint, change max number of clusters If you are trying to improve the throughput, being able to run as many queries as possible then having an additional cluster(s) will improve the performance.
Databricks SQL automatically scales as soon as it detects queries are in queuing state, in this example scaling is set for min 1 and max 3 which means the warehouse can add three clusters if it detects queries are waiting.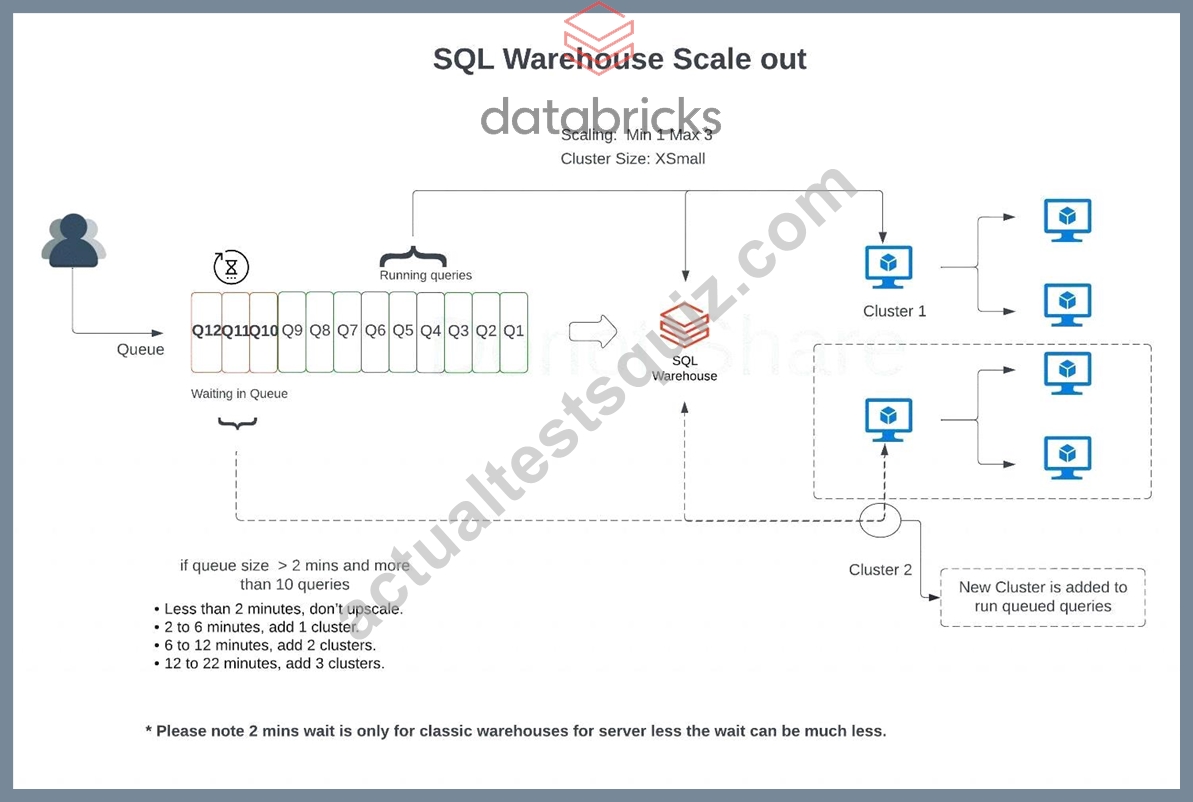
During the warehouse creation or after you have the ability to change the warehouse size (2X-Small....to
...4XLarge) to improve query performance and the maximize scaling range to add more clusters on a SQL Endpoint(SQL Warehouse) scale-out, if you are changing an existing warehouse you may have to restart the warehouse to make the changes effective.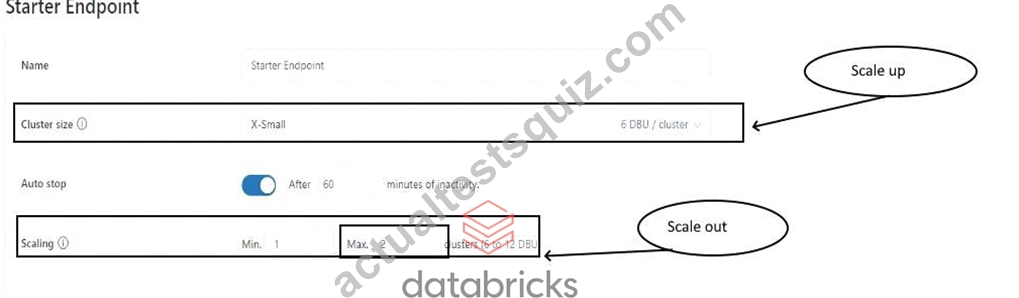
How do you know how many clusters you need(How to set Max cluster size)?
When you click on an existing warehouse and select the monitoring tab, you can see warehouse utilization information(see below), there are two graphs that provide important information on how the warehouse is being utilized, if you see queries are being queued that means your warehouse can benefit from additional clusters. Please review the additional DBU cost associated with adding clusters so you can take a well balanced decision between cost and performance.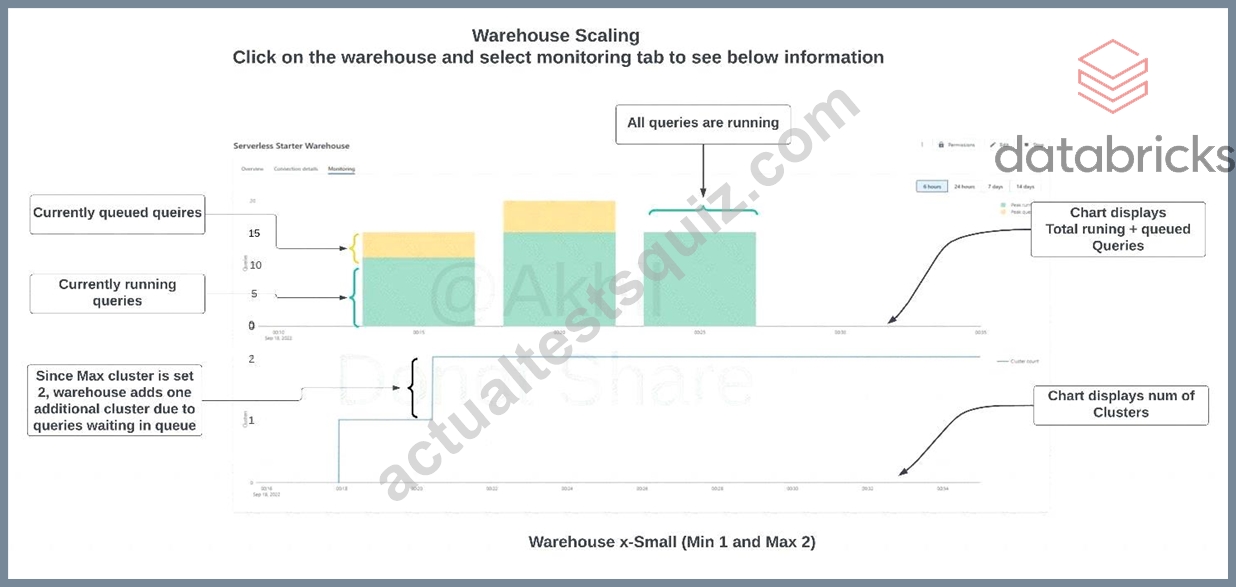
NEW QUESTION # 183
The Delta Live Table Pipeline is configured to run in Production mode using the continuous Pipe-line Mode.
what is the expected outcome after clicking Start to update the pipeline?
Answer: D
Explanation:
Explanation
The answer is,
All datasets will be updated continuously and the pipeline will not shut down. The compute re-sources will persist with the pipeline until it is shut down since the execution mode is chosen to be continuous. It does not matter if the pipeline mode is development or production, pipeline mode only matters during the pipeline initialization.
DLT pipeline supports two modes Development and Production, you can switch between the two based on the stage of your development and deployment lifecycle.
Development and production modes
Development:
When you run your pipeline in development mode, the Delta Live Tables system:
*Reuses a cluster to avoid the overhead of restarts.
*Disables pipeline retries so you can immediately detect and fix errors.
Production:
In production mode, the Delta Live Tables system:
*Restarts the cluster for specific recoverable errors, including memory leaks and stale cre-dentials.
*Retries execution in the event of specific errors, for example, a failure to start a cluster.
Use the buttons in the Pipelines UI to switch between develop-ment and production modes. By default,
pipelines run in development mode.
Switching between development and production modes only controls cluster and pipeline execution behavior.
Storage locations must be configured as part of pipeline settings and are not affected when switching between modes.
Delta Live Tables supports two different modes of execution:
Triggered pipelines update each table with whatever data is currently available and then stop the cluster running the pipeline. Delta Live Tables automatically analyzes the dependencies between your tables and starts by computing those that read from external sources. Tables within the pipe-line are updated after their dependent data sources have been updated.
Continuous pipelines update tables continuously as input data changes. Once an update is started, it continues to run until manually stopped. Continuous pipelines require an always-running cluster but ensure that downstream consumers have the most up-to-date data Please review additional DLT concepts using the below link
https://docs.databricks.com/data-engineering/delta-live-tables/delta-live-tables-concepts.html#delta-live-tables-c
NEW QUESTION # 184
What are the advantages of the Hashing Features?
Answer: B,C
Explanation:
Explanation
SGD-based classifiers avoid the need to predetermine vector size by simply picking a reasonable size and
shoehorning the training data into vectors of that size. This approach is known as feature hashing. The
shoehorning is done by picking one or more locations by using a hash of the name of the variable for
continuous variables or a hash of the variable name and the category name or word for categorical, text*like, or
word-like data.
This hashed feature approach has the distinct advantage of requiring less memory and one less pass through
the training data, but it can make it much harder to reverse engineer vectors to determine which original
feature mapped to a vector location. This is because multiple features may hash to the same location. With
large vectors or with multiple locations per feature, this isn't a problem for accuracy but it can make it hard to
understand what a classifier is doing.
An additional benefit of feature hashing is that the unknown and unbounded vocabularies typical of word-like
variables aren't a problem.
NEW QUESTION # 185
Below sample input data contains two columns, one cartId also known as session id, and the second column is called items, every time a customer makes a change to the cart this is stored as an array in the table, the Marketing team asked you to create a unique list of item's that were ever added to the cart by each customer, fill in blanks by choosing the appropriate array function so the query produces below expected result as shown below.
Schema: cartId INT, items Array<INT>
Sample Data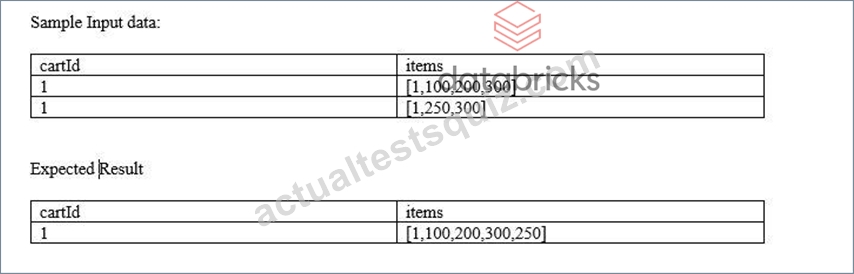
1.SELECT cartId, ___ (___(items)) as items
2.FROM carts GROUP BY cartId
Expected result:
cartId items
1 [1,100,200,300,250]
Answer: A
Explanation:
Explanation
COLLECT SET is a kind of aggregate function that combines a column value from all rows into a unique list ARRAY_UNION combines and removes any duplicates, Graphical user interface, application Description automatically generated with medium confidence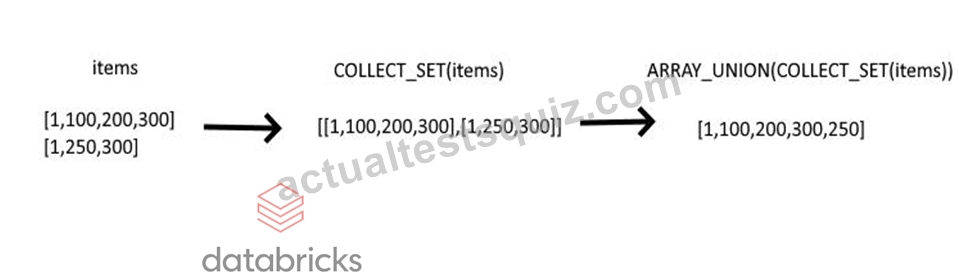
NEW QUESTION # 186
......
Users of this format don't need to install excessive plugins or software to attempt the Databricks-Certified-Professional-Data-Engineer web-based practice exams. Another format of the Databricks-Certified-Professional-Data-Engineer practice test is the desktop-based software. This Databricks-Certified-Professional-Data-Engineer Exam simulation software needs installation only on Windows computers to operate. The third format of the ActualTestsQuiz Databricks Databricks-Certified-Professional-Data-Engineer exam dumps is the Databricks-Certified-Professional-Data-Engineer Dumps PDF.
Databricks-Certified-Professional-Data-Engineer Valid Dumps Demo: https://www.actualtestsquiz.com/Databricks-Certified-Professional-Data-Engineer-test-torrent.html