
BONUS!!! Download part of TrainingDumps AIF-C01 dumps for free: https://drive.google.com/open?id=1XVK9TgQk7Z7qiCkOZfjShxk2li25sh83
Desktop and web-based AIF-C01 practice exams are available at TrainingDumps for thorough preparation. Going through these Amazon AIF-C01 mock exams boosts your learning and reduces mistakes in the Amazon AIF-C01 Test Preparation. Customization features of Amazon AIF-C01 practice tests allow you to change the settings of the AIF-C01 test sessions.
| Section | Weight | Objectives |
|---|---|---|
| AWS AI Services Overview | 26% | - Describe AWS AI services for specific use cases
|
| AI/ML Fundamentals | 24% | - Understand the AI/ML lifecycle
|
| AI Application Development | 30% | - Understand foundational concepts for building AI applications
|
| Responsible AI | 20% | - Implement responsible AI best practices
|
>> Latest AIF-C01 Exam Experience <<
The TrainingDumps AWS Certified AI Practitioner (AIF-C01) PDF dumps file work with all devices and operating system. You can easily install the AIF-C01 exam questions file on your desktop computer, laptop, tabs, and smartphone devices and start AWS Certified AI Practitioner (AIF-C01) exam dumps preparation without wasting further time. Whereas the other two TrainingDumps Amazon AIF-C01 Practice Test software is concerned, both are the mock AWS Certified AI Practitioner (AIF-C01) exam that will give you a real-time AIF-C01 practice exam environment for preparation.
NEW QUESTION # 315
A company has developed an ML model for image classification. The company wants to deploy the model to production so that a web application can use the model.
The company needs to implement a solution to host the model and serve predictions without managing any of the underlying infrastructure.
Which solution will meet these requirements?
Answer: C
NEW QUESTION # 316
An AI practitioner is using an Amazon Bedrock base model to summarize session chats from the customer service department. The AI practitioner wants to store invocation logs to monitor model input and output data.
Which strategy should the AI practitioner use?
Answer: D
NEW QUESTION # 317
A bank is building a chatbot to answer customer questions about opening a bank account. The chatbot will use public bank documents to generate responses. The company will use Amazon Bedrock and prompt engineering to improve the chatbot's responses.
Which prompt engineering technique meets these requirements?
Answer: C
Explanation:
Directional stimulus prompting guides the foundation model to produce outputs aligned with business context. It's particularly effective for aligning responses with public documents and improving coherence. From Bedrock Prompt Engineering Techniques documentation:
Explanation:
Directional stimulus prompting guides the foundation model to produce outputs aligned with business context. It's particularly effective for aligning responses with public documents and improving coherence. From Bedrock Prompt Engineering Techniques documentation:
"Directional stimulus prompting provides structured prompts to steer the model output towards desired formats or behaviors using specific linguistic cues."
NEW QUESTION # 318
A company is using Amazon SageMaker to develop AI models.
Select the correct SageMaker feature or resource from the following list for each step in the AI model lifecycle workflow. Each SageMaker feature or resource should be selected one time or not at all. (Select TWO.) SageMaker Clarify SageMaker Model Registry SageMaker Serverless Inference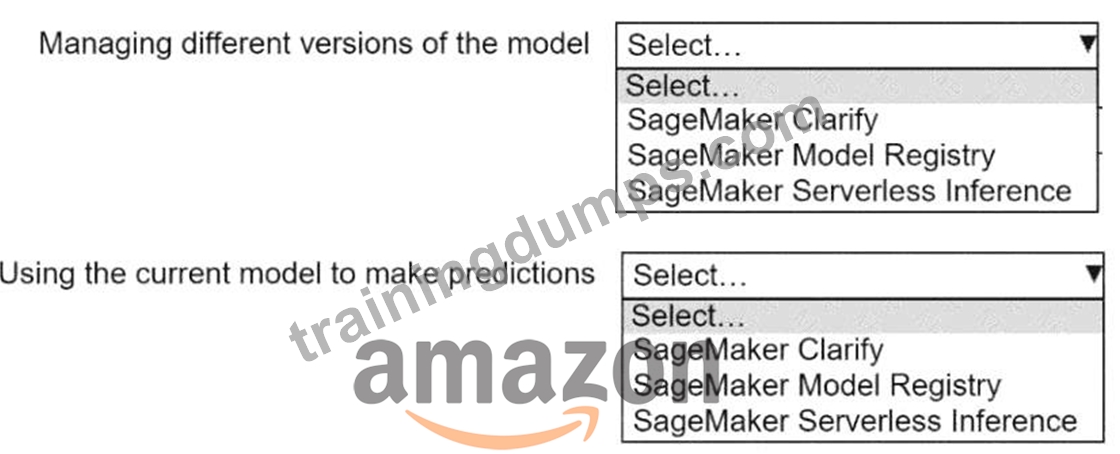
Answer:
Explanation: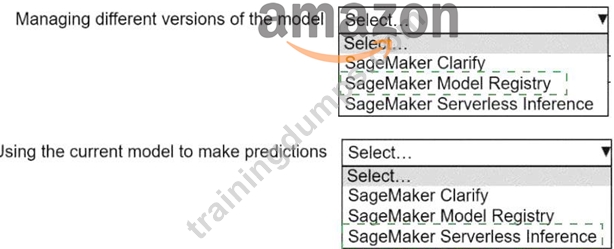
Explanation:
SageMaker Model Registry, SageMaker Serverless interference
This question requires selecting the appropriate Amazon SageMaker feature for two distinct steps in the AI model lifecycle. Let's break down each step and evaluate the options:
Step 1: Managing different versions of the model
The goal here is to identify a SageMaker feature that supports version control and management of machine learning models. Let's analyze the options:
SageMaker Clarify: This feature is used to detect bias in models and explain model predictions, helping with fairness and interpretability. It does not provide functionality for managing model versions.
SageMaker Model Registry: This is a centralized repository in Amazon SageMaker that allows users to catalog, manage, and track different versions of machine learning models. It supports model versioning, approval workflows, and deployment tracking, making it ideal for managing different versions of a model.
SageMaker Serverless Inference: This feature enables users to deploy models for inference without managing servers, automatically scaling based on demand. It is focused on inference (predictions), not on managing model versions.
Conclusion for Step 1: The SageMaker Model Registry is the correct choice for managing different versions of the model.
Exact Extract Reference: According to the AWS SageMaker documentation, "The SageMaker Model Registry allows you to catalog models for production, manage model versions, associate metadata, and manage approval status for deployment." (Source: AWS SageMaker Documentation - Model Registry,
https://docs.aws.amazon.com/sagemaker/latest/dg/model-registry.html).
Step 2: Using the current model to make predictions
The goal here is to identify a SageMaker feature that facilitates making predictions (inference) with a deployed model. Let's evaluate the options:
SageMaker Clarify: As mentioned, this feature focuses on bias detection and explainability, not on performing inference or making predictions.
SageMaker Model Registry: While the Model Registry helps manage and catalog models, it is not used directly for making predictions. It can store models, but the actual inference process requires a deployment mechanism.
SageMaker Serverless Inference: This feature allows users to deploy models for inference without managing infrastructure. It automatically scales based on traffic and is specifically designed for making predictions in a cost-efficient, serverless manner.
Conclusion for Step 2: SageMaker Serverless Inference is the correct choice for using the current model to make predictions.
Exact Extract Reference: The AWS documentation states, "SageMaker Serverless Inference is a deployment option that allows you to deploy machine learning models for inference without configuring or managing servers. It automatically scales to handle inference requests, making it ideal for workloads with intermittent or unpredictable traffic." (Source: AWS SageMaker Documentation - Serverless Inference, https://docs.aws.
amazon.com/sagemaker/latest/dg/serverless-inference.html).
Why Not Use the Same Feature Twice?
The question specifies that each SageMaker feature or resource should be selected one time or not at all. Since SageMaker Model Registry is used for version management and SageMaker Serverless Inference is used for predictions, each feature is selected exactly once. SageMaker Clarify is not applicable to either step, so it is not selected at all, fulfilling the question's requirements.
References:
AWS SageMaker Documentation: Model Registry (https://docs.aws.amazon.com/sagemaker/latest/dg/model- registry.html) AWS SageMaker Documentation: Serverless Inference (https://docs.aws.amazon.com/sagemaker/latest/dg
/serverless-inference.html)
AWS AI Practitioner Study Guide (conceptual alignment with SageMaker features for model lifecycle management and inference) Let's format this question according to the specified structure and provide a detailed, verified answer based on AWS AI Practitioner knowledge and official AWS documentation. The question focuses on selecting an AWS database service that supports storage and queries of embeddings as vectors, which is relevant to generative AI applications.
NEW QUESTION # 319
An online media streaming company wants to give its customers the ability to perform natural language-based image search and filtering. The company needs a vector database that can help with similarity searches and nearest neighbor queries.
Which AWS service meets these requirements?
Answer: D
Explanation:
The correct answer is D because Amazon OpenSearch Service supports k-Nearest Neighbor (k-NN) search and vector similarity search, which are required for semantic search tasks, such as matching natural language queries to image embeddings.
From AWS documentation:
"Amazon OpenSearch Service supports k-NN search, which allows you to run efficient similarity searches on large-scale datasets using vector embeddings generated by models. This enables applications like natural language-based image search and personalized recommendations." In this use case, image data can be encoded into vectors using foundation models (e.g., via Amazon Bedrock or SageMaker), and OpenSearch Service can index and retrieve results based on vector similarity.
Explanation of other options:
A). Amazon Comprehend is for text-based NLP tasks and does not provide vector similarity or search functionality.
B). Amazon Personalize is for user-item recommendations and personalization, not vector-based semantic search.
C). Amazon Polly is a text-to-speech service and not related to image search or vector databases.
Referenced AWS AI/ML Documents and Study Guides:
* Amazon OpenSearch Service Documentation - k-NN and Vector Search
* AWS ML Specialty Study Guide - Semantic Search and Vector Indexing
* AWS Generative AI Best Practices - Embeddings and Vector Databases
NEW QUESTION # 320
......
Great concentrative progress has been made by our company, who aims at further cooperation with our candidates in the way of using our AIF-C01 exam engine as their study tool. Owing to the devotion of our professional research team and responsible working staff, our AIF-C01 Training Materials have received wide recognition and now, with more people joining in the AIF-C01 exam army, we has become the top-raking AIF-C01 training materials provider in the international market.
Reliable AIF-C01 Exam Review: https://www.trainingdumps.com/AIF-C01_exam-valid-dumps.html
What's more, part of that TrainingDumps AIF-C01 dumps now are free: https://drive.google.com/open?id=1XVK9TgQk7Z7qiCkOZfjShxk2li25sh83