In order to meet the needs of all customers, Our AI-200 study torrent has a long-distance aid function. If you feel confused about our AI-200 test torrent when you use our products, do not hesitate and send a remote assistance invitation to us for help, we are willing to provide remote assistance for you in the shortest time. We have professional staff, so your all problems about AI-200 Guide Torrent will be solved by our professional staff. We can make sure that you will enjoy our considerate service if you buy our AI-200 study torrent.
| Section | Objectives |
|---|---|
| Topic 1: Connect to and consume Azure services | - Integrate Azure services
|
| Topic 2: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Topic 3: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 4: Develop containerized solutions on Azure | - Implement containerized applications
|
DumpsValid is a platform that will provide candidates with most effective AI-200 study materials to help them pass their AI-200 exam. It has been recognized by all of our customers, because it was compiled by many professional experts of our website. Not only did they pass their AI-200 Exam but also got a satisfactory score. These are due to the high quality of our AI-200 study torrent that leads to such a high pass rate as more than 98%. You will never feel dispointment about our AI-200 exam questions.
NEW QUESTION # 88
A large retail company operates online and physical stores. The company tracks inventory levels in real time to manage stock efficiently across all locations. You develop an Azure Event Grid solution to handle events generated by the inventory management system deployed to Azure.
You need to implement a subscription filter that dynamically adjusts to seasonal changes in product demand.
Which event filter should you use?
Answer: C
NEW QUESTION # 89
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Drag and Drop Question
You need to implement trace correlation according to the business requirements.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.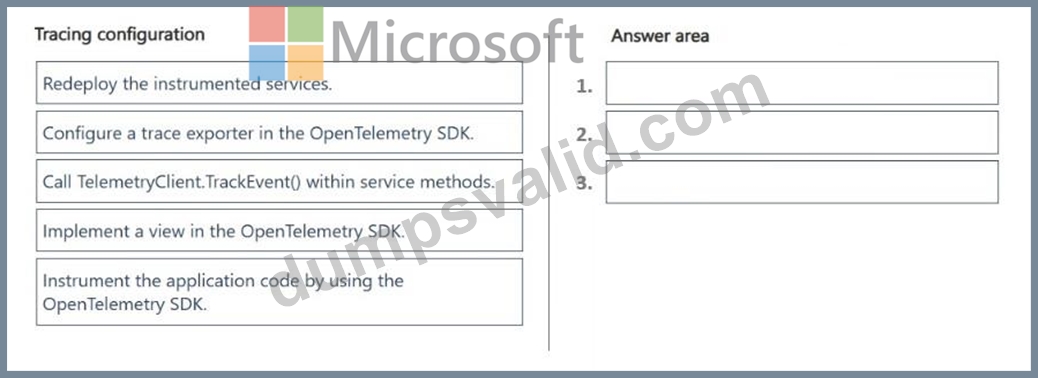
Answer:
Explanation: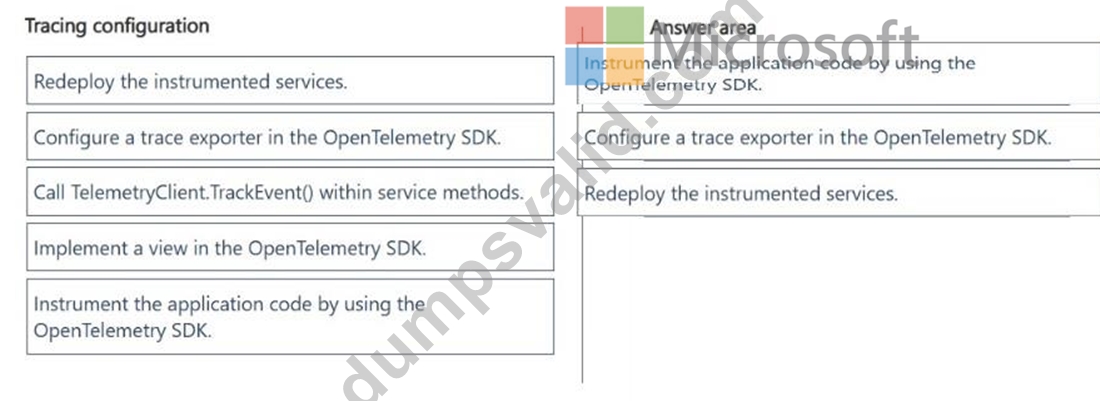
Explanation:
Scenario, Business Requirements
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Step 1: Instrument the application code by using OpenTelemetry SDK
This adds the foundational tracking APIs to your code so it can create and capture trace spans.
Step 2: Configure a trace exporter in the OpenTelemetry SDK
This instructs the initialized SDK where to transmit the captured trace data (e.g., to a local console or a cloud backend).
Step 3: Redeploy the instrumented services
This pushes the modified codebase and configuration changes into your active runtime environment.
Reference:
https://opentelemetry.io/docs/languages/python/instrumentation/
NEW QUESTION # 90
You are reviewing an Azure Function app that processes incoming order requests for a company. The function must:
* Accept order submissions from an external client application.
* Require controlled access for security
* Return a response containing the processed request payload.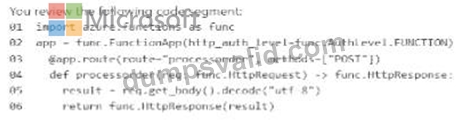
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.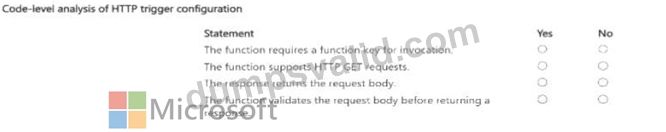
Answer:
Explanation:
Explanation: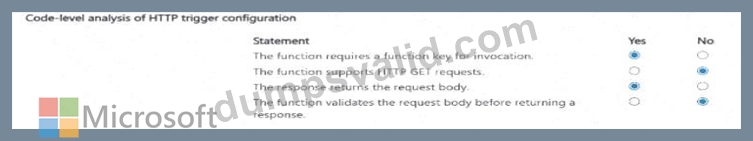
Verified answer: Yes; No; Yes; No.
Detailed Explanation: `auth_level=FUNCTION` means invocation requires a function key unless a stronger platform authentication layer is configured, so the first statement is true. The route explicitly permits POST, not GET. The function reads `req.get_body()` and returns that value in the HttpResponse, so the response contains the request body. No schema, type, required-field, or other payload validation is performed before the response is constructed, making the final statement false.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Azure Functions HTTP trigger
NEW QUESTION # 91
You are developing an AI search API that caches semantic search results in Redis.
Search results must remain cached for 10 minutes. If the underlying data changes, cached entries must NOT be returned.
You need to implement a cache aside strategy to ensure data consistency.
Which two actions should you perform? Each correct answer presents part of the solution. Choose two NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
Detailed Explanation: The cache-aside design needs both bounded lifetime and explicit invalidation. A ten- minute TTL ensures cached search results do not persist indefinitely, while deleting related keys when source data changes prevents known-stale entries from being returned during that ten-minute window. Sliding expiration would extend lifetime based on access and can preserve stale data. Keyspace notifications report Redis key events; they do not replace application logic that invalidates entries when the authoritative source changes.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Azure Managed Redis documentation
NEW QUESTION # 92
You plan to deploy a web application to AKS.
The solution must:
* Scale out the application by adding more pods during peak CPU usage
* Expose the application internally within the cluster only
You need to configure a Kubernetes resource for each requirement
Which resources should you configure? To answer, move the appropriate resources to the correct requirements You may use each resource once, more than once, or not at all. You may need to move split bar between .. or scroll to view content.
Answer:
Explanation: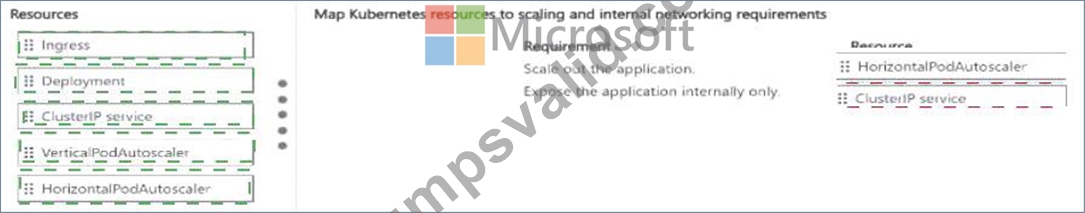
Explanation: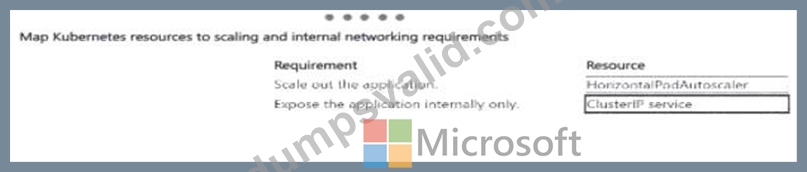
Verified Answer: Scale out the application: HorizontalPodAutoscaler. Expose internally only: ClusterIP service.
Detailed Explanation: The Kubernetes HorizontalPodAutoscaler increases or decreases pod replicas in response to CPU, memory, or other metrics, so it is the resource that implements CPU-driven pod scale-out. A ClusterIP service creates an internal service IP that is reachable within the Kubernetes cluster and is the normal choice for an internal-only service. A Deployment defines the workload but does not itself implement metric-driven autoscaling, while Ingress is intended to route inbound network traffic.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | AKS scaling overview | Kubernetes services in AKS
NEW QUESTION # 93
......
Our services before, during and after the clients use our AI-200 certification material are considerate. Before the purchase, the clients can download and try out our AI-200 learning file freely. During the clients use our products they can contact our online customer service staff to consult the problems about our products. Our company gives priority to the satisfaction degree of the clients on our AI-200 Exam Questions and puts the quality of the service in the first place. We also have free demo of our AI-200 learning guide for you to check the quality before your payment.
AI-200 Valid Test Sample: https://www.dumpsvalid.com/AI-200-still-valid-exam.html