Übrigens, Sie können die vollständige Version der EchteFrage Databricks-Generative-AI-Engineer-Associate Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1zUy9CpLWI43VQajDlqlTdKlgU5b3_6A0
Die Databricks Databricks-Generative-AI-Engineer-Associate Prüfung zu bestehen ist eigentlich nicht leicht. Trotzdem ist die Zertifizierung nicht nur ein Beweis für Ihre IT-Fähigkeit, sondern auch ein weltweit anerkannter Durchgangsausweis. Auf Databricks Databricks-Generative-AI-Engineer-Associate vorzubereiten darf man nicht blindlings. Die Technik-Gruppe von uns EchteFrage haben die Prüfungssoftware der Databricks Databricks-Generative-AI-Engineer-Associate nach der Mnemotechnik entwickelt. Sie kann mit vernünftiger Methode Ihre Belastungen der Vorbereitung auf Databricks Databricks-Generative-AI-Engineer-Associate erleichtern.
| Section | Weight | Objectives |
|---|---|---|
| Evaluation and Monitoring | 12% | - Iterate and improve solutions - Monitor application behavior and outputs - Evaluate model and application performance |
| Assembling and Deploying Apps | 22% | - Manage application lifecycle - Deploy models via Model Serving - Package and deploy applications |
| Design Applications | 14% | - Decompose complex requirements into tasks - Select appropriate models, tools and approaches - Design solution architecture |
| Governance | 8% | - Manage access and permissions - Apply Unity Catalog for data governance - Ensure compliance and security |
| Data Preparation | 14% | - Prepare and process data for LLM use - Manage data quality and format - Implement data pipelines and transformations |
| Application Development | 30% | - Build RAG applications - Use Databricks Vector Search - Develop LLM chains and workflows - Integrate with MLflow |
>> Databricks-Generative-AI-Engineer-Associate Examengine <<
Aufgrund der großen Übereinstimmung mit den echten Databricks Databricks-Generative-AI-Engineer-Associate Prüfungsfragen und -antworten (Databricks Certified Generative AI Engineer Associate) können wir Ihnen 100%-Pass-Garantie versprechen. Wir aktualisieren jeden Tag nach den Informationen von Prüfungsabsolventen oder Mitarbeitern aus dem Testcenter unsere Prüfungsfragen und Antworten zu Databricks Databricks-Generative-AI-Engineer-Associate Fragenpool (Databricks Certified Generative AI Engineer Associate). Wir extrahieren jeden Tag die Informationen der tatsächlichen Prüfungen und integrieren in unsere Produkte.
26. Frage
A Generative AI Engineer is experimenting with using parameters to configure an agent in Mosaic Agent Framework. However, they are struggling to get the agent to respond with relevant information with this configuration:
config = {"prompt_template": "You are a trivia bot. Generate a question based on the user's input: {user_input}", "input_vars": ["user_input"], "parameters": {"temperature": 0.01, "max_tokens": 500}} Which error is causing the problem?
Antwort: A
Begründung:
In the Mosaic AI Agent Framework and underlying LangChain-based configurations, the "input_vars" or "input_variables" must be correctly mapped and referenced within the template. If the configuration dictionary identifies user_input as the variable but the logic executing the chain does not correctly "inject" the runtime value into the {user_input} placeholder, the LLM will receive a literal string (or an empty value) rather than the user's actual question. This results in the model failing to provide relevant information because it essentially doesn't know what the user asked. Engineering standards require ensuring that the key used in the input_vars list matches the key in the JSON payload sent to the model serving endpoint. If there is a mismatch or a failure to parse, the prompt remains static, leading to generic or irrelevant responses.
27. Frage
A Generative Al Engineer is setting up a Databricks Vector Search that will lookup news articles by topic within 10 days of the date specified An example query might be "Tell me about monster truck news around January 5th 1992". They want to do this with the least amount of effort.
How can they set up their Vector Search index to support this use case?
Antwort: D
Begründung:
The task is to set up a Databricks Vector Search index for news articles, supporting queries like "monster truck news around January 5th, 1992," with minimal effort. The index must filter by topic and a 10-day date range. Let's evaluate the options.
* Option A: Split articles by 10-day blocks and return the block closest to the query
* Pre-splitting articles into 10-day blocks requires significant preprocessing and index management (e.g., one index per block). It's effort-intensive and inflexible for dynamic date ranges.
* Databricks Reference:"Static partitioning increases setup complexity; metadata filtering is preferred"("Databricks Vector Search Documentation").
* Option B: Include metadata columns for article date and topic to support metadata filtering
* Adding date and topic as metadata in the Vector Search index allows dynamic filtering (e.g., date
± 5 days, topic = "monster truck") at query time. This leverages Databricks' built-in metadata filtering, minimizing setup effort.
* Databricks Reference:"Vector Search supports metadata filtering on columns like date or category for precise retrieval with minimal preprocessing"("Vector Search Guide," 2023).
* Option C: Pass the query directly to the vector search index and return the best articles
* Passing the full query (e.g., "Tell me about monster truck news around January 5th, 1992") to Vector Search relies solely on embeddings, ignoring structured filtering for date and topic. This risks inaccurate results without explicit range logic.
* Databricks Reference:"Pure vector similarity may not handle temporal or categorical constraints effectively"("Building LLM Applications with Databricks").
* Option D: Create separate indexes by topic and add a classifier model to appropriately pick the best index
* Separate indexes per topic plus a classifier model adds significant complexity (index creation, model training, maintenance), far exceeding "least effort." It's overkill for this use case.
* Databricks Reference:"Multiple indexes increase overhead; single-index with metadata is simpler"("Databricks Vector Search Documentation").
Conclusion: Option B is the simplest and most effective solution, using metadata filtering in a single Vector Search index to handle date ranges and topics, aligning with Databricks' emphasis on efficient, low-effort setups.
28. Frage
A Generative Al Engineer is using an LLM to classify species of edible mushrooms based on text descriptions of certain features. The model is returning accurate responses in testing and the Generative Al Engineer is confident they have the correct list of possible labels, but the output frequently contains additional reasoning in the answer when the Generative Al Engineer only wants to return the label with no additional text.
Which action should they take to elicit the desired behavior from this LLM?
Antwort: A
Begründung:
The LLM classifies mushroom species accurately but includes unwanted reasoning text, and the engineer wants only the label. Let's assess how to control output format effectively.
* Option A: Use few shot prompting to instruct the model on expected output format
* Few-shot prompting provides examples (e.g., input: description, output: label). It can work but requires crafting multiple examples, which is effort-intensive and less direct than a clear instruction.
* Databricks Reference:"Few-shot prompting guides LLMs via examples, effective for format control but requires careful design"("Generative AI Cookbook").
* Option B: Use zero shot prompting to instruct the model on expected output format
* Zero-shot prompting relies on a single instruction (e.g., "Return only the label") without examples. It's simpler than few-shot but may not consistently enforce succinctness if the LLM's default behavior is verbose.
* Databricks Reference:"Zero-shot prompting can specify output but may lack precision without examples"("Building LLM Applications with Databricks").
* Option C: Use zero shot chain-of-thought prompting to prevent a verbose output format
* Chain-of-Thought (CoT) encourages step-by-step reasoning, which increases verbosity-opposite to the desired outcome. This contradicts the goal of label-only output.
* Databricks Reference:"CoT prompting enhances reasoning but often results in detailed responses"("Databricks Generative AI Engineer Guide").
* Option D: Use a system prompt to instruct the model to be succinct in its answer
* A system prompt (e.g., "Respond with only the species label, no additional text") sets a global instruction for the LLM's behavior. It's direct, reusable, and effective for controlling output style across queries.
* Databricks Reference:"System prompts define LLM behavior consistently, ideal for enforcing concise outputs"("Generative AI Cookbook," 2023).
Conclusion: Option D is the most effective and straightforward action, using a system prompt to enforce succinct, label-only responses, aligning with Databricks' best practices for output control.
29. Frage
A Generative Al Engineer is creating an LLM-based application. The documents for its retriever have been chunked to a maximum of 512 tokens each. The Generative Al Engineer knows that cost and latency are more important than quality for this application. They have several context length levels to choose from.
Which will fulfill their need?
Antwort: C
Begründung:
When prioritizing cost and latency over quality in a Large Language Model (LLM)-based application, it is crucial to select a configuration that minimizes both computational resources and latency while still providing reasonable performance. Here's whyDis the best choice:
* Context length: The context length of 512 tokens aligns with the chunk size used for the documents (maximum of 512 tokens per chunk). This is sufficient for capturing the needed information and generating responses without unnecessary overhead.
* Smallest model size: The model with a size of 0.13GB is significantly smaller than the other options.
This small footprint ensures faster inference times and lower memory usage, which directly reduces both latency and cost.
* Embedding dimension: While the embedding dimension of 384 is smaller than the other options, it is still adequate for tasks where cost and speed are more important than precision and depth of understanding.
This setup achieves the desired balance between cost-efficiency and reasonable performance in a latency- sensitive, cost-conscious application.
30. Frage
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: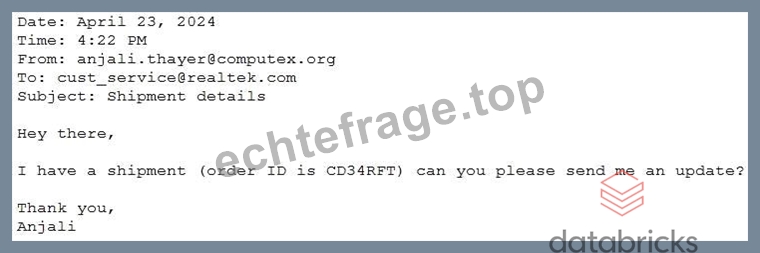
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Antwort: B
Begründung:
Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options:
* Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore,Option Bis optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
31. Frage
......
Wir EchteFrage bieten Ihnen die freundlichsten Kundendienst. Nach der Kauf der Databricks Databricks-Generative-AI-Engineer-Associate Prüfungssoftware, bieten wir Ihnen kostenlosen Aktualisierungsdienst für ein voll Jahr, um Sie die neusten und die umfassendsten Unterlagen der Databricks Databricks-Generative-AI-Engineer-Associate wissen zu lassen. Darum werden Sie sehr sicher sein, die Zertifizierungstest der Databricks Databricks-Generative-AI-Engineer-Associate zu bestehen. Falls Sie unglücklich die Test der Databricks Databricks-Generative-AI-Engineer-Associate nicht bei der ersten Proben bestehen, geben wir Ihnen die vollständige Gebühren zurück, um Iheren finanziellen Verlust zu entschädigen.
Databricks-Generative-AI-Engineer-Associate Schulungsunterlagen: https://www.echtefrage.top/Databricks-Generative-AI-Engineer-Associate-deutsch-pruefungen.html
Übrigens, Sie können die vollständige Version der EchteFrage Databricks-Generative-AI-Engineer-Associate Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1zUy9CpLWI43VQajDlqlTdKlgU5b3_6A0