New SPS-C01 Test Pass4sure - Exam SPS-C01 Registration

2026 Latest Actual4Labs SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1AMKVupXyl19wpDuUv7rC9qIn1kFd5O_c
And you can also use the Snowflake SPS-C01 PDF on smart devices like smartphones, laptops, and tablets. The second one is the web-based Snowflake SPS-C01 practice exam which can be accessed through the browsers like Firefox, Safari, and Snowflake Chrome. The customers don't need to download or install excessive plugins or software to get the full advantage from web-based SPS-C01 Practice Tests.
| Section | Weight | Objectives |
|---|
| Snowpark API and Development | 30% | - Python API fundamentals
- 1. Data persistence and writing results
- 2. Column operations and functions
- 3. DataFrame creation from tables, views, SQL
- Multi-language support
- 1. Java and Scala API basics
- 2. Environment setup and dependencies
|
| Data Transformations and Operations | 35% | - Advanced operations
- 1. Pivot and unpivot transformations
- 2. Window functions and analytics
- 3. Semi-structured data processing
- DataFrame manipulation
- 1. Selection, projection, renaming, casting
- 2. Filtering, sorting, grouping, aggregation
- 3. Joins, unions, set operations
- User-defined logic
- 1. UDFs, UDAFs, UDTFs
- 2. Stored procedures with Snowpark
|
| Performance and Best Practices | 10% | - Security and governance
- 1. Access control and permissions
- 2. Data protection and compliance
- Optimization techniques
- 1. Minimizing data movement
- 2. Query pushdown and execution plans
- 3. Caching and warehouse sizing
|
| Snowpark Concepts and Architecture | 25% | - Session management and connection
- 1. Authentication and connection settings
- 2. Create and configure Snowpark sessions
- Snowpark architecture and execution model
- 1. Transformations vs actions
- 2. Lazy evaluation and DAG execution
- 3. Client-side vs server-side processing
|
>> New SPS-C01 Test Pass4sure <<
Exam SPS-C01 Registration & SPS-C01 Latest Braindumps Files
We have handled professional SPS-C01 practice materials for over ten years. Our experts have many years’ experience in this particular line of business, together with meticulous and professional attitude towards jobs. Their abilities are unquestionable, besides, SPS-C01 practice materials are priced reasonably with three kinds. We also have free demo offering the latest catalogue and brief contents for your information, if you do not have thorough understanding of our materials. Many exam candidates build long-term relation with our company on the basis of our high quality SPS-C01 practice materials.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q333-Q338):
NEW QUESTION # 333
You have a Snowpark Python application that performs several data transformations on a DataFrame representing customer transactions. The application is experiencing performance issues, and you suspect that some transformations are unnecessarily expensive. Which of the following techniques can MOST effectively optimize the performance of your Snowpark application, specifically focusing on minimizing data movement and leveraging Snowflake's query optimization capabilities?
- A. Always use the largest available Snowflake warehouse size to ensure sufficient compute resources.
- B. Take the dataframe to Pandas dataframe as soon as possible in between transformations, since Pandas dataframes will be faster.
- C. Leverage Snowpark's built-in DataFrame transformations (e.g., .groupBy()') to allow Snowflake to optimize the query execution plan. Avoid pulling large amounts of data into the client application for simple operations. Only call 'collect()' as the last and final option, as this is the most costly activity of all.
- D. Explicitly call .cache()' on the DataFrame after each transformation to materialize intermediate results in memory.
- E. Use User-Defined Functions (UDFs) written in Python for all transformations, regardless of their complexity.
Answer: C
Explanation:
Snowpark is designed to push down computations to Snowflake, allowing Snowflake's query optimizer to handle the execution. Using Snowpark's built-in DataFrame transformations allows Snowflake to understand the intent and optimize the query accordingly. Materializing intermediate results using .cache()' (A) can lead to unnecessary data movement. Python UDFs (B) can be useful for complex logic but should be avoided for simple transformations as they bypass Snowflake's optimization capabilities and are generally slower than native SQL functions. Warehouse size (E) is a factor, but optimizing the query logic is more crucial. Using Pandas dataframe is also costly and performance heavy.
NEW QUESTION # 334
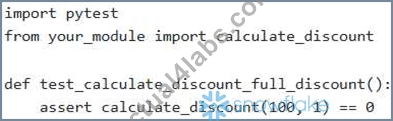
You are developing a Snowpark Python application and want to write unit tests for your custom UDFs using pytest. Consider the following UDF:
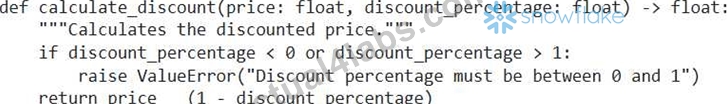
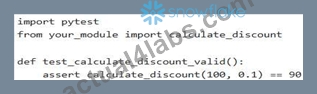
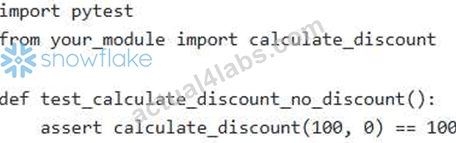
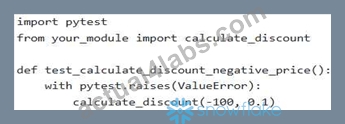
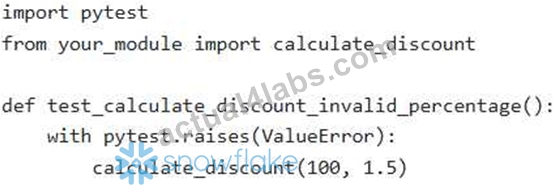
Which of the following pytest tests are correctly written and effectively test the UDF, including handling potential exceptions? (Select all that apply)
Answer: A,B,D,E
Explanation:
Options A, B, C, and D represent correctly written pytest tests. A tests a valid discount, B tests the exception handling for an invalid percentage, C tests the case with no discount, and D tests a full discount. E is incorrect because the calculate_discount function does not explicitly check for negative prices, therefore 'pytest.raises(ValueErrorV will cause a failed test since no ValueError is raised.
NEW QUESTION # 335
You're building a Snowpark Python application that processes sensor data from various devices. The data arrives as a stream of JSON objects, each containing the device ID, timestamp, and sensor readings. You want to use a Streamlit application to visualize near real- time aggregates on the data'. You're aiming to create a Snowpark DataFrame from this data, perform transformations, and then serve this DataFrame to Streamlit. Which of the following approaches concerning creating the initial DataFrame from JSON data is generally the MOST efficient and scalable for handling such a stream of data?
- A. Iteratively append each JSON object to a Python list, then create a Snowpark DataFrame from the list using 'session.createDataFrame(list_of_json_objectsy.
- B. Read the JSON data directly from the stream into a Pandas DataFrame using , then convert the Pandas DataFrame to a Snowpark DataFrame using 'session.createDataFrame(pandas_df)'.
- C. Use Snowflake's Kafka connector to ingest the JSON data directly into a Snowflake table, and then create a Snowpark DataFrame from that table using 'session.table()'.
- D. Utilize Snowpipe with auto-ingest configured to load the JSON data into a raw data Snowflake table, and subsequently, establish a Snowpark DataFrame using 'session.table('raw_data_table')'. You can then apply necessary transformations using Snowpark.
- E. Write each incoming JSON object to a temporary file in cloud storage (e.g., AWS S3 or Azure Blob Storage) and then periodically use 'session.read.json()' to create a Snowpark DataFrame from the files.
Answer: C
Explanation:
Using Snowflake's Kafka connector (or a similar streaming ingestion service) is the most efficient and scalable way to handle streaming data. It allows for near real-time ingestion and avoids intermediate steps like writing to temporary files or using Pandas DataFrames. Using Snowpipe with auto-ingest is also a valid approach, however Kafka connector is slightly better suited for streaming data because of its real time data processing. Kafka is also a common real time streaming platform. Therefore, option C is the best answer. Other options may encounter scalability and performance issues with high-volume, continuous data streams.
NEW QUESTION # 336
Consider the following Snowpark Python code snippet that retrieves data and calculates aggregate values, however, the application performance is slow when you are fetching dataframe, given the 'block' parameter controls the synchronous/asynchronous behavior of the 'collect()' method. Choose ALL the statements about "session.create_dataframe([rowl ,row2],schema)' that are correct:
- A. Snowflake warehouse size has no influence on dataframe creation, so if the dataframe is large and 'block=True' it will block the performance.
- B. The 'block' parameter has no influence on performance when creating dataframes, and hence the performance is mainly based on query optimization and ware house size.
- C. The method, when executed with default 'block=True' , will wait for the result to be available before proceeding to the other statements in the code and hence performance is low. However, makes it asynchronous.
- D. Consider replacing the call of 'collect()' with and converting Snowpark dataframe to Pandas dataframe. The dataframe operations could be efficient.
- E. Increasing warehouse size of Snowflake will increase performance irrespective of the fact whether block is True or False.
Answer: C
Explanation:
The method, when used with the default 'block=True' , operates synchronously, meaning it waits for the result to be fully available before proceeding to the next line of code. This can introduce latency and slow down the application, especially with larger datasets. Using 'block=False' makes the operation asynchronous, allowing the application to continue executing other tasks while the data is being retrieved in the background. Increasing warehouse size will have the same effect regardless, because of . The 'block' parameter is crucial for controlling synchronous versus asynchronous behaviour. The warehouse has no direct influence since the bottleneck is with 'collect()'. Converting to pandas does not fix the inherent blocking problem and makes the problem worse, given it increase network I/O to move data to client side.
NEW QUESTION # 337
You are working with two large Snowpark DataFrames: 'transaction_df and 'product df. 'transaction_df contains transaction data including 'transaction id', 'product id', and 'transaction_date'. 'product df contains product details including 'product id', product_name', and 'product category'. You need to join these DataFrames to analyze transaction data by product category. The 'transaction_df is significantly larger than 'product_df. Which of the following strategies can significantly improve the performance of the join operation in Snowpark? (Select all that apply)
- A. Cache the 'transaction_df DataFrame before the join operation using
- B. Use a 'hint' to force Snowflake to use a specific join algorithm like 'MERGE JOINS.
- C. Ensure that the 'product_id' column in both DataFrames is of the same data type and has statistics collected on it.
- D. Filter the 'transaction_df to a smaller subset based on 'transaction_date' before performing the join, if only recent transactions are needed.
- E. Use a broadcast join by explicitly specifying 'broadcast-True in the 'join' function when joining 'product_df to 'transaction_df.
Answer: C,D,E
Explanation:
Options A, B, and D are correct. A ensures efficient comparison and join execution. B leverages broadcast join when smaller dataframe is broadcasted to all nodes, reducing data movement. D reduces the size of the larger DataFrame before the join, improving performance. C is incorrect because caching the larger 'transaction_df DataFrame before the join won't significantly improve performance; Snowpark automatically optimizes query execution. E is wrong because Snowflake manages join algorithms efficiently, forcing a specific algorithm might be counterproductive.
NEW QUESTION # 338
......
We think of providing the best services as our obligation. So we have patient colleagues offering help 24/7 and solve your problems about SPS-C01 training materials all the way. We have considerate services as long as you need us. Do not underestimate your ability, we will be your strongest backup while you are trying with our SPS-C01 Real Exam. Besides, to fail while trying hard is no dishonor. We will provide the free update of our SPS-C01 study engine until you pass your exam successfully!
Exam SPS-C01 Registration: https://www.actual4labs.com/Snowflake/SPS-C01-actual-exam-dumps.html
- SPS-C01 Valid Exam Fee 🎁 SPS-C01 Examcollection Dumps Torrent 🆖 SPS-C01 Latest Exam Book 🦘 Go to website ▶ www.examcollectionpass.com ◀ open and search for ⏩ SPS-C01 ⏪ to download for free 🍸SPS-C01 Examcollection Dumps Torrent
- SPS-C01 Discount 🍚 SPS-C01 Discount 🏥 New SPS-C01 Test Voucher 🛸 Download ➡ SPS-C01 ️⬅️ for free by simply entering ☀ www.pdfvce.com ️☀️ website 🧝Reliable SPS-C01 Test Review
- 100% Pass Quiz SPS-C01 Marvelous New Snowflake Certified SnowPro Specialty - Snowpark Test Pass4sure 🎧 Enter [ www.exam4labs.com ] and search for ✔ SPS-C01 ️✔️ to download for free 🤡SPS-C01 Exam Success
- New SPS-C01 Test Pass4sure | Efficient Exam SPS-C01 Registration: Snowflake Certified SnowPro Specialty - Snowpark 🆖 Immediately open ➡ www.pdfvce.com ️⬅️ and search for ➠ SPS-C01 🠰 to obtain a free download 🩲Reliable SPS-C01 Test Review
- SPS-C01 Real Exam ✊ New SPS-C01 Exam Dumps 🤝 SPS-C01 Real Exam 🍡 Search for [ SPS-C01 ] and download it for free on ➽ www.vce4dumps.com 🢪 website ☝SPS-C01 Latest Exam Book
- New SPS-C01 Exam Dumps 🔩 Valid SPS-C01 Test Blueprint 📎 New SPS-C01 Test Voucher 💯 Immediately open 《 www.pdfvce.com 》 and search for ⮆ SPS-C01 ⮄ to obtain a free download 🔚SPS-C01 Latest Exam Book
- New SPS-C01 Exam Dumps ↙ SPS-C01 Reliable Braindumps Free 🔈 SPS-C01 Exam Success 📅 Copy URL ▷ www.testkingpass.com ◁ open and search for ☀ SPS-C01 ️☀️ to download for free 🎫SPS-C01 Valid Exam Fee
- SPS-C01 Examcollection Dumps Torrent ℹ SPS-C01 Real Exam 🏮 New SPS-C01 Exam Dumps 🦅 Download ( SPS-C01 ) for free by simply entering ⏩ www.pdfvce.com ⏪ website 👰SPS-C01 Examcollection Dumps Torrent
- SPS-C01 Test Vce 📑 Certification SPS-C01 Exam Dumps 💌 Test SPS-C01 Pdf 🎢 Enter { www.easy4engine.com } and search for ▷ SPS-C01 ◁ to download for free 🆖SPS-C01 Valid Exam Camp
- SPS-C01 Latest Learning Material 📩 SPS-C01 Reliable Exam Registration 🐄 New SPS-C01 Exam Dumps ☀ Easily obtain free download of ➠ SPS-C01 🠰 by searching on 【 www.pdfvce.com 】 🥋Certification SPS-C01 Exam Dumps
- Valid SPS-C01 Test Blueprint 💒 Valid SPS-C01 Test Blueprint 👤 Exam SPS-C01 Consultant ☝ Search for ➠ SPS-C01 🠰 and obtain a free download on ▛ www.exam4labs.com ▟ 🚼SPS-C01 Test Vce
- www.stes.tyc.edu.tw, www.notebook.ai, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! Download part of Actual4Labs SPS-C01 dumps for free: https://drive.google.com/open?id=1AMKVupXyl19wpDuUv7rC9qIn1kFd5O_c