
DOWNLOAD the newest TestKingIT DOP-C02 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1rHLUda8ngNMhLdtBo508hEoXhZZmtvo4
It is really a tough work to getting DOP-C02 certification in their spare time because preparing actual exam dumps needs plenty time and energy. As the one of certification exam dumps provider, TestKingIT enjoys a high popularity for its profession of DOP-C02 Exam Dumps and training materials. You will get high passing score in test with the help of our DOP-C02 braindumps torrent.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Incident and Event Response | 18% | - Design and implement event and incident management
|
| Topic 2: Policies and Standards Automation | 10% | - Design and implement governance strategies
|
| Topic 3: High Availability and Disaster Recovery | 16% | - Design and implement high availability and scalability
|
| Topic 4: Monitoring and Logging | 12% | - Design and implement monitoring and observability strategies
|
| Topic 5: Configuration Management and Infrastructure as Code | 22% | - Design and implement configuration management
|
| Topic 6: SDLC Automation | 22% | - Design and implement CI/CD pipelines
|
The DOP-C02 exam materials is a dump, maybe many candidates will worry about how to payment and whether it is safe when pay for it. Some people may think that online shopping is not safe. Now I will tell you responsibly that our payment method of DOP-C02 exam materials is very secure. The payment method we use is credit card payment, not only can we guarantee your security of the payment, but also we can protect your right and interests. As for the safety issue of DOP-C02 Exam Materials you are concerned about is completely unnecessary. You can rest assured to buy and use it.
NEW QUESTION # 81
A DevOps engineer manages a company's Amazon Elastic Container Service (Amazon ECS) cluster. The cluster runs on several Amazon EC2 instances that are in an Auto Scaling group. The DevOps engineer must implement a solution that logs and reviews all stopped tasks for errors.
Which solution will meet these requirements?
Answer: C
Explanation:
The best solution to log and review all stopped tasks for errors is to use Amazon EventBridge and Amazon CloudWatch Logs. Amazon EventBridge allows the DevOps engineer to create a rule that matches task state change events from Amazon ECS. The rule can then send the event data to Amazon CloudWatch Logs as the target. Amazon CloudWatch Logs can store and monitor the log data, and also provide CloudWatch Logs Insights, a feature that enables the DevOps engineer to interactively search and analyze the log data. Using CloudWatch Logs Insights, the DevOps engineer can filter and aggregate the log data based on various fields, such as cluster, task, container, and reason. This way, the DevOps engineer can easily identify and investigate the stopped tasks and their errors.
The other options are not as effective or efficient as the solution in option A. Option B is not suitable because the embedded metric format is designed for custom metrics, not for logging task state changes. Option C is not feasible because the EC2 instances do not store the task state change events in their logs. Option D is not relevant because theEC2_INSTANCE_TERMINATING lifecycle hook is triggered when an EC2 instance is terminated by the Auto Scaling group, not when a task is stopped by Amazon ECS.
References:
* : Creating a CloudWatch Events Rule That Triggers on an Event - Amazon Elastic Container Service
* : Sending and Receiving Events Between AWS Accounts - Amazon EventBridge
* : Working with Log Data - Amazon CloudWatch Logs
* : Analyzing Log Data with CloudWatch Logs Insights - Amazon CloudWatch Logs
* : Embedded Metric Format - Amazon CloudWatch
* : Amazon EC2 Auto Scaling Lifecycle Hooks - Amazon EC2 Auto Scaling
NEW QUESTION # 82
A company deploys a web application on Amazon EC2 instances that are behind an Application Load Balancer (ALB). The company stores the application code in an AWS CodeCommit repository. When code is merged to the main branch, an AWS Lambda function invokes an AWS CodeBuild project. The CodeBuild project packages the code, stores the packaged code in AWS CodeArtifact, and invokes AWS Systems Manager Run Command to deploy the packaged code to the EC2 instances.
Previous deployments have resulted in defects, EC2 instances that are not running the latest version of the packaged code, and inconsistencies between instances.
Which combination of actions should a DevOps engineer take to implement a more reliable deployment solution? (Select TWO.)
Answer: C,D
Explanation:
To implement a more reliable deployment solution, a DevOps engineer should take the following actions:
Create a pipeline in AWS CodePipeline that uses the CodeCommit repository as a source provider. Configure pipeline stages that run the CodeBuild project in parallel to build and test the application. In the pipeline, pass the CodeBuild project output artifact to an AWS CodeDeploy action. This action will improve the deployment reliability by automating the entire process from code commit to deployment, reducing human errors and inconsistencies. By running the build and test stages in parallel, the pipeline can also speed up the delivery time and provide faster feedback. By using CodeDeploy as the deployment action, the pipeline can leverage the features of CodeDeploy, such as traffic shifting, health checks, rollback, and deployment configuration123 Create an AWS CodeDeploy application and a deployment group to deploy the packaged code to the EC2 instances. Configure the ALB for the deployment group. This action will improve the deployment reliability by using CodeDeploy to orchestrate the deployment across multiple EC2 instances behind an ALB. CodeDeploy can perform blue/green deployments or in-place deployments with traffic shifting, which can minimize downtime and reduce risks. CodeDeploy can also monitor the health of the instances during and after the deployment, and automatically roll back if any issues are detected. By configuring the ALB for the deployment group, CodeDeploy can register and deregister instances from the load balancer as needed, ensuring that only healthy instances receive traffic45 The other options are not correct because they do not improve the deployment reliability or follow best practices. Creating separate pipeline stages that run a CodeBuild project to build and then test the application is not a good option because it will increase the pipeline execution time and delay the feedback loop. Creating individual Lambda functions that use CodeDeploy instead of Systems Manager to run build, test, and deploy actions is not a valid option because it will add unnecessary complexity and cost to the solution. Lambda functions are not designed for long-running tasks such as building or deploying applications. Creating an Amazon S3 bucket and modifying the CodeBuild project to store the packages in the S3 bucket instead of in CodeArtifact is not a necessary option because it will not affect the deployment reliability. CodeArtifact is a secure, scalable, and cost-effective package management service that can store and share software packages for application development67
:
1: What is AWS CodePipeline? - AWS CodePipeline
2: Create a pipeline in AWS CodePipeline - AWS CodePipeline
3: Deploy an application with AWS CodeDeploy - AWS CodePipeline
4: What is AWS CodeDeploy? - AWS CodeDeploy
5: Configure an Application Load Balancer for your blue/green deployments - AWS CodeDeploy
6: What is AWS Lambda? - AWS Lambda
7: What is AWS CodeArtifact? - AWS CodeArtifact
NEW QUESTION # 83
A company is reviewing its 1AM policies. One policy written by the DevOps engineer has been (lagged as too permissive. The policy is used by an AWS Lambda function that issues a stop command to Amazon EC2 instances tagged with Environment: NonProduccion over the weekend. The current policy is: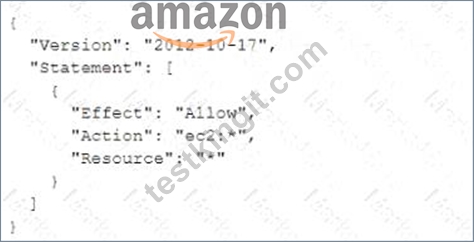
What changes should the engineer make to achieve a policy ot least permission? (Select THREE.)

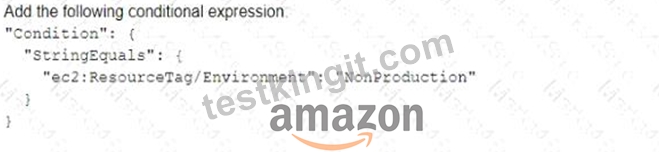
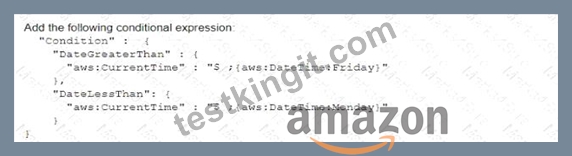
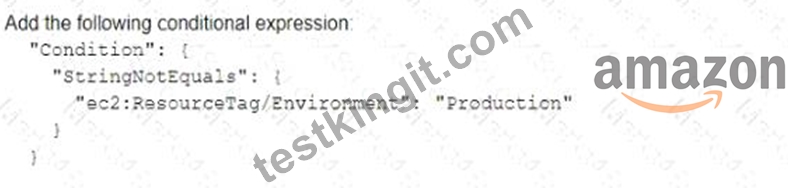

Answer: B,E,F
Explanation:
Explanation
The engineer should make the following changes to achieve a policy of least permission:
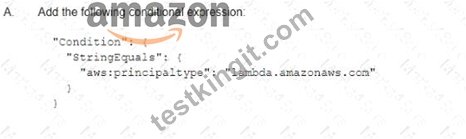
* A: Add a condition to ensure that the principal making the request is an AWS Lambda function. This ensures that only Lambda functions can execute this policy.
* B: Narrow down the resources by specifying the ARN of EC2 instances instead of allowing all resources. This ensures that the policy only affects EC2 instances.
* D: Add a condition to ensure that this policy only applies to EC2 instances tagged with "Environment:
NonProduction". This ensures that production environments are not affected by this policy.
References:
* AWS Identity and Access Management (IAM) - AWS Documentation
* Certified DevOps Engineer - Professional (DOP-C02) Study Guide (page 179)
NEW QUESTION # 84
A company's DevOps engineer uses AWS Systems Manager to perform maintenance tasks during maintenance windows. The company has a few Amazon EC2 instances that require a restart after notifications from AWS Health. The DevOps engineer needs to implement an automated solution to remediate these notifications. The DevOps engineer creates an Amazon EventBridge rule.
How should the DevOps engineer configure the EventBridge rule to meet these requirements?
Answer: A
Explanation:
AWS Health provides real-time events and information related to your AWS infrastructure. It can be integrated with Amazon EventBridge to act upon the health events automatically. If the maintenance notification from AWS Health indicates that an EC2 instance requires a restart, you can set up an EventBridge rule to respond to such events. In this case, the target of this rule would be a Lambda function that would trigger a Systems Manager automation to restart the EC2 instance during a maintenance window. Remember, AWS Health is the source of the events (not EC2 or Systems Manager), and AWS Lambda can be used to execute complex remediation tasks, such as scheduling maintenance tasks via Systems Manager.
The following are the steps involved in configuring the EventBridge rule to meet these requirements:
Configure an event source of AWS Health, a service of EC2, and an event type that indicates instance maintenance.
Target a newly created AWS Lambda function that registers an automation task to restart the EC2 instance during a maintenance window.
The AWS Lambda function will be triggered by the event from AWS Health. The function will then register an automation task to restart the EC2 instance during the next maintenance window.
NEW QUESTION # 85
A company has multiple development teams in different business units that work in a shared single AWS account All Amazon EC2 resources that are created in the account must include tags that specify who created the resources. The tagging must occur within the first hour of resource creation.
A DevOps engineer needs to add tags to the created resources that Include the user ID that created the resource and the cost center ID The DevOps engineer configures an AWS Lambda function With the cost center mappings to tag the resources. The DevOps engineer also sets up AWS CloudTrail in the AWS account. An Amazon S3 bucket stores the CloudTrail event logs Which solution will meet the tagging requirements?
Answer: A
Explanation:
Option A is incorrect because S3 event notifications do not support s3.ObjectTagging:Put events. S3 event notifications only support events related to object creation, deletion, replication, and restore. Moreover, enabling bucket versioning on the S3 bucket is not relevant to the tagging requirements, as it only keeps multiple versions of objects in the bucket.
Option B is incorrect because enabling server access logging on the S3 bucket does not help with tagging the resources. Server access logging only records requests for access to the bucket or its objects. It does not capture the user ID or the cost center ID of the resources. Furthermore, creating an S3 event notification on the S3 bucket for s3.ObjectTagging:Put events is not possible, as explained in option A.
Option C is incorrect because creating a recurring hourly Amazon EventBridge scheduled rule that invokes the Lambda function is not efficient or timely. The Lambda function would have to read the logs from the S3 bucket every hour and tag the resources accordingly, which could incur unnecessary costs and delays. A better solution would be to trigger the Lambda function as soon as a resource is created, rather than waiting for an hourly schedule.
Option D is correct because creating an Amazon EventBridge rule that uses Amazon EC2 as the event source and matches events delivered by CloudTrail is a valid way to tag the resources. CloudTrail records all API calls made to AWS services, including EC2, and delivers them as events to EventBridge. The EventBridge rule can filter the events based on the user ID and the resource type, and then target the Lambda function to tag the resources with the cost center ID. This solution meets the tagging requirements in a timely and efficient manner.
Reference:
S3 event notifications
Server access logging
Amazon EventBridge rules
AWS CloudTrail
NEW QUESTION # 86
......
The only goal of all experts and professors in our company is to design the best and suitable study materials for all people. According to the different demands of many customers, they have designed the three different versions of the DOP-C02 Study Materials for all customers. They sincerely hope that all people who use the DOP-C02 study materials from our company can pass the exam and get the related certification successfully.
DOP-C02 Latest Exam Registration: https://www.testkingit.com/Amazon/latest-DOP-C02-exam-dumps.html
P.S. Free 2026 Amazon DOP-C02 dumps are available on Google Drive shared by TestKingIT: https://drive.google.com/open?id=1rHLUda8ngNMhLdtBo508hEoXhZZmtvo4