BTW, DOWNLOAD part of ExamsLabs MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1scCCW62RI2sQ5h7-rE0vBVG2L4eG9P5G
These formats are MLA-C01 web-based practice test software, desktop practice exam software, and AWS Certified Machine Learning Engineer - Associate (MLA-C01) PDF dumps files. All these three Amazon MLA-C01 exam questions formats are easy to use and compatible with all devices and the latest web browsers. Just choose the right AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam dumps format and start MLA-C01 exam questions preparation today.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
If you decide to buy our MLA-C01 study questions, you can get the chance that you will pass your MLA-C01 exam and get the certification successfully in a short time. For we have helped tens of thousands of our customers achieved their dreams. We believe you won't be the exception, so if you want to achieve your dream and become the excellent people in the near future, please buy our MLA-C01 Actual Exam, it will help you.
NEW QUESTION # 168
A data scientist is evaluating different binary classification models. A false positive result is 5 times more expensive (from a business perspective) than a false negative result.
The models should be evaluated based on the following criteria:
1) Must have a recall rate of at least 80%
2) Must have a false positive rate of 10% or less
3) Must minimize business costs
After creating each binary classification model, the data scientist generates the corresponding confusion matrix.
Which confusion matrix represents the model that satisfies the requirements?
Answer: A
Explanation:
The following calculations are required:
TP = True Positive
FP = False Positive
FN = False Negative
TN = True Negative
FN = False Negative
Recall = TP / (TP + FN)
False Positive Rate (FPR) = FP / (FP + TN)
Cost = 5 * FP + FN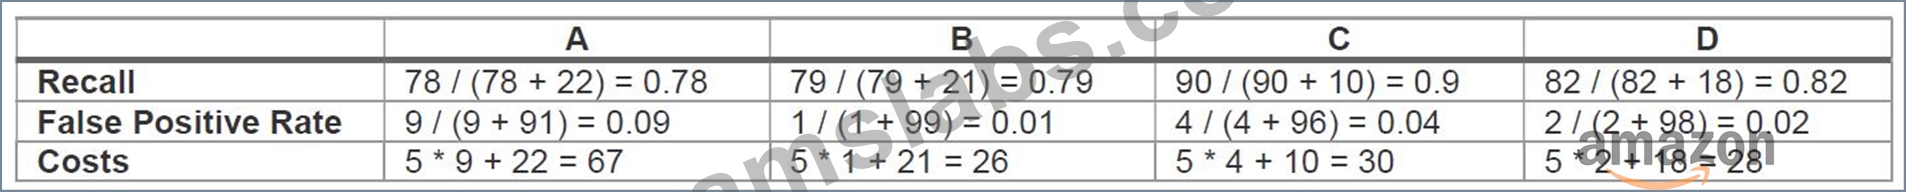
NEW QUESTION # 169
Case study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
The ML engineer needs to use an Amazon SageMaker built-in algorithm to train the model.
Which algorithm should the ML engineer use to meet this requirement?
Answer: C
Explanation:
Why Linear Learner?
* SageMaker'sLinear Learneralgorithm is well-suited for binary classification problems such as fraud detection. It handles class imbalance effectively by incorporating built-in options forweight balancing across classes.
* Linear Learner can capture patterns in the data while being computationally efficient.
Key Features of Linear Learner:
* Automatically weights minority and majority classes.
* Supports both classification and regression tasks.
* Handles interdependencies among features effectively through gradient optimization.
Steps to Implement:
* Use the SageMaker Python SDK to set up a training job with the Linear Learner algorithm.
* Configure the hyperparameters to enable balanced class weights.
* Train the model with the balanced dataset created using SageMaker Data Wrangler.
NEW QUESTION # 170
A company is building an enterprise AI platform. The company must catalog models for production, manage model versions, and associate metadata such as training metrics with models. The company needs to eliminate the burden of managing different versions of models.
Which solution will meet these requirements?
Answer: A
Explanation:
The correct answer is B. Use the Amazon SageMaker Model Registry to catalog the models. Create model groups for each model to manage the model versions and to maintain associated metadata.
The Amazon SageMaker Model Registry is a managed repository within SageMaker designed specifically for production-grade ML model lifecycle management. It allows organizations to catalog models, track multiple versions of a model, associate rich metadata, and manage deployment workflows in a scalable, controlled manner. Each model can belong to a model group, which acts as a container for all versions of that particular model. Versions can store training metrics, hyperparameters, model artifacts, and other key metadata, enabling reproducibility, auditing, and automated promotion between stages (e.g., Staging # Production).
Option A, while using the Model Registry, relies on manually tagging versions and creating key-value pairs to store metadata. This approach is error-prone, lacks structured versioning, and does not integrate with SageMaker's deployment pipelines.
Options C and D suggest using Amazon ECR repositories. While ECR can store containerized model artifacts, it is not designed for ML-specific metadata, versioning, or automated model stage transitions. Using ECR alone would require custom-built solutions for metadata management, auditing, and version tracking, adding unnecessary operational overhead.
By leveraging the Model Registry with model groups, organizations can automate promotions, apply approval workflows, and track lineage efficiently, fully aligning with AWS best practices for ML model development and production readiness. This ensures compliance, reproducibility, and reduces operational complexity in enterprise AI platforms.
Using the Model Registry and model groups is the standard AWS-recommended approach for enterprise-scale model cataloging and version control, enabling teams to focus on model improvement rather than infrastructure management.
NEW QUESTION # 171
An ML engineer needs to use an ML model to predict the price of apartments in a specific location.
Which metric should the ML engineer use to evaluate the model's performance?
Answer: D
Explanation:
When predicting continuous variables, such as apartment prices, it's essential to evaluate the model's performance using appropriate regression metrics. The Mean Absolute Error (MAE) is a widely used metric for this purpose.
Understanding Mean Absolute Error (MAE):
MAE measures the average magnitude of errors in a set of predictions, without considering their direction. It calculates the average absolute difference between predicted values and actual values, providing a straightforward interpretation of prediction accuracy.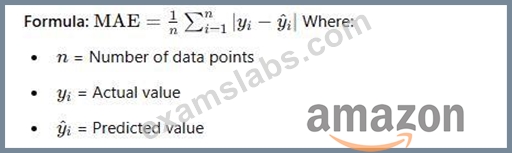
Advantages of MAE:
* Interpretability: MAE is expressed in the same units as the target variable, making it easy to understand.
* Robustness to Outliers: Unlike metrics that square the errors (e.g., Mean Squared Error), MAE does not disproportionately penalize larger errors, making it more robust to outliers.
Comparison with Other Metrics:
* Accuracy, AUC, F1 Score: These metrics are designed for classification tasks, where the goal is to predict discrete labels. They are not suitable for regression problems involving continuous target variables.
* Mean Squared Error (MSE): While MSE also measures prediction errors, it squares the differences, giving more weight to larger errors. This can be useful in certain contexts but may be sensitive to outliers.
Conclusion:
For evaluating the performance of a model predicting apartment prices-a continuous variable-MAE is an appropriate and effective metric. It provides a clear indication of the average prediction error in the same units as the target variable, facilitating straightforward interpretation and comparison.
References:
Regression Metrics - GeeksforGeeks
Evaluation Metrics for Your Regression Model - Analytics Vidhya
Regression Metrics for Machine Learning - Machine Learning Mastery
NEW QUESTION # 172
A customer call center uses Amazon Transcribe to convert hundreds of audio recordings of conversations between customers and support agents to text files. The call center wants to use the text files to train an ML model. To comply with industry regulations, the call center must remove customer names, addresses, and phone numbers from the training text files.
Which solution will meet these requirements with the LEAST development effort?
Answer: B
Explanation:
Option B is correct because AWS Glue provides a built-in Detect PII transform that can detect, mask, or remove personally identifiable information with minimal custom development. AWS documentation says the Detect PII transform can process predefined AWS-managed PII entity types and supports actions such as removing or masking values. The examples in AWS docs explicitly mention sensitive entities such as phone numbers and addresses , which directly match the problem statement.
The question specifically asks for the least development effort . That wording makes AWS Glue Detect PII the strongest answer because it is a native transformation capability rather than a custom code-heavy workflow. AWS also documents fine-grained sensitive data detection features that let you apply actions per entity type, improving usability and reducing the need to build custom parsing and redaction logic yourself.
This is much easier than creating Lambda-based transformation code or custom text-cleaning logic inside another ML preprocessing tool.
The other options are less suitable. Amazon Bedrock Guardrails is not the standard AWS service documented for bulk ETL-style redaction of training text files in this context. S3 Object Lambda would require more custom engineering to inspect and redact each object. SageMaker Data Wrangler custom transformation would also involve extra implementation work compared with using a purpose-built Glue transform. Because the call center already has text output and simply needs regulated fields like names, addresses, and phone numbers removed before training, the AWS-native low-effort solution is AWS Glue Detect PII . Therefore, the best verified answer is B .
NEW QUESTION # 173
......
There is a ton of AWS Certified Machine Learning Engineer - Associate (MLA-C01) prep material available on the internet. But the main thing to notice is their validity and reliability. Many applicants remain unsuccessful in locating the right AWS Certified Machine Learning Engineer - Associate (MLA-C01) practice test and lose their time and money.
MLA-C01 Reliable Test Preparation: https://www.examslabs.com/Amazon/AWS-Certified-Associate/best-MLA-C01-exam-dumps.html
2026 Latest ExamsLabs MLA-C01 PDF Dumps and MLA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1scCCW62RI2sQ5h7-rE0vBVG2L4eG9P5G