Confronting a tie-up during your review of the exam? Feeling anxious and confused to choose the perfect Databricks-Certified-Professional-Data-Engineer Latest Dumps to pass it smoothly? We understand your situation of susceptibility about the exam, and our Databricks-Certified-Professional-Data-Engineer test guide can offer timely help on your issues right here right now. Without tawdry points of knowledge to remember, our experts systematize all knowledge for your reference. You can download our free demos and get to know synoptic outline before buying.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Available Languages: | English, Korean, Portuguese (Brazil), Japanese |
| Exam Price: | USD 200 |
| Exam Duration: | 120 minutes |
| Real Exam Qty: | 59 |
| Certificate Validity Period: | 2 years |
| Exam Format: | Multiple Choice |
| Related Certifications: | Databricks Certified Associate Data Engineer |
| Passing Score: | 70% |
| Recommended Training: | Databricks Data Engineer Professional Training |
| Exam Registration: | Databricks Official Certification Registration |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored or onsite test center |
| Pre Condition: | No mandatory prerequisites; 1+ year hands-on experience and related training highly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-engineer-professional |
>> Databricks-Certified-Professional-Data-Engineer Study Dumps <<
What we provide for you is the latest and comprehensive Databricks-Certified-Professional-Data-Engineer exam dumps, the safest purchase guarantee and the immediate update of Databricks-Certified-Professional-Data-Engineer exam software. Free demo download can make you be rest assured to buy; one-year free update of Databricks-Certified-Professional-Data-Engineer Exam software after payment can assure you during your preparation for the exam. What's more, what make you be rest assured most is that we develop the exam software which will help more candidates get Databricks-Certified-Professional-Data-Engineer exam certification.
Databricks Certified Professional Data Engineer Exam is an online exam that can be taken from anywhere in the world. Databricks-Certified-Professional-Data-Engineer exam is timed and consists of multiple-choice questions and hands-on tasks that require the candidate to demonstrate their ability to perform specific tasks using Databricks. Databricks-Certified-Professional-Data-Engineer Exam is designed to be challenging and requires a thorough understanding of Databricks data engineering concepts and techniques.
NEW QUESTION # 169
A Delta Lake table representing metadata about content posts from users has the following schema:
user_id LONG
post_text STRING
post_id STRING
longitude FLOAT
latitude FLOAT
post_time TIMESTAMP
date DATE
Based on the above schema, which column is a good candidate for partitioning the Delta Table?
Answer: D
Explanation:
Partitioning a Delta Lake table is a strategy used to improve query performance by dividing the table into distinct segments based on the values of a specific column. This approach allows queries to scan only the relevant partitions, thereby reducing the amount of data read and enhancing performance.
Considerations for Choosing a Partition Column:
Cardinality: Columns with high cardinality (i.e., a large number of unique values) are generally poor choices for partitioning. High cardinality can lead to a large number of small partitions, which can degrade performance.
Query Patterns: The partition column should align with common query filters. If queries frequently filter data based on a particular column, partitioning by that column can be beneficial.
Partition Size: Each partition should ideally contain at least 1 GB of data. This ensures that partitions are neither too small (leading to too many partitions) nor too large (negating the benefits of partitioning).
Evaluation of Columns:
date:
Cardinality: Typically low, especially if data spans over days, months, or years.
Query Patterns: Many analytical queries filter data based on date ranges.
Partition Size: Likely to meet the 1 GB threshold per partition, depending on data volume.
user_id:
Cardinality: High, as each user has a unique ID.
Query Patterns: While some queries might filter by user_id, the high cardinality makes it unsuitable for partitioning.
Partition Size: Partitions could be too small, leading to inefficiencies.
post_id:
Cardinality: Extremely high, with each post having a unique ID.
Query Patterns: Unlikely to be used for filtering large datasets.
Partition Size: Each partition would be very small, resulting in a large number of partitions.
post_time:
Cardinality: High, especially if it includes exact timestamps.
Query Patterns: Queries might filter by time, but the high cardinality poses challenges.
Partition Size: Similar to user_id, partitions could be too small.
Conclusion:
Given the considerations, the date column is the most suitable candidate for partitioning. It has low cardinality, aligns with common query patterns, and is likely to result in appropriately sized partitions.
Reference:
Delta Lake Best Practices
Partitioning in Delta Lake
NEW QUESTION # 170
A data team ' s Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.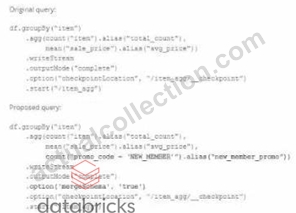
Which step must also be completed to put the proposed query into production?
Answer: A
Explanation:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
:
Databricks documentation on Structured Streaming: https://docs.databricks.com/spark/latest/structured- streaming/index.html Databricks documentation on streaming checkpoints: https://docs.databricks.com/spark/latest/structured- streaming/production.html#checkpointing
NEW QUESTION # 171
The data engineer team has been tasked with configured connections to an external database that does not have a supported native connector with Databricks. The external database already has data security configured by group membership. These groups map directly to user group already created in Databricks that represent various teams within the company.
A new login credential has been created for each group in the external database. The Databricks Utilities Secrets module will be used to make these credentials available to Databricks users.
Assuming that all the credentials are configured correctly on the external database and group membership is properly configured on Databricks, which statement describes how teams can be granted the minimum necessary access to using these credentials?
Answer: A
Explanation:
In Databricks, using the Secrets module allows for secure management of sensitive information such as database credentials. Granting 'Read' permissions on a secret key that maps to database credentials for a specific team ensures that only members of that team can access these credentials. This approach aligns with the principle of least privilege, granting users the minimum level of access required to perform their jobs, thus enhancing security.
Reference:
Databricks Documentation on Secret Management: Secrets
NEW QUESTION # 172
You are asked to setup an AUTO LOADER to process the incoming data, this data arrives in JSON format and get dropped into cloud object storage and you are required to process the data as soon as it arrives in cloud storage, which of the following statements is correct
Answer: E
Explanation:
Explanation
Auto Loader supports two modes when ingesting new files from cloud object storage Directory listing: Auto Loader identifies new files by listing the input directory, and uses a directory polling approach.
File notification: Auto Loader can automatically set up a notification service and queue service that subscribe to file events from the input directory.
Diagram Description automatically generated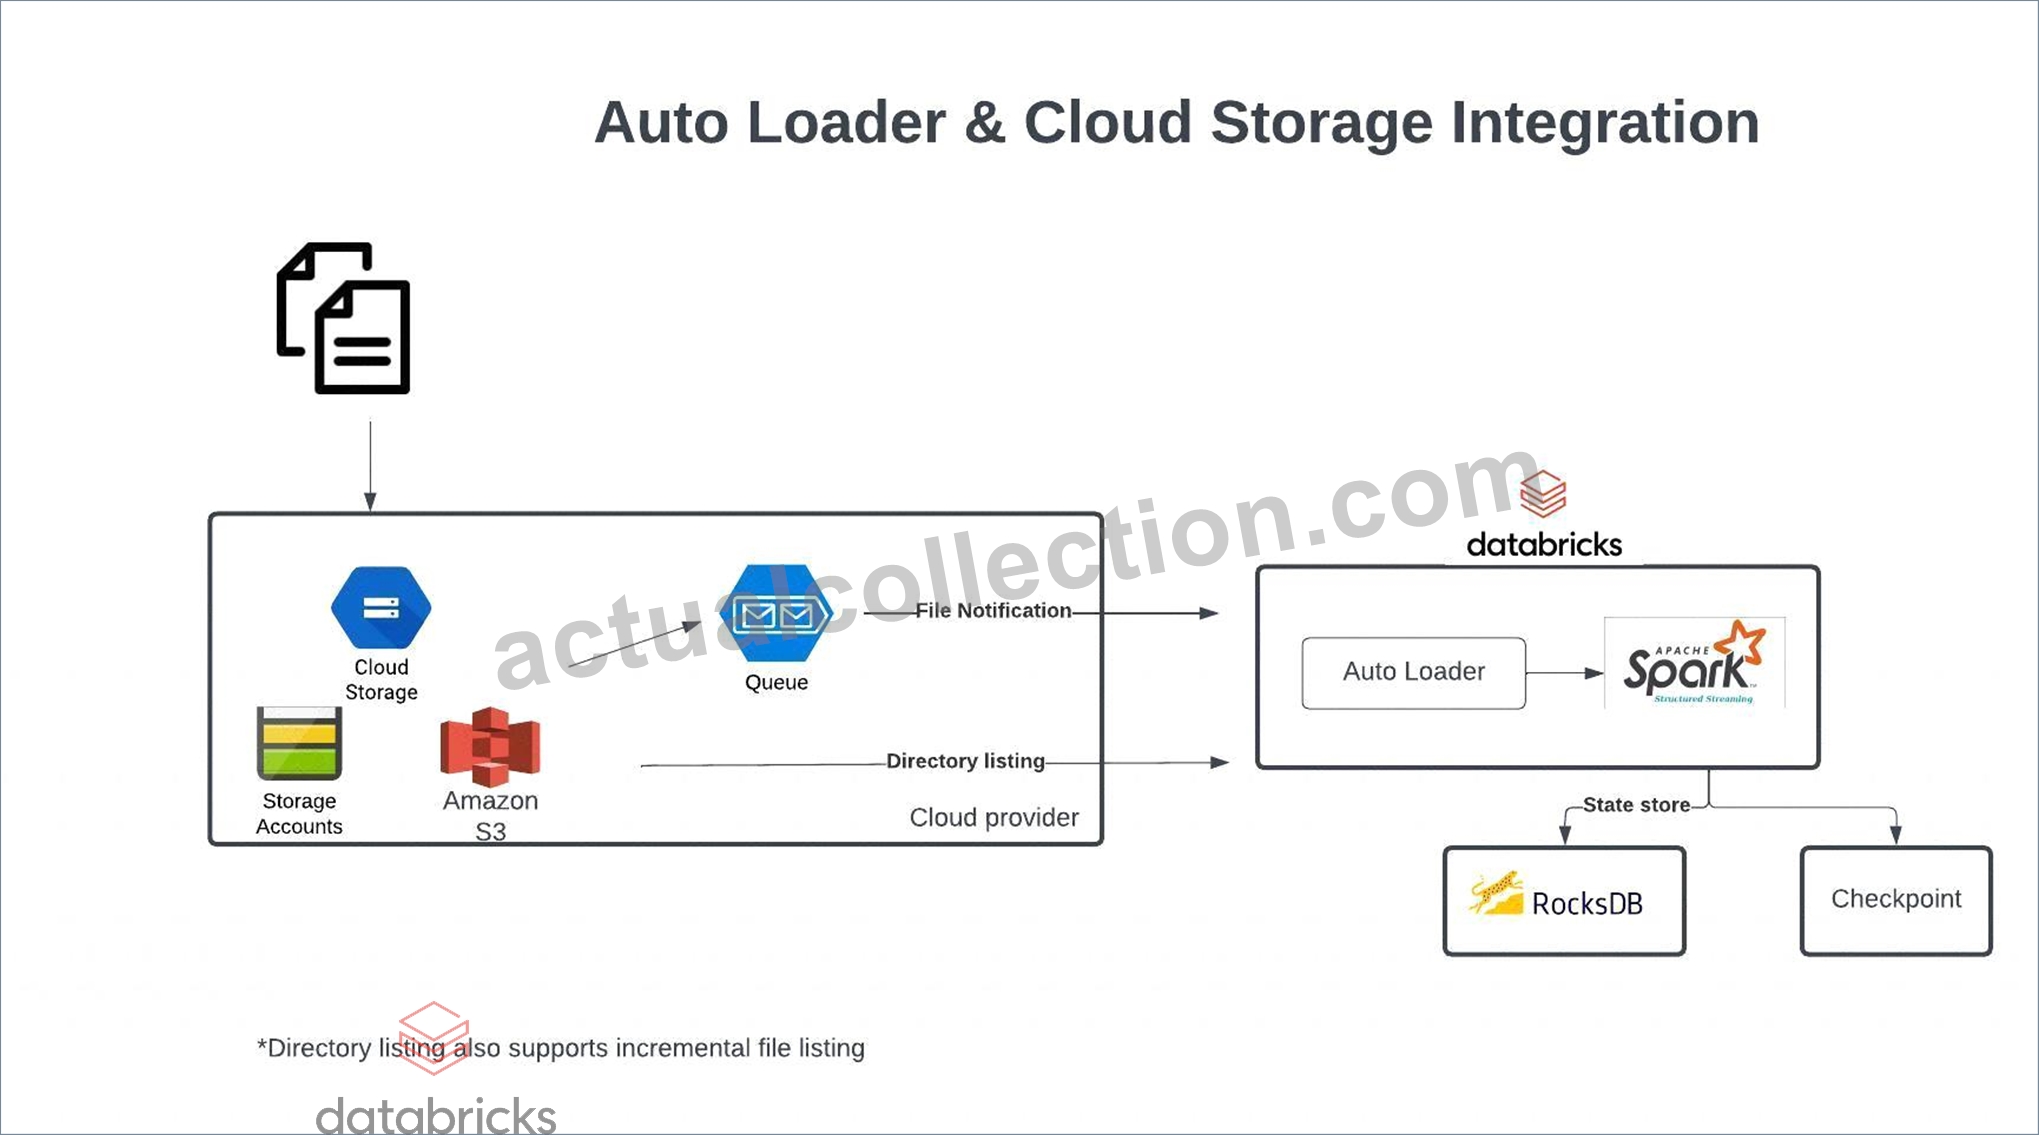
File notification is more efficient and can be used to process the data in real-time as data arrives in cloud object storage.
Choosing between file notification and directory listing modes | Databricks on AWS
NEW QUESTION # 173
How do you handle failures gracefully when writing code in Pyspark, fill in the blanks to complete the below statement
1._____
2.
3. Spark.read.table("table_name").select("column").write.mode("append").SaveAsTable("new_table_name")
4.
5._____
6.
7. print(f"query failed")
Answer: D
Explanation:
Explanation
The answer is try: and except:
NEW QUESTION # 174
......
Pass Databricks-Certified-Professional-Data-Engineer Exam: https://www.actualcollection.com/Databricks-Certified-Professional-Data-Engineer-exam-questions.html