BTW, DOWNLOAD part of PassLeaderVCE DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1buPrAkjwdxwzxYvzcbwmU4YdxKBIb2ex
Our evaluation system for DP-750 test material is smart and very powerful. First of all, our researchers have made great efforts to ensure that the data scoring system of our DP-750 test questions can stand the test of practicality. Once you have completed your study tasks and submitted your training results, the evaluation system will begin to quickly and accurately perform statistical assessments of your marks on the DP-750 Exam Torrent. If you encounter something you do not understand, in the process of learning our DP-750 exam torrent, you can ask our staff. We provide you with 24-hour online services to help you solve the problem. Therefore we can ensure that we will provide you with efficient services.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Topic 2: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Topic 3: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Topic 4: Prepare and process data | 30-35% | - Data transformation and modeling
|
It is acknowledged that there are numerous DP-750 learning questions for candidates for the exam, however, it is impossible for you to summarize all of the key points in so many materials by yourself. But since you have clicked into this website for DP-750 practice materials you need not to worry about that at all because our company is especially here for you to solve this problem. We have a lot of regular customers for a long-term cooperation now since they have understood how useful and effective our DP-750 Actual Exam is. So will you!
NEW QUESTION # 79
Drag and Drop Question
You have an Azure Databricks workspace named Workspace1 that is attached to a Unity Catalog metastore named metastore1.
You need to register an Azure Storage account named account1 that has a hierarchical namespace enabled as an external location. The external location must use a managed identity to authenticate to account1 and the solution must follow the principle of least privilege.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.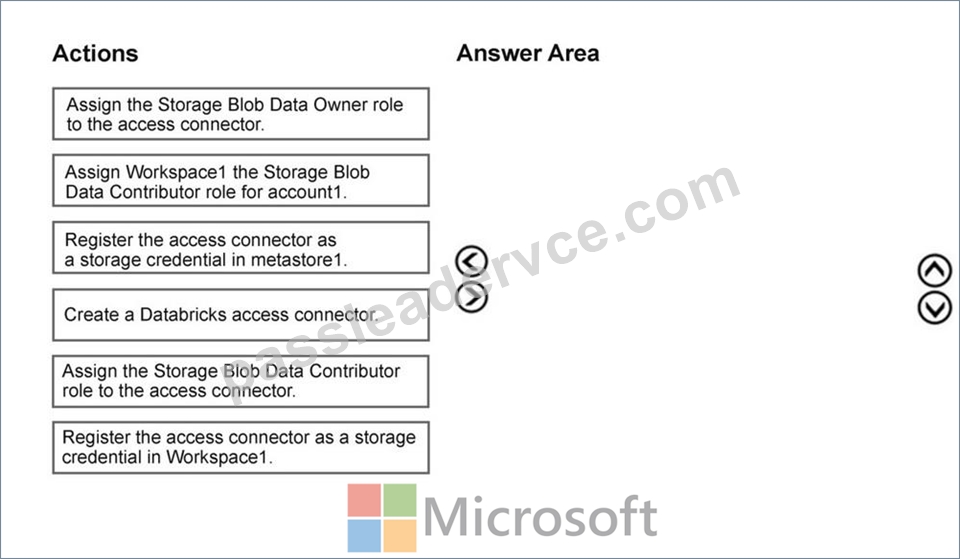
Answer:
Explanation: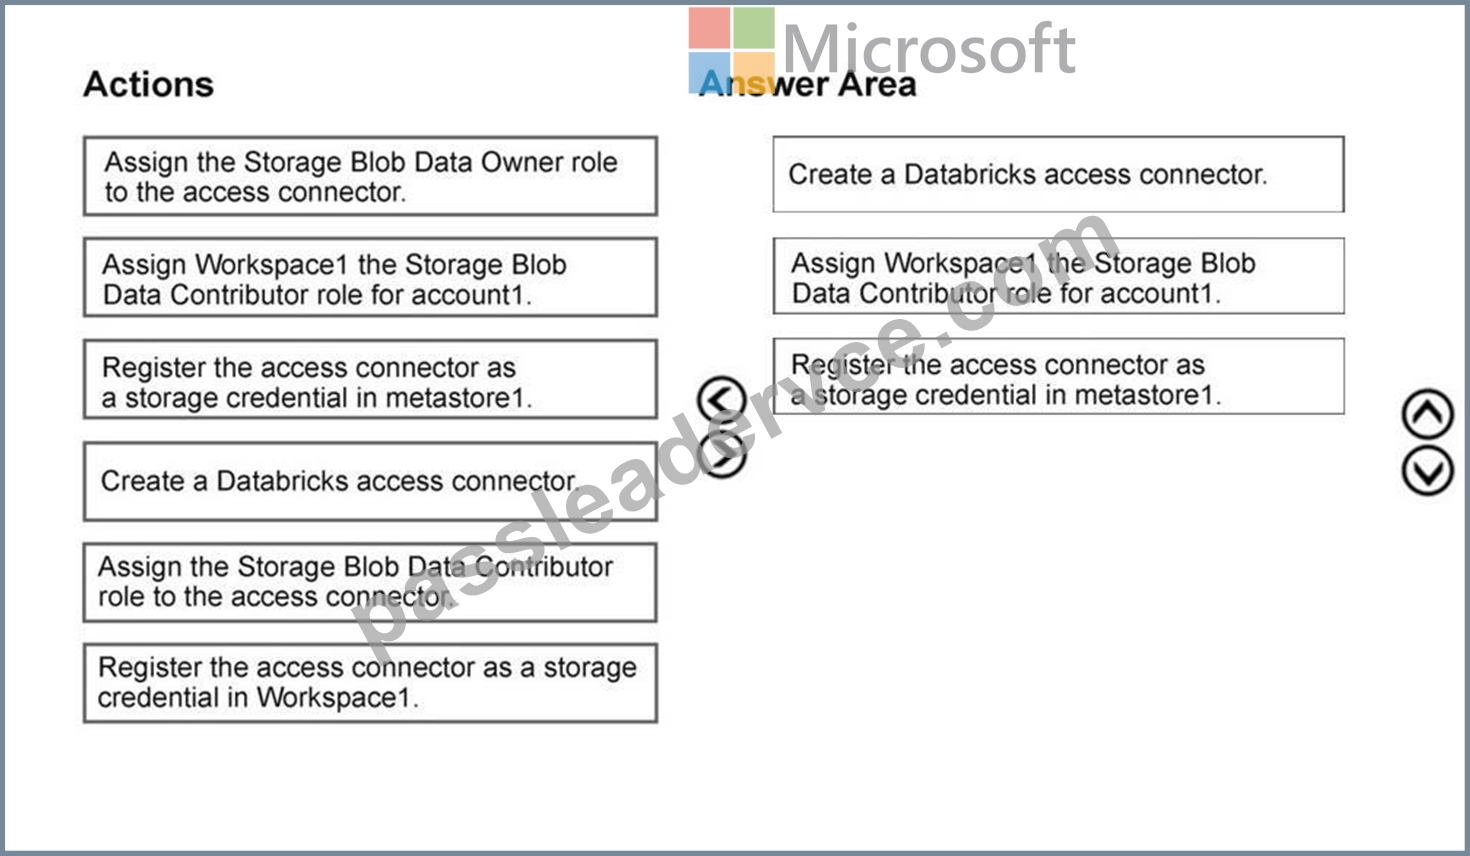
NEW QUESTION # 80
You need to develop the task logic for a new job in Lakeflow Jobs that processes telemetry data.
Each task must contain only the appropriate logic for its step in the pipeline. The solution must support the planned changes and meet the data ingestion and processing requirements.
What should you do?
Answer: B
Explanation:
The correct answer is D. Breaking the pipeline into separate tasks for ingestion, cleansing, and curation is the foundation of well-designed Lakeflow Jobs pipelines. Each task should own one responsibility - when a task does too much, debugging a failure becomes a hunt through unrelated code, and retry logic becomes expensive because you re-execute work that already succeeded.
Contoso ' s planned changes explicitly call for ' a clear execution order and dependencies ' and ' orchestrate multi-step ingestion and transformation workflows. ' Separate tasks map directly to those goals: Lakeflow Jobs tracks each task ' s status independently, so if cleansing fails, ingestion doesn ' t re-run.
Option A bundles everything into one notebook, which means a curation bug forces a full re-ingestion. Option B copies logic three times - any future change must be applied in triplicate, which is a maintenance hazard.
Option C forces everything through SQL MERGE, which is the wrong tool for raw-event ingestion and doesn
' t address cleansing or schema drift.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/
NEW QUESTION # 81
You have an Azure Databricks workspace
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically. You need to configure compute for the pipeline. The solution must minimize operational costs and effort. What should you use?
Answer: C
Explanation:
The correct answer is C - a job cluster that uses autoscaling.
Job clusters (also called pipeline clusters in the SDP context) are created exclusively for a pipeline run and terminated when the pipeline stops. You pay only for what the pipeline uses, and there's no idle cost between runs. Autoscaling on a job cluster lets the pipeline expand during heavy processing and contract during lighter stages - the combination of on-demand lifecycle and elastic scaling gives the lowest operational cost.
Option A (all-purpose cluster) runs at a higher DBU rate and persists beyond the pipeline's lifecycle, meaning you're paying for it even when the pipeline isn't running. Option B (SQL warehouse) is optimised for interactive BI and ad-hoc queries, not for the batch/streaming workloads SDP pipelines run. Option D (single- node all-purpose) has no scaling, runs at the all-purpose DBU rate, and is capped at one node - unsuitable for any production pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/configure-pipeline
NEW QUESTION # 82
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Sales_orders. Sales.orders stores historical sales data.
You receive a daily CSV file daily that contains new sales records only. The file does NOT contain updates to existing rows You need to load the daily data into Sales.orders. The solution must meet the following requirements:
* Preserve the existing data.
* Add only the new records.
* Minimize processing effort.
Which command should include in the loading strategy?
Answer: C
Explanation:
The correct answer is C - INSERT INTO.
The scenario is clear: the daily file contains only new records, no updates to existing rows. INSERT INTO is the right command because it appends the new rows to Sales.orders without touching the existing historical data. All three requirements are satisfied: existing data is preserved, only new records are added, and the loading strategy is as simple as it gets.
Option A (INSERT OVERWRITE) replaces the existing data with just today's file. After the first day you'd have only 24 hours of history - all prior sales records would be gone. Option B (UPDATE) modifies specific existing rows based on a match condition; it doesn't load new records at all.
Because the source file is guaranteed to contain only new records and no duplicates of existing rows, a full MERGE is unnecessary overhead. Simple INSERT INTO is both correct and the most efficient approach.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-insert-into
NEW QUESTION # 83
Drag and Drop Question
You have an Azure Databricks workspace that contains an all-purpose compute cluster named Cluster1. Cluser1 is used for interactive development.
You need to configure Cluster1 to meet the following requirements:
- Automatically add and remove worker nodes based on workload demand.
- Automatically shut down when the cluster has been idle for a specific period.
What should you configure for each requirement? To answer, drag the appropriate options to the correct requirements. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.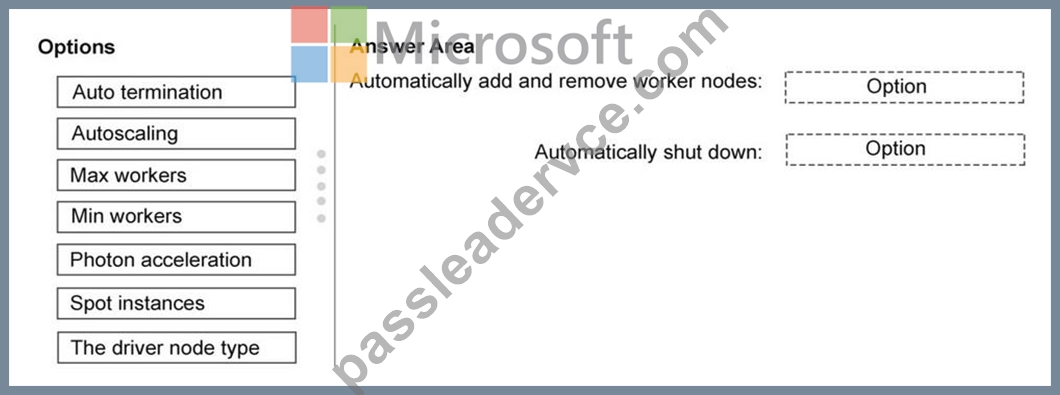
Answer:
Explanation: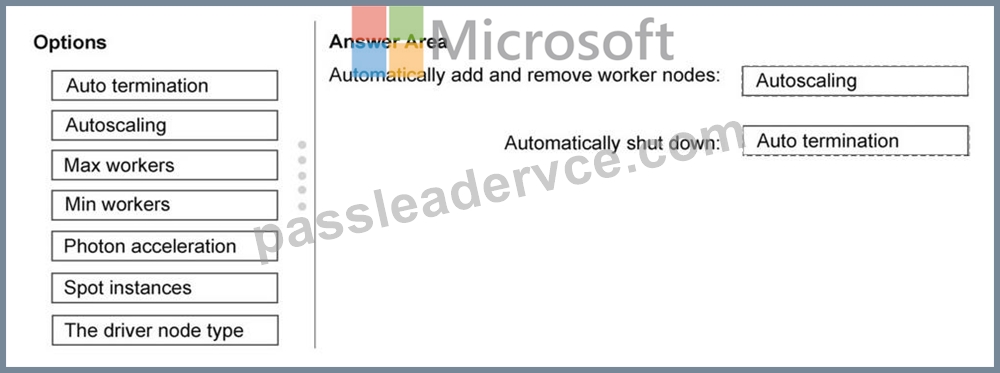
NEW QUESTION # 84
......
The content of our DP-750 practice engine is based on real exam by whittling down superfluous knowledge without delinquent mistakes rather than dropping out of reality. Being subjected to harsh tests of market, our DP-750 exam questions are highly the manifestation of responsibility carrying out the tenets of customer oriented. And our DP-750 Study Materials are warmly praised and welcomed by the customers all over the world.
Valid Test DP-750 Bootcamp: https://www.passleadervce.com/Microsoft-Certified-Fabric-Data-Engineer-Associate/reliable-DP-750-exam-learning-guide.html
2026 Latest PassLeaderVCE DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1buPrAkjwdxwzxYvzcbwmU4YdxKBIb2ex