P.S. Free & New DEA-C02 dumps are available on Google Drive shared by Prep4SureReview: https://drive.google.com/open?id=19YlcCcPgVpdgJ-y6CN7PHNCqiUA22K_D
Different from general education training software, our DEA-C02 exam questions just need students to spend 20 to 30 hours practicing on the platform which provides simulation problems, can let them have the confidence to pass the DEA-C02 exam, so little time great convenience for some workers, how efficiency it is. Time is money, in today's increasingly pay attention to efficiency, we should use time in the right place, with low time get high scores in return, the DEA-C02 Latest Exam torrents are very good to do this.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion and Sourcing | 20-25% | - Ingest data from various sources: data lakes, APIs, on-premises systems, cloud storage - Handle different data formats: structured, semi-structured, unstructured - Design and implement continuous and batch ingestion pipelines - Use Snowflake ingestion methods: Snowpipe, COPY INTO, External Functions |
| Data Governance, Security, and Compliance | 10-15% | - Enforce data quality and governance standards - Manage data lineage, cataloging, and compliance policies - Implement access control: RBAC, authentication, authorization - Apply data protection: encryption, masking, row-level security |
| Data Pipeline Architecture and Design | 15-20% | - Build end-to-end near real-time streaming solutions - Integrate with external tools and platforms: orchestration, BI, ML - Design scalable, reliable, and maintainable data pipelines - Apply design patterns for data engineering workloads |
| Performance Optimization and Compute Management | 15-20% | - Use search optimization and query acceleration services - Manage virtual warehouses: sizing, scaling, multi-cluster, cost control - Optimize query performance: clustering, partitioning, materialized views - Monitor and tune workloads and resource utilization |
| Data Sharing and Collaboration | 5-10% | - Design multi-tenant and cross-account data architectures - Implement secure data sharing and data exchanges - Work with Snowflake Data Marketplace and external data providers |
| Data Transformation and Processing | 20-25% | - Process semi-structured data: JSON, Avro, Parquet, ORC - Implement ELT/ETL workflows using Streams, Tasks, and Dynamic Tables - Manage data quality, validation, and deduplication - Transform and enrich data using SQL, JavaScript, Python, and Snowpark |
>> Test DEA-C02 Simulator Fee <<
With many advantages such as immediate download, simulation before the real test as well as high degree of privacy, our DEA-C02 actual exam survives all the ordeals throughout its development and remains one of the best choices for those in preparation for exams. Many people have gained good grades after using our DEA-C02 real test, so you will also enjoy the good results. Don’t hesitate any more. Time and tide wait for no man. Now that using our DEA-C02 practice materials have become an irresistible trend, why don’t you accept it with pleasure?
NEW QUESTION # 198
You have a 'WEB EVENTS' table that stores user activity on a website. It includes columns like 'USER ID, 'EVENT TYPE , EVENT TIMESTAMP, and 'PAGE URL'. You need to create a materialized view that calculates the number of distinct users visiting each page daily. You are also tasked with minimizing the impact on the underlying 'WEB EVENTS' table during materialized view refreshes, as other critical processes rely on it. Which of the following strategies would provide the MOST efficient solution, considering both performance and concurrency?
Answer: A
Explanation:
Option D provides the most efficient solution. Incremental refreshes are designed to efficiently update the materialized view with only the changes from the base table, minimizing the impact on the 'WEB_EVENTS' table. Options A, B and E might lock the table for longer periods. Option C is not a valid option in Snowflake. Option E is not efficient since it involves truncating and reloading the materialized view, consuming unnecessary resources and being potentially slow.
NEW QUESTION # 199
You are designing a data ingestion process that involves loading data from an external stage. The data is partitioned into multiple files based on date. The stage is configured to point to the root directory of the partitioned dat a. You want to efficiently load only the data for a specific date (e.g., '2023-01-15') using the 'COPY' command. Assume your stage name is 'my _ stage' , your table is 'my_table', your date column is named 'event_date', and the files in the stage are named in the format 'data YYYY-MM-DD.csv'. Which of the following options allows you to selectively load the data for the specific date? (Select ALL that apply)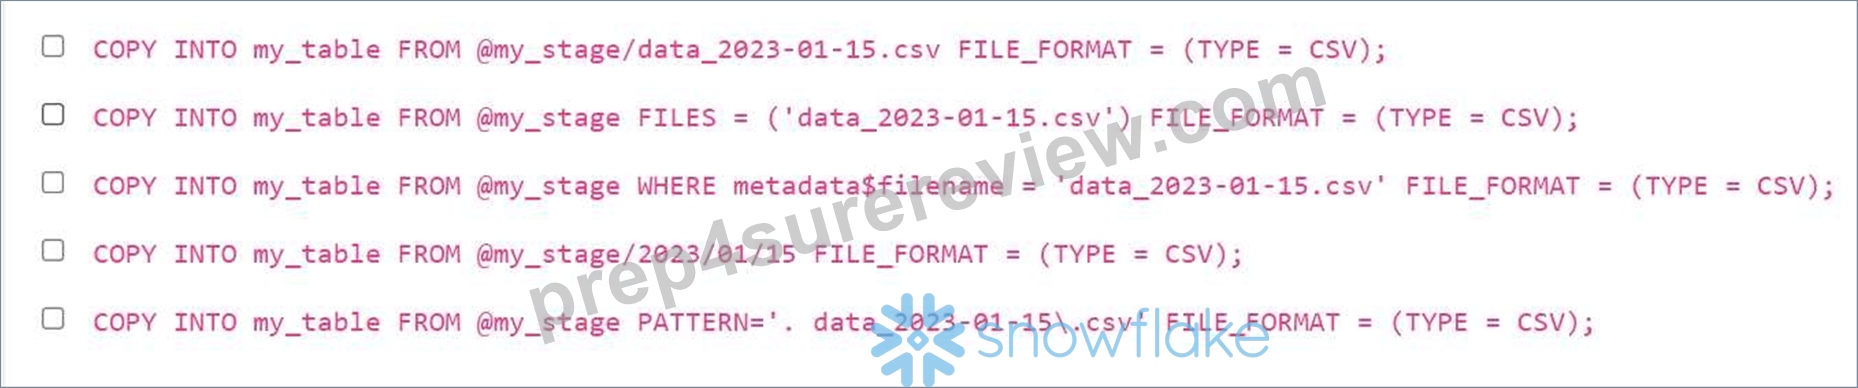
Answer: C,D,E
Explanation:
Options A, B and E are valid ways to selectively load the data. Option A: specifies the full path to the desired file directly in the FROM clause. Option B: uses the 'FILES' parameter to explicitly list the file to be loaded. Option E: uses PATTERN regular expression to filter the files. Option C is incorrect because the 'WHERE clause is invalid in 'COPY' command. Option D is wrong as it's not a correct directory structure, and also invalid as it is trying to specify folders with year, month, day structure.
NEW QUESTION # 200
You need to unload data from a Snowflake table named 'CUSTOMER DATA to an AWS S3 bucket The data should be unloaded in Parquet format, partitioned by the 'CUSTOMER REGION' column, and automatically compressed with GZIP. Furthermore, you only want to unload customers whose 'REGISTRATION DATE is after '2023-01-01'. Which of the following 'COPY INTO' statement correctly achieves this?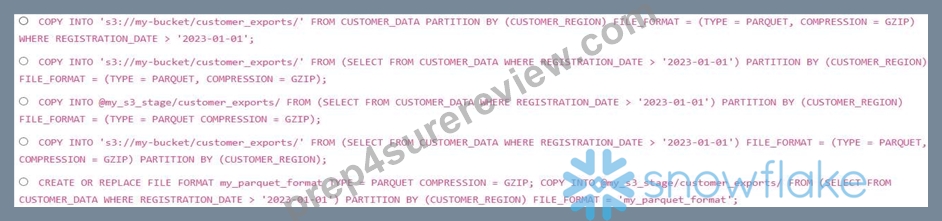
Answer: D
Explanation:
The correct 'COPY INTO' statement requires using a named stage and a named file format. A subquery is used to filter the data based on the 'REGISTRATION_DATE. The 'PARTITION BY clause is used to partition the data by 'CUSTOMER REGION'. You must create a FILE FORMAT seperately and refer to it later. Other solutions have syntax errors, incorrect stage references, or incorrect ordering of clauses. Option 'A' doesn't use a stage nor it allows for a where condition. Option 'B' doesn't work since 'TYPE' and 'COMPRESSIONS are properties of a file format, not direct arguments to FILE_FORMAT. 'C' includes the 'TYPE and 'COMPRESSION' inline when this is not allowed. 'D' contains the same error with FILE FORMAT as 'C' and 'B' and does not use a stage.
NEW QUESTION # 201
A data engineer observes that a daily data transformation pipeline in Snowflake, which processes data from external stage 's3://my- bucket/raw_dataP , is consistently taking longer to complete. Upon investigation, the engineer finds that the COPY INTO statement is the bottleneck. The COPY INTO statement is as follows: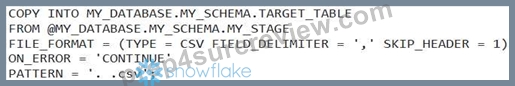
Which of the following could be the root cause of the performance degradation and how would you address them? Select two options.
Answer: C,E
Explanation:
Option B is correct because a large number of small files can significantly degrade COPY INTO performance. Snowflake performs best with fewer, larger files. Option E is also correct because an overly broad pattern can force Snowflake to evaluate unnecessary files. Refining the pattern and leveraging partition pruning can improve performance. Option A is incorrect as 'ON_ERROR = CONTINUE' is not the primary cause for performance issues, it just handles the error instead of failing the job. Option C might help in some cases but its not the primary cause, more focusing on the data loading part. Option D is incorrect as Snowflake does not fully automize COPY INTO operations and some level of tuning might be needed.
NEW QUESTION # 202
You have configured a Snowpipe to load data from an AWS S3 bucket into a Snowflake table. The data in S3 is updated frequently. You've noticed that despite the Snowpipe being active and the S3 event notifications being configured correctly, some newly added files are not being picked up by the Snowpipe. You run 'SYSTEM$PIPE and see the 'executionstate' is 'RUNNING' but the 'pendingFileCount' remains at O, even after new files are placed in the S3 bucket. Choose all of the reasons that could explain the observations.
Answer: A,B,E
Explanation:
The problem states that the snowpipe is active, but 'pendingFileCount' remains zero. This means that the events are not making its way to snowpipe. Insufficient permissions (A) on the IAM role will prevent Snowflake from accessing the files. Incorrect event notification settings (B) would stop events from being sent to the queue/topic. Mismatched file format will not generate any events, and will cause files to be skipped. Incorrect message retension period may result in loss of messages before snowpipe could process them, hence can be the root cause. (C) is incorrect as it does not impact picking up of event notifications. Warehouse size mainly affects processing data and not the notification retrieval.
NEW QUESTION # 203
......
Our DEA-C02 learning materials provide multiple functions and considerate services to help the learners have no inconveniences to use our product. We guarantee to the clients if only they buy our DEA-C02 study materials and learn patiently for some time they will be sure to pass the DEA-C02 test with few failure odds. The price of our product is among the range which you can afford and after you use our study materials you will certainly feel that the value of the product far exceed the amount of the money you pay. Choosing our DEA-C02 Study Guide equals choosing the success and the perfect service.
Exam DEA-C02 Voucher: https://www.prep4surereview.com/DEA-C02-latest-braindumps.html
2026 Latest Prep4SureReview DEA-C02 PDF Dumps and DEA-C02 Exam Engine Free Share: https://drive.google.com/open?id=19YlcCcPgVpdgJ-y6CN7PHNCqiUA22K_D