BONUS!!! Download part of BraindumpsIT DP-600 dumps for free: https://drive.google.com/open?id=1olVf3NHtG5uoty2Xd84koF82PcrlSmG4
The customizable mock tests make an image of a real-based Implementing Analytics Solutions Using Microsoft Fabric (DP-600) exam which is helpful for you to overcome the pressure of taking the final examination. Customers of BraindumpsIT can take multiple Implementing Analytics Solutions Using Microsoft Fabric (DP-600) practice tests and improve their preparation to achieve the DP-600 Certification. You can even access your previously given tests from the history, which allows you to be careful while giving the mock test next time and prepare for Implementing Analytics Solutions Using Microsoft Fabric (DP-600) certification in a better way.
| Section | Weight | Objectives |
|---|---|---|
| Implement and manage semantic models | 25–30 | - Design and build semantic models
|
| Prepare data for analytics | 45–50 | - Ingest and load data
|
| Maintain a data analytics solution | 25–30 | - Implement security and governance
|
>> DP-600 Latest Exam Price <<
BraindumpsIT will be with you, and make sure you can be successful. No matter how big your IT dream it is, our BraindumpsIT will help you to make it come true step by step. Because BraindumpsIT's DP-600 exam certification training material is worked out by senior IT specialist team through their own exploration and continuous practice. If you still have some hesitation, you can download DP-600 Dumps PDF free demo and answers on probation on BraindumpsIT websites. I believe that it won't let you down.
NEW QUESTION # 30
Case Study 2 - Litware, Inc
Overview
Litware, Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
Fabric Environment
Litware has been using a Microsoft Power BI tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Available Data
Litware has data that must be analyzed as shown in the following table.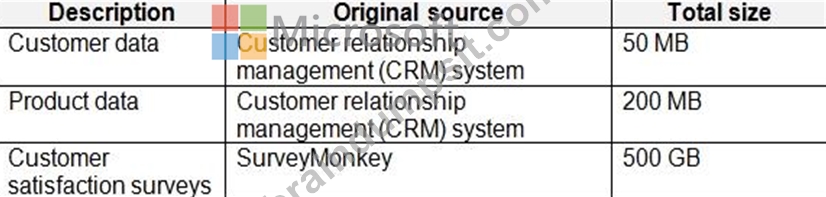
The Product data contains a single table and the following columns.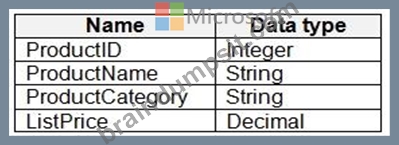
The customer satisfaction data contains the following tables:
- Survey
- Question
- Response
For each survey submitted, the following occurs:
- One row is added to the Survey table.
- One row is added to the Response table for each question in the survey.
- The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Requirements
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Liware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity The following three workspaces will be created:
- AnalyticsPOC: Will contain the data store, semantic models, reports pipelines, dataflow, and notebooks used to populate the data store
- DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate OneLake
- DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
- A data store (type to be decided)
- A custom semantic model
- A default semantic model
Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest, transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
- Read access by using T-SQL or Python
- Semi-structured and unstructured data
- Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SOL. queries and in the default semantic model. The following logic must be used:
- List prices that are less than or equal to 50 are in the low pricing group.
- List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
- List prices that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC.
Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
- Fabric administrators will be the workspace administrators.
- The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
- The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
- The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook
- The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power BI reports by using the semantic models created by the analytics engineers.
- The date dimension must be available to all users of the data store.
- The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
FabricAdmins: Fabric administrators
- AnalyticsTeam: All the members of the analytics team
- DataAnalysts: The data analysts on the analytics team
- DataScientists: The data scientists on the analytics team
- DataEngineers: The data engineers on the analytics team
- AnalyticsEngineers: The analytics engineers on the analytics team
Report Requirements
The data analysts must create a customer satisfaction report that meets the following requirements:
- Enables a user to select a product to filter customer survey responses to only those who have purchased that product.
- Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected dat.
- Shows data as soon as the data is updated in the data store.
- Ensures that the report and the semantic model only contain data from the current and previous year.
- Ensures that the report respects any table-level security specified in the source data store.
- Minimizes the execution time of report queries.
What should you recommend using to ingest the customer data into the data store in the AnalyticsPOC workspace?
Answer: C
Explanation:
Even though the text reads "Data will be loaded without transformation in one area of the AnalyticsPOC data store": in general, dataflows are used when data transformations are involved after ingestion. As suggested by user BHARAT, the Copy Activity should be the optimal solution.
NEW QUESTION # 31
You have a Fabric tenant that contains a warehouse named Warehouse1. Warehouse1 contains a fact table named FactSales that has one billion rows. You run the following T-SQL statement.
CREATE TABLE test.FactSales AS CLONE OF Dbo.FactSales;
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 32
You have a Fabric tenant that contains a warehouse named DW1 and a lakehouse named LH1. DW1 contains a table named Sales.Product. LH1 contains a table named Sales.Orders.
You plan to schedule an automated process that will create a new point-in-time (PIT) table named Sales.
ProductOrder in DW1. Sales.ProductOrder will be built by using the results of a query that will join Sales.
Product and Sales.Orders.
You need to ensure that the types of columns in Sales. ProductOrder match the column types in the source tables. The solution must minimize the number of operations required to create the new table.
Which operation should you use?
Answer: A
NEW QUESTION # 33
You have a Microsoft Power Bl project that contains a file named definition.pbir. definition.pbir contains the following JSON.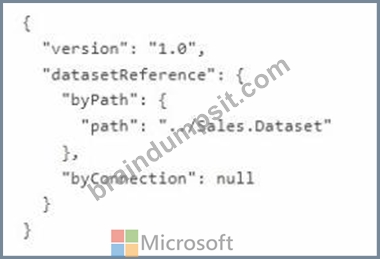
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.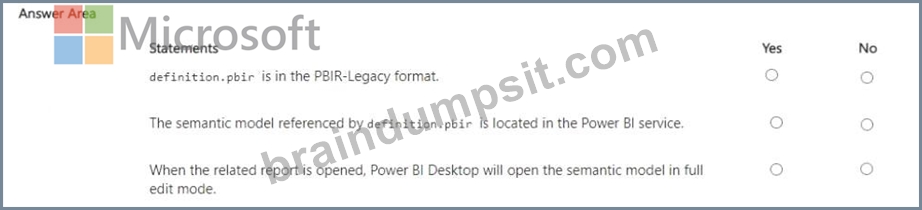
Answer:
Explanation: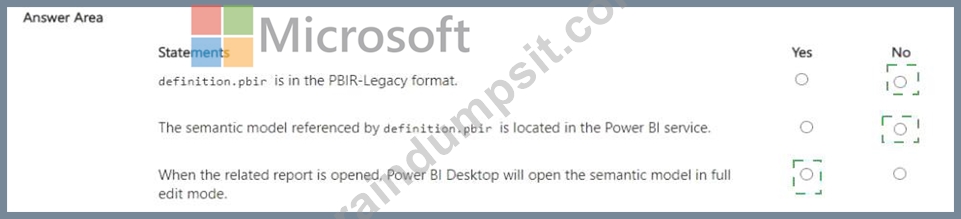
Explanation: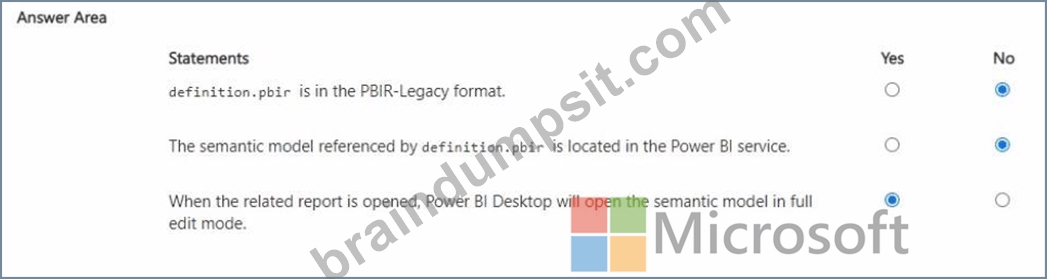
NEW QUESTION # 34
You have a Fabric tenant that contains a semantic model named Model1. Model1 uses Import mode. Model1 contains a table named Orders. Orders has 100 million rows and the following fields.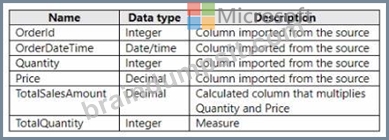
You need to reduce the memory used by Model! and the time it takes to refresh the model. Which two actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct answer is worth one point.
Answer: A,C
Explanation:
To reduce memory usage and refresh time, splitting the OrderDateTime into separate date and time columns (A) can help optimize the model because date/time data types can be more memory-intensive than separate date and time columns. Moreover, replacing TotalSalesAmount with a measure (D) instead of a calculated column ensures that the calculation is performed at query time, which can reduce the size of the model as the value is not stored but calculated on the fly. References = The best practices for optimizing Power BI models are detailed in the Power BI documentation, which recommends using measures for calculations that don't need to be stored and adjusting data types to improve performance.
NEW QUESTION # 35
......
With the development of economic globalization, your competitors have expanded to a global scale. Obtaining an international DP-600 certification should be your basic configuration. What I want to tell you is that for DP-600 Preparation materials, this is a very simple matter. And as we can claim that as long as you study with our DP-600 learning guide for 20 to 30 hours, then you will pass the exam as easy as pie.
DP-600 Latest Dumps Sheet: https://www.braindumpsit.com/DP-600_real-exam.html
2026 Latest BraindumpsIT DP-600 PDF Dumps and DP-600 Exam Engine Free Share: https://drive.google.com/open?id=1olVf3NHtG5uoty2Xd84koF82PcrlSmG4