Snowflake SPS-C01 PDF Questions - An Easy Way To Prepare For Exam

P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by ITdumpsfree: https://drive.google.com/open?id=1EU9LrdHUoOF4EyJR_DvIyfnLHav-V329
Our SPS-C01 training materials provide 3 versions to the client and they include the PDF version, PC version, APP online version. Each version’s using method and functions are different but the questions and answers of our SPS-C01 study quiz is the same. The client can decide which SPS-C01 version to choose according their hobbies and their practical conditions. You will be surprised by the convenient functions of our SPS-C01 exam dumps.
| Section | Objectives |
|---|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
- 1. Python UDFs
- 2. Stored procedures in Snowpark
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
- 1. Pushdown optimization concepts
- 2. Resource utilization tuning
|
| Testing, Debugging, and Deployment | - Production readiness
- 1. Debugging Snowpark applications
- 2. Deployment strategies
|
| DataFrame Operations and Data Processing | - Data transformation workflows
- 1. Filtering, selecting, and aggregations
- 2. Joins and window functions
|
| Data Engineering with Snowpark | - Pipeline development
- 1. Batch processing workflows
- 2. Integration with Snowflake data pipelines
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
- 1. Snowpark APIs and supported languages
- 2. Snowflake execution model overview
|
>> Dumps SPS-C01 Torrent <<
SPS-C01 Online Training, Practice SPS-C01 Exam Online
Our team of experts updates actual Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) questions regularly so you can prepare for the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam according to the latest syllabus. Additionally, we also offer up to 1 year of free Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam questions updates. We have a 24/7 customer service team available for your assistance if you get stuck somewhere. Buy Snowflake SPS-C01 Latest Questions of ITdumpsfree now and get ready to crack the SPS-C01 certification exam in a single attempt.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q364-Q369):
NEW QUESTION # 364
You are developing a Snowpark application that performs several complex transformations on a large DataFrame representing customer purchase history. This DataFrame is used multiple times in the application. You need to optimize the application's performance by caching the DataFrame. Which of the following approaches is the MOST efficient and memory-conscious way to cache the DataFrame in Snowpark?
- A. Using immediately after the initial DataFrame creation.
- B. Using without specifying a storage level. Snowflake will choose a default storage level.
- C. Creating a temporary table in Snowflake using and then reading it back into a new DataFrame for each subsequent operation.
- D. Using 'session.createDataFrame(df.toPandas())' to convert the Snowpark DataFrame to Pandas and back to Snowpark DataFrame.
- E. Using to store the entire DataFrame in a Python list, then creating a new DataFrame from that list for each subsequent operation.
Answer: A
Explanation:
' df.cache_result()' is the recommended approach for caching DataFrames in Snowpark. It is designed to efficiently materialize the results of a DataFrame and store them in Snowflake's internal cache. This avoids recomputation in subsequent operations. brings the entire DataFrame into the client's memory, which is inefficient for large datasets. is not directly available in Snowpark like Spark. Creating a temporary table involves unnecessary I/O operations. Converting to Pandas and back introduces overhead and defeats the purpose of using Snowpark's optimized execution.
NEW QUESTION # 365
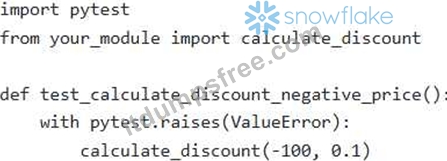
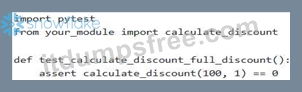
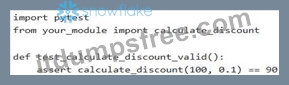
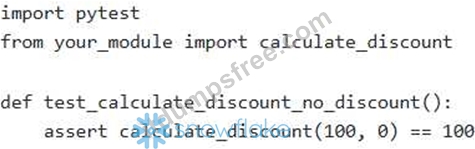
You are developing a Snowpark Python application and want to write unit tests for your custom UDFs using pytest. Consider the following UDF:
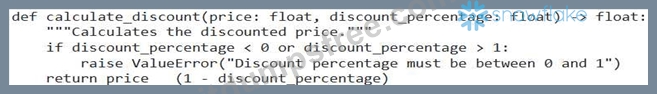
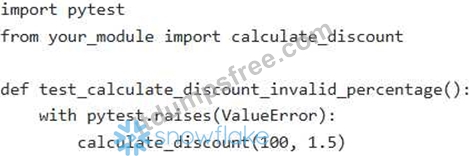
Which of the following pytest tests are correctly written and effectively test the UDF, including handling potential exceptions? (Select all that apply)
Answer: B,C,D,E
Explanation:
Options A, B, C, and D represent correctly written pytest tests. A tests a valid discount, B tests the exception handling for an invalid percentage, C tests the case with no discount, and D tests a full discount. E is incorrect because the calculate_discount function does not explicitly check for negative prices, therefore 'pytest.raises(ValueErrorV will cause a failed test since no ValueError is raised.
NEW QUESTION # 366
You are migrating a Pandas-based data processing pipeline to Snowpark to leverage Snowflake's scalability and performance. One part of the pipeline involves a computationally intensive custom function that is applied row-by-row to a DataFrame using the 'apply' method in Pandas. When migrating this to Snowpark, what are the most effective strategies for achieving similar functionality while maximizing performance within the Snowflake environment?
- A. Rewrite the custom function as a vectorized operation using Snowpark DataFrame functions and expressions, avoiding row-by-row processing.
- B. Utilize Snowpark's Pandas API to seamlessly execute the Pandas code within the Snowflake environment with minimal modifications.
- C. Create a Snowpark User-Defined Function (UDF) using Python and apply it to the DataFrame using the 'select method, leveraging Snowflake's distributed execution capabilities.
- D. Directly translate the Pandas 'apply' operation to a Snowpark 'apply' operation, assuming that Snowpark's implementation is automatically optimized for distributed execution.
- E. Use a stored procedure to execute the pandas 'apply' row by row on the data from snowflake table.
Answer: A,C
Explanation:
Vectorized operations in Snowpark provide the best performance by leveraging Snowflake's distributed processing. Creating a UDF allows you to push the computation to the Snowflake engine, avoiding the need to transfer large amounts of data to the Python environment. Direct translation to Snowpark 'apply' is not available as Snowpark 'apply' is significantly different, pandas code requires explicit data copying from and to snowflake. Stored procedures do not leverage the parallel processing capabilities of Snowflake as effectively as UDFs or vectorized operations. Pandas API is not the recommended way as UDF or vectorized operation.
NEW QUESTION # 367
You are developing a Snowpark Python application to process streaming data from a Kafka topic, enrich it with data from a Snowflake table, and store the results in another Snowflake table. The enrichment process involves joining the streaming data with a large dimension table in Snowflake. Which of the following Snowpark features would be most efficient and scalable for this use case, considering the continuous nature of the streaming data and the size of the dimension table?
- A. Utilizing Snowpark UDFs to fetch data from the dimension table for each row of the streaming data DataFrame.
- B. Employing a Snowpark Stored Procedure that periodically refreshes a smaller, aggregated version of the dimension table and using that for joining with the streaming data.
- C. Creating a Snowflake materialized view that pre-joins the streaming data (landing in a table) with the dimension table and using Snowpark to query the materialized view.
- D. Using a standard Snowpark DataFrame join operation with a broadcast hint on the smaller streaming data DataFrame.
- E. Leveraging a dynamic table to incrementally update the join of the streaming data and dimension table.
Answer: E
Explanation:
Dynamic tables are designed for incremental data transformations, which is ideal for continuous streaming data processing and joining with a large dimension table. They automatically manage data refreshes and optimize performance for incremental updates, making them the most efficient and scalable option. Option A might work for small datasets, but it doesn't scale well with larger dimension tables or sustained streaming. Option B is generally inefficient for large-scale joins. Option C adds unnecessary complexity and latency due to the periodic refresh. Option D is not well-suited for true streaming as it relies on landing data into a static table first.
NEW QUESTION # 368
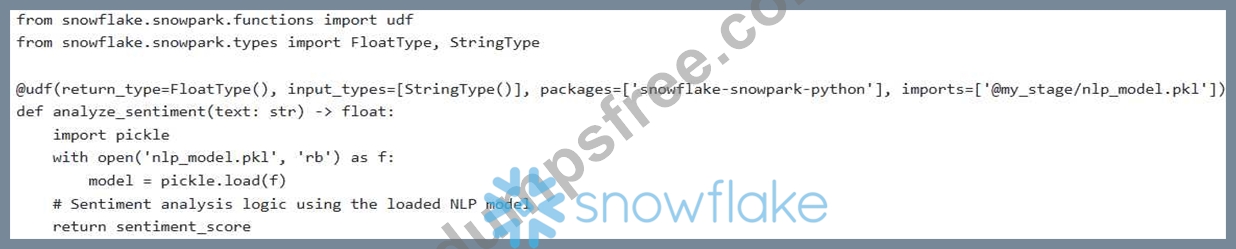
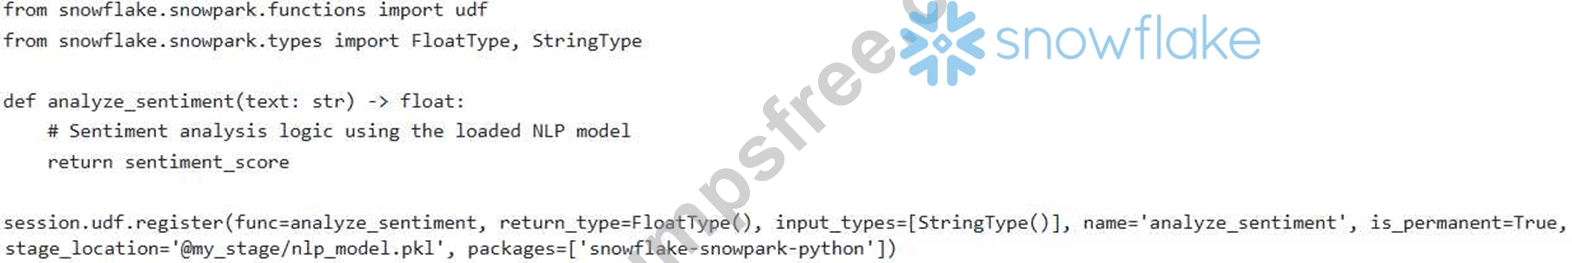
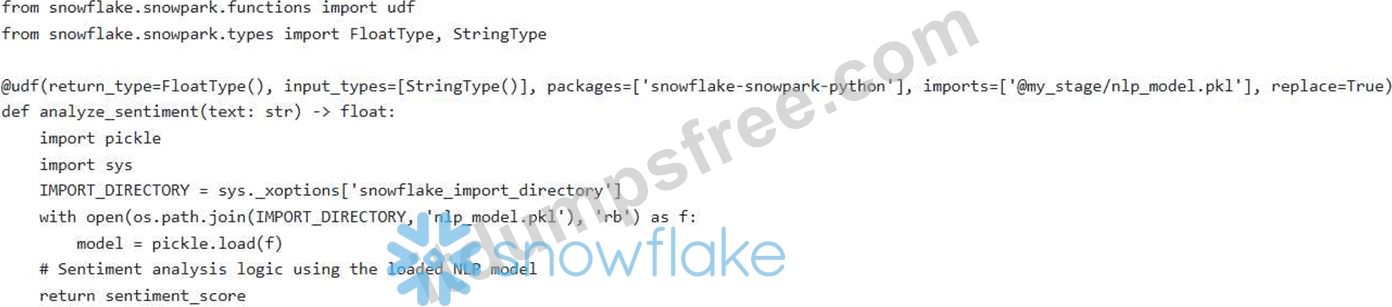
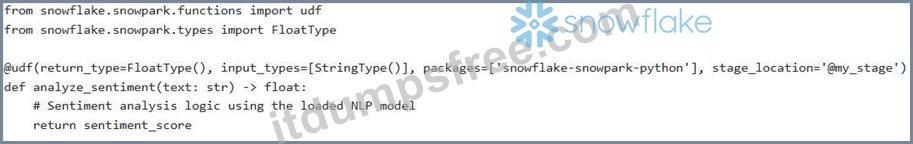
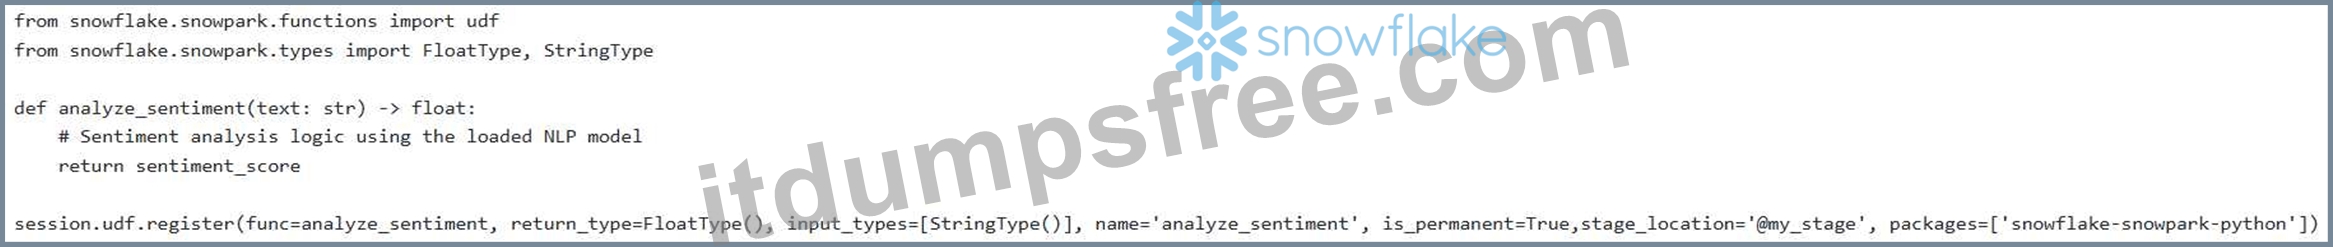
You are developing a Snowpark application to process customer sentiment from text reviews. You have a Python function, , that utilizes a pre-trained NLP model loaded from a file on a Snowflake stage named This function returns a sentiment score (float) between -1 and 1. You need to register this function as a UDF so that it can be used within Snowpark DataFrames. Which of the following code snippets correctly registers the UDF, ensuring the NLP model is available to the function during execution?
Answer: C
Explanation:
Option E correctly uses the '@udf decorator with the 'imports' parameter to specify the location of the pickled model on the stage. It also uses to correctly construct the path to the imported file within the UDF's execution environment. Replace=True prevents errors if the UDF already exists. Options A, C and D don't correctly handle importing the NLP model. Option B has a security issue of loading file without validating the Path.
NEW QUESTION # 369
......
To fit in this amazing and highly accepted exam, you must prepare for it with high-rank practice materials like our Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 study materials. Our SPS-C01 exam questions are the Best choice in terms of time and money. If you are a beginner, start with the learning guide of SPS-C01 Practice Engine and our products will correct your learning problems with the help of the Snowflake SPS-C01 training braindumps.
SPS-C01 Online Training: https://www.itdumpsfree.com/SPS-C01-exam-passed.html
- New SPS-C01 Exam Discount 🧖 New SPS-C01 Study Notes 🥖 SPS-C01 Pass Guide 🥀 Search on ☀ www.prepawaypdf.com ️☀️ for ➥ SPS-C01 🡄 to obtain exam materials for free download 🍛New SPS-C01 Study Notes
- SPS-C01 Valid Exam Cram 🥕 Test Certification SPS-C01 Cost 🚓 SPS-C01 Frenquent Update ↔ The page for free download of ⏩ SPS-C01 ⏪ on ▛ www.pdfvce.com ▟ will open immediately 🚌Cert SPS-C01 Exam
- 2026 Dumps SPS-C01 Torrent | High Pass-Rate Snowflake SPS-C01 Online Training: Snowflake Certified SnowPro Specialty - Snowpark 💕 Immediately open “ www.pass4test.com ” and search for ➽ SPS-C01 🢪 to obtain a free download ➡️SPS-C01 New Braindumps Pdf
- Latest Dumps SPS-C01 Torrent Offer You The Best Online Training | Snowflake Certified SnowPro Specialty - Snowpark 🪓 Search for ✔ SPS-C01 ️✔️ and easily obtain a free download on “ www.pdfvce.com ” 🦽Test Certification SPS-C01 Cost
- Dumps SPS-C01 Torrent | Professional SPS-C01 Online Training: Snowflake Certified SnowPro Specialty - Snowpark ⬆ Go to website “ www.practicevce.com ” open and search for ▷ SPS-C01 ◁ to download for free 🚛SPS-C01 Prepaway Dumps
- Reliable Dumps SPS-C01 Torrent offer you accurate Online Training | Snowflake Snowflake Certified SnowPro Specialty - Snowpark 💜 Search for ⮆ SPS-C01 ⮄ and download exam materials for free through ➽ www.pdfvce.com 🢪 👴SPS-C01 Pass Guide
- Excellent Dumps SPS-C01 Torrent | Amazing Pass Rate For SPS-C01 Exam | Fast Download SPS-C01: Snowflake Certified SnowPro Specialty - Snowpark 🕤 Search for “ SPS-C01 ” and download exam materials for free through ⇛ www.verifieddumps.com ⇚ 🐏Valid SPS-C01 Exam Vce
- New SPS-C01 Practice Questions 🏔 New SPS-C01 Study Notes 🩸 Valid SPS-C01 Exam Vce 🧨 Download ( SPS-C01 ) for free by simply entering ⏩ www.pdfvce.com ⏪ website 🆕Free SPS-C01 Brain Dumps
- Make Exam Preparation Simple www.prep4away.com Real Snowflake SPS-C01 Exam Questions 🤣 Download ⇛ SPS-C01 ⇚ for free by simply entering ➤ www.prep4away.com ⮘ website 🗼SPS-C01 Pass Guide
- Quiz Snowflake - SPS-C01 –Latest Dumps Torrent 🚎 Immediately open ➡ www.pdfvce.com ️⬅️ and search for “ SPS-C01 ” to obtain a free download 🚓Relevant SPS-C01 Exam Dumps
- 2026 Dumps SPS-C01 Torrent | High Pass-Rate Snowflake SPS-C01 Online Training: Snowflake Certified SnowPro Specialty - Snowpark ☸ Search for 【 SPS-C01 】 and easily obtain a free download on ▷ www.prepawaypdf.com ◁ 🧃Relevant SPS-C01 Exam Dumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BTW, DOWNLOAD part of ITdumpsfree SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1EU9LrdHUoOF4EyJR_DvIyfnLHav-V329