The format name of Microsoft DP-750 practice test questions is Microsoft PDF Questions file, desktop practice test software, and web-based practice test software. Choose the nay type of Implementing Data Engineering Solutions Using Azure Databricks DP-750 Practice Exam Questions that fit your DP-750 exam preparation requirement and budget and start preparation without wasting further time.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 2: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 3: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 4: Prepare and process data | 30-35% | - Ingest and transform data
|
>> Valid DP-750 Test Voucher <<
It is a common sense that only high quality and accuracy DP-750 training prep can relive you from those worries. It is our communal wish to reap successful fruits. So our company did a lot to make sure that happen. Our DP-750 learning quiz compiled by the most professional experts can offer you with high quality and accuracy results for your success. And we can claim that if you study with our DP-750 Exam Braindumps for 20 to 30 hours, you will pass the exam for sure.
NEW QUESTION # 79
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes curated Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Answer: A
Explanation:
The best choice is a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
Low Development Effort: Lakeflow SDP (formerly known as Delta Live Tables or DLT) is a completely declarative ETL framework. You simply define the target schemas and data transformations using standard SQL or Python. Databricks automatically manages the underlying operational complexities, state maintenance, task orchestration, and DAG dependencies for you.
Built-in Quality & Monitoring: It offers out-of-the-box data monitoring capabilities via Expectations, which allow you to specify data cleansing policies (like drop, retain, or fail on bad rows) with zero custom validation code. It also captures complete, automatic end-to-end data lineage and operational stats straight into Unity Catalog.
Built-in Resilience: Infrastructure failure handling and automatic retries are natively managed by the Lakeflow runtime.
Native Storage Ingestion: Using read_files() (Auto Loader) within SDP allows effortless, incremental ingestion of files from cloud object storage directly into curated Delta tables.
Reference:
https://docs.databricks.com/aws/en/ldp/
NEW QUESTION # 80
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
- The schemas and tables can be queried in Databricks.
- The schemas and tables appear alongside other Unity Catalog objects.
- The data is NOT copied into Databricks-managed storage.
Solution: You create a Databricks access connector.
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You create a foreign catalog in Catalog Explorer.
You should create a Foreign Catalog using Lakehouse Federation.
Data Copying: Lakehouse Federation queries data directly in the source SQL Server without moving or copying it.
Seamless Integration: The database schemas and tables appear right inside Unity Catalog alongside your other data objects.Real-time Access: It provides immediate access to live SQL Server data.
Incorrect:
* You create a Databricks access connector.
* You create a Lakeflow Connect pipeline and connect it to DB1.
Data Copying: Lakeflow Connect is an ingestion tool that physically replicates and copies data into Databricks-managed storage (Delta tables).
Storage Costs: It violates your requirement to keep data out of Databricks storage.
* You create a new native catalog in Unity Catalog.
Note:
To expose the external SQL Server database in Unity Catalog without copying the data, you must use Lakehouse Federation.
Here are the step-by-step actions you need to take:
1. Create a Connection
Create a securable object in Unity Catalog that specifies the path and credentials to access the SQL Server database.
Go to Catalog Explorer or use SQL.
Select External Data > Connections.
Create a connection using the SQL Server connection details (URL, host, port, and database credentials).
*-> 2. Create a Foreign Catalog
Create a specific type of catalog in Unity Catalog that mirrors the external database.
Use the CREATE FOREIGN CATALOG SQL command or the Catalog Explorer UI.
Link this foreign catalog directly to the connection you created in step 1.
3. Query the DataOnce the foreign catalog is created, Unity Catalog automatically syncs the schemas and tables from SQL Server.
Reference:
https://docs.databricks.com/gcp/en/database-objects/
NEW QUESTION # 81
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table! is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table!
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Answer: D
Explanation:
The correct answer is C - Enable schema evolution.
When new columns are added to the source data, a pipeline without schema evolution treats the unexpected columns as a schema mismatch and fails the write. Schema evolution, when enabled in an SDP pipeline, automatically adds those new columns to the target Delta table on the next pipeline run. The pipeline continues without intervention, and no historical data is lost.
Option A (disable schema enforcement) is the wrong lever - it removes all schema validation, which could allow corrupt or mistyped data into Table1. Schema evolution is a targeted, safer response.
Option B (row filters to exclude records with new columns) would silently discard valid records just because they carry extra fields - that's data loss. Option D (separate table per schema version) creates an explosion of tables as schemas evolve and makes downstream analytics significantly more complex. Schema evolution is the clean, built-in solution.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/schema-evolution
NEW QUESTION # 82
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
* asset.id
* asset, type
* asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.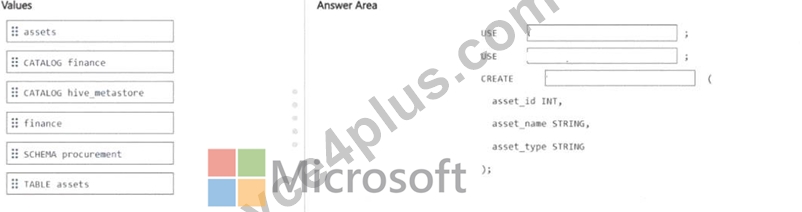
Answer:
Explanation: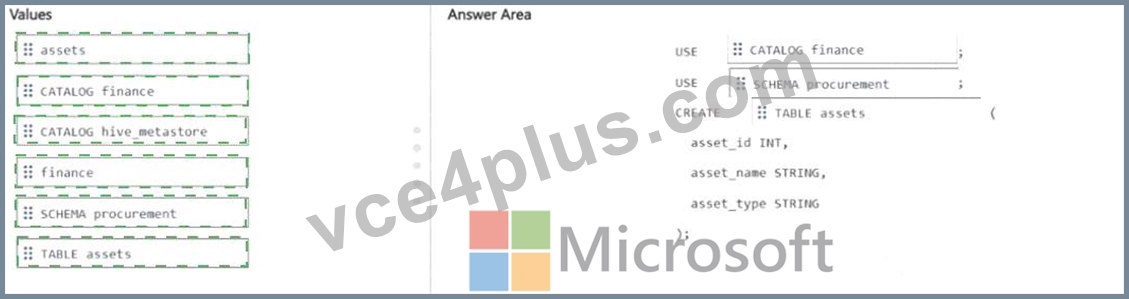
Explanation:
The correct SQL statement uses the full three-part namespace finance.procurement.assets with the three specified columns.
In Unity Catalog, every object lives in a three-tier hierarchy: catalog # schema # table. Using the full path finance.procurement.assets guarantees the table lands in the right schema regardless of the session's current catalog or schema context. Omitting the catalog or schema name relies on the session default, which may not be finance.procurement - a silent mistake that's hard to catch.
The column names asset_id, asset_type, and asset_name must match the spec exactly. Unity Catalog applies access controls, lineage tracking, and tagging at the column level, so the names are meaningful beyond just the schema. Once created, any GRANT statements can target specific columns for fine-grained access control.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-ddl-create- table-using
NEW QUESTION # 83
Hotspot Question
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming. The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.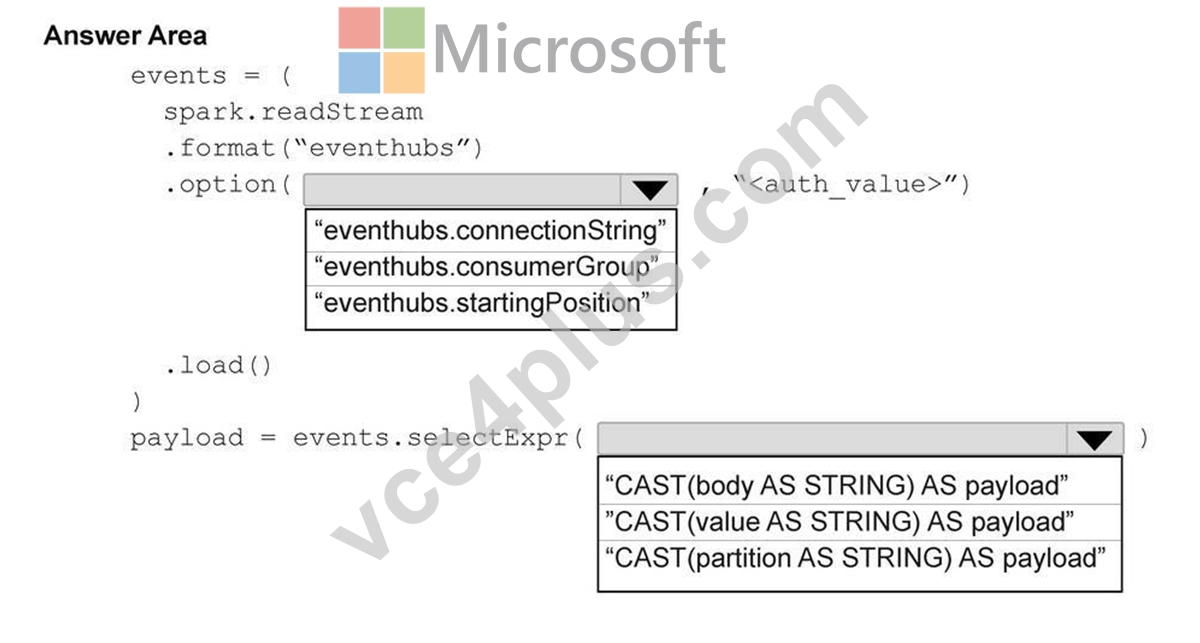
Answer:
Explanation: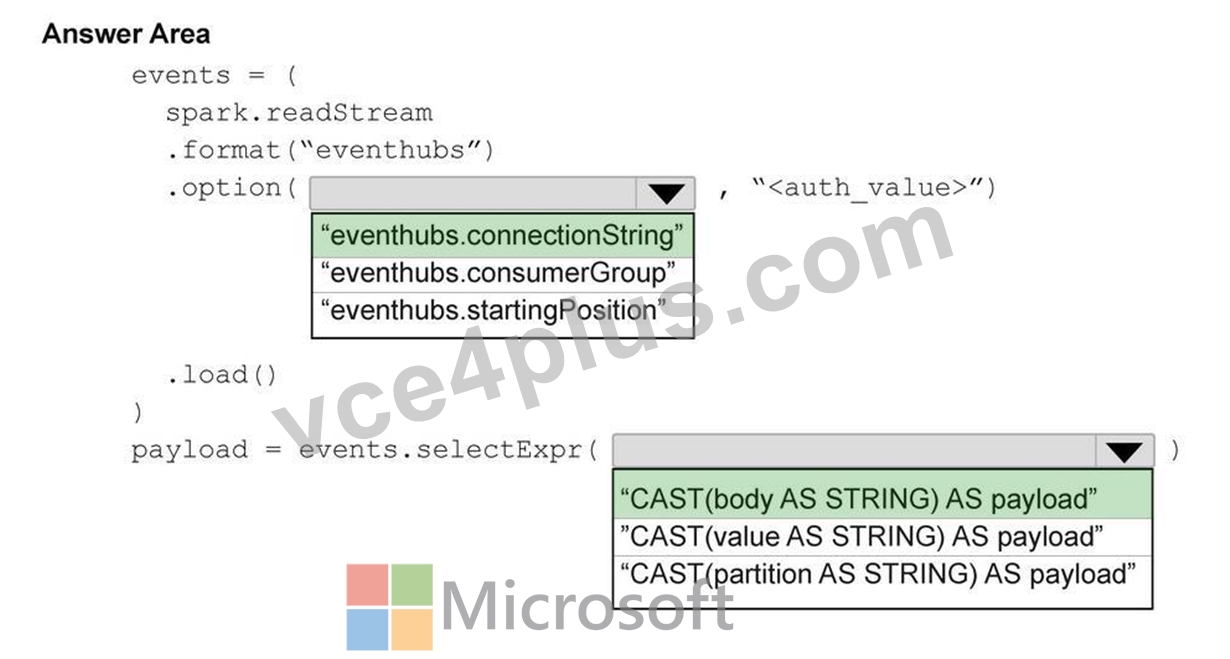
NEW QUESTION # 84
......
No matter what kind of DP-750 learning materials you need, you can find the best one for you. Our expert team has spent a lot of time and energy just to provide you with the best quality DP-750study guide. DP-750 Exam Materials will definitely make you feel value for money. Your exam results will help you prove this! And countless of the candidates have been benefited from our DP-750 practice braindumps.
Practice DP-750 Exam: https://www.vce4plus.com/Microsoft/DP-750-valid-vce-dumps.html