Authoritative Databricks-Machine-Learning-Professional Latest Dumps Sheet & Leader in Qualification Exams & Effective Databricks Databricks Certified Machine Learning Professional

DOWNLOAD the newest TroytecDumps Databricks-Machine-Learning-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1X3Tu3afZrfLQP8vC2RYDoyz-6_hVnWQ0
As a market leader, our company is able to attract quality staffs, it actively seeks out those who are energetic, persistent, and professional to various Databricks-Machine-Learning-Professional certificate and good communicator. And we strongly believe that the key of our company's success is its people, skills, knowledge and experience. Over 50% of the account executives and directors have been with the Group for more than ten years. The successful selection, development and Databricks-Machine-Learning-Professional training of personnel are critical to our company's ability to provide a high pass rate of Databricks-Machine-Learning-Professional exam questions for you to pass the Databricks-Machine-Learning-Professional exam.
| Topic | Details |
|---|
| Topic 1 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 2 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 3 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 4 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 5 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Topic 6 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 7 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| Topic 8 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
>> Databricks-Machine-Learning-Professional Latest Dumps Sheet <<
Databricks-Machine-Learning-Professional Free Download Pdf & Valid Dumps Databricks-Machine-Learning-Professional Files
You can easily download these formats of Databricks Databricks-Machine-Learning-Professional actual dumps and use them to prepare for the Databricks Databricks-Machine-Learning-Professional certification test. You don't need to enroll yourself in expensive Databricks-Machine-Learning-Professional Exam Training classes. With the Databricks Databricks-Machine-Learning-Professional valid dumps, you can easily prepare well for the actual Databricks Databricks-Machine-Learning-Professional exam at home.
Databricks Certified Machine Learning Professional Sample Questions (Q171-Q176):
NEW QUESTION # 171
A Machine Learning Engineer is building a Databricks ML pipeline to predict customer churn. The pipeline needs to include automated feature engineering, model training, evaluation, and deployment to a REST API endpoint using MLflow. What is the primary goal of an integration test for this pipeline?
- A. To ensure the pipeline runs with all components working together and data flowing correctly between stages
- B. To monitor the model's performance after it has been deployed into the production environment
- C. To ensure that the pipeline's performance meets latency and scalability requirements under simulated production loads
- D. To verify that the pipeline can process a variety of data formats, even if some stages are skipped or bypassed
Answer: A
Explanation:
The primary purpose of an integration test is to validate that all components of the ML pipeline work together as expected. This includes confirming that data flows correctly through feature engineering, training, evaluation, and deployment steps, ensuring the end-to-end pipeline functions properly as a cohesive system.
NEW QUESTION # 172
A Data Scientist at a company with rapidly increasing sales has deployed a scikit-learn model in production, which is retrained weekly on a single-node cluster. During the most recent retraining, the job failed due to an out-of-memory error. Upon investigation, the Data Scientist discovered that the training data had increased to 700GB as a result of the company's expanding customer base. Which approach will reliably resolve this issue in the long term?
- A. Wrap the current model training code as a Spark UDF and apply it to the Spark DataFrame to distribute model training across multiple nodes.
- B. Refactor the code to use the DeepSpeed library to shard the scikit-learn model across multiple nodes, enabling distributed model training on large volumes of data
- C. Refactor the code to use MLlib across multiple nodes, enabling distributed model training on large volumes of data
- D. Increase the size of the current single-node cluster to handle the increase of data while minimizing the need for code refactoring
Answer: C
Explanation:
Spark MLlib is designed for distributed model training on large-scale datasets and can natively handle hundreds of gigabytes of data across multiple nodes. Refactoring to MLlib enables the training workload to scale with data growth, avoids single-node memory limitations, and provides a reliable long-term solution as the company's data continues to expand.
NEW QUESTION # 173
A Machine Learning Engineer has deployed a fraud detection model that processes 10,000 transactions per hour. The model was trained on data from Q1 2024, but it's now Q4 2024. The ML team notices three concerning trends: (1) the model's precision has dropped from 92% to
78% over the past month, (2) the average transaction amount in recent data has increased from
$150 to $220 and (3) the relationship between transaction frequency and fraud likelihood has weakened significantly due to new payment methods being introduced. The engineer needs to implement a monitoring solution that can detect the root cause of the performance degradation, identify why the precision dropped, and be able to do this at the scale needed. Which monitoring pipeline component will do this?
- A. Model Health Monitoring Pipeline because it ensures the infrastructure can handle the 10,000 transactions per hour load.
- B. Logging and Monitoring Pipeline because it captures all prediction requests and can identify patterns in the fraud predictions.
- C. Drift Detection Pipeline because it can identify both the data drift (transaction amount changes) and concept drift (weakened relationship between features and target).
- D. Model Performance Monitoring Pipeline because it directly tracks precision metrics and can alert when thresholds are breached.
Answer: C
Explanation:
A drift detection pipeline is designed to diagnose the root causes of model performance degradation at scale. It can detect data drift, such as changes in the distribution of transaction amounts, and concept drift, where the relationship between input features and the fraud label changes due to new payment methods. This directly explains why precision dropped and provides actionable insight beyond simply observing metric degradation.
NEW QUESTION # 174
A data scientist has developed a scikit-learn model sklearn_model and they want to log the model using MLflow.
They write the following incomplete code block:
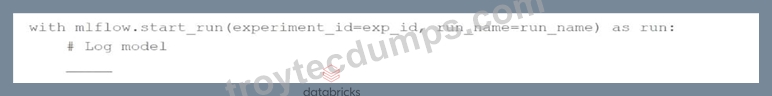
Which of the following lines of code can be used to fill in the blank so the code block can successfully complete the task?
- A. mlflow.sklearn.track_model(sklearn_model, "model")
- B. mlflow.spark.track_model(sklearn_model, "model")
- C. mlflow.sklearn.load_model("model")
- D. mlflow.sklearn.log_model(sklearn_model, "model")
- E. mlflow.spark.log_model(sklearn_model, "model")
Answer: B
NEW QUESTION # 175
A Machine Learning Engineer wants to implement MLOps. They currently have three environments: dev, stage, and prod. They have many private PyPI packages that they use to train their models, and they are concerned that their environments will not be consistent between dev, stage, and prod. The engineer needs to follow enterprise scaling and CI/CD best practices to ensure that their environments are consistent. Which approach will do this?
- A. Use the same DBR for ML runtime across environments and %pip install any additional packages at the top of the notebook.
- B. Use the same DBR across environments.
- C. Define dependencies for each task in their job(s) running the ML pipeline using Databricks Asset Bundles or Terraform.
- D. Define an all purpose cluster with the private PyPI packages installed, and use the same cluster config across environments.
Answer: C
Explanation:
Defining dependencies at the job or task level using Databricks Asset Bundles or Terraform aligns with enterprise MLOps and CI/CD best practices. This approach makes environment configuration declarative, version-controlled, and reproducible across dev, stage, and prod, ensuring consistent use of private PyPI packages without relying on mutable clusters or manual installation steps.
NEW QUESTION # 176
......
With the rapid development of the world economy and frequent contacts between different countries, the talent competition is increasing day by day, and the employment pressure is also increasing day by day. If you want to get a better job and relieve your employment pressure, it is essential for you to get the Databricks-Machine-Learning-Professional Certification. However, due to the severe employment situation, more and more people have been crazy for passing the Databricks-Machine-Learning-Professional exam by taking examinations, the exam has also been more and more difficult to pass.
Databricks-Machine-Learning-Professional Free Download Pdf: https://www.troytecdumps.com/Databricks-Machine-Learning-Professional-troytec-exam-dumps.html
- Databricks Certified Machine Learning Professional Training Vce - Databricks-Machine-Learning-Professional Lab Questions - Databricks Certified Machine Learning Professional Practice Training ✅ Copy URL { www.practicevce.com } open and search for ⮆ Databricks-Machine-Learning-Professional ⮄ to download for free 🤬Databricks-Machine-Learning-Professional Test Voucher
- Valid Dumps Databricks-Machine-Learning-Professional Sheet 🎯 Valid Test Databricks-Machine-Learning-Professional Tutorial 🆒 Databricks-Machine-Learning-Professional Latest Torrent 🚹 Search for 【 Databricks-Machine-Learning-Professional 】 on ▷ www.pdfvce.com ◁ immediately to obtain a free download 💘Databricks-Machine-Learning-Professional Free Exam
- Pass Guaranteed Quiz Databricks - Databricks-Machine-Learning-Professional - Databricks Certified Machine Learning Professional Fantastic Latest Dumps Sheet 🧬 Easily obtain ➥ Databricks-Machine-Learning-Professional 🡄 for free download through ✔ www.troytecdumps.com ️✔️ 🐫Databricks-Machine-Learning-Professional Free Practice
- Pdf Databricks-Machine-Learning-Professional Version 🕡 New Databricks-Machine-Learning-Professional Learning Materials 🥙 Excellect Databricks-Machine-Learning-Professional Pass Rate 🦌 Search for ⇛ Databricks-Machine-Learning-Professional ⇚ and download it for free on ✔ www.pdfvce.com ️✔️ website 🍤Databricks-Machine-Learning-Professional Test Voucher
- Databricks-Machine-Learning-Professional Latest Torrent 📬 Pdf Databricks-Machine-Learning-Professional Version 🍩 Valid Dumps Databricks-Machine-Learning-Professional Sheet 🕐 Search for 《 Databricks-Machine-Learning-Professional 》 and download it for free on ▶ www.testkingpass.com ◀ website 🙌Latest Databricks-Machine-Learning-Professional Test Labs
- Pass Guaranteed Quiz Databricks - Databricks-Machine-Learning-Professional - Databricks Certified Machine Learning Professional Fantastic Latest Dumps Sheet 😓 Open ➠ www.pdfvce.com 🠰 enter ✔ Databricks-Machine-Learning-Professional ️✔️ and obtain a free download 👌New Databricks-Machine-Learning-Professional Learning Materials
- Databricks-Machine-Learning-Professional Questions Exam 😷 Databricks-Machine-Learning-Professional Exam Review 🧦 New Databricks-Machine-Learning-Professional Test Fee 🔊 Immediately open ▶ www.easy4engine.com ◀ and search for ➥ Databricks-Machine-Learning-Professional 🡄 to obtain a free download ✈Testing Databricks-Machine-Learning-Professional Center
- New Databricks-Machine-Learning-Professional Test Fee 🎍 Pdf Databricks-Machine-Learning-Professional Version 🍳 Testing Databricks-Machine-Learning-Professional Center 🎍 Simply search for ✔ Databricks-Machine-Learning-Professional ️✔️ for free download on ▛ www.pdfvce.com ▟ ‼Excellect Databricks-Machine-Learning-Professional Pass Rate
- Databricks-Machine-Learning-Professional Dump Torrent 👻 Latest Databricks-Machine-Learning-Professional Test Labs 🍍 Flexible Databricks-Machine-Learning-Professional Testing Engine 🟨 Search for 「 Databricks-Machine-Learning-Professional 」 and obtain a free download on ▷ www.exam4labs.com ◁ 🧳Databricks-Machine-Learning-Professional Dump Torrent
- Valid Dumps Databricks-Machine-Learning-Professional Sheet 🙁 Excellect Databricks-Machine-Learning-Professional Pass Rate 😀 Valid Test Databricks-Machine-Learning-Professional Tutorial 🧏 Download 「 Databricks-Machine-Learning-Professional 」 for free by simply entering ▶ www.pdfvce.com ◀ website 🧴Pdf Databricks-Machine-Learning-Professional Version
- New Databricks-Machine-Learning-Professional Test Fee ⛰ Databricks-Machine-Learning-Professional Reliable Test Answers 🏖 New Databricks-Machine-Learning-Professional Learning Materials 🥪 Search for ⏩ Databricks-Machine-Learning-Professional ⏪ and download it for free immediately on ✔ www.practicevce.com ️✔️ ↔Databricks-Machine-Learning-Professional Free Practice
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free & New Databricks-Machine-Learning-Professional dumps are available on Google Drive shared by TroytecDumps: https://drive.google.com/open?id=1X3Tu3afZrfLQP8vC2RYDoyz-6_hVnWQ0