P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Itcertking: https://drive.google.com/open?id=1eYt71qcZyM0F93rxHhc-d9QiQRchhF2m
The chance of making your own mark is open, and only smart one can make it. We offer SPS-C01 exam materials this time and support you with our high quality and accuracy SPS-C01 learning quiz. Comparing with other exam candidates who still feel confused about the perfect materials, you have outreached them. So it is our sincere suggestion that you are supposed to get some high-rank practice materials like our SPS-C01 Study Guide.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and DataFrame Operations | 35% | - Window functions - Filtering, Aggregating, and Joining DataFrames - Persisting transformed data - Using built-in functions - Complex data pipelines |
| Snowpark API for Python | 30% | - Establishing connections and session management - User-Defined Functions (UDFs) and Stored Procedures - Reading and writing data - DataFrame creation and manipulation - Working with Semi-structured data |
| Performance Optimization and Best Practices | 20% | - Minimizing data transfer - Caching strategies - Vectorized UDFs - Debugging and explain plans - Query pushdown and optimization - Warehouse sizing for Snowpark |
| Snowpark Concepts | 15% | - Snowpark DataFrames and query plans - Transformations vs. Actions - Stored procedures and conditional logic - Snowpark architecture and core concepts - Client-side vs. Server-side execution - Snowpark Sessions and connection management |
>> SPS-C01 Valid Exam Duration <<
We can't forget the advantages and the conveniences that reliable SPS-C01 study materials complied by our companies bring to us. First, by telling our customers what the key points of learning, and which learning SPS-C01 method is available, they may save our customers money and time. They guide our customers in finding suitable jobs and other information as well. Secondly, a wide range of practice types and different version of our SPS-C01 Study Materials receive technological support through our expert team.
NEW QUESTION # 337
You have a Snowpark DataFrame named 'orders df with columns 'order id', 'customer id', 'order date', and 'total amount'. You need to create a new DataFrame that contains only the 'customer_id" and the total number of orders placed by each customer. However, you want to perform this aggregation in parallel using a user-defined function (UDF) to improve performance. Which approach is MOST efficient and CORRECT?
Answer: C
Explanation:
The most efficient and correct approach is to use the built-in 'groupBy' and 'count' functions. These functions are optimized for Snowflake's architecture and will generally outperform UDF-based solutions for simple aggregations. Using UDFs for simple tasks introduces overhead and can negate any potential performance benefits. While options A, B and D could achieve the result, they are less efficient. Option E is irrelevant to the problem.
NEW QUESTION # 338
You are tasked with creating a secure UDF in Snowflake using Snowpark Python API that encrypts sensitive customer data before storing it. The UDF should be accessible only to users with specific roles. You have the following code snippet. What needs to be done to make it secure and operationalize for multiple users?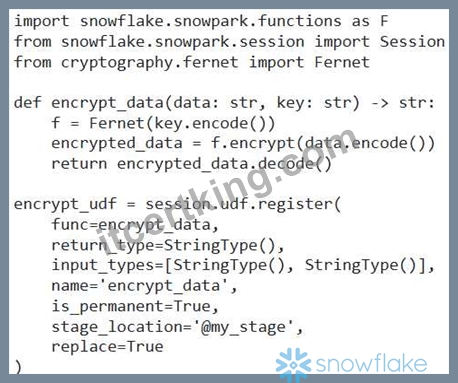
Considering Security best practices, what steps are critical for securing the UDF and granting appropriate permissions to other users?
Answer: A,E
Explanation:
Storing the encryption key directly in the UDF code is a major security vulnerability. Snowflake's Secret object provides a secure way to store and manage sensitive information like encryption keys. Granting EXECUTE privilege on the UDF and USAGE privilege on the database and schema is essential for allowing authorized users to execute the UDF. USAGE privilege on the database and schema allows users to 'see' the UDF. Option C is incorrect because granting global USAGE privilege on the stage location is overly permissive. Option E is incorrect as bypassing role-based access control is insecure.
NEW QUESTION # 339
You are developing a Snowpark stored procedure in Python that utilizes the 'requests' library to fetch data from an external API. Your Snowflake account is configured to use Anaconda packages. You encounter an error indicating that the 'requests' library is not found. Which of the following steps are MOST effective in ensuring the 'requests' library is available to your stored procedure?
Answer: B
Explanation:
The 'packages' argument in the 'CREATE OR REPLACE PROCEDURE statement is the correct way to specify dependencies on Anaconda packages. Snowflake will automatically resolve and make these packages available to the stored procedure. Option B is incomplete; while Anaconda integration is necessary, it doesn't automatically import the library. Options A, C and E are incorrect and not best practices.
NEW QUESTION # 340
You are tasked with creating a Snowpark stored procedure that needs to access a secret stored in Snowflake's Secret Managen The secret contains credentials required to connect to an external API. Which of the following steps are necessary to correctly and securely access and use the secret within your Snowpark stored procedure? (Select all that apply)
Answer: B,D,E
Explanation:
Options A, B, and D are the correct steps. First, the executing role needs 'USAGE on the secret. Second, session.get_secret('secret_name')' is the correct method to access the secret value within the procedure. The stored procedure must be created with EXECUTE AS CALLER for it to use the caller's permissions (which include access to the secret). Option C is incorrect because storing secrets directly in the code is a security risk. Option E is incorrect because Creating a UDF is unneccessary, stored procedures are capable of accessing secret manager directly with provided right access.
NEW QUESTION # 341
You are developing a Snowpark Python application that reads data from a Snowflake table, performs several transformations including filtering, aggregation, and joining with another DataFrame, and then writes the results back to a new table. You want to optimize the execution plan to minimize data movement and processing time. Which of the following strategies would be MOST effective in leveraging Snowpark's lazy evaluation capabilities to achieve this optimization?
Answer: A
Explanation:
Chaining transformations and delaying execution until the final action allows Snowpark to optimize the entire query plan. Caching the initial DataFrame might improve performance in some cases, but it can also introduce unnecessary materialization. Defining transformations in a single SQL query string bypasses Snowpark's optimization capabilities. Calling 'collect()' after each transformation defeats the purpose of lazy evaluation. Python multiprocessing does not directly interact with Snowpark's query optimization.
NEW QUESTION # 342
......
The web-based SPS-C01 practice test is accessible via any browser. This SPS-C01 mock exam simulates the actual Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam and does not require any software or plugins. Compatible with iOS, Mac, Android, and Windows operating systems, it provides all the features of the desktop-based SPS-C01 Practice Exam software.
Reliable SPS-C01 Exam Practice: https://www.itcertking.com/SPS-C01_exam.html
2026 Latest Itcertking SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1eYt71qcZyM0F93rxHhc-d9QiQRchhF2m