With HPE7-S02 study engine, you will get rid of the dilemma that you work hard but cannot improve. With our HPE7-S02 learning materials, you can spend less time but learn more knowledge than others. HPE7-S02 exam questions will help you reach the peak of your career. Just think of that after you get the HPE7-S02 Certification, you will have a lot of opportunities of going to biger and better company and getting higher incomes! what a brighter future!
| Section | Objectives |
|---|---|
| Topic 1: HPE Compute Architecture and Solutions | - HPE ProLiant server families overview - Compute solution positioning and use cases |
| Topic 2: Server Deployment and Configuration | - Firmware and system configuration tools (iLO, SPP) - Initial setup and provisioning |
| Topic 3: Troubleshooting and Support | - Hardware and firmware troubleshooting - Performance monitoring and diagnostics |
| Topic 4: Solution Design and Implementation | - Workload sizing and architecture planning - High availability and redundancy design |
| Topic 5: Storage and Networking Integration | - Networking configuration and connectivity options - SAN and direct-attached storage integration |
>> New APP HP HPE7-S02 Simulations <<
Our experts generalize the knowledge of the exam into our HPE7-S02 exam materials showing in three versions. PDF version of HPE7-S02 study questions - support customers' printing request, and allow you to have a print and practice in papers. Software version of HPE7-S02 learning guide - supporting simulation test system. App/online version of mock quiz - Being suitable to all kinds of equipment or digital devices, and you can review history and performance better. And you can choose the favorite one.
NEW QUESTION # 28
What is one benefit of HPE Slingshot for HPC workloads?
Answer: A
Explanation:
HPE Slingshot improves bandwidth utilization with fine-grained adaptive routing; routing decisions can be packet-by-packet for unordered traffic.
NEW QUESTION # 29
What is one way that NVIDIA Spectrum-X meets the needs for AI networks?
Answer: A
Explanation:
NVIDIA Spectrum-X uses telemetry-based congestion control with high-frequency telemetry probes and flow metering to protect AI workloads and maintain predictable performance. It improves on traditional ECMP with adaptive routing.
NEW QUESTION # 30
You are helping a customer troubleshoot performance issues on an HPE ProLiant DL server acting as a VMware ESXi host.
You have used the esxtop command, and the output is shown below. (In this output, the details for many VMs have been omitted; however, other VMs have similar stats to the ones that are shown.)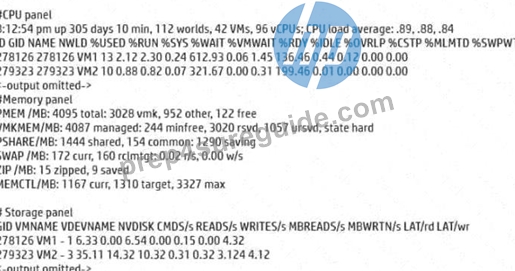
Based on this output, what should you explain?
Answer: A
Explanation:
A is correct. The esxtop output indicates memory pressure rather than CPU or storage saturation. The host has only about 122 MB of free physical memory, the VMkernel memory state is shown as hard, ballooning is active, and swap is in use. Those are strong indicators that ESXi is reclaiming memory because demand is approaching or exceeding comfortable physical capacity. Reclamation can increase latency sharply, especially when guest memory is swapped to storage.
The CPU figures do not show the classic signature of CPU contention. The displayed VMs have low %RDY values, so they are not spending excessive time waiting for physical CPU scheduling. The storage panel also shows relatively low read/write latency for the displayed workloads, which does not support a storage- controller or storage-network bottleneck as the primary cause.
The appropriate remediation is therefore to add physical memory, reduce VM memory commitments, or evacuate some VMs to other hosts. The screenshot is a good example of why VMware troubleshooting should correlate multiple esxtop panels rather than infer the bottleneck from utilization alone.
References/topics: Advanced HPE Compute Solutions, Rev. 26.21, Module 8 "Troubleshooting HPE running VMware"; VMware ESXi esxtop memory-reclamation concepts.
NEW QUESTION # 31
An HPE Private Cloud AI customer has a model deployed with HPE Machine Learning Inference Software (MLIS). You have helped the customer further fine-tune that model. Now the customer would like to test the new model by directing 10% of traffic to it.
What should you do?
Answer: C
Explanation:
A is correct. HPE Machine Learning Inference Software supports canary rollout behavior for a deployment when a new model version is introduced. A canary allows the current production version and the candidate version to run concurrently while a defined percentage of inference traffic is directed to each. Setting the new version to 10% gives the customer a controlled production test while retaining 90% of traffic on the established version.
Option B invents a "Canal" routing service and unnecessarily creates a separate deployment. Option C confuses autoscaling with traffic splitting; autoscaling changes replica capacity, not the percentage of requests routed to different model versions. Option D also misstates the model: traffic distribution is part of the versioned canary rollout rather than an arbitrary routing rule between two independently configured model versions in the existing deployment.
The canary mechanism reduces change risk because model quality, latency, error rate, and resource consumption can be compared before full promotion. If the candidate is satisfactory, its traffic share can be increased; if not, the rollout can be stopped or rolled back.
References/topics: Advanced HPE Compute Solutions, Rev. 26.21, Module 5 "Serving models with HPE Machine Learning Inference Software"; HPE AI Essentials MLIS documentation, "Initiate Canary Rollout."
NEW QUESTION # 32
What option does HPE Private Cloud AI provide for organizations who want to retain Prometheus metrics over the long term?
Answer: C
Explanation:
D is correct. HPE Private Cloud AI can export observability data through an OpenTelemetry (OTel) endpoint.
HPE AI Essentials retains Prometheus metrics for a defined local retention period, but organizations that require longer retention can register an OTel endpoint and send the telemetry to an external observability or storage platform with the retention policy they require. This decouples operational history from the local Prometheus retention window.
Option A does not describe the supported long-term metrics export mechanism. Option B would merely add another visualization component and would not solve durable metric retention; Grafana reads metrics but is not itself the long-term time-series store. Option C concerns alert output, which is a subset of operational events and cannot substitute for retained Prometheus time-series data.
This design is operationally important for capacity analysis, incident review, compliance evidence, and trend detection. The platform remains responsible for producing metrics, while the external OTel destination provides enterprise-scale storage and analytics.
References/topics: Advanced HPE Compute Solutions, Rev. 26.21, Modules 3 and 7, monitoring and troubleshooting; HPE AI Essentials Software documentation, "Configuring Endpoints," which describes OTel export for long-term metric storage.
NEW QUESTION # 33
......
The great reputation of our HPE7-S02 study materials has earned the title “the model study material for the test certification” for us. Our assiduous pursuit for high quality of our products creates our top-ranking HPE7-S02 study materials and constantly increasing sales volume. Our company has forged a group of professional experts with the excelsior craftsmanship and a mature service system. The quality of our HPE7-S02 Study Materials is high because our experts team organizes and compiles them according to the real exam’s needs and has extracted the essence of all of the information about the test.
HPE7-S02 Reliable Test Tips: https://www.prep4sureguide.com/HPE7-S02-prep4sure-exam-guide.html