Latest Certified-Data-Engineer-Professional Exam Vce, New Certified-Data-Engineer-Professional Study Guide

Our company is a multinational company with sales and after-sale service of Certified-Data-Engineer-Professional exam torrent compiling departments throughout the world. In addition, our company has become the top-notch one in the fields, therefore, if you are preparing for the exam in order to get the related certification, then the Databricks Certified Data Engineer Professional exam question compiled by our company is your solid choice. All employees worldwide in our company operate under a common mission: to be the best global supplier of electronic Certified-Data-Engineer-Professional Exam Torrent for our customers through product innovation and enhancement of customers' satisfaction. Wherever you are in the world we will provide you with the most useful and effectively Certified-Data-Engineer-Professional guide torrent in this website, which will help you to pass the exam as well as getting the related certification with a great ease.
| Section | Objectives |
|---|
| Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Create pipeline components using control flow operators such as if/else and foreach
- 3. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 4. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 5. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 6. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use row filters and column masks to protect sensitive table data
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
>> Latest Certified-Data-Engineer-Professional Exam Vce <<
New Certified-Data-Engineer-Professional Study Guide - Latest Certified-Data-Engineer-Professional Exam Fee
Actual Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) dumps are designed to help applicants crack the Central Finance in Certified-Data-Engineer-Professional test in a short time. There are dozens of websites that offer Certified-Data-Engineer-Professional exam questions. But all of them are not trustworthy. Some of these platforms may provide you with Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) invalid dumps. Upon using outdated Central Finance in Certified-Data-Engineer-Professional dumps you fail in the Certified-Data-Engineer-Professional test and lose your resources. Therefore, it is indispensable to choose a trusted website for real Central Finance in Certified-Data-Engineer-Professional dumps.
Databricks Certified Data Engineer Professional Sample Questions (Q49-Q54):
NEW QUESTION # 49
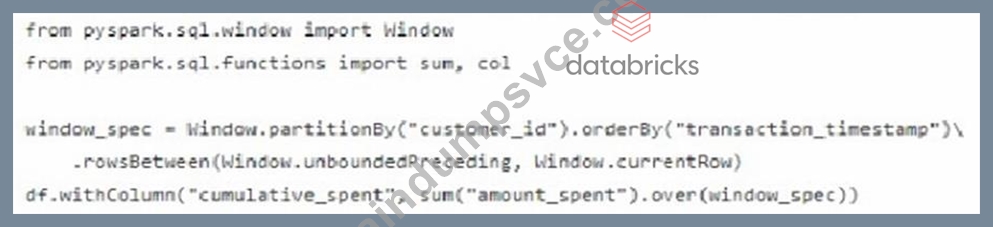
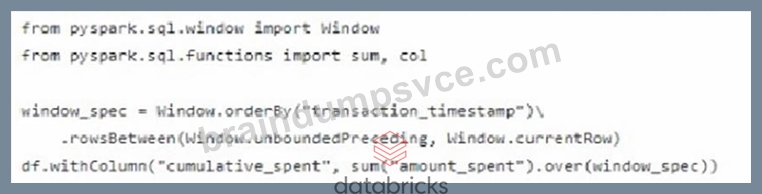
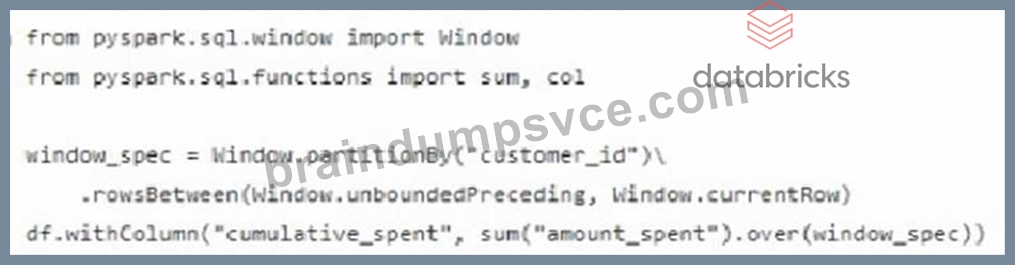
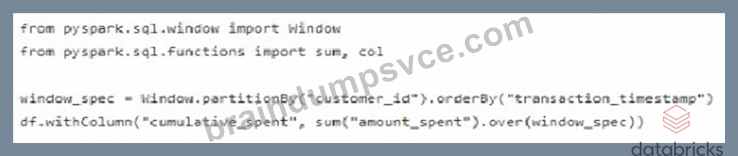
A data engineer is analyzing transactional data in a PySpark DataFrame df containing customer_id, transaction_timestamp (precise to milliseconds), and amount_spent. The objective is to compute a cumulative sum of amount_spent per customer, strictly ordered by transaction_timestamp. The cumulative sum must include all transactions from the earliest timestamp up to and including the current row, respecting temporal ordering within each customer partition. Which PySpark code snippet most accurately constructs the appropriate window specification and applies the aggregation to yield the correct cumulative expenditure per customer?
Answer: A
Explanation:
This window specification partitions the data by customer_id, orders transactions by transaction_timestamp, and defines the frame from the first transaction through the current one.
This guarantees that the cumulative sum is computed independently per customer and strictly follows the temporal order, including all prior transactions up to the current row.
NEW QUESTION # 50
A data engineer is designing a system to process batch patient encounter data stored in an S3 bucket, creating a Delta table (patient_encounters) with columns encounter_id, patient_id, encounter_date, diagnosis_code, and treatment_cost. The table is queried frequently by patient_id and encounter_date, requiring fast performance. Fine-grained access controls must be enforced. The engineer wants to minimize maintenance and boost performance. How should the data engineer create the patient_encounters table?
- A. Create an external table in Unity Catalog, specifying an S3 location for the data files. Enable predictive optimization through table properties, and configure Unity Catalog permissions for access controls.
- B. Create a managed table in Unity Catalog. Configure Unity Catalog permissions for access controls, and rely on predictive optimization to enhance query performance and simplify maintenance.
- C. Create a managed table in Unity Catalog. Configure Unity Catalog permissions for access controls, schedule jobs to run OPTIMIZE and VACUUM commands daily to achieve best performance.
- D. Create a managed table in Hive Metastore. Configure Hive Metastore permissions for access controls, and rely on predictive optimization to enhance query performance and simplify maintenance.
Answer: B
Explanation:
Databricks documentation specifies that Unity Catalog managed tables are the preferred choice for secure, low-maintenance Delta Lake architectures. Managed tables provide full lifecycle management, including metadata, file storage, and access control integration with Unity Catalog.
Fine-grained permissions can be enforced at the column and row level through built-in Unity Catalog governance.
Additionally, Predictive Optimization (Auto Optimize + Auto Compaction) automatically manages file sizes, metadata pruning, and layout optimization, eliminating the need for manual maintenance such as scheduling OPTIMIZE or VACUUM.
External tables (A) require manual path management, and Hive Metastore tables (D) do not support Unity Catalog access policies. Therefore, creating a managed Unity Catalog table with predictive optimization provides both the security and performance benefits needed, making B the correct solution.
NEW QUESTION # 51
Incorporating unit tests into a PySpark application requires upfront attention to the design of your jobs, or a potentially significant refactoring of existing code.
Which statement describes a main benefit that offset this additional effort?
- A. Yields faster deployment and execution times
- B. Improves the quality of your data
- C. Troubleshooting is easier since all steps are isolated and tested individually
- D. Validates a complete use case of your application
- E. Ensures that all steps interact correctly to achieve the desired end result
Answer: C
Explanation:
Unit tests are small, isolated tests that are used to check specific parts of the code, such as functions or classes.
NEW QUESTION # 52
Which statement describes the default execution mode for Databricks Auto Loader?
- A. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; new files are incrementally and impotently into the target Delta Lake table.
- B. New files are identified by listing the input directory; the target table is materialized by directory querying all valid files in the source directory.
- C. Webhook trigger Databricks job to run anytime new data arrives in a source directory; new data automatically merged into target tables using rules inferred from the data.
- D. New files are identified by listing the input directory; new files are incrementally and idempotently loaded into the target Delta Lake table.
- E. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; the target table is materialized by directly querying all valid files in the source directory.
Answer: D
Explanation:
Databricks Auto Loader simplifies and automates the process of loading data into Delta Lake.
The default execution mode of the Auto Loader identifies new files by listing the input directory. It incrementally and idempotently loads these new files into the target Delta Lake table. This approach ensures that files are not missed and are processed exactly once, avoiding data duplication. The other options describe different mechanisms or integrations that are not part of the default behavior of the Auto Loader.
NEW QUESTION # 53
A table in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
- A. Apply the churn model to all rows in the customer_churn_params table, but implement logic to perform an upsert into the predictions table that ignores rows where predictions have not changed.
- B. Calculate the difference between the previous model predictions and the current customer_churn_params on a key identifying unique customers before making new predictions; only make predictions on those customers not in the previous predictions.
- C. Modify the overwrite logic to include a field populated by calling
spark.sql.functions.current_timestamp() as data are being written; use this field to identify records written on a particular date. - D. Replace the current overwrite logic with a merge statement to modify only those records that have changed; write logic to make predictions on the changed records identified by the change data feed.
- E. Convert the batch job to a Structured Streaming job using the complete output mode; configure a Structured Streaming job to read from the customer_churn_params table and incrementally predict against the churn model.
Answer: D
Explanation:
The approach that would simplify the identification of the changed records is to replace the current overwrite logic with a merge statement to modify only those records that have changed, and write logic to make predictions on the changed records identified by the change data feed.
This approach leverages the Delta Lake features of merge and change data feed, which are designed to handle upserts and track row-level changes in a Delta table. By using merge, the data engineering team can avoid overwriting the entire table every night, and only update or insert the records that have changed in the source data. By using change data feed, the ML team can easily access the change events that have occurred in the customer_churn_params table, and filter them by operation type (update or insert) and timestamp. This way, they can only make predictions on the records that have changed in the past 24 hours, and avoid re-processing the unchanged records.
NEW QUESTION # 54
......
One failure makes many candidates fall into despair, become unconfident or even someone want to give up testing for IT certification. Now Certified-Data-Engineer-Professional reliable practice exam online will help you out. It covers most real test questions and will assist you to clear exam certainly. You will be confident in your test. Certified-Data-Engineer-Professional reliable practice exam online will be an important choice for your Databricks certification. Sometimes choice is greater than effort.
New Certified-Data-Engineer-Professional Study Guide: https://www.braindumpsvce.com/Certified-Data-Engineer-Professional_exam-dumps-torrent.html
- 2026 Updated 100% Free Certified-Data-Engineer-Professional – 100% Free Latest Exam Vce | New Databricks Certified Data Engineer Professional Study Guide 🐽 Download ⮆ Certified-Data-Engineer-Professional ⮄ for free by simply searching on ( www.practicevce.com ) 🥈Certified-Data-Engineer-Professional Certified
- Certified-Data-Engineer-Professional New Braindumps Free ⚒ Certified-Data-Engineer-Professional Examcollection Dumps 😳 Certified-Data-Engineer-Professional New APP Simulations 🙌 Download [ Certified-Data-Engineer-Professional ] for free by simply entering ✔ www.pdfvce.com ️✔️ website 📯Certified-Data-Engineer-Professional Trustworthy Exam Content
- Pass Guaranteed Quiz Databricks - Certified-Data-Engineer-Professional - Valid Latest Databricks Certified Data Engineer Professional Exam Vce ☣ Immediately open ➤ www.prepawaypdf.com ⮘ and search for ✔ Certified-Data-Engineer-Professional ️✔️ to obtain a free download 🧣Certified-Data-Engineer-Professional Certified
- Exam Certified-Data-Engineer-Professional PDF 🥟 Practice Certified-Data-Engineer-Professional Exams 🚃 Exam Certified-Data-Engineer-Professional Collection 🙍 Immediately open ⇛ www.pdfvce.com ⇚ and search for ▛ Certified-Data-Engineer-Professional ▟ to obtain a free download 📔Latest Certified-Data-Engineer-Professional Test Cost
- Certified-Data-Engineer-Professional Trustworthy Exam Content 🍿 Online Certified-Data-Engineer-Professional Training 💅 Certified-Data-Engineer-Professional Valid Test Sample 🥮 Download ☀ Certified-Data-Engineer-Professional ️☀️ for free by simply searching on ⏩ www.prepawayete.com ⏪ 😦Certification Certified-Data-Engineer-Professional Dump
- Updated Latest Certified-Data-Engineer-Professional Exam Vce, New Certified-Data-Engineer-Professional Study Guide 🦑 Search for ✔ Certified-Data-Engineer-Professional ️✔️ and easily obtain a free download on ⇛ www.pdfvce.com ⇚ ⌛Exam Certified-Data-Engineer-Professional Collection
- Online Certified-Data-Engineer-Professional Training 😏 Practice Certified-Data-Engineer-Professional Exams 📋 Certified-Data-Engineer-Professional Latest Material 🧐 Search for [ Certified-Data-Engineer-Professional ] on “ www.prep4away.com ” immediately to obtain a free download 🦪Certified-Data-Engineer-Professional Latest Material
- Updated Latest Certified-Data-Engineer-Professional Exam Vce, New Certified-Data-Engineer-Professional Study Guide 💠 Open website ⮆ www.pdfvce.com ⮄ and search for ➡ Certified-Data-Engineer-Professional ️⬅️ for free download 💜Exam Certified-Data-Engineer-Professional PDF
- Certified-Data-Engineer-Professional Real Exam Answers 🏣 Certified-Data-Engineer-Professional Pdf Free ⚔ Certified-Data-Engineer-Professional Latest Learning Materials 🔗 Search on ➽ www.examcollectionpass.com 🢪 for ➡ Certified-Data-Engineer-Professional ️⬅️ to obtain exam materials for free download 🔱Real Certified-Data-Engineer-Professional Torrent
- Efficient Latest Certified-Data-Engineer-Professional Exam Vce, Ensure to pass the Certified-Data-Engineer-Professional Exam ⚪ Open website 《 www.pdfvce.com 》 and search for ⮆ Certified-Data-Engineer-Professional ⮄ for free download 🏵Certified-Data-Engineer-Professional Latest Learning Materials
- Practice Certified-Data-Engineer-Professional Exams 🔀 Certified-Data-Engineer-Professional Latest Material 🎅 Real Certified-Data-Engineer-Professional Torrent ⚡ Open ▶ www.exam4labs.com ◀ and search for ▶ Certified-Data-Engineer-Professional ◀ to download exam materials for free 🟫Certified-Data-Engineer-Professional Latest Learning Materials
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, link.woomy.me, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes