What's more, part of that Test4Engine Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1iKlGQkvB5tHUdRbSjCH12YusF_hYZjgR
Our Data-Engineer-Associate learning questions engage our working staff in understanding customers’ diverse and evolving expectations and incorporate that understanding into our strategies, thus you can 100% trust our Data-Engineer-Associate exam engine. And our professional Data-Engineer-Associate Study Materials determine the high pass rate. According to the research statistics, we can confidently tell that 99% candidates after using our products have passed the Data-Engineer-Associate exam.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion and Transformation | 34% | - Build and manage data pipelines - Ingest and transform data using AWS services |
| Data Store Management | 26% | - Select appropriate data storage solutions - Optimize storage performance and cost |
| Data Operations and Support | 22% | - Monitor and maintain data pipelines - Troubleshoot data workflow issues |
| Data Security and Governance | 18% | - Implement data security controls - Apply governance and compliance best practices |
>> Reliable Data-Engineer-Associate Exam Questions <<
Our Data-Engineer-Associate quiz torrent can provide you with a free trial version, thus helping you have a deeper understanding about our Data-Engineer-Associate test prep and estimating whether this kind of study material is suitable to you or not before purchasing. With the help of our trial version, you will have a closer understanding about our Data-Engineer-Associate Exam Torrent from different aspects, ranging from choice of three different versions available on our test platform to our after-sales service. After you have a try on our Data-Engineer-Associate exam questions, you will love to buy it.
NEW QUESTION # 279
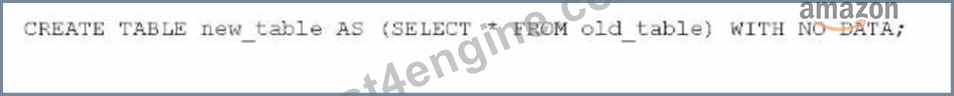
A data engineer needs to create a new empty table in Amazon Athena that has the same schema as an existing table named old-table.
Which SQL statement should the data engineer use to meet this requirement?


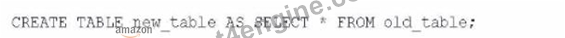
Answer: B
Explanation:
Problem Analysis:
The goal is to create a new empty table in Athena with the same schema as an existing table (old_table).
The solution must avoid copying any data.
Key Considerations:
CREATE TABLE AS (CTAS) is commonly used in Athena for creating new tables based on an existing table.
Adding the WITH NO DATA clause ensures only the schema is copied, without transferring any data.
Solution Analysis:
Option A: Copies both schema and data. Does not meet the requirement for an empty table.
Option B: Inserts data into an existing table, which does not create a new table.
Option C: Creates an empty table but does not copy the schema.
Option D: Creates a new table with the same schema and ensures it is empty by using WITH NO DATA.
Final Recommendation:
Use D. CREATE TABLE new_table AS (SELECT * FROM old_table) WITH NO DATA to create an empty table with the same schema.
Reference:
Athena CTAS Queries
CREATE TABLE Statement in Athena
NEW QUESTION # 280
A hotel management company receives daily data files from each of its hotels. The company wants to upload its data to AWS. The company plans to use Amazon Athena to access the files. The company needs to protect the files from accidental deletion. The company will develop an application on its on-premises servers to automatically forward the files to a fully managed AWS ingestion service.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: B
Explanation:
Amazon Kinesis Data Firehose is a fully managed data ingestion service that enables reliable and scalable delivery of streaming and batch data into Amazon S3 with minimal operational overhead. This directly satisfies the requirement for a fully managed AWS ingestion service while avoiding the need to provision, scale, or manage infrastructure.
By using the Amazon Kinesis Agent on the on-premises servers, the company can automatically forward daily data files to Kinesis Data Firehose. Firehose handles buffering, retry logic, scaling, and delivery without requiring administrative effort. Delivering the data to Amazon S3 allows seamless integration with Amazon Athena, which natively queries data stored in S3 without requiring data movement or transformation.
Enabling Amazon S3 versioning protects files from accidental deletion by preserving previous versions of objects. This aligns with AWS best practices for data durability and governance, especially for analytics workloads and compliance requirements.
Other options introduce unnecessary operational complexity. AWS DataSync with Amazon EFS is not optimized for Athena-based analytics. AWS Glue jobs and Amazon RDS are unsuitable for file-based analytical access. A self-managed Apache Kafka solution with Amazon MSK significantly increases operational overhead.
Therefore, option B is the most efficient, scalable, and operationally optimal solution according to AWS Certified Data Engineer - Associate best practices.
NEW QUESTION # 281
A company saves customer data to an Amazon S3 bucket. The company uses server-side encryption with AWS KMS keys (SSE-KMS) to encrypt the bucket. The dataset includes personally identifiable information (PII) such as social security numbers and account details.
Data that is tagged as PII must be masked before the company uses customer data for analysis. Some users must have secure access to the PII data during the preprocessing phase. The company needs a low- maintenance solution to mask and secure the PII data throughout the entire engineering pipeline.
Which combination of solutions will meet these requirements? (Select TWO.)
Answer: A,E
Explanation:
To address the requirement ofmasking PII dataand ensuring secure access throughout the data pipeline, the combination ofAWS Glue DataBrewandIAMprovides a low-maintenance solution.
* A. AWS Glue DataBrew for Masking:
* AWS Glue DataBrew provides a visual tool to performdata transformations, includingmasking PII data. It allows for easy configuration of data transformation tasks without requiring manual coding, making it ideal for this use case.
Reference:AWS Glue DataBrew
D: AWS Identity and Access Management (IAM):
UsingIAM policiesallows fine-grained control over access to PII data, ensuring that only authorized users can view or process sensitive data during the pipeline stages.
Reference:AWS IAM Best Practices
Alternatives Considered:
B (Amazon GuardDuty): GuardDuty is for threat detection and does not handle data masking or access control for PII.
C (Amazon Macie): Macie can help discover sensitive data but does not handle the masking of PII or access control.
E (Custom scripts): Custom scripting increases the operational burden compared to a built-in solution like DataBrew.
References:
AWS Glue DataBrew for Data Masking
IAM Policies for PII Access Control
NEW QUESTION # 282
A manufacturing company collects sensor data from its factory floor to monitor and enhance operational efficiency. The company uses Amazon Kinesis Data Streams to publish the data that the sensors collect to a data stream. Then Amazon Kinesis Data Firehose writes the data to an Amazon S3 bucket.
The company needs to display a real-time view of operational efficiency on a large screen in the manufacturing facility.
Which solution will meet these requirements with the LOWEST latency?
Answer: C
Explanation:
This solution will meet the requirements with the lowest latency because it uses Amazon Managed Service for Apache Flink to process the sensor data in real time and write it to Amazon Timestream, a fast, scalable, and serverless time series database. Amazon Timestream is optimized for storing and analyzing time series data, such as sensor data, and can handle trillions of events per day with millisecond latency. By using Amazon Timestream as a source, you can create an Amazon QuickSight dashboard that displays a real-time view of operational efficiency on a large screen in the manufacturing facility. Amazon QuickSight is a fully managed business intelligence service that can connect to various data sources, including Amazon Timestream, and provide interactive visualizations and insights123.
The other options are not optimal for the following reasons:
* A. Use Amazon Managed Service for Apache Flink (previously known as Amazon Kinesis Data Analytics) to process the sensor data. Use a connector for Apache Flink to write data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard. This option is similar to option C, but it uses Grafana instead of Amazon QuickSight to create the dashboard.
Grafana is an open source visualization tool that can also connect to Amazon Timestream, but it requires additional steps to set up and configure, such as deploying a Grafana server on Amazon EC2, installing the Amazon Timestream plugin, and creating an IAM role for Grafana to access Timestream.
These steps can increase the latency and complexity of the solution.
* B. Configure the S3 bucket to send a notification to an AWS Lambda function when any new object is created. Use the Lambda function to publish the data to Amazon Aurora. Use Aurora as a source to create an Amazon QuickSight dashboard. This option is not suitable for displaying a real-time view of operational efficiency, as it introduces unnecessary delays and costs in the data pipeline. First, the sensor data is written to an S3 bucket by Amazon Kinesis Data Firehose, which can have a buffering interval of up to 900 seconds. Then, the S3 bucket sends a notification to a Lambda function, which can incur additional invocation and execution time. Finally, the Lambda function publishes the data to Amazon Aurora, a relational database that is not optimized for time series data and can have higher storage and performance costs than Amazon Timestream .
* D. Use AWS Glue bookmarks to read sensor data from the S3 bucket in real time. Publish the data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard.
This option is also not suitable for displaying a real-time view of operational efficiency, as it uses AWS Glue bookmarks to read sensor data from the S3 bucket. AWS Glue bookmarks are a feature that helps AWS Glue jobs and crawlers keep track of the data that has already been processed, so that they can resume from where they left off. However, AWS Glue jobs and crawlers are not designed for real-time data processing, as they can have a minimum frequency of 5 minutes and a variable start-up time.
Moreover, this option also uses Grafana instead of Amazon QuickSight to create the dashboard, which can increase the latency and complexity of the solution .
References:
* 1: Amazon Managed Streaming for Apache Flink
* 2: Amazon Timestream
* 3: Amazon QuickSight
* : Analyze data in Amazon Timestream using Grafana
* : Amazon Kinesis Data Firehose
* : Amazon Aurora
* : AWS Glue Bookmarks
* : AWS Glue Job and Crawler Scheduling
NEW QUESTION # 283
A technology company currently uses Amazon Kinesis Data Streams to collect log data in real time. The company wants to use Amazon Redshift for downstream real-time queries and to enrich the log data.
Which solution will ingest data into Amazon Redshift with the LEAST operational overhead?
Answer: A
Explanation:
The most efficient and low-operational-overhead solution for ingesting data into Amazon Redshift from Amazon Kinesis Data Streams is to use Amazon Redshift streaming ingestion. This feature allows Redshift to directly ingest streaming data from Kinesis Data Streams and process it in real-time.
* Amazon Redshift Streaming Ingestion:
* Redshift supports native streaming ingestion from Kinesis Data Streams, allowing real-time data to be queried using materialized views.
* This solution reduces operational complexity because you don't need intermediary services like Amazon Kinesis Data Firehose or S3 for batch loading.
NEW QUESTION # 284
......
You many face many choices of attending the certificate exams and there are a variety of certificates for you to get. You want to get the most practical and useful certificate which can reflect your ability in some area. If you choose to attend the test Data-Engineer-Associate certification buying our Data-Engineer-Associate exam guide can help you pass the test and get the valuable certificate. Our company has invested a lot of personnel, technology and capitals on our products and is always committed to provide the top-ranking Data-Engineer-Associate Study Material to the clients and serve for the client wholeheartedly.
Reliable Data-Engineer-Associate Exam Pdf: https://www.test4engine.com/Data-Engineer-Associate_exam-latest-braindumps.html
BTW, DOWNLOAD part of Test4Engine Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1iKlGQkvB5tHUdRbSjCH12YusF_hYZjgR