Maximize Your Chances of Getting Databricks-Certified-Professional-Data-Engineer Exam

For the Databricks-Certified-Professional-Data-Engineer web-based practice exam no special software installation is required. because it is a browser-based Databricks-Certified-Professional-Data-Engineer practice test. The web-based Databricks Certified Professional Data Engineer Exam practice exam works on all operating systems like Mac, Linux, iOS, Android, and Windows. In the same way, IE, Firefox, Opera and Safari, and all the major browsers support the web-based Databricks Databricks-Certified-Professional-Data-Engineer Practice Test. So it requires no special plugins.
| Section | Weight | Objectives |
|---|
| Topic 1: Ensuring Data Security and Compliance | 10% | - Compliance standards implementation
- Data encryption and masking
- Access control and permissions
|
| Topic 2: Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion
- Schema inference and evolution
- Connecting to diverse data sources
|
| Topic 3: Data Transformation, Cleansing, and Quality | 10% | - Data validation and quality checks
- Standardization and normalization
- Handling missing or inconsistent data
|
| Topic 4: Data Modelling | 6% | - Delta Lake table design
- Schema design and management
- Medallion Architecture implementation
|
| Topic 5: Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools
- Batch and incremental processing logic
- Data transformation and aggregation
|
| Topic 6: Monitoring and Alerting | 10% | - Pipeline observability and logging
- Performance and health monitoring
- Setting up alerts and notifications
|
| Topic 7: Cost & Performance Optimisation | 13% | - Query optimization and caching
- Cluster configuration and scaling
- Storage optimization (partitioning, Z-order, indexing)
|
| Topic 8: Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs
- Troubleshooting pipelines and errors
- CI/CD and DevOps practices
|
| Topic 9: Data Governance | 7% | - Unity Catalog management
- Data lineage and metadata tracking
- Policy enforcement
|
| Topic 10: Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access
- Unity Catalog data sharing
|
>> Databricks-Certified-Professional-Data-Engineer Exam Online <<
Databricks-Certified-Professional-Data-Engineer Exam Certification - New Databricks-Certified-Professional-Data-Engineer Test Syllabus
It is well known, to get the general respect of the community needs to be achieved by acquiring knowledge, and a harvest. Society will never welcome lazy people, and luck will never come to those who do not. We must continue to pursue own life value, such as get the test Databricks-Certified-Professional-Data-Engineer Certification, not only to meet what we have now, but also to constantly challenge and try something new and meaningful.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q160-Q165):
NEW QUESTION # 160
A data engineer has configured their Databricks Asset Bundle with multiple targets in databricks.yml and deployed it to the production workspace. Now, to validate the deployment, they need to invoke a job named my_project_job specifically within the prod target context. Assuming the job is already deployed, they need to trigger its execution while ensuring the target-specific configuration is respected.
Which command will trigger the job execution?
- A. databricks execute my_project_job -e prod
- B. databricks run my_project_job -t prod
- C. databricks bundle run my_project_job -t prod
- D. databricks job run my_project_job --env prod
Answer: C
Explanation:
Databricks Asset Bundles (DABs) enable declarative configuration and deployment of Databricks resources such as jobs, pipelines, and dashboards across multiple environments.
Once deployed, jobs can be executed in a specific target context using the databricks bundle run command, which ensures all environment-specific configurations from the bundle definition (such as parameters, cluster settings, and workspace URLs) are respected.
The -t flag specifies the target environment (e.g., dev, staging, or prod). This ensures that the execution runs with the correct configuration defined under that target in databricks.yml.
Other options (A, B, and C) are invalid because they reference deprecated or incorrect command syntax that doesn't integrate with bundle targets. Therefore, D is the correct and verified answer.
NEW QUESTION # 161
Which approach demonstrates a modular and testable way to use DataFrame.transform for ETL code in PySpark?
- A. def upper_transform(df):
return df.withColumn( " value_upper " , upper(col( " value " )))
actual = test_input.transform(upper_transform)
assertDataFrameEqual(actual, expected) - B. def upper_value(df):
return df.withColumn( " value_upper " , upper(col( " value " )))
def filter_positive(df):
return df.filter(df[ " id " ] > 0)
pipeline_df = df.transform(upper_value).transform(filter_positive) - C. class Pipeline:
def transform(self, df):
return df.withColumn( " value_upper " , upper(col( " value " )))
pipeline = Pipeline()
assertDataFrameEqual(pipeline.transform(test_input), expected) - D. def transform_data(input_df):
# transformation logic here
return output_df
test_input = spark.createDataFrame([(1, " a " )], [ " id " , " value " ]) assertDataFrameEqual(transform_data(test_input), expected)
Answer: B
Explanation:
Databricks and Apache Spark recommend building modular and reusable ETL transformations by leveraging the DataFrame.transform() API. This method allows you to chain multiple transformation functions in a clean and testable way.
* Option A : Encapsulating the logic in a class (Pipeline) works, but it reduces modularity and flexibility.
It does not show the true intended use of DataFrame.transform() which is chaining functional transformations.
* Option B : This is the correct approach. It defines small, reusable functions (upper_value, filter_positive) that each take a DataFrame and return a transformed DataFrame. By chaining them with df.transform(func), you can compose ETL pipelines in a clear and declarative manner. This enables unit testing of individual functions and makes the ETL pipeline modular, testable, and production- ready.
* Option C : This shows a single transformation wrapped in a function and tested, but it lacks pipeline composition - it is not demonstrating modular chaining across multiple transformations.
* Option D : This simply defines a transformation function with hardcoded logic. It does not leverage DataFrame.transform() nor demonstrate modularity through composition.
Therefore, Option B is the best demonstration of how to use DataFrame.transform() in PySpark ETL pipelines.
Databricks documentation explicitly highlights that DataFrame.transform() allows developers to "chain together reusable functions in a readable and modular way, improving testability and maintainability of ETL code." This makes B the correct and officially supported pattern.
NEW QUESTION # 162
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert:
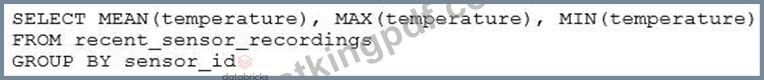
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120. Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
- A. The average temperature recordings for at least one sensor exceeded 120 on three consecutive executions of the query
- B. The recent_sensor_recordingstable was unresponsive for three consecutive runs of the query
- C. The total average temperature across all sensors exceeded 120 on three consecutive executions of the query
- D. The maximum temperature recording for at least one sensor exceeded 120 on three consecutive executions of the query
- E. The source query failed to update properly for three consecutive minutes and then restarted
Answer: A
Explanation:
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120. Verified References: [Databricks Certified Data Engineer Professional], under "SQL Analytics" section; Databricks Documentation, under "Alerts" section.
NEW QUESTION # 163
Which statement characterizes the general programming model used by Spark Structured Streaming?
- A. Structured Streaming leverages the parallel processing of GPUs to achieve highly parallel data throughput.
- B. Structured Streaming uses specialized hardware and I/O streams to achieve sub-second latency for data transfer.
- C. Structured Streaming relies on a distributed network of nodes that hold incremental state values for cached stages.
- D. Structured Streaming is implemented as a messaging bus and is derived from Apache Kafka.
- E. Structured Streaming models new data arriving in a data stream as new rows appended to an unbounded table.
Answer: D
Explanation:
This is the correct answer because it characterizes the general programming model used by Spark Structured Streaming, which is to treat a live data stream as a table that is being continuously appended. This leads to a new stream processing model that is very similar to a batch processing model, where users can express their streaming computation using the same Dataset/DataFrame API as they would use for static data. The Spark SQL engine will take care of running the streaming query incrementally and continuously and updating the final result as streaming data continues to arrive. Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Overview" section.
NEW QUESTION # 164
The marketing team is looking to share data in an aggregate table with the sales organization, but the field names used by the teams do not match, and a number of marketing specific fields have not been approval for the sales org.
Which of the following solutions addresses the situation while emphasizing simplicity?
- A. Create a new table with the required schema and use Delta Lake's DEEP CLONE functionality to sync up changes committed to one table to the corresponding table.
- B. Create a view on the marketing table selecting only these fields approved for the sales team alias the names of any fields that should be standardized to the sales naming conventions.
- C. Use a CTAS statement to create a derivative table from the marketing table configure a production jon to propagation changes.
- D. Add a parallel table write to the current production pipeline, updating a new sales table that varies as required from marketing table.
Answer: B
Explanation:
Creating a view is a straightforward solution that can address the need for field name standardization and selective field sharing between departments. A view allows for presenting a transformed version of the underlying data without duplicating it. In this scenario, the view would only include the approved fields for the sales team and rename any fields as per their naming conventions.
Reference:
Databricks documentation on using SQL views in Delta Lake: https://docs.databricks.com/delta/quick-start.html#sql-views
NEW QUESTION # 165
......
Whereas the Databricks Databricks-Certified-Professional-Data-Engineer web-based version of our practice test is compatible with iOS, Android, Windows, Linux, and Mac. Additionally, you can take the Databricks Databricks-Certified-Professional-Data-Engineer web-based practice test online using Chrome, Firefox, Safari, MS Edge, Internet Explorer or any other popular browser.
Databricks-Certified-Professional-Data-Engineer Exam Certification: https://www.testkingpdf.com/Databricks-Certified-Professional-Data-Engineer-testking-pdf-torrent.html
- Test Databricks-Certified-Professional-Data-Engineer Dumps 🤭 Databricks-Certified-Professional-Data-Engineer Exam Pattern 🍔 Databricks-Certified-Professional-Data-Engineer Exam Certification 🐺 Copy URL ⮆ www.pdfdumps.com ⮄ open and search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ to download for free 🤸Databricks-Certified-Professional-Data-Engineer Mock Test
- Databricks-Certified-Professional-Data-Engineer test-preparation routine proven to help you pass the exams 🟨 Search for 【 Databricks-Certified-Professional-Data-Engineer 】 and download it for free on [ www.pdfvce.com ] website 🚘Databricks-Certified-Professional-Data-Engineer Study Demo
- Databricks-Certified-Professional-Data-Engineer test-preparation routine proven to help you pass the exams 🦺 Immediately open ✔ www.examdiscuss.com ️✔️ and search for ( Databricks-Certified-Professional-Data-Engineer ) to obtain a free download 🍿Exam Databricks-Certified-Professional-Data-Engineer Vce
- Databricks-Certified-Professional-Data-Engineer Latest Exam Question ☔ Practice Databricks-Certified-Professional-Data-Engineer Test Engine 🍈 Latest Databricks-Certified-Professional-Data-Engineer Dumps Files 😩 Immediately open ➥ www.pdfvce.com 🡄 and search for 「 Databricks-Certified-Professional-Data-Engineer 」 to obtain a free download 🥑Study Databricks-Certified-Professional-Data-Engineer Materials
- Databricks Certified Professional Data Engineer Exam actual questions - Databricks-Certified-Professional-Data-Engineer torrent pdf - Databricks Certified Professional Data Engineer Exam training vce 🦐 Copy URL ✔ www.easy4engine.com ️✔️ open and search for { Databricks-Certified-Professional-Data-Engineer } to download for free 🐇Test Databricks-Certified-Professional-Data-Engineer Dumps
- Practice Databricks-Certified-Professional-Data-Engineer Test Engine 🚂 Databricks-Certified-Professional-Data-Engineer Exam Engine 🍆 Latest Databricks-Certified-Professional-Data-Engineer Dumps Files 🚎 Download ➤ Databricks-Certified-Professional-Data-Engineer ⮘ for free by simply entering ➡ www.pdfvce.com ️⬅️ website 🔑Databricks-Certified-Professional-Data-Engineer Latest Exam Question
- Databricks-Certified-Professional-Data-Engineer Valid Torrent 🧅 Databricks-Certified-Professional-Data-Engineer Exam Pattern 🍐 Databricks-Certified-Professional-Data-Engineer Exam Certification 👯 ⇛ www.examcollectionpass.com ⇚ is best website to obtain ➽ Databricks-Certified-Professional-Data-Engineer 🢪 for free download 🥉Databricks-Certified-Professional-Data-Engineer Study Demo
- Databricks-Certified-Professional-Data-Engineer Exam Dumps.zip 🤏 Databricks-Certified-Professional-Data-Engineer Exam Certification 🙆 Databricks-Certified-Professional-Data-Engineer Valid Torrent 🍊 ( www.pdfvce.com ) is best website to obtain ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ for free download 🖊Databricks-Certified-Professional-Data-Engineer Latest Exam Question
- Databricks-Certified-Professional-Data-Engineer test-preparation routine proven to help you pass the exams 🚤 Easily obtain ➤ Databricks-Certified-Professional-Data-Engineer ⮘ for free download through ☀ www.vce4dumps.com ️☀️ 🚐New Databricks-Certified-Professional-Data-Engineer Test Papers
- 100% Pass Databricks-Certified-Professional-Data-Engineer - High Pass-Rate Databricks Certified Professional Data Engineer Exam Exam Online 🦛 ⇛ www.pdfvce.com ⇚ is best website to obtain 【 Databricks-Certified-Professional-Data-Engineer 】 for free download 🐰Databricks-Certified-Professional-Data-Engineer Study Demo
- Databricks-Certified-Professional-Data-Engineer Study Demo 🦺 Authorized Databricks-Certified-Professional-Data-Engineer Exam Dumps 🐈 Reliable Databricks-Certified-Professional-Data-Engineer Exam Topics 🤛 Search for “ Databricks-Certified-Professional-Data-Engineer ” and download it for free on ➽ www.prepawaypdf.com 🢪 website 🏟New Databricks-Certified-Professional-Data-Engineer Study Notes
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes