BONUS!!! Download part of PassReview MLA-C01 dumps for free: https://drive.google.com/open?id=1mS-8RMVFe-_-QfRVLXZsKIzqJSWe-hM7
In order to make all customers feel comfortable, our company will promise that we will offer the perfect and considerate service for all customers. If you buy the MLA-C01 training files from our company, you will have the right to enjoy the perfect service. We have employed a lot of online workers to help all customers solve their problem. If you have any questions about the MLA-C01 learning dumps, do not hesitate and ask us in your anytime, we are glad to answer your questions and help you use our MLA-C01 study questions well. We believe our perfect service will make you feel comfortable when you are preparing for your exam.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Available Languages: | Simplified Chinese, Korean, Traditional Chinese, English, Japanese |
| Real Exam Qty: | 85 |
| Exam Price: | 150 USD |
| Passing Score: | 1000-2000 scaled score (passing score approximately 720) |
| Certificate Validity Period: | 3 years |
| Exam Duration: | 170 minutes |
| Related Certifications: | AWS Certified Data Engineer - Associate AWS Certified Developer - Associate AWS Certified Solutions Architect - Associate |
| Exam Format: | Multiple choice, Multiple response |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored (Pearson VUE) or in-person testing center |
| Pre Condition: | Recommended: 2+ years of ML engineering experience, familiarity with AWS ML services |
| Official Syllabus URL: | https://aws.amazon.com/certification/certified-machine-learning-engineer-associate/ |
Everyone wishes to spend their career at one level. Obtaining a AWS Certified Machine Learning Engineer - Associate MLA-C01 certificate is the reason that many people join the Amazon MLA-C01 exam. They can be sure of earning promotions and higher pay at their current job with this credential. While attempting career growth is crucial, you can only do so after clearing the AWS Certified Machine Learning Engineer - Associate MLA-C01 Exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 18
An ML engineer is analyzing potential biases in a customer dataset before training an ML model. The dataset contains customer age (numeric), product reviews (text), and purchase outcomes (categorical).
Which statistical metrics should the ML engineer use to identify potential biases in the dataset before model training?
Answer: B
Explanation:
Bias detection is a critical step in responsible machine learning and is emphasized in AWS documentation, particularly in Amazon SageMaker Clarify. When analyzing structured datasets that include sensitive or influential attributes such as age, AWS recommends evaluating label distribution fairness and group-based outcome differences before training a model.
The class imbalance metric helps identify whether certain outcomes (for example, purchase vs. no purchase) are overrepresented or underrepresented. Severe imbalance can cause models to favor majority classes, leading to biased predictions. AWS explicitly highlights class imbalance as a key issue to assess during data exploration.
The Difference in Proportions of Labels (DPL) is a fairness metric supported by SageMaker Clarify that measures whether outcome labels are disproportionately distributed across different groups, such as age ranges. DPL compares the proportion of favorable outcomes between groups, making it especially effective for identifying demographic bias in categorical labels.
Options A and D focus on descriptive statistics or correlations, which are useful for data understanding but do not directly measure bias or fairness. Option B partially addresses imbalance and sentiment but sentiment analysis of reviews alone does not quantify demographic bias tied to outcomes.
AWS documentation strongly recommends using group fairness metrics, including DPL, alongside class imbalance checks to identify bias before training. These metrics provide actionable insights into whether a dataset may lead to unfair or skewed model behavior.
Therefore, Option C is the most appropriate and AWS-aligned choice.
NEW QUESTION # 19
A company needs to update the model definition of an existing Amazon SageMaker Al endpoint.
Select and order the correct steps from the following list to update the model definition settings with the LEAST interruption of inferences. Select each step one time or not at all. (Select and order THREE.)
* Create a new endpoint configuration that uses the new model definition.
* Create a new model definition with updated settings by using the CreateModel action in the SageMaker AI API.
* Delete the endpoint that needs to be updated and recreate the endpoint with the new endpoint configuration.
* Delete the IAM role and permissions for the ExecutionRoleArn parameter.
* Update the endpoint with the new endpoint configuration.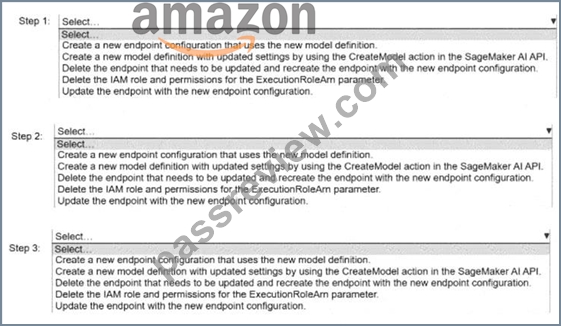
Answer:
Explanation: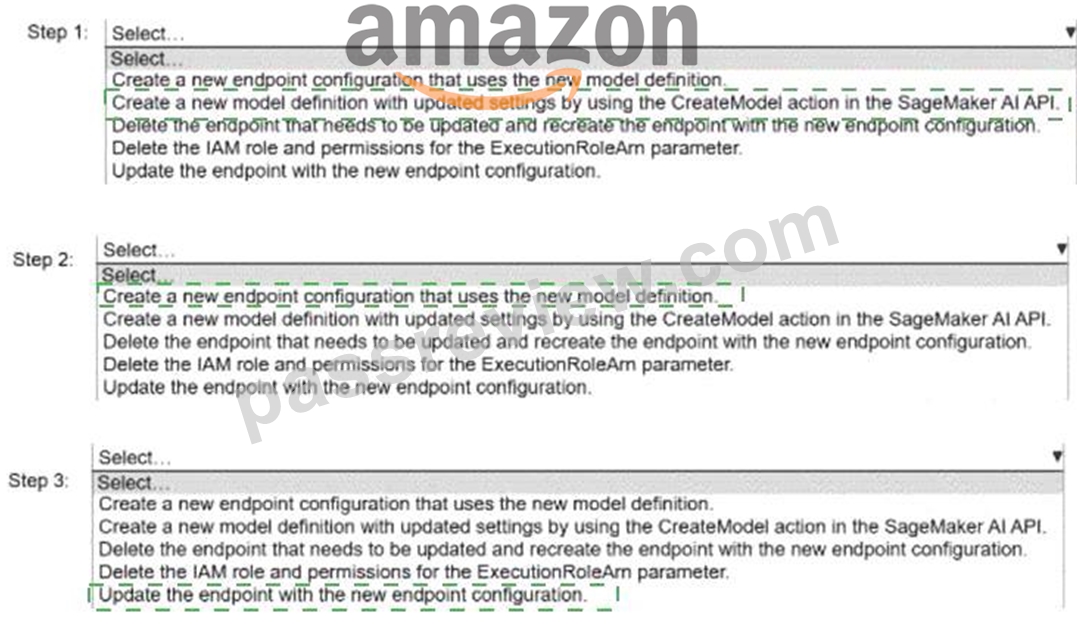
Explanation:
Step 1: Create a new model definition with updated settings by using the CreateModel action in the SageMaker AI API.
Step 2: Create a new endpoint configuration that uses the new model definition.
Step 3: Update the endpoint with the new endpoint configuration.
Do not delete and recreate the endpoint. That causes unnecessary inference interruption. SageMaker endpoint updates are designed to use a new EndpointConfig; AWS explicitly states that to update an endpoint, you must create a new endpoint configuration, then call UpdateEndpoint on the existing endpoint. During the update, SageMaker changes the endpoint to Updating and then back to InService.
NEW QUESTION # 20
A company wants to migrate ML models from an on-premises environment to Amazon SageMaker AI. The models are based on the PyTorch algorithm. The company needs to reuse its existing custom scripts as much as possible.
Which SageMaker AI feature should the company use?
Answer: C
Explanation:
SageMaker script mode allows ML engineers to bring existing training scripts written for frameworks such as PyTorch and TensorFlow directly into SageMaker with minimal changes. AWS documentation explicitly states that script mode is designed to support migration of existing ML workloads.
With script mode, the user provides a custom training script, and SageMaker handles infrastructure provisioning, distributed training, logging, and model artifact storage. This makes script mode ideal for companies that want to reuse established codebases without rewriting them.
Built-in algorithms require adopting AWS-provided implementations. SageMaker Canvas is a no-code tool, and JumpStart provides pretrained models and templates but does not focus on custom script reuse.
Therefore, Option D is the correct and AWS-recommended choice.
NEW QUESTION # 21
A company wants to use large language models (LLMs) that are supported by Amazon Bedrock to develop a chat interface for the company ' s internal technical documentation. The company stores the documentation as dozens of text files that are several megabytes in total size. The company updates the text files often.
Which solution will meet these requirements MOST cost-effectively?
Answer: D
Explanation:
Option D is correct because Amazon Bedrock Knowledge Bases are designed for applications that need to answer questions using private documents without retraining or repeatedly fine-tuning a foundation model.
AWS documentation states that with Amazon Bedrock Knowledge Bases , you can build applications enriched by context retrieved from a knowledge base, and that this provides an out-of-the-box RAG solution
. AWS also explicitly says that adding a knowledge base increases cost-effectiveness by removing the need to continually train your model to use your private data. That matches this use case very closely.
The question also says the documentation consists of text files that are only several megabytes total and are updated often . A retrieval-based approach is more economical and operationally simpler than creating a new model or repeatedly fine-tuning one whenever the documents change. AWS documentation for Bedrock knowledge bases describes adding data sources and running ingestion jobs to process and index the content, which is exactly the pattern needed for frequently updated internal documentation used by a chat interface.
The other options are not as cost-effective. Creating a new LLM is far beyond the need here. Guardrails help control model behavior and policy enforcement, but they do not serve as a document retrieval layer for internal documentation. Fine-tuning a model on frequently changing text files is usually more expensive and less flexible than using retrieval augmentation. For a modest-sized, frequently updated documentation corpus, the AWS-native and most cost-effective solution is to load the files into an Amazon Bedrock knowledge base and use it to provide context at inference time. Therefore, the best verified answer is D .
NEW QUESTION # 22
A travel company wants to create an ML model to recommend the next airport destination for its users. The company has collected millions of data records about user location, recent search history on the company's website, and 2,000 available airports. The data has several categorical features with a target column that is expected to have a high-dimensional sparse matrix.
The company needs to use Amazon SageMaker AI built-in algorithms for the model. An ML engineer converts the categorical features by using one-hot encoding.
Which algorithm should the ML engineer implement to meet these requirements?
Answer: B
Explanation:
This problem describes a recommendation system with millions of records, many categorical variables, and a high-dimensional sparse feature space created by one-hot encoding. AWS documentation explicitly recommends Amazon SageMaker Factorization Machines (FM) for such use cases.
Factorization Machines are designed to handle sparse datasets efficiently and to model interactions between categorical features without explicitly enumerating all feature combinations. This capability makes FM particularly well-suited for recommendation problems such as predicting user-item interactions, including destination recommendations.
With 2,000 possible airport destinations, the target space is large and sparse. One-hot encoding further increases sparsity. Factorization Machines address this challenge by learning latent factors that capture relationships between features, even when many feature combinations are rarely observed.
Option A (CatBoost) is not an Amazon SageMaker built-in algorithm and therefore does not meet the requirement. Option B (DeepAR) is a time-series forecasting algorithm, not intended for recommendation or classification problems. Option D (k-means) is an unsupervised clustering algorithm and cannot directly predict a specific destination label.
AWS documentation explicitly lists recommendation systems and click prediction as primary use cases for the SageMaker Factorization Machines algorithm.
Therefore, Option C is the correct and AWS-verified choice.
NEW QUESTION # 23
......
Dump MLA-C01 File: https://www.passreview.com/MLA-C01_exam-braindumps.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by PassReview: https://drive.google.com/open?id=1mS-8RMVFe-_-QfRVLXZsKIzqJSWe-hM7