BONUS!!! Download part of Actual4Exams Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=1o9yr1MmyqdnuagjLiuVn3QRX2-QGZZaM
During review, you can contact with our after-sales if there are any problems with our Databricks-Generative-AI-Engineer-Associate exam torrent. They will help you 24/7 all the time. These services assure you avoid any loss. Besides, our passing rate of Databricks-Generative-AI-Engineer-Associate practice materials has reached up to 98 to 100 percent up to now, so you cannot miss this opportunity. Besides, free updates of Databricks-Generative-AI-Engineer-Associate Exam Torrent will be sent to your mailbox freely for one year, hope you can have a great experience during usage of our practice materials.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Generative AI Engineer Associate |
| Exam Price: | $200 USD |
| Real Exam Qty: | 45 |
| Exam Format: | Multiple Choice, Multiple Select |
| Related Certifications: | Databricks Certified Machine Learning Associate Databricks Certified Data Engineer Associate |
| Available Languages: | Portuguese (Brazil), English, Korean, Japanese |
| Passing Score: | Scaled Score (approx. 70%) |
| Exam Duration: | 90 minutes |
| Certificate Validity Period: | 2 years |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online (Proctored) or Test Center |
| Pre Condition: | None (Recommended: 6+ months hands-on experience) |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> Databricks-Generative-AI-Engineer-Associate Pass4sure <<
Compared to other products in the industry, our Databricks-Generative-AI-Engineer-Associate actual exam has a higher pass rate. If you really want to pass the exam, this must be the one that makes you feel the most suitable and effective. According the data which is provided and tested by our loyal customers, our pass rate of the Databricks-Generative-AI-Engineer-Associate Exam Questions is high as 98% to 100%. It is hard to find such high pass rate in the market. And the quality of the Databricks-Generative-AI-Engineer-Associate training guide won't let you down.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 23
A Generative Al Engineer is helping a cinema extend its website's chat bot to be able to respond to questions about specific showtimes for movies currently playing at their local theater. They already have the location of the user provided by location services to their agent, and a Delta table which is continually updated with the latest showtime information by location. They want to implement this new capability In their RAG application.
Which option will do this with the least effort and in the most performant way?
Answer: D
Explanation:
The task is to extend a cinema chatbot to provide movie showtime information using a RAG application, leveraging user location and a continuously updated Delta table, with minimal effort and high performance. Let's evaluate the options.
Option A: Create a Feature Serving Endpoint from a FeatureSpec that references an online store synced from the Delta table. Query the Feature Serving Endpoint as part of the agent logic / tool implementation Databricks Feature Serving provides low-latency access to real-time data from Delta tables via an online store. Syncing the Delta table to a Feature Serving Endpoint allows the chatbot to query showtimes efficiently, integrating seamlessly into the RAG agent's tool logic. This leverages Databricks' native infrastructure, minimizing effort and ensuring performance.
Databricks Reference: "Feature Serving Endpoints provide real-time access to Delta table data with low latency, ideal for production systems" ("Databricks Feature Engineering Guide," 2023).
Option B: Query the Delta table directly via a SQL query constructed from the user's input using a text-to-SQL LLM in the agent logic / tool Using a text-to-SQL LLM to generate queries adds complexity (e.g., ensuring accurate SQL generation) and latency (LLM inference + SQL execution). While feasible, it's less performant and requires more effort than a pre-built serving solution.
Databricks Reference: "Direct SQL queries are flexible but may introduce overhead in real-time applications" ("Building LLM Applications with Databricks").
Option C: Write the Delta table contents to a text column, then embed those texts using an embedding model and store these in the vector index. Look up the information based on the embedding as part of the agent logic / tool implementation Converting structured Delta table data (e.g., showtimes) into text, embedding it, and using vector search is inefficient for structured lookups. It's effort-intensive (preprocessing, embedding) and less precise than direct queries, undermining performance.
Databricks Reference: "Vector search excels for unstructured data, not structured tabular lookups" ("Databricks Vector Search Documentation").
Option D: Set up a task in Databricks Workflows to write the information in the Delta table periodically to an external database such as MySQL and query the information from there as part of the agent logic / tool implementation Exporting to an external database (e.g., MySQL) adds setup effort (workflow, external DB management) and latency (periodic updates vs. real-time). It's less performant and more complex than using Databricks' native tools.
Databricks Reference: "Avoid external systems when Delta tables provide real-time data natively" ("Databricks Workflows Guide").
Conclusion: Option A minimizes effort by using Databricks Feature Serving for real-time, low-latency access to the Delta table, ensuring high performance in a production-ready RAG chatbot.
NEW QUESTION # 24
A Generative AI Engineer is designing an LLM-powered live sports commentary platform. The platform provides real-time updates and LLM-generated analyses for any users who would like to have live summaries, rather than reading a series of potentially outdated news articles.
Which tool below will give the platform access to real-time data for generating game analyses based on the latest game scores?
Answer: B
Explanation:
* Problem Context: The engineer is developing an LLM-powered live sports commentary platform that needs to provide real-time updates and analyses based on the latest game scores. The critical requirement here is the capability to access and integrate real-time data efficiently with the platform for immediate analysis and reporting.
* Explanation of Options:
* Option A: DatabricksIQ: While DatabricksIQ offers integration and data processing capabilities, it is more aligned with data analytics rather than real-time feature serving, which is crucial for immediate updates necessary in a live sports commentary context.
* Option B: Foundation Model APIs: These APIs facilitate interactions with pre-trained models and could be part of the solution, but on their own, they do not provide mechanisms to access real- time game scores.
* Option C: Feature Serving: This is the correct answer as feature serving specifically refers to the real-time provision of data (features) to models for prediction. This would be essential for an LLM that generates analyses based on live game data, ensuring that the commentary is current and based on the latest events in the sport.
* Option D: AutoML: This tool automates the process of applying machine learning models to real-world problems, but it does not directly provide real-time data access, which is a critical requirement for the platform.
Thus,Option C(Feature Serving) is the most suitable tool for the platform as it directly supports the real-time data needs of an LLM-powered sports commentary system, ensuring that the analyses and updates are based on the latest available information.
NEW QUESTION # 25
A Generative Al Engineer wants their (inetuned LLMs in their prod Databncks workspace available for testing in their dev workspace as well. All of their workspaces are Unity Catalog enabled and they are currently logging their models into the Model Registry in MLflow.
What is the most cost-effective and secure option for the Generative Al Engineer to accomplish their gAi?
Answer: C
Explanation:
The goal is to make fine-tuned LLMs from a production (prod) Databricks workspace available for testing in a development (dev) workspace, leveraging Unity Catalog and MLflow, while ensuring cost-effectiveness and security. Let's analyze the options.
Option A: Use an external model registry which can be accessed from all workspaces An external registry adds cost (e.g., hosting fees) and complexity (e.g., integration, security configurations) outside Databricks' native ecosystem, reducing security compared to Unity Catalog's governance.
Databricks Reference: "Unity Catalog provides a centralized, secure model registry within Databricks" ("Unity Catalog Documentation," 2023).
Option B: Setup a script to export the model from prod and import it to dev Export/import scripts require manual effort, storage for model artifacts, and repeated execution, increasing operational cost and risk (e.g., version mismatches, unsecured transfers). It's less efficient than a native solution.
Databricks Reference: Manual processes are discouraged when Unity Catalog offers built-in sharing: "Avoid redundant workflows with Unity Catalog's cross-workspace access" ("MLflow with Unity Catalog").
Option C: Setup a duplicate training pipeline in dev, so that an identical model is available in dev Duplicating the training pipeline doubles compute and storage costs, as it retrains the model from scratch. It's neither cost-effective nor necessary when the prod model can be reused securely.
Databricks Reference: "Re-running training is resource-intensive; leverage existing models where possible" ("Generative AI Engineer Guide").
Option D: Use MLflow to log the model directly into Unity Catalog, and enable READ access in the dev workspace to the model Unity Catalog, integrated with MLflow, allows models logged in prod to be centrally managed and accessed across workspaces with fine-grained permissions (e.g., READ for dev). This is cost-effective (no extra infrastructure or retraining) and secure (governed by Databricks' access controls).
Databricks Reference: "Log models to Unity Catalog via MLflow, then grant access to other workspaces securely" ("MLflow Model Registry with Unity Catalog," 2023).
Conclusion: Option D leverages Databricks' native tools (MLflow and Unity Catalog) for a seamless, cost-effective, and secure solution, avoiding external systems, manual scripts, or redundant training.
NEW QUESTION # 26
A Generative AI Engineer has a provisioned throughput model serving endpoint as part of a RAG application and would like to monitor the serving endpoint's incoming requests and outgoing responses. The current approach is to include a micro-service in between the endpoint and the user interface to write logs to a remote server.
Which Databricks feature should they use instead which will perform the same task?
Answer: D
Explanation:
Problem Context: The goal is to monitor theserving endpointfor incoming requests and outgoing responses in aprovisioned throughput model serving endpointwithin aRetrieval-Augmented Generation (RAG) application. The current approach involves using a microservice to log requests and responses to a remote server, but the Generative AI Engineer is looking for a more streamlined solution within Databricks.
Explanation of Options:
* Option A: Vector Search: This feature is used to perform similarity searches within vector databases.
It doesn't provide functionality for logging or monitoring requests and responses in a serving endpoint, so it's not applicable here.
* Option B: Lakeview: Lakeview is not a feature relevant to monitoring or logging request-response cycles for serving endpoints. It might be more related to viewing data in Databricks Lakehouse but doesn't fulfill the specific monitoring requirement.
* Option C: DBSQL: Databricks SQL (DBSQL) is used for running SQL queries on data stored in Databricks, primarily for analytics purposes. It doesn't provide the direct functionality needed to monitor requests and responses in real-time for an inference endpoint.
* Option D: Inference Tables: This is the correct answer.Inference Tablesin Databricks are designed to store the results and metadata of inference runs. This allows the system to logincoming requests and outgoing responsesdirectly within Databricks, making it an ideal choice for monitoring the behavior of a provisioned serving endpoint. Inference Tables can be queried and analyzed, enabling easier monitoring and debugging compared to a custom microservice.
Thus,Inference Tablesare the optimal feature for monitoring request and response logs within the Databricks infrastructure for a model serving endpoint.
NEW QUESTION # 27
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: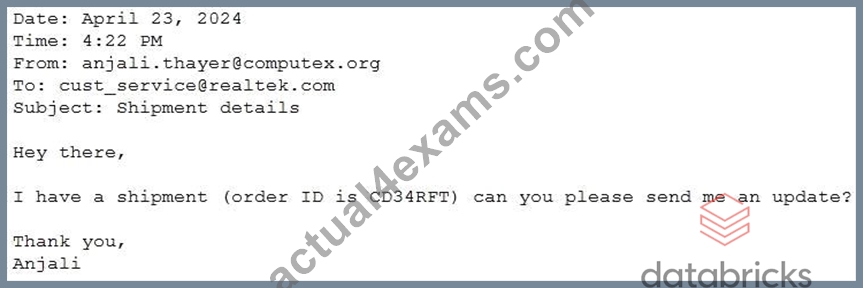
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: A
Explanation:
Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options:
* Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore,Option Bis optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 28
......
New Databricks-Generative-AI-Engineer-Associate Exam Price: https://www.actual4exams.com/Databricks-Generative-AI-Engineer-Associate-valid-dump.html
P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Actual4Exams: https://drive.google.com/open?id=1o9yr1MmyqdnuagjLiuVn3QRX2-QGZZaM