DOWNLOAD the newest Lead2PassExam Professional-Machine-Learning-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1bLc_M1iOa40QevhPlLg1TvVjiGUI5skx
Our Professional-Machine-Learning-Engineer test guide keep pace with contemporary talent development and makes every learner fit in the needs of the society. There is no doubt that our Professional-Machine-Learning-Engineer latest question can be your first choice for your relevant knowledge accumulation and ability enhancement. Moreover, Professional-Machine-Learning-Engineer exam questions have been expanded capabilities through partnership with a network of reliable local companies in distribution, software and product referencing for a better development. That helping you pass the Professional-Machine-Learning-Engineer Exam with our Professional-Machine-Learning-Engineer latest question successfully has been given priority to our agenda.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Scale prototypes into AI models | 18% | - Optimize model performance and generalization - Design and run experiments - Work with foundation models and generative AI techniques - Select appropriate model architectures and frameworks |
| Topic 2: Automate and orchestrate ML pipelines | 18% | - Use Vertex AI Pipelines, TFX, and other orchestration tools - Implement CI/CD for ML systems - Design end-to-end ML workflows - Automate retraining and model updates |
| Topic 3: Train and deploy models | 20% | - Implement generative AI deployment patterns - Deploy models for online, batch, and streaming prediction - Use Vertex AI deployment features and infrastructure - Configure training jobs and environments |
| Topic 4: Monitor and optimize AI solutions | 16% | - Troubleshoot and maintain production systems - Monitor model performance, fairness, and drift - Monitor data quality and pipeline health - Optimize cost, latency, and resource usage |
| Topic 5: Architect low-code AI solutions | 12% | - Identify use cases for low-code/no-code AI tools - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder - Apply responsible AI principles to low-code designs |
| Topic 6: Collaborate to manage data and models | 16% | - Organize and prepare enterprise data
- Manage datasets and features in Vertex AI |
>> Professional-Machine-Learning-Engineer Practice Test Pdf <<
In the world in which the competition is constantly intensifying, owning the excellent abilities in some certain area and profound knowledge can make you own a high social status and establish yourself in the society. Passing the test Professional-Machine-Learning-Engineer certification can help you realize your goal and find an ideal job. Buying our Professional-Machine-Learning-Engineer latest question can help you pass the Professional-Machine-Learning-Engineer exam successfully. Just have a try on our free demo of our Professional-Machine-Learning-Engineer exam questions, you will love our Professional-Machine-Learning-Engineer study material!
NEW QUESTION # 83
You have been asked to productionize a proof-of-concept ML model built using Keras. The model was trained in a Jupyter notebook on a data scientist's local machine. The notebook contains a cell that performs data validation and a cell that performs model analysis. You need to orchestrate the steps contained in the notebook and automate the execution of these steps for weekly retraining. You expect much more training data in the future. You want your solution to take advantage of managed services while minimizing cost. What should you do?
Answer: B
NEW QUESTION # 84
You work for a large social network service provider whose users post articles and discuss news. Millions of comments are posted online each day, and more than 200 human moderators constantly review comments and flag those that are inappropriate. Your team is building an ML model to help human moderators check content on the platform. The model scores each comment and flags suspicious comments to be reviewed by a human. Which metric(s) should you use to monitor the model's performance?
Answer: D
NEW QUESTION # 85
You work for a social media company. You need to detect whether posted images contain cars. Each training example is a member of exactly one class. You have trained an object detection neural network and deployed the model version to Al Platform Prediction for evaluation. Before deployment, you created an evaluation job and attached it to the Al Platform Prediction model version. You notice that the precision is lower than your business requirements allow. How should you adjust the model's final layer softmax threshold to increase precision?
Answer: B
Explanation:
Precision and recall are two common metrics for evaluating the performance of a classification model. Precision measures the proportion of positive predictions that are correct, while recall measures the proportion of positive examples that are correctly predicted. Precision and recall are inversely related, meaning that increasing one will decrease the other, and vice versa. The trade-off between precision and recall depends on the goal and the cost of the classification problem1.
For the use case of detecting whether posted images contain cars, precision is more important than recall, as the social media company wants to minimize the number of false positives, or images that are incorrectly labeled as containing cars. A high precision means that the model is confident and accurate in its positive predictions, while a low recall means that the model may miss some positive examples, or images that actually contain cars. The cost of missing some positive examples is lower than the cost of making wrong positive predictions, as the latter may affect the user experience and the reputation of the social media company.
The softmax function is a function that transforms a vector of real numbers into a probability distribution over the possible classes. The softmax function is often used as the final layer of a neural network for multi-class classification problems, as it assigns a probability to each class, and the class with the highest probability is chosen as the prediction. The softmax function is defined as:
softmax (x_i) exp (x_i) / sum_j exp (x_j)
where x_i is the input value for class i, and softmax (x_i) is the output probability for class i.
The softmax threshold is a parameter that determines the minimum probability that a class must have to be chosen as the prediction. For example, if the softmax threshold is 0.5, then the class with the highest probability must have at least 0.5 to be selected, otherwise the prediction is none. The softmax threshold can be used to adjust the trade-off between precision and recall, as a higher threshold will increase the precision and decrease the recall, while a lower threshold will decrease the precision and increase the recall2.
For the use case of detecting whether posted images contain cars, the best way to adjust the model's final layer softmax threshold to increase precision is to decrease the recall. This means that the softmax threshold should be increased, so that the model will only make positive predictions when it is highly confident, and avoid making false positives. By increasing the softmax threshold, the model will become more selective and accurate in its positive predictions, and improve the precision metric. Therefore, decreasing the recall is the best option for this use case.
Reference:
Precision and recall - Wikipedia
How to add a threshold in softmax scores - Stack Overflow
NEW QUESTION # 86
You are experimenting with a built-in distributed XGBoost model in Vertex AI Workbench user-managed notebooks. You use BigQuery to split your data into training and validation sets using the following queries:
CREATE OR REPLACE TABLE 'myproject.mydataset.training' AS
(SELECT * FROM 'myproject.mydataset.mytable' WHERE RAND() < = 0.8);
CREATE OR REPLACE TABLE 'myproject.mydataset.validation' AS
(SELECT * FROM 'myproject.mydataset.mytable' WHERE RAND() < = 0.2);
After training the model, you achieve an area under the receiver operating characteristic curve (AUC ROC) value of 0.8, but after deploying the model to production, you notice that your model performance has dropped to an AUC ROC value of 0.65. What problem is most likely occurring?
Answer: A
Explanation:
The most likely problem is that the tables that you created to hold your training and validation records share some records, and you may not be using all the data in your initial table. This is because the RAND() function generates a random number between 0 and 1 for each row, and the probability of a row being in both the training and validation tables is 0.2 * 0.8 = 0.16, which is not negligible. This means that some of the records that you use to validate your model are also used to train your model, which can lead to overfitting and poor generalization. Moreover, the probability of a row being in neither the training nor the validation table is 0.2 *
0.2 = 0.04, which means that you are wasting some of the data in your initial table and reducing the size of your datasets. A better way to split your data into training and validation sets is to use a hash function on a unique identifier column, such as the following queries:
CREATE OR REPLACE TABLE 'myproject.mydataset.training' AS (SELECT * FROM 'myproject.
mydataset.mytable' WHERE MOD(FARM_FINGERPRINT(id), 10) < 8); CREATE OR REPLACE TABLE
'myproject.mydataset.validation' AS (SELECT * FROM 'myproject.mydataset.mytable' WHERE MOD (FARM_FINGERPRINT(id), 10) > = 8); This way, you can ensure that each row has a fixed 80% chance of being in the training table and a 20% chance of being in the validation table, without any overlap or omission.
:
Professional ML Engineer Exam Guide
Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate Google Cloud launches machine learning engineer certification BigQuery ML: Splitting data for training and testing BigQuery: FARM_FINGERPRINT function
NEW QUESTION # 87
You are training an LSTM-based model on Al Platform to summarize text using the following job submission script: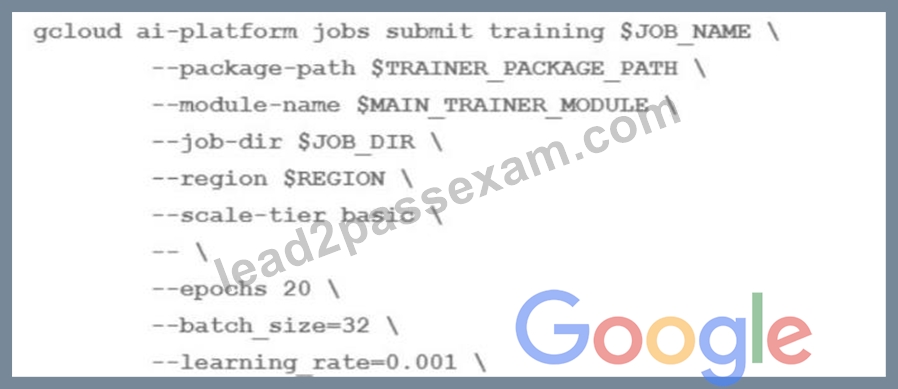
You want to ensure that training time is minimized without significantly compromising the accuracy of your model. What should you do?
Answer: A
Explanation:
The training time of a machine learning model depends on several factors, such as the complexity of the model, the size of the data, the hardware resources, and the hyperparameters. To minimize the training time without significantly compromising the accuracy of the model, one should optimize these factors as much as possible.
One of the factors that can have a significant impact on the training time is the scale-tier parameter, which specifies the type and number of machines to use for the training job on AI Platform. The scale-tier parameter can be one of the predefined values, such as BASIC, STANDARD_1, PREMIUM_1, or BASIC_GPU, or a custom value that allows you to configure the machine type, the number of workers, and the number of parameter servers1 To speed up the training of an LSTM-based model on AI Platform, one should modify the scale-tier parameter to use a higher tier or a custom configuration that provides more computational resources, such as more CPUs, GPUs, or TPUs. This can reduce the training time by increasing the parallelism and throughput of the model training. However, one should also consider the trade-off between the training time and the cost, as higher tiers or custom configurations may incur higher charges2 The other options are not as effective or may have adverse effects on the model accuracy. Modifying the epochs parameter, which specifies the number of times the model sees the entire dataset, may reduce the training time, but also affect the model's convergence and performance. Modifying the batch size parameter, which specifies the number of examples per batch, may affect the model's stability and generalization ability, as well as the memory usage and the gradient update frequency. Modifying the learning rate parameter, which specifies the step size of the gradient descent optimization, may affect the model's convergence and performance, as well as the risk of overshooting or getting stuck in local minima3
NEW QUESTION # 88
......
From your first contact with our Professional-Machine-Learning-Engineer practice guide, you can enjoy our excellent service. Before you purchase Professional-Machine-Learning-Engineer exam questions, you can consult our online customer service. Even if you choose to use our trial version of our Professional-Machine-Learning-Engineer Study Materials first, we will not give you any differential treatment. As long as you have questions on the Professional-Machine-Learning-Engineer learning guide, we will give you the professional suggestions.
Valid Professional-Machine-Learning-Engineer Test Duration: https://www.lead2passexam.com/Google/valid-Professional-Machine-Learning-Engineer-exam-dumps.html
What's more, part of that Lead2PassExam Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1bLc_M1iOa40QevhPlLg1TvVjiGUI5skx