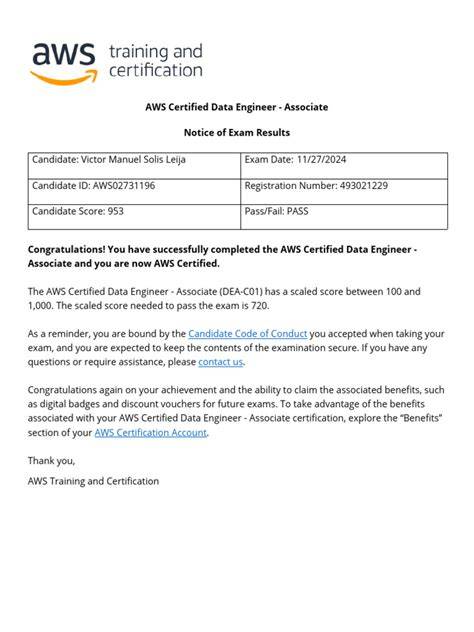
P.S. Free 2026 Amazon Data-Engineer-Associate dumps are available on Google Drive shared by TestSimulate: https://drive.google.com/open?id=1pglsQbl98M55xA4FnQwl4h69NRSKBPeo
Each product has a trial version and our products are without exception, literally means that our Data-Engineer-Associate guide torrent can provide you with a free demo when you browse our website of Data-Engineer-Associate prep guide, and we believe it is a good way for our customers to have a better understanding about our products in advance. We are committed to offer you with data protect act and guarantee you will not suffer from virus intrusion and information leakage after purchasing our Data-Engineer-Associate Guide Torrent. The last but not least we have professional groups providing guidance in terms of download and installment remotely.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Ingestion and Transformation | 34% | - Implement data quality and validation - Ingest data from various sources
|
| Topic 2: Data Operations and Support | 22% | - Backup, restore, and disaster recovery - Monitor and troubleshoot data pipelines
- Ensure reliability and scalability |
| Topic 3: Data Security and Governance | 18% | - Enforce compliance and data governance
- Implement access control and authentication
|
| Topic 4: Data Store Management | 26% | - Design and implement data storage solutions
- Manage data lifecycle and storage tiers |
>> Composite Test Amazon Data-Engineer-Associate Price <<
Thousands of Data-Engineer-Associate certification holders provide helpful input to TestSimulate. It helps us to keep our Data-Engineer-Associate exam dumps preparation material polished, updated, and error-free. To achieve its mission, TestSimulate offers a free demo of the Amazon Data-Engineer-Associate exam questions.This free trial enables customers to evaluate the quality of the Amazon Data-Engineer-Associate Dumps before making a purchase. You will also receive up to 1 year of free Amazon Data-Engineer-Associate exam question updates. TestSimulate guarantees that nothing will prevent you from clearing the Data-Engineer-Associate exam on your first attempt if you diligently study from our updated Data-Engineer-Associate exam questions.
NEW QUESTION # 99
A data engineer is processing a large amount of log data from web servers. The data is stored in an Amazon S3 bucket. The data engineer uses AWS services to process the data every day. The data engineer needs to extract specific fields from the raw log data and load the data into a data warehouse for analysis.
Answer: B
NEW QUESTION # 100
A data engineer must use AWS services to ingest a dataset into an Amazon S3 data lake. The data engineer profiles the dataset and discovers that the dataset contains personally identifiable information (PII). The data engineer must implement a solution to profile the dataset and obfuscate the PII.
Which solution will meet this requirement with the LEAST operational effort?
Answer: D
Explanation:
AWS Glue is a fully managed service that provides a serverless data integration platform for data preparation, data cataloging, and data loading. AWS Glue Studio is a graphical interface that allows you to easily author, run, and monitor AWS Glue ETL jobs. AWS Glue Data Quality is a feature that enables you to validate, cleanse, and enrich your data using predefined or custom rules. AWS Step Functions is a service that allows you to coordinate multiple AWS services into serverless workflows.
Using the Detect PII transform in AWS Glue Studio, you can automatically identify and label the PII in your dataset, such as names, addresses, phone numbers, email addresses, etc. You can then create a rule in AWS Glue Data Quality to obfuscate the PII, such as masking, hashing, or replacing the values with dummy data. You can also use other rules to validate and cleanse your data, such as checking for null values, duplicates, outliers, etc. You can then use an AWS Step Functions state machine to orchestrate a data pipeline to ingest the data into the S3 data lake. You can use AWS Glue DataBrew to visually explore and transform the data, AWS Glue crawlers to discover and catalog the data, and AWS Glue jobs to load the data into the S3 data lake.
This solution will meet the requirement with the least operational effort, as it leverages the serverless and managed capabilities of AWS Glue, AWS Glue Studio, AWS Glue Data Quality, and AWS Step Functions. You do not need to write any code to identify or obfuscate the PII, as you can use the built-in transforms and rules in AWS Glue Studio and AWS Glue Data Quality. You also do not need to provision or manage any servers or clusters, as AWS Glue and AWS Step Functions scale automatically based on the demand.
The other options are not as efficient as using the Detect PII transform in AWS Glue Studio, creating a rule in AWS Glue Data Quality, and using an AWS Step Functions state machine. Using an Amazon Kinesis Data Firehose delivery stream to process the dataset, creating an AWS Lambda transform function to identify the PII, using an AWS SDK to obfuscate the PII, and setting the S3 data lake as the target for the delivery stream will require more operational effort, as you will need to write and maintain code to identify and obfuscate the PII, as well as manage the Lambda function and its resources. Using the Detect PII transform in AWS Glue Studio to identify the PII, obfuscating the PII, and using an AWS Step Functions state machine to orchestrate a data pipeline to ingest the data into the S3 data lake will not be as effective as creating a rule in AWS Glue Data Quality to obfuscate the PII, as you will need to manually obfuscate the PII after identifying it, which can be error-prone and time-consuming. Ingesting the dataset into Amazon DynamoDB, creating an AWS Lambda function to identify and obfuscate the PII in the DynamoDB table and to transform the data, and using the same Lambda function to ingest the data into the S3 data lake will require more operational effort, as you will need to write and maintain code to identify and obfuscate the PII, as well as manage the Lambda function and its resources. You will also incur additional costs and complexity by using DynamoDB as an intermediate data store, which may not be necessary for your use case. Reference:
AWS Glue
AWS Glue Studio
AWS Glue Data Quality
[AWS Step Functions]
[AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide], Chapter 6: Data Integration and Transformation, Section 6.1: AWS Glue
NEW QUESTION # 101
A data engineer needs to create an Amazon Athena table based on a subset of data from an existing Athena table named cities_world. The cities_world table contains cities that are located around the world. The data engineer must create a new table named cities_us to contain only the cities from cities_world that are located in the US.
Which SQL statement should the data engineer use to meet this requirement?
Answer: A
Explanation:
To create a new table named cities_usa in Amazon Athena based on a subset of data from the existing cities_world table, you should use an INSERT INTO statement combined with a SELECT statement to filter only the records where the country is 'usa'. The correct SQL syntax would be:
Option A: INSERT INTO cities_usa (city, state) SELECT city, state FROM cities_world WHERE country='usa';This statement inserts only the cities and states where the country column has a value of 'usa' from the cities_world table into the cities_usa table. This is a correct approach to create a new table with data filtered from an existing table in Athena.
Options B, C, and D are incorrect due to syntax errors or incorrect SQL usage (e.g., the MOVE command or the use of UPDATE in a non-relevant context).
References:
Amazon Athena SQL Reference
Creating Tables in Athena
NEW QUESTION # 102
A data engineer needs to use an Amazon QuickSight dashboard that is based on Amazon Athena queries on data that is stored in an Amazon S3 bucket. When the data engineer connects to the QuickSight dashboard, the data engineer receives an error message that indicates insufficient permissions.
Which factors could cause to the permissions-related errors? (Choose two.)
Answer: A,B
Explanation:
QuickSight does not have access to the S3 bucket and QuickSight does not have access to decrypt S3 data are two possible factors that could cause the permissions-related errors. Amazon QuickSight is a business intelligence service that allows you to create and share interactive dashboards based on various data sources, including Amazon Athena. Amazon Athena is a serverless query service that allows you to analyze data stored in Amazon S3 using standard SQL. To use an Amazon QuickSight dashboard that is based on Amazon Athena queries on data that is stored in an Amazon S3 bucket, you need to grant QuickSight access to both Athena and S3, as well as any encryption keys that are used to encrypt the S3 data. If QuickSight does not have access to the S3 bucket or the encryption keys, it will not be able to read the data from Athena and display it on the dashboard, resulting in an error message that indicates insufficient permissions.
The other options are not factors that could cause the permissions-related errors. Option A, there is no connection between QuickSight and Athena, is not a factor, as QuickSight supports Athena as a native data source, and you can easily create a connection between them using the QuickSight console or the API. Option B, the Athena tables are not cataloged, is not a factor, as QuickSight can automatically discover the Athena tables that are cataloged in the AWS Glue Data Catalog, and you can also manually specify the Athena tables that are not cataloged. Option E, there is no IAM role assigned to QuickSight, is not a factor, as QuickSight requires an IAM role to access any AWS data sources, including Athena and S3, and you can create and assign an IAM role to QuickSight using the QuickSight console or the API. References:
Using Amazon Athena as a Data Source
Granting Amazon QuickSight Access to AWS Resources
Encrypting Data at Rest in Amazon S3
NEW QUESTION # 103
A company uses AWS Glue jobs to implement several data pipelines. The pipelines are critical to the company.
The company needs to implement a monitoring mechanism that will alert stakeholders if the pipelines fail.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: C
Explanation:
Creating an EventBridge rule that triggers a Lambda function on AWS Glue job failure events and then sends notifications via Amazon SNS is the most direct and operationally efficient method:
"Practice Quiz 10: A data engineer must monitor the data pipeline... Which solution will meet these requirements?
A: Inspect the job run monitoring section of the AWS Glue console.
-Ace the AWS Certified Data Engineer - Associate Certification - version 2 - apple.pdf Although this reference directly supports using AWS Glue's monitoring features via EventBridge, it implies that solutions likeA-which directly use EventBridge failure events for automation-are more optimal and less complex than constructing custom logs and metrics.
NEW QUESTION # 104
......
TestSimulate has rich resources and Data-Engineer-Associate test questions. It equips with Data-Engineer-Associate exam simulations and test dumps. You can try to download questions and answers. Moreover, TestSimulate answers real questions. Equipping with online Amazon Data-Engineer-Associate Study Guide, 100% guarantee to Pass Your Data-Engineer-Associate Exam.
Valid Data-Engineer-Associate Exam Objectives: https://www.testsimulate.com/Data-Engineer-Associate-study-materials.html
2026 Latest TestSimulate Data-Engineer-Associate PDF Dumps and Data-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1pglsQbl98M55xA4FnQwl4h69NRSKBPeo