
BONUS!!! Download part of ITdumpsfree MLA-C01 dumps for free: https://drive.google.com/open?id=1DTP0vjGE4APCx5kXZokuc_GrTjiGc4jQ
In addition to the content updates, our system will also be updated for the MLA-C01 training materials. If you have any opinions, you can tell us that our common goal is to create a product that users are satisfied with. After you start learning, I hope you can set a fixed time to check emails. If the content of the MLA-C01 Practice Guide or system is updated, we will send updated information to your e-mail address. Of course, you can also consult our e-mail on the status of the product updates. I hope we can work together to make you better use MLA-C01 simulating exam to pass the MLA-C01 exam.
| Section | Weight | Objectives |
|---|---|---|
| ML Solution Monitoring, Maintenance, and Security | 24% | - Monitoring and observability
|
| Deployment and Orchestration of ML Workflows | 22% | - ML pipeline orchestration
|
| ML Model Development | 26% | - Model selection and training
|
| Data Preparation for Machine Learning (ML) | 28% | - Data ingestion and collection
|
>> Amazon MLA-C01 Practice Guide <<
A certification is not only an affirmation to your ability but also can help you enter a better company and improve your salary. MLA-C01 exam cram can help you get your certification successfully. We have a professional team to collect and research the latest information for the exam, and we offer you free update for 365 days after payment, so that you can obtain the latest information. In order to build up your confidence for MLA-C01 Exam Braindumps, we are pass guarantee and money back guarantee if you fail to pass the exam.
NEW QUESTION # 230
A company is planning to create an internal-only chat interface to help employees handle customer queries. Currently, the employees need to refer to a massive knowledge base of internal documents to address customer issues. The new solution must be serverless. Which combination of steps will meet these requirements?
Answer: B,D,E
Explanation:
To build a serverless internal chat interface, you can use Amazon Bedrock with a foundation model like Claude, invoke the model API through AWS Lambda with Amazon API Gateway, and store embeddings in a vector database format using Amazon S3. This avoids server management, ensures scalability, and leverages serverless components end-to-end.
NEW QUESTION # 231
An ML engineer is using Amazon SageMaker Canvas to build a custom ML model from an imported dataset.
The model must make continuous numeric predictions based on 10 years of data.
Which metric should the ML engineer use to evaluate the model's performance?
Answer: C
Explanation:
This is a regression problem, where the target variable is continuous and numeric. AWS documentation clearly states that classification metrics such as accuracy and AUC are not appropriate for regression models.
Root Mean Square Error (RMSE) measures the square root of the average squared differences between predicted and actual values. RMSE penalizes larger errors more heavily, making it especially useful when large prediction errors are costly or undesirable.
SageMaker Canvas automatically selects regression metrics such as RMSE and MAE when building regression models. RMSE is widely used for time-based and numeric prediction problems, especially when evaluating long historical datasets.
Inference latency measures system performance, not model accuracy.
Therefore, Option D is the correct and AWS-verified answer.
NEW QUESTION # 232
A gaming company needs to deploy a natural language processing (NLP) model to moderate a chat forum in a game. The workload experiences heavy usage during evenings and weekends but minimal activity during other hours.
Which solution will meet these requirements MOST cost-effectively?
Answer: B
Explanation:
The key requirements in this scenario are variable traffic patterns and cost efficiency. The workload has unpredictable spikes during evenings and weekends, followed by long periods of low or no usage. According to AWS Machine Learning documentation, Amazon SageMaker Serverless Inference is specifically designed for such use cases.
SageMaker Serverless Inference automatically provisions, scales, and shuts down compute resources based on incoming inference requests. Customers are billed only for the compute time used during inference, not for idle resources. This makes it highly cost-effective for workloads with intermittent or spiky traffic, such as real- time chat moderation in gaming environments.
Option A is incorrect because batch transform jobs are intended for offline, large-scale inference and require fixed capacity during job execution. They are not suitable for real-time NLP moderation.
Option C is also incorrect because reserving an EC2 GPU instance incurs continuous costs regardless of utilization. This would be inefficient given the long idle periods described in the scenario.
Option D, SageMaker Asynchronous Inference, is designed for workloads with long processing times or large payloads and still requires endpoint provisioning. While it can handle traffic spikes, it does not scale down to zero in the same cost-efficient manner as Serverless Inference.
Therefore, Amazon SageMaker Serverless Inference is the most cost-effective and operationally efficient solution for deploying an NLP moderation model with highly variable usage patterns.
NEW QUESTION # 233
A company needs to update the model definition of an existing Amazon SageMaker Al endpoint.
Select and order the correct steps from the following list to update the model definition settings with the LEAST interruption of inferences. Select each step one time or not at all. (Select and order THREE.)
* Create a new endpoint configuration that uses the new model definition.
* Create a new model definition with updated settings by using the CreateModel action in the SageMaker AI API.
* Delete the endpoint that needs to be updated and recreate the endpoint with the new endpoint configuration.
* Delete the IAM role and permissions for the ExecutionRoleArn parameter.
* Update the endpoint with the new endpoint configuration.
Answer:
Explanation: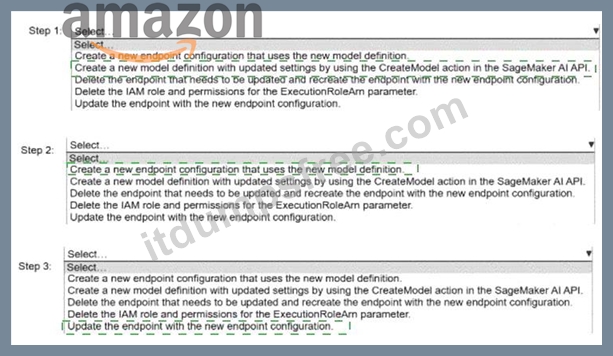
Explanation:
Step 1: Create a new model definition with updated settings by using the CreateModel action in the SageMaker AI API.
Step 2: Create a new endpoint configuration that uses the new model definition.
Step 3: Update the endpoint with the new endpoint configuration.
Do not delete and recreate the endpoint. That causes unnecessary inference interruption. SageMaker endpoint updates are designed to use a new EndpointConfig; AWS explicitly states that to update an endpoint, you must create a new endpoint configuration, then call UpdateEndpoint on the existing endpoint. During the update, SageMaker changes the endpoint to Updating and then back to InService.
NEW QUESTION # 234
A company wants to improve the sustainability of its ML operations.
Which actions will reduce the energy usage and computational resources that are associated with the company's training jobs? (Choose two.)
Answer: B,D
NEW QUESTION # 235
......
You buy our ITdumpsfree Amazon MLA-C01 Certification which is 100% risk free. Before you decide to use ITdumpsfree Amazon MLA-C01 dumps, you can try our free demo and pdf. Click ITdumpsfree, download it now! Affordable, and good service – free update for a year. Quality first. Welcomes your order. Thank you.
Latest MLA-C01 Test Guide: https://www.itdumpsfree.com/MLA-C01-exam-passed.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by ITdumpsfree: https://drive.google.com/open?id=1DTP0vjGE4APCx5kXZokuc_GrTjiGc4jQ