我們VCESoft Microsoft的AI-200考試 的問題包含了完整的無限制的轉儲,所以你很容易的通過考試,不管你是通過你的產品合格證或是其他當今流行的身份驗證,完美的展現VCESoft Microsoft的AI-200考試培訓資料的長處,這不僅僅是依靠,也是指導,這其實是最好的,你可以使用VCESoft Microsoft的AI-200考試 培訓資料裏的問題和答案通過考試,獲得Microsoft的AI-200考試認證。
| Section | Objectives |
|---|---|
| Topic 1: Connect to and consume Azure services | - Integrate Azure services
|
| Topic 2: Develop containerized solutions on Azure | - Implement containerized applications
|
| Topic 3: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Topic 4: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
我們不但能保證你通過AI-200考試,還會為你提供一年的免費更新服務,如果不小心考試沒有成功,我們將會全額退款給你。但這種可能性幾乎不會發生的。我們是可以100%幫你通過AI-200考試的,你可以先在網上下載我們提供的部分考題VCESoft免費嘗試。
問題 #126
Drag and Drop Question
You are implementing a Retrieval-Augmented Generation (RAG) system by using the native vector search capabilities of Azure Cosmos DB for NoSQL API.
You have a container named Documents that stores technical articles. Each article includes a property named embedding.
You must ensure that the system can perform efficient similarity searches between user queries and the stored articles.
You need to configure the database resources to support semantic retrieval.
Which configurations should you use? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.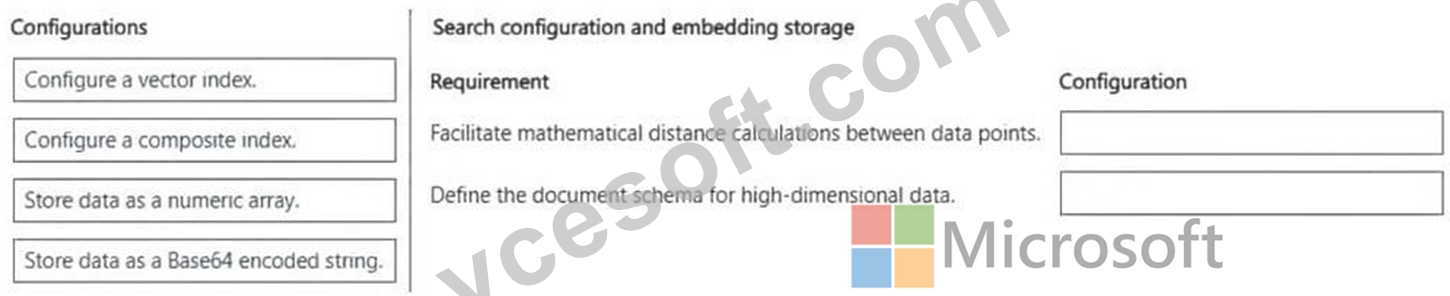
答案:
解題說明: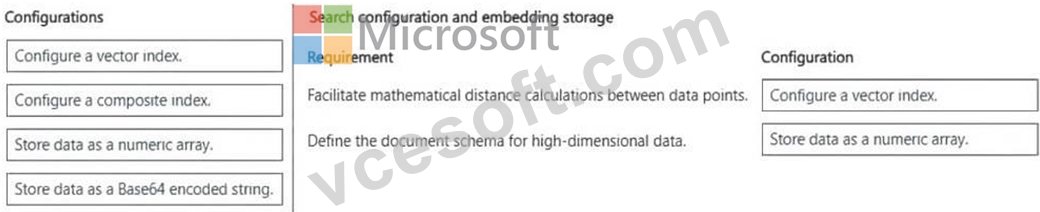
Explanation:
Box 1: Configure a vector index.
To support semantic retrieval and perform mathematical distance calculations using the native vector search capabilities of Azure Cosmos DB for NoSQL, you must configure a vector index.
Azure Cosmos DB for NoSQL relies on a specialized indexing structure (such as DiskANN or QuantizedFlat) to organize vector data. Defining a vector index policy within the container configurations is a strict requirement for enabling high-speed similarity searches (using functions like VectorDistance) without requiring full, unindexed scans of documents.
Box 2: Store data as a numeric array
Azure Cosmos DB for NoSQL, you must store the embedding property as a numeric array (an array of floating-point numbers like float32) inside your JSON documents.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/gen-ai/agentic-retrieval
問題 #127
You are implementing semantic retrieval for a chatbot.
Embeddings are already stored in Redis. However, vector similarity queries do not return matches.
You need to resolve the vector similarity search issue.
What should you do?
答案:D
解題說明:
Creating a FLAT vector index on your embedding field will resolve the issue and allow your Redis vector similarity queries to return matches.
In Redis (using the Redis Search and Query features), vector fields cannot be queried using Vector Similarity Search (VSS) syntax until a dedicated vector index is explicitly built over them.
No Automatic Indexing: Redis does not automatically index JSON or Hash fields containing raw binary or string embeddings.
Query Failure: Without an index, VSS queries (using the KNN operator) will fail with syntax errors or return zero results because the query engine cannot parse the unindexed field.
Reference:
https://www.louisbouchard.ai/indexing-methods/
問題 #128
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You are preparing a production deployment for an Azure Function app. The app will run across multiple environments.
The solution must support environment-specific configuration and prevent secrets from being stored in source control.
You need to develop the solution.
Solution: Store production secrets in environment variables set by the Dockerfile.
Does the solution meet the goal?
答案:A
解題說明:
Correct:
* Use App Configuration with Key Vault references to store environment-specific settings and secrets, accessed from the function app by using a managed identity.
This is an industry-standard best practice architectural pattern.
Using Azure App Configuration combined with Azure Key Vault references completely satisfies your compliance requirements. It centralizes feature flags and non-sensitive configurations, keeps sensitive data safely out of source control, handles multi-environment deployments cleanly, and eliminates credentials via a passwordless Managed Identity.
Incorrect:
* Store connection strings in the Function app application settings configured in the Azure Portal.
* Store production secrets in environment variables set by the Dockerfile.
Reference:
https://learn.microsoft.com/en-us/azure/app-service/app-service-key-vault-references
問題 #129
A Python API running in ACA must send distributed traces to Azure Monitor.
The API creates spans. However, no traces appear in Azure Monitor.
You need to configure the OpenTelemetry SDK pipeline to export traces to Azure Monitor.
What should you do? To answer, move the appropriate actions to the correct requirements. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
答案:
解題說明:
Explanation:
Verified Answer: Register a global trace provider # initialize the application TraceProvider. Export traces to Azure Monitor # create/configure AzureMonitorTraceExporter. Connect exporter to provider # add a span processor. Generate spans # use tracer.start_as_current_span(...).
Detailed Explanation: OpenTelemetry tracing is a pipeline: the application obtains a tracer from a configured provider, creates spans, passes ended spans through a span processor, and exports them using the Azure Monitor exporter. Creating spans alone is insufficient; without the provider/processor/exporter chain, no telemetry reaches Azure Monitor. Log sampling and legacy Application Insights TrackEvent calls are unrelated to the required OpenTelemetry trace-export path.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Enable Azure Monitor OpenTelemetry
問題 #130
An AI platform uses App Configuration for feature flags and endpoint routing.
The platform stores secrets alongside configuration data and does NOT support dynamic refresh.
The solution must support dynamic configuration refresh while ensuring that secrets are NOT stored in App Configuration.
You need to enable secure dynamic configuration management for the platform.
Which three actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
答案:C,D,E
解題說明:
[A]
Setting up a cache expiration or polling interval enables the application to detect configuration changes periodically without restarting, fulfilling the requirement for dynamic refresh.
[B]
Using Azure Managed Identities eliminates hardcoded credentials. It allows your application to securely authenticate to both Azure App Configuration and Azure Key Vault.
[C]
Moving API keys to Azure Key Vault adheres to security best practices. Azure App Configuration can reference these secrets securely using Key Vault references, ensuring secrets are never stored as plaintext in the configuration store.
Reference:
https://smartbridge.com/azure-ai-foundry-enterprise-guide-2/
問題 #131
......
VCESoft 應一些考友的需要,在第一時間內及時更新了 AI-200 這門題目,更新之後的 AI-200 擬真試題覆蓋率100%。考生可在反復練習這份真題的基礎上,多思考,多總結,通過 AI-200 考試就沒有問題了。建議的是,一定要瞭解這門考試的最新動態資訊,這樣才能在考試中做到隨機應變。而我們就是一個可以滿足很多參加Microsoft AI-200 認證考試的IT人士的需求的網站。
AI-200證照信息: https://www.vcesoft.com/AI-200-pdf.html