Databricks Databricks-Certified-Data-Engineer-Professional Exam Quizzes - Exam Databricks-Certified-Data-Engineer-Professional Questions Answers
Are you still overwhelmed by the low-production and low-efficiency in your daily life? If your answer is yes, please pay attention to our Databricks-Certified-Data-Engineer-Professional guide torrent, because we will provide well-rounded and first-tier services for you, thus supporting you obtain your dreamed Databricks-Certified-Data-Engineer-Professional certificate and have a desired occupation. There are some main features of our products and we believe you will be satisfied with our Databricks-Certified-Data-Engineer-Professional test questions. And once you have a try on our Databricks-Certified-Data-Engineer-Professional exam questions, you will love it.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Governance | 7% | - Enforce data policies and standards
- Manage data assets and metadata
- Use Unity Catalog for governance
|
| Topic 2: Data Ingestion & Acquisition | 7% | - Handle incremental and batch data loads
- Ingest data from diverse sources
- Use Auto Loader and structured streaming
|
| Topic 3: Data Sharing and Federation | 5% | - Implement Lakehouse Federation
- Manage cross-platform data access
- Use Delta Sharing for secure data sharing
|
| Topic 4: Monitoring and Alerting | 10% | - Set up alerts and notifications
- Monitor pipeline performance and health
- Track data lineage and metrics
|
| Topic 5: Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management
- Enforce data quality standards
- Apply data cleansing and validation rules
|
| Topic 6: Data Modelling | 6% | - Optimize table design and partitioning
- Implement dimensional and relational models
- Design Medallion Architecture
|
| Topic 7: Ensuring Data Security and Compliance | 10% | - Secure data at rest and in transit
- Ensure data privacy and compliance
- Implement access control and permissions
|
| Topic 8: Cost & Performance Optimisation | 13% | - Improve query and pipeline performance
- Optimize compute and storage resources
- Apply cost management best practices
|
| Topic 9: Debugging and Deploying | 10% | - Implement CI/CD and DevOps practices
- Troubleshoot and debug pipelines
- Deploy using Asset Bundles, CLI, and APIs
|
| Topic 10: Developing Code for Data Processing using Python and SQL | 22% | - Write efficient and maintainable code
- Implement complex data processing logic
- Use Databricks-specific libraries and APIs
|
>> Databricks Databricks-Certified-Data-Engineer-Professional Exam Quizzes <<
Databricks-Certified-Data-Engineer-Professional Exam Quizzes | Professional Exam Databricks-Certified-Data-Engineer-Professional Questions Answers: Databricks Certified Data Engineer Professional Exam 100% Pass
In order to make the Databricks-Certified-Data-Engineer-Professional exam easier for every candidate, DumpsReview compiled such a wonderful Databricks-Certified-Data-Engineer-Professional study materials that allows making you test and review history performance, and then you can find your obstacles and overcome them. In addition, once you have used this type of Databricks-Certified-Data-Engineer-Professional Exam Question online for one time, next time you can practice in an offline environment. It must be highest efficiently exam tool to help you pass the Databricks-Certified-Data-Engineer-Professional exam.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q229-Q234):
NEW QUESTION # 229
An upstream system is emitting change data capture (CDC) logs that are being written to a cloud object storage directory. Each record in the log indicates the change type (insert, update, or delete) and the values for each field after the change. The source table has a primary key identified by the field pk_id.
For auditing purposes, the data governance team wishes to maintain a full record of all values that have ever been valid in the source system. For analytical purposes, only the most recent value for each record needs to be recorded. The Databricks job to ingest these records occurs once per hour, but each individual record may have changed multiple times over the course of an hour.
Which solution meets these requirements?
- A. Use merge into to insert, update, or delete the most recent entry for each pk_id into a bronze table, then propagate all changes throughout the system.
- B. Create a separate history table for each pk_id resolve the current state of the table by running a union all filtering the history tables for the most recent state.
- C. Ingest all log information into a bronze table; use merge into to insert, update, or delete the most recent entry for each pk_id into a silver table to recreate the current table state.
- D. Use Delta Lake's change data feed to automatically process CDC data from an external system, propagating all changes to all dependent tables in the Lakehouse.
- E. Iterate through an ordered set of changes to the table, applying each in turn; rely on Delta Lake's versioning ability to create an audit log.
Answer: C
Explanation:
CDF captures changes only from a Delta table and is only forward-looking once enabled. The CDC logs are writing to object storage. So you would need to ingestion those and merge into downstream tables.
NEW QUESTION # 230
A data engineer needs to productionize a new Spark application written by teammate. This application has numerous external dependencies, including libraries, and requires custom environment variables and Spark configuration parameters to be set. Which two methods will help the data engineer accomplish the task? (Choose two.)
- A. Use secrets in init scripts to store configuration data
- B. Add libraries to compute policies
- C. Use compute policies to set system properties, environment variables, and Spark configuration parameters.
- D. Install libraries on DBFS
- E. Create init scripts on DBFS.
Answer: C,E
Explanation:
Compute policies allow centrally defining and enforcing Spark configuration parameters, system properties, and environment variables required by the application, ensuring consistent production settings. Init scripts enable installing external dependencies and performing custom environment setup at cluster startup, making them essential for productionizing Spark applications with complex dependency and configuration requirements.
NEW QUESTION # 231
A data engineer manages a production Lakeflow Declarative Pipeline that processes customer transaction data. The pipeline includes several data quality expectations such as transaction_amount > 0 and customer_id IS NOT NULL. These expectations are defined using the EXPECT clause in SQL.
The engineer aims to monitor the pipeline's data quality by analyzing the number of records that passed or failed each expectation during the latest pipeline update. The Lakeflow Declarative Pipelines event logs are stored in a Delta table named event_log_table.
For the most recent pipeline update, determine a programmatically appropriate approach to extract information like the name of each expectation, associated dataset, count of records that passed the expectation, and count of records that failed the expectation.
Which method retrieves the desired data quality metrics from the Lakeflow Declarative Pipelines event log?
- A. Access the event_log_table, filter for events where event_type = 'expectation_result', and extract the expectation metrics from the details field.
- B. Use the Lakeflow Declarative Pipelines UI to navigate to the specific pipeline, select the dataset, and view the Data Quality tab to manually retrieve the expectation metrics.
- C. Access the event_log_table, filter for events where event_type = 'flow_progress', and parse details.flow_progress.data_quality.expectations field to extract the required metrics.
- D. Query the event_log_table for events with event_type = 'data_quality' and directly select the passed_records and failed_records fields.
Answer: A
Explanation:
The Databricks documentation specifies that for Lakeflow Declarative Pipelines, detailed data quality metrics are logged as events of type expectation_result within the event log. Each record of this type contains fields including expectation_name, dataset_name, passed_records, and failed_records. Filtering on event_type = 'expectation_result' and expanding the details field allows retrieving metrics for each expectation from the most recent pipeline update. While flow_progress provides summary statistics and data_quality events aggregate results, only expectation_result events provide granular, per-expectation metrics required for audit and monitoring automation.
NEW QUESTION # 232
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users.
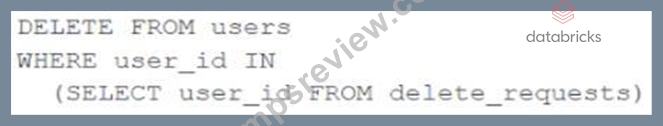
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
- A. No; the Delta Lake delete command only provides ACID guarantees when combined with the merge into command.
- B. No; the Delta cache may return records from previous versions of the table until the cluster is restarted.
- C. Yes; the Delta cache immediately updates to reflect the latest data files recorded to disk.
- D. Yes; Delta Lake ACID guarantees provide assurance that the delete command succeeded fully and permanently purged these records.
- E. No; files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files.
Answer: E
Explanation:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from Explanation:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage.
NEW QUESTION # 233
A data engineer is setting up a pipeline to ingest data from a message bus system that occasionally delivers duplicate messages. The duplicate messages can be a week apart. The target is a Databricks Delta Lake table where each record should appear exactly once. Which Databricks ingestion pattern should be implemented to handle potential duplicates where events can arrive outside of the configured watermark?
- A. Implement a write operation using MERGE INTO with a unique key
- B. Use Delta Lake's change data feed to filter duplicate records
- C. Configure Structured Streaming with dropDuplicates transformation
- D. Use Delta Lake time travel to identify and remove duplicates
Answer: A
Explanation:
Using MERGE INTO with a unique key enforces idempotent writes at the Delta Lake table level.
This approach reliably handles duplicates even when events arrive far outside any streaming watermark, ensuring that each logical record is written exactly once regardless of arrival time.
NEW QUESTION # 234
......
Our Databricks-Certified-Data-Engineer-Professional free demo provides you with the free renewal in one year so that you can keep track of the latest points happening. As the questions of exams of our Databricks-Certified-Data-Engineer-Professional exam dumps are more or less involved with heated issues and customers who prepare for the exams must haven’t enough time to keep trace of exams all day long, our Databricks-Certified-Data-Engineer-Professional Practice Engine can serve as a conducive tool for you make up for those hot points you have ignored. You will be completed ready for your Databricks-Certified-Data-Engineer-Professional exam.
Exam Databricks-Certified-Data-Engineer-Professional Questions Answers: https://www.dumpsreview.com/Databricks-Certified-Data-Engineer-Professional-exam-dumps-review.html
- Databricks-Certified-Data-Engineer-Professional Braindumps 🪕 New Databricks-Certified-Data-Engineer-Professional Study Materials 🍮 New Databricks-Certified-Data-Engineer-Professional Study Materials 😌 Go to website ▷ www.prepawaypdf.com ◁ open and search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ to download for free 🟤Databricks-Certified-Data-Engineer-Professional Exam Fee
- Valid Databricks-Certified-Data-Engineer-Professional Practice Materials 👫 Test Databricks-Certified-Data-Engineer-Professional Question 🧾 Latest Databricks-Certified-Data-Engineer-Professional Exam Bootcamp 🔕 Search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ and download it for free on 《 www.pdfvce.com 》 website 👤Latest Databricks-Certified-Data-Engineer-Professional Test Report
- Databricks-Certified-Data-Engineer-Professional Practice Test Training Materials - Databricks-Certified-Data-Engineer-Professional Test Prep - www.prep4sures.top ❤ Immediately open ( www.prep4sures.top ) and search for ➽ Databricks-Certified-Data-Engineer-Professional 🢪 to obtain a free download 🥈Latest Databricks-Certified-Data-Engineer-Professional Test Report
- Databricks-Certified-Data-Engineer-Professional Exam Quizzes: 2026 Databricks Realistic Databricks Certified Data Engineer Professional Exam Exam Quizzes Pass Guaranteed ⚔ Search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ and obtain a free download on ( www.pdfvce.com ) 👫New Databricks-Certified-Data-Engineer-Professional Study Materials
- Databricks-Certified-Data-Engineer-Professional Exam Fee 🕌 New Databricks-Certified-Data-Engineer-Professional Study Materials 🥟 Latest Databricks-Certified-Data-Engineer-Professional Test Online 🚼 Search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ and download it for free immediately on ⮆ www.pass4test.com ⮄ 🐛Databricks-Certified-Data-Engineer-Professional Braindumps
- Databricks-Certified-Data-Engineer-Professional - Professional Databricks Certified Data Engineer Professional Exam Exam Quizzes 🕰 Download ➽ Databricks-Certified-Data-Engineer-Professional 🢪 for free by simply searching on “ www.pdfvce.com ” 🎶Valid Databricks-Certified-Data-Engineer-Professional Practice Materials
- Pass Guaranteed 2026 Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Latest Exam Quizzes 😋 Simply search for ➤ Databricks-Certified-Data-Engineer-Professional ⮘ for free download on ➡ www.practicevce.com ️⬅️ 🪒Databricks-Certified-Data-Engineer-Professional Braindumps
- Databricks Databricks-Certified-Data-Engineer-Professional Practice Test - Effortless Solution To Pass Exam 🐧 Copy URL ( www.pdfvce.com ) open and search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ to download for free ☮Databricks-Certified-Data-Engineer-Professional Exam Fee
- Vce Databricks-Certified-Data-Engineer-Professional Exam 🐪 Databricks-Certified-Data-Engineer-Professional Braindumps 📗 Valid Databricks-Certified-Data-Engineer-Professional Practice Materials 🦎 Download ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ for free by simply searching on ➡ www.examcollectionpass.com ️⬅️ 🌐Latest Databricks-Certified-Data-Engineer-Professional Test Online
- Databricks-Certified-Data-Engineer-Professional Test Vce 🚆 Databricks-Certified-Data-Engineer-Professional Passguide 🧍 Latest Databricks-Certified-Data-Engineer-Professional Test Report ⬛ Search for 「 Databricks-Certified-Data-Engineer-Professional 」 and download exam materials for free through 《 www.pdfvce.com 》 🆗Latest Databricks-Certified-Data-Engineer-Professional Exam Bootcamp
- Databricks-Certified-Data-Engineer-Professional - Professional Databricks Certified Data Engineer Professional Exam Exam Quizzes 🍐 Download ▛ Databricks-Certified-Data-Engineer-Professional ▟ for free by simply searching on 《 www.verifieddumps.com 》 🌙Databricks-Certified-Data-Engineer-Professional Exam Fee
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes