What's more, part of that UpdateDumps Databricks-Generative-AI-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1MMMb2v_Kt9VGiBO5m8pcQCR1BAgFkrOa
With the rapid development of society, people pay more and more attention to knowledge and skills. So every year a large number of people take Databricks-Generative-AI-Engineer-Associate tests to prove their abilities. But even the best people fail sometimes. In addition to the lack of effort, may also not make the right choice. A good choice can make one work twice the result with half the effort, and our Databricks-Generative-AI-Engineer-Associate Study Materials will be your right choice.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Application Development | 30% | - Build RAG applications - Use Databricks Vector Search - Integrate with MLflow - Develop LLM chains and workflows |
| Topic 2: Assembling and Deploying Apps | 22% | - Manage application lifecycle - Package and deploy applications - Deploy models via Model Serving |
| Topic 3: Data Preparation | 14% | - Implement data pipelines and transformations - Prepare and process data for LLM use - Manage data quality and format |
| Topic 4: Design Applications | 14% | - Select appropriate models, tools and approaches - Design solution architecture - Decompose complex requirements into tasks |
| Topic 5: Evaluation and Monitoring | 12% | - Iterate and improve solutions - Monitor application behavior and outputs - Evaluate model and application performance |
| Topic 6: Governance | 8% | - Ensure compliance and security - Apply Unity Catalog for data governance - Manage access and permissions |
>> Customized Databricks-Generative-AI-Engineer-Associate Lab Simulation <<
UpdateDumps Databricks-Generative-AI-Engineer-Associate study material also has a timekeeping function that allows you to be cautious and keep your own speed while you are practicing, so as to avoid the situation that you can't finish all the questions during the exam. With Databricks Certified Generative AI Engineer Associate Databricks-Generative-AI-Engineer-Associate Learning Materials, you only need to spend half your money to get several times better service than others.
NEW QUESTION # 81
A Generative AI Engineer has created a RAG application which can help employees retrieve answers from an internal knowledge base, such as Confluence pages or Google Drive. The prototype application is now working with some positive feedback from internal company testers. Now the Generative Al Engineer wants to formally evaluate the system's performance and understand where to focus their efforts to further improve the system.
How should the Generative AI Engineer evaluate the system?
Answer: D
Explanation:
* Problem Context: After receiving positive feedback for the RAG application prototype, the next step is to formally evaluate the system to pinpoint areas for improvement.
* Explanation of Options:
* Option A: While cosine similarity scores are useful, they primarily measure similarity rather than the overall performance of an RAG system.
* Option B: This option provides a systematic approach to evaluation by testing both retrieval and generation components separately. This allows for targeted improvements and a clear understanding of each component's performance, using MLflow's metrics for a structured and standardized assessment.
* Option C: Benchmarking multiple LLMs does not focus on evaluating the existing system's components but rather on comparing different models.
* Option D: Using an LLM as a judge is subjective and less reliable for systematic performance evaluation.
OptionBis the most comprehensive and structured approach, facilitating precise evaluations and improvements on specific components of the RAG system.
NEW QUESTION # 82
A Generative AI Engineer is tasked with deploying an application that takes advantage of a custom MLflow Pyfunc model to return some interim results.
How should they configure the endpoint to pass the secrets and credentials?
Answer: C
NEW QUESTION # 83
A Generative AI Engineer is building an LLM to generate article summaries in the form of a type of poem, such as a haiku, given the article content. However, the initial output from the LLM does not match the desired tone or style.
Which approach will NOT improve the LLM's response to achieve the desired response?
Answer: A
Explanation:
The task at hand is to improve the LLM's ability to generate poem-like article summaries with the desired tone and style. Using a neutralizer to normalize the tone and style of the underlying documents (option B) will not help improve the LLM's ability to generate the desired poetic style. Here's why:
Neutralizing Underlying Documents:
A neutralizer aims to reduce or standardize the tone of input data. However, this contradicts the goal, which is to generate text with a specific tone and style (like haikus). Neutralizing the source documents will strip away the richness of the content, making it harder for the LLM to generate creative, stylistic outputs like poems.
Why Other Options Improve Results:
A (Explicit Instructions in the Prompt): Directly instructing the LLM to generate text in a specific tone and style helps align the output with the desired format (e.g., haikus). This is a common and effective technique in prompt engineering.
C (Few-shot Examples): Providing examples of the desired output format helps the LLM understand the expected tone and structure, making it easier to generate similar outputs.
D (Fine-tuning the LLM): Fine-tuning the model on a dataset that contains examples of the desired tone and style is a powerful way to improve the model's ability to generate outputs that match the target format.
Therefore, using a neutralizer (option B) is not an effective method for achieving the goal of generating stylized poetic summaries.
NEW QUESTION # 84
A Generative AI Engineer is experimenting with using parameters to configure an agent in Mosaic Agent Framework. However, they are struggling to get the agent to respond with relevant information with this configuration:
config = {"prompt_template": "You are a trivia bot. Generate a question based on the user's input: {user_input}", "input_vars": ["user_input"], "parameters": {"temperature": 0.01, "max_tokens": 500}} Which error is causing the problem?
Answer: A
Explanation:
In the Mosaic AI Agent Framework and underlying LangChain-based configurations, the "input_vars" or "input_variables" must be correctly mapped and referenced within the template. If the configuration dictionary identifies user_input as the variable but the logic executing the chain does not correctly "inject" the runtime value into the {user_input} placeholder, the LLM will receive a literal string (or an empty value) rather than the user's actual question. This results in the model failing to provide relevant information because it essentially doesn't know what the user asked. Engineering standards require ensuring that the key used in the input_vars list matches the key in the JSON payload sent to the model serving endpoint. If there is a mismatch or a failure to parse, the prompt remains static, leading to generic or irrelevant responses.
NEW QUESTION # 85
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: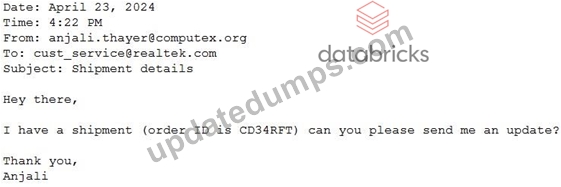
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: B
Explanation:
* Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM's responses.
* Explanation of Options:
Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore, Option B is optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 86
......
As we know, Databricks actual test is related to the IT professional knowledge and experience, it is not easy to clear Databricks-Generative-AI-Engineer-Associate practice exam. The difficulty of exam and the lack of time reduce your pass rate. And it will be a great loss for you if you got a bad result in the Databricks-Generative-AI-Engineer-Associate Exam Tests. So it is urgent for you to choose a study appliance, especially for most people participating Databricks-Generative-AI-Engineer-Associate real exam first time.
Test Databricks-Generative-AI-Engineer-Associate Study Guide: https://www.updatedumps.com/Databricks/Databricks-Generative-AI-Engineer-Associate-updated-exam-dumps.html
DOWNLOAD the newest UpdateDumps Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1MMMb2v_Kt9VGiBO5m8pcQCR1BAgFkrOa