You can see the demos of our Databricks-Certified-Professional-Data-Engineer exam questions which are part of the all titles selected from the test bank and the forms of the questions and answers and know the form of our software on the website pages of our study materials. The website pages list the important information about our Databricks-Certified-Professional-Data-Engineer real quiz. You can analyze the information the website pages provide carefully before you decide to buy our Databricks-Certified-Professional-Data-Engineer learning braindumps.
Databricks Certified Professional Data Engineer exam is a practical and hands-on exam that requires candidates to demonstrate their ability to design and implement data pipelines using Databricks. Databricks-Certified-Professional-Data-Engineer exam consists of multiple-choice questions and hands-on exercises that test the candidate's ability to apply their knowledge to real-world scenarios. Databricks-Certified-Professional-Data-Engineer Exam is designed to be challenging, but fair, and it is intended to accurately assess a candidate's skills and knowledge.
>> Databricks-Certified-Professional-Data-Engineer Reliable Dumps Questions <<
Having a good command of professional knowledge for customers related to this Databricks-Certified-Professional-Data-Engineer exam is of superior condition. However, that is not certain and sure enough to successfully pass this exam. You need efficiency and exam skills as well. Actually, a great majority of exam candidates feel abstracted at this point, wondering which one is the perfect practice material they are looking for. To make things clear, we will instruct you on the traits of our Databricks-Certified-Professional-Data-Engineer real materials one by one. Here we recommend our Databricks-Certified-Professional-Data-Engineer guide question for your reference.
Databricks Certified Professional Data Engineer exam is a valuable certification for data professionals who work with the Databricks platform. By demonstrating their expertise in using Databricks for data engineering tasks, candidates can enhance their career prospects and contribute to the success of their organizations.
NEW QUESTION # 51
The data engineering team maintains the following code: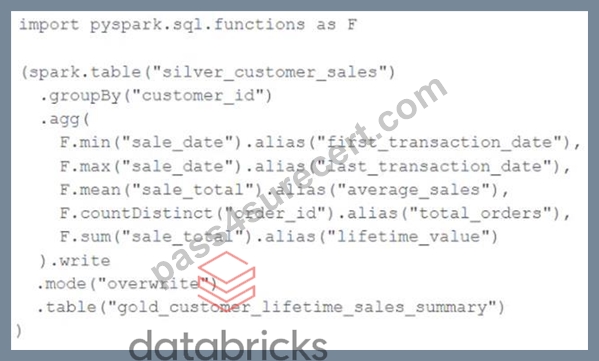
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Answer: B
Explanation:
Explanation
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids.
The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed. References:
https://docs.databricks.com/spark/latest/dataframes-datasets/introduction-to-dataframes-python.html
https://docs.databricks.com/spark/latest/dataframes-datasets/transforming-data-with-dataframes.html
https://docs.databricks.com/spark/latest/dataframes-datasets/aggregating-data-with-dataframes.html
NEW QUESTION # 52
Review the following error traceback: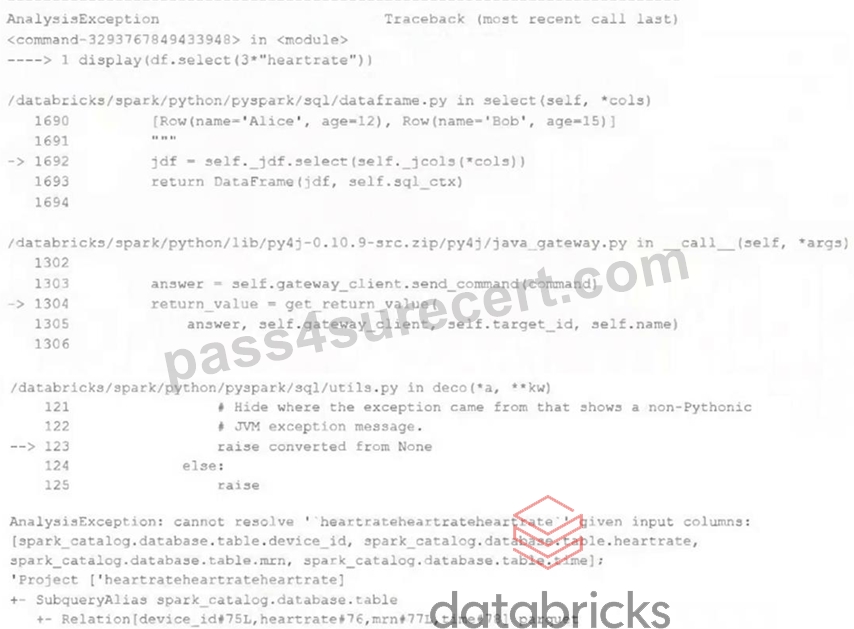
Which statement describes the error being raised?
Answer: D
Explanation:
Explanation
The error is a Py4JJavaError, which means that an exception was thrown in Java code called by Python code using Py4J. Py4J is a library that enables Python programs to dynamically access Java objects in a Java Virtual Machine (JVM). PySpark uses Py4J to communicate with Spark's JVM-based engine. The error message shows that the exception was thrown by org.apache.spark.sql.AnalysisException, which means that an error occurred during the analysis phase of Spark SQL query processing. The error message also shows that the cause of the exception was "cannot resolve 'heartrateheartrateheartrate' given input columns". This means that Spark could not find a column named heartrateheartrateheartrate in the input DataFrame or Dataset. The reason for this error is that there is a syntax error in the code that caused this exception. The code is:
df.withColumn("heartrate", heartrate * 3)
The code tries to create a new column called heartrate by multiplying an existing column called heartrate by 3.
However, the code does not correctly identify the heartrate column as a column object, but rather as a plain Python variable. This causes PySpark to concatenate the variable name with itself three times, resulting in heartrateheartrateheartrate, which is not a valid column name. To fix this error, the code should use one of the following ways to identify the heartrate column as a column object:
df.withColumn("heartrate", df["heartrate"] * 3) df.withColumn("heartrate", df.heartrate * 3) df.withColumn("heartrate", col("heartrate") * 3) Verified References: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Py4J Documentation, under "What is Py4J?"; Databricks Documentation, under "Query plans - Analysis phase"; Databricks Documentation, under "Accessing columns".
NEW QUESTION # 53
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Incremental state information should be maintained for 10 minutes for late-arriving data.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block: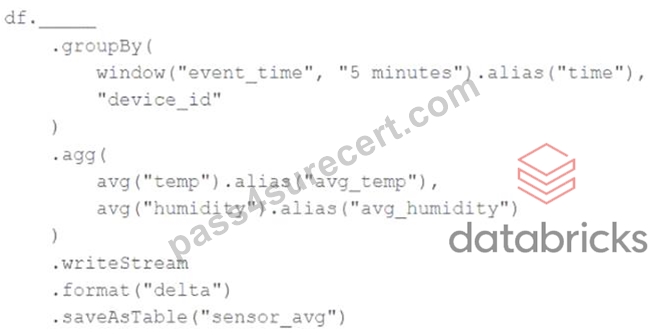
Choose the response that correctly fills in the blank within the code block to complete this task.
Answer: C
Explanation:
The correct answer is A. withWatermark("event_time", "10 minutes"). This is because the question asks for incremental state information to be maintained for 10 minutes for late-arriving data. The withWatermark method is used to define the watermark for late data. The watermark is a timestamp column and a threshold that tells the system how long to wait for late data. In this case, the watermark is set to 10 minutes. The other options are incorrect because they are not valid methods or syntax for watermarking in Structured Streaming. References:
* Watermarking: https://docs.databricks.com/spark/latest/structured-streaming/watermarks.html
* Windowed aggregations:
https://docs.databricks.com/spark/latest/structured-streaming/window-operations.html
NEW QUESTION # 54
Two of the most common data locations on Databricks are the DBFS root storage and external object storage mounted with dbutils.fs.mount().
Which of the following statements is correct?
Answer: E
Explanation:
Explanation
DBFS is a file system protocol that allows users to interact with files stored in object storage using syntax and guarantees similar to Unix file systems1. DBFS is not a physical file system, but a layer over the object storage that provides a unified view of data across different data sources1. By default, the DBFS root is accessible to all users in the workspace, and the access to mounted data sources depends on the permissions of the storage account or container2. Mounted storage volumes do not need to have full public read and write permissions, but they do require a valid connection string or access key to be provided when mounting3. Both the DBFS root and mounted storage can be accessed when using %sh in a Databricks notebook, as long as the cluster has FUSE enabled4. The DBFS root does not store files in ephemeral block volumes attached to the driver, but in the object storage associated with the workspace1. Mounted directories will persist saved data to external storage between sessions, unless they are unmounted or deleted3. References: DBFS, Work with files on Azure Databricks, Mounting cloud object storage on Azure Databricks, Access DBFS with FUSE
NEW QUESTION # 55
You are working on a table called orders which contains data for 2021 and you have the second table called orders_archive which contains data for 2020, you need to combine the data from two tables and there could be a possibility of the same rows between both the tables, you are looking to combine the results from both the tables and eliminate the duplicate rows, which of the following SQL statements helps you accomplish this?
Answer: C
Explanation:
Explanation
Answer is SELECT * FROM orders UNION SELECT * FROM orders_archive
UNION and UNION ALL are set operators,
UNION combines the output from both queries but also eliminates the duplicates.
UNION ALL combines the output from both queries.
NEW QUESTION # 56
......
Databricks-Certified-Professional-Data-Engineer Learning Engine: https://www.pass4surecert.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html